Search Blogs

Showing results for "Diameter of Binary Tree"

Found 6 results

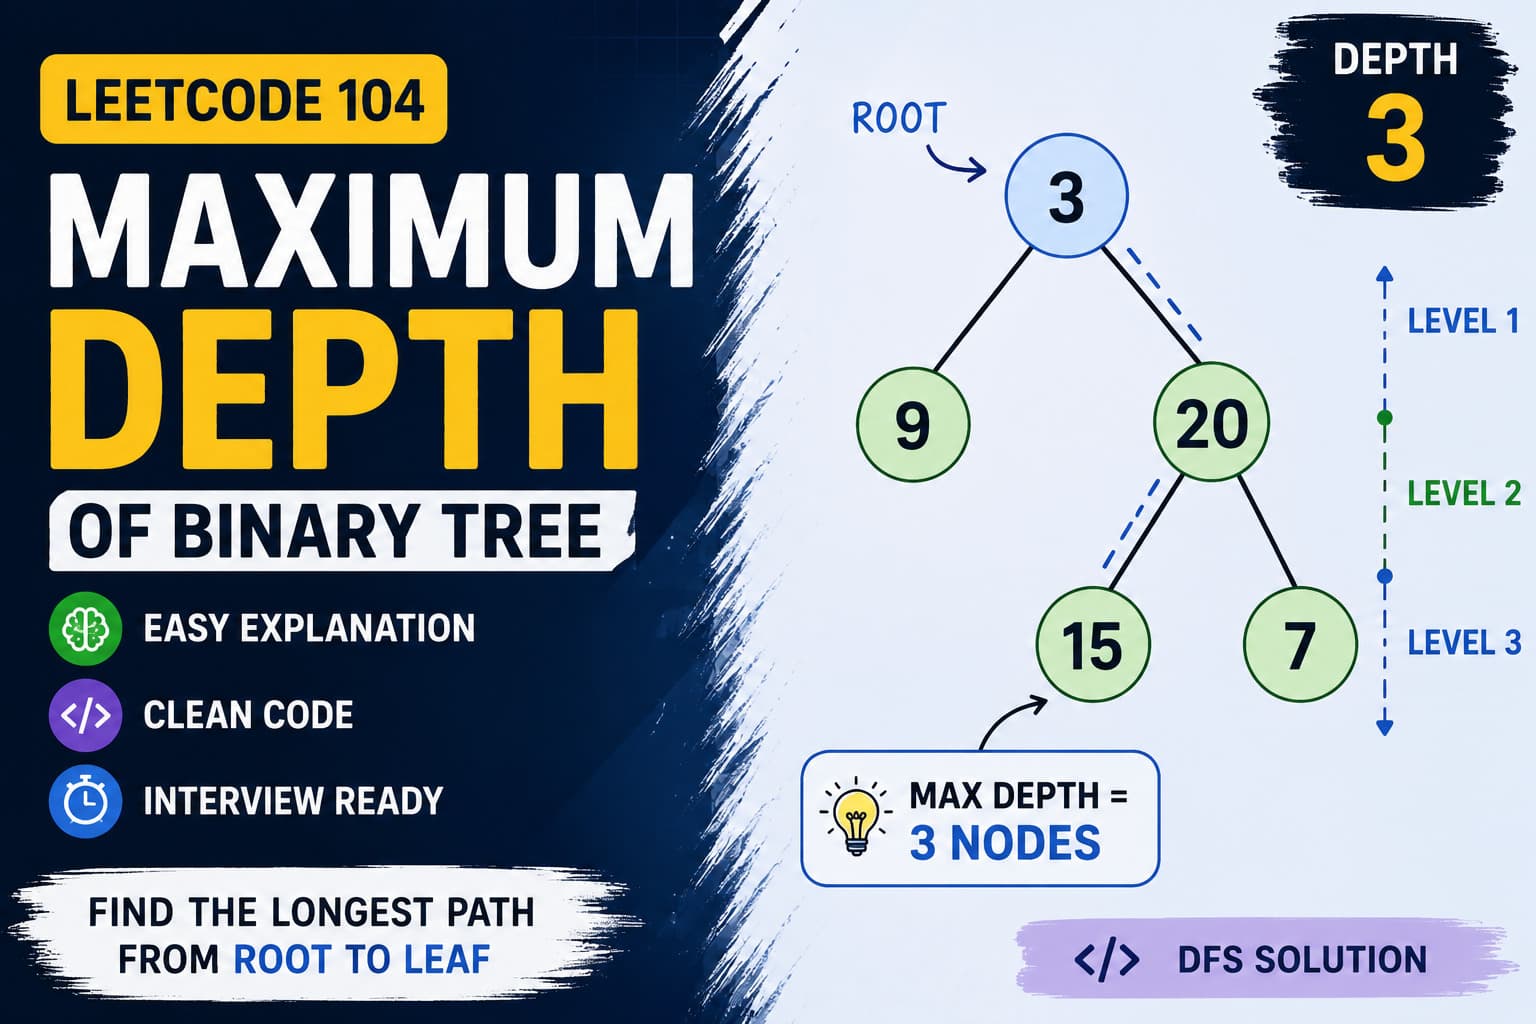
LeetCode 104: Maximum Depth of Binary Tree – Java Recursive Solution Explained

LeetCode 104: Maximum Depth of Binary Tree – Java Recursive Solution Explained

IntroductionLeetCode 104 – Maximum Depth of Binary Tree is one of the most important beginner tree problems in Data Structures and Algorithms.This problem teaches:Binary Tree TraversalDepth First Search (DFS)RecursionTree Height CalculationDivide and ConquerIt is one of the most frequently asked tree questions in coding interviews because it builds the foundation for:Tree recursionHeight problemsBalanced tree problemsDiameter problemsDFS traversalIf you are starting binary trees, this is one of the best problems to master first.Problem LinkπŸ”— https://leetcode.com/problems/maximum-depth-of-binary-tree/Problem StatementGiven the root of a binary tree:Return:Maximum depth of the treeMaximum depth means:Number of nodes along the longest path from root to the farthest leaf node.Example 1Inputroot = [3,9,20,null,null,15,7]Tree: 3 / \ 9 20 / \ 15 7Output3Explanation:Longest path:3 β†’ 20 β†’ 15contains:3 nodesExample 2Inputroot = [1,null,2]Tree:1 \ 2Output:2Understanding Maximum DepthDepth means:How many levels exist in the treeFor example: 1 / \ 2 3 / 4Levels:Level 1 β†’ 1Level 2 β†’ 2,3Level 3 β†’ 4Maximum depth:3Key ObservationThe depth of a tree depends on:Maximum depth of left subtreeandMaximum depth of right subtreeSo:Depth(root)=1 + max(leftDepth, rightDepth)This is the core recursive formula.Recursive IntuitionAt every node:Find depth of left subtreeFind depth of right subtreeTake maximumAdd current nodeThis naturally becomes a recursive DFS problem.Java Recursive Solutionclass Solution { public int maxDepth(TreeNode root) { if(root == null) return 0; int left = maxDepth(root.left); int right = maxDepth(root.right); return 1 + Math.max(left, right); }}Why This WorksAt every node:Recursively calculate left depthRecursively calculate right depthChoose bigger depthAdd:1for current node.This continues until leaf nodes.Dry RunInput 3 / \ 9 20 / \ 15 7Step 1Start from root:3Step 2Left subtree:9Depth:1Step 3Right subtree:20Its children:15 and 7Depth becomes:2Step 4At root:1 + max(1,2)Result:3Recursive Call FlowmaxDepth(3) β”œβ”€β”€ maxDepth(9) β”‚ β”œβ”€β”€ 0 β”‚ └── 0 β”‚ └── maxDepth(20) β”œβ”€β”€ maxDepth(15) └── maxDepth(7)Then values return upward.Alternative BFS ApproachWe can also solve this using:Level Order Traversalusing a queue.Every level increases depth by:1BFS Java Solutionclass Solution { public int maxDepth(TreeNode root) { if(root == null) return 0; Queue<TreeNode> queue = new LinkedList<>(); queue.offer(root); int depth = 0; while(!queue.isEmpty()) { int size = queue.size(); for(int i = 0; i < size; i++) { TreeNode node = queue.poll(); if(node.left != null) queue.offer(node.left); if(node.right != null) queue.offer(node.right); } depth++; } return depth; }}DFS vs BFSApproachTechniqueSpaceDFSRecursionO(H)BFSQueueO(N)Time Complexity AnalysisRecursive DFS SolutionTime ComplexityO(N)because every node is visited once.Space ComplexityO(H)where:H = tree heightWorst case:O(N)for skewed tree.BFS SolutionTime ComplexityO(N)Space ComplexityO(N)queue may contain full level.Interview ExplanationIn interviews, explain:The depth of a node depends on the maximum depth between its left and right subtree. This naturally forms a recursive divide-and-conquer problem.This demonstrates:Tree recursion understandingDFS traversal knowledgeDivide and conquer thinkingCommon Mistakes1. Forgetting Base CaseAlways handle:if(root == null) return 0;2. Using Min Instead of MaxWe need:Longest pathnot shortest.3. Incorrect Depth CountingRemember to add:1for current node.FAQsQ1. What is maximum depth?It is the number of nodes in the longest root-to-leaf path.Q2. Why is recursion preferred?Tree problems naturally fit recursive structures.Q3. Can this be solved iteratively?Yes.Using BFS with queue.Q4. Is this problem important for interviews?Very important.It is one of the most fundamental tree recursion problems.Related ProblemsAfter mastering this problem, practice:Minimum Depth of Binary TreeBalanced Binary TreeDiameter of Binary TreeBinary Tree Level Order TraversalPath SumConclusionLeetCode 104 is one of the most important beginner binary tree problems.It teaches:Recursive DFSTree height calculationDivide and conquerBinary tree traversalThe key insight is:Maximum depth equals 1 + maximum depth of left and right subtree.Once this recursive pattern becomes clear, many advanced tree problems become easier to solve.
LeetCodeDepth of Binary TreeJavaBinary TreeDFSBFSRecursionTreeEasy
LeetCode 543: Diameter of Binary Tree – Java DFS Solution Explained

LeetCode 543: Diameter of Binary Tree – Java DFS Solution Explained

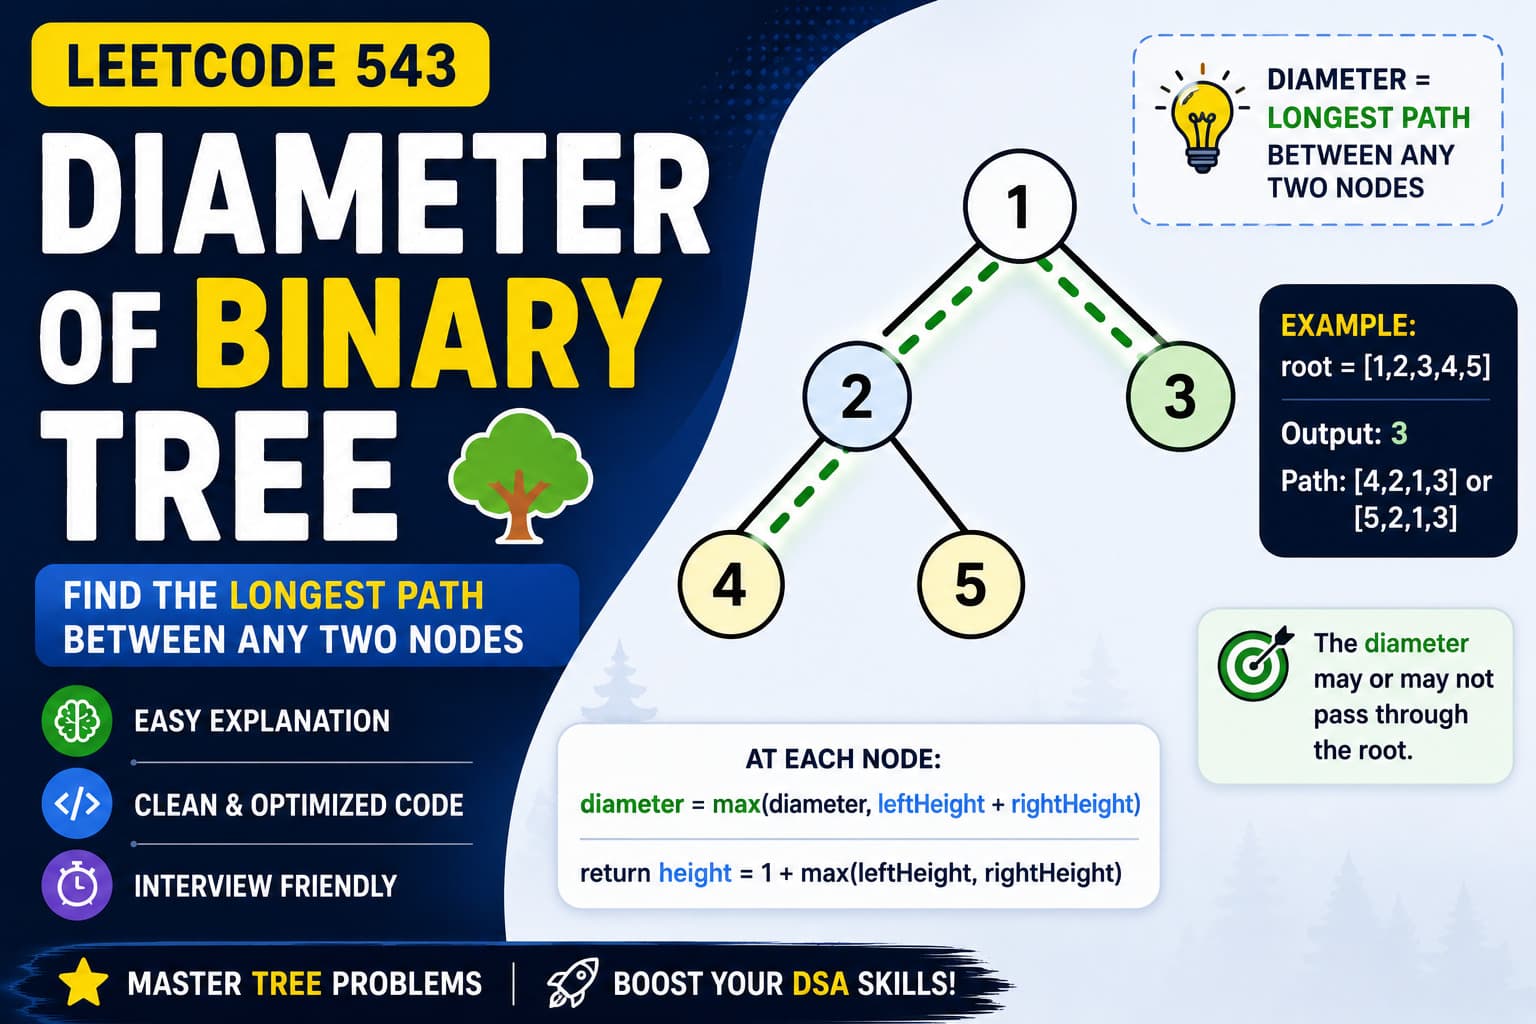
IntroductionLeetCode 543 – Diameter of Binary Tree is one of the most popular binary tree interview problems.This problem teaches:Depth First Search (DFS)Tree height calculationRecursive traversalBottom-up recursionTree optimization techniquesIt is extremely important because it introduces a very common pattern in tree problems:Use recursion to calculate subtree heights while simultaneously updating a global answer.This same idea is used in:Balanced Binary TreeMaximum Path SumLongest ZigZag PathTree DP problemsProblem LinkπŸ”— https://leetcode.com/problems/diameter-of-binary-tree/Problem StatementGiven the root of a binary tree:Return:Length of the diameter of the treeThe diameter is:The length of the longest path between any two nodes in the tree.This path:May pass through the rootMay not pass through the rootImportant NoteThe diameter is measured in:EDGESnot nodes.Example 1Inputroot = [1,2,3,4,5]Tree: 1 / \ 2 3 / \ 4 5Output3Explanation:Longest path:4 β†’ 2 β†’ 1 β†’ 3Edges count:3Example 2Inputroot = [1,2]Tree: 1 / 2Output:1Understanding DiameterAt every node:Possible longest path through that node is:left subtree height + right subtree heightWhy?Because:One side contributes left edgesOther side contributes right edgesTogether they form a path.Key ObservationFor every node:Diameter through node=leftHeight + rightHeightWe compute this for all nodes.Maximum among them becomes answer.Brute Force ApproachIntuitionFor every node:Calculate left subtree heightCalculate right subtree heightCompute diameterRecursively repeat for childrenBrute Force ComplexityHeight gets recalculated repeatedly.Time ComplexityO(NΒ²)Space ComplexityO(H)where:H = tree heightOptimized DFS ApproachInstead of separately calculating:HeightDiameterWe calculate both in one DFS traversal.Core IdeaWhile calculating subtree height:We also update:max diameterThis avoids repeated traversal.Java Solutionclass Solution { int max = Integer.MIN_VALUE; public int solve(TreeNode roo) { if(roo == null) return 0; int left = solve(roo.left); int right = solve(roo.right); max = Math.max(max, left + right); return 1 + Math.max(left, right); } public int diameterOfBinaryTree(TreeNode root) { solve(root); return max; }}Cleaner Optimized Versionclass Solution { int diameter = 0; public int height(TreeNode root) { if(root == null) return 0; int left = height(root.left); int right = height(root.right); diameter = Math.max(diameter, left + right); return 1 + Math.max(left, right); } public int diameterOfBinaryTree(TreeNode root) { height(root); return diameter; }}Why This WorksAt every node:Find left subtree heightFind right subtree heightCompute:left + rightUpdate global maximum diameterReturn current subtree height upwardDry RunInput 1 / \ 2 3 / \ 4 5Step 1Leaf nodes:4 β†’ height = 15 β†’ height = 13 β†’ height = 1Step 2At node:2Left height:1Right height:1Diameter through node:1 + 1 = 2Update:max = 2Height of node 2:2Step 3At root:1Left height:2Right height:1Diameter:2 + 1 = 3Update:max = 3Final Answer3Recursive Visualizationheight(1) β”œβ”€β”€ height(2) β”‚ β”œβ”€β”€ height(4) β”‚ └── height(5) β”‚ └── height(3)Diameter gets updated during return phase.Time Complexity AnalysisOptimized DFS SolutionTime ComplexityO(N)because every node is visited once.Space ComplexityO(H)where:H = tree heightWorst case:O(N)for skewed tree.Brute Force vs OptimizedApproachTime ComplexitySpace ComplexityBrute ForceO(NΒ²)O(H)Optimized DFSO(N)O(H)Interview ExplanationIn interviews, explain:While recursively calculating subtree heights, we simultaneously compute the maximum possible path passing through every node.This demonstrates:DFS understandingBottom-up recursionOptimization skillsTree DP thinkingCommon Mistakes1. Counting Nodes Instead of EdgesDiameter measures:edgesnot nodes.2. Forgetting Global VariableDiameter must be updated across all nodes.3. Returning Diameter Instead of HeightRecursive function should return:heightnot diameter.FAQsQ1. Does diameter always pass through root?No.It can exist completely inside a subtree.Q2. Why use DFS?Because height calculation naturally follows recursive depth traversal.Q3. Why update diameter globally?Because longest path may occur at any node.Q4. Is this problem important for interviews?Very important.It is one of the most common recursive tree questions.ConclusionLeetCode 543 is one of the best problems for learning recursive tree optimization.It teaches:DFS traversalHeight calculationBottom-up recursionGlobal answer trackingThe key insight is:Diameter through a node equals left subtree height + right subtree height.Once you understand this pattern, many advanced binary tree problems become much easier.

LeetCodeDiameter of Binary TreeJavaBinary TreeDFSTreeRecursionEasy
LeetCode 110: Balanced Binary Tree – Java Optimized DFS Solution Explained

LeetCode 110: Balanced Binary Tree – Java Optimized DFS Solution Explained

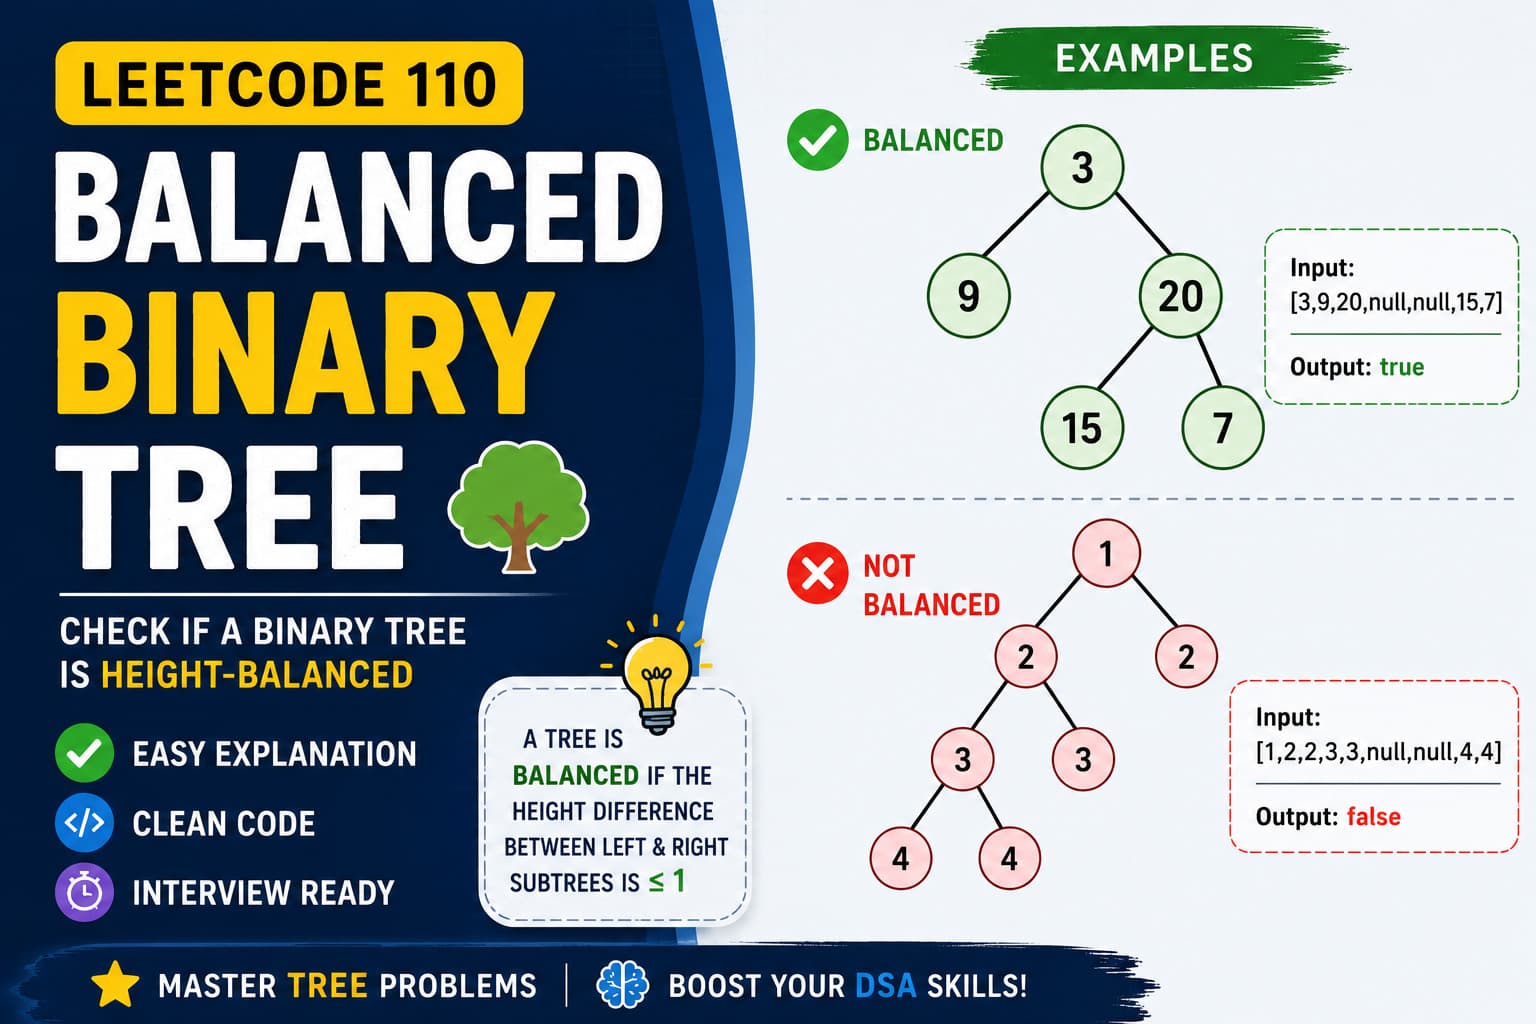
IntroductionLeetCode 110 – Balanced Binary Tree is one of the most important binary tree interview problems.This problem teaches:Tree recursionHeight calculationDepth First Search (DFS)Bottom-up recursionOptimization techniquesIt is frequently asked in coding interviews because it checks whether you can:Traverse trees efficientlyAvoid repeated calculationsCombine recursion with conditionsOptimize brute force tree solutionsThis problem is also a foundation for advanced tree problems like:AVL TreesHeight-balanced treesDiameter of Binary TreeTree DP problemsProblem LinkπŸ”— https://leetcode.com/problems/balanced-binary-tree/Problem StatementGiven the root of a binary tree:Return:trueif the tree is:height-balancedOtherwise return:falseWhat is a Balanced Binary Tree?A binary tree is balanced if:For every node,|height(left subtree) - height(right subtree)| <= 1Meaning:Left and right subtree heights should not differ by more than:1Example 1Inputroot = [3,9,20,null,null,15,7]Tree:3/ \9 20/ \15 7OutputtrueExplanation:Every node satisfies:height difference <= 1Example 2Inputroot = [1,2,2,3,3,null,null,4,4]Tree:1/ \2 2/ \3 3/ \4 4OutputfalseExplanation:Left subtree becomes much deeper than right subtree.Difference becomes greater than:1Key ObservationTo determine if tree is balanced:At every node we need:Height of left subtreeHeight of right subtreeCompare differenceThis naturally becomes a recursive DFS problem.Brute Force ApproachIntuitionFor every node:Calculate left heightCalculate right heightCompare differenceRecursively check childrenBrute Force Java Solutionclass Solution {public int height(TreeNode root) {if(root == null)return 0;return 1 + Math.max(height(root.left), height(root.right));}public boolean isBalanced(TreeNode root) {if(root == null)return true;int left = height(root.left);int right = height(root.right);if(Math.abs(left - right) > 1)return false;return isBalanced(root.left) && isBalanced(root.right);}}Problem with Brute ForceThe height function gets called repeatedly.For every node:Heights are recalculated again and again.This increases complexity significantly.Brute Force ComplexityTime ComplexityO(NΒ²)because height calculation repeats.Space ComplexityO(H)for recursion stack.Optimized DFS ApproachInstead of:Calculating heights separatelyWe can:Calculate height and balance together.Core Optimization IdeaWhile calculating height:If subtree becomes unbalanced:Return negative value immediatelyThis avoids unnecessary computation.Optimized Java Solutionclass Solution {public int solve(TreeNode roo) {if(roo == null)return 0;int left = solve(roo.left);if(left < 0) {return -1;}int right = solve(roo.right);if(right < 0) {return -1;}if(Math.abs(left - right) > 1) {return -1000;}return 1 + Math.max(left, right);}public boolean isBalanced(TreeNode root) {int ans = solve(root);return ans < 0 ? false : true;}}Cleaner Optimized VersionWe can simplify negative returns using:-1consistently.Cleaner Java Solutionclass Solution {public int height(TreeNode root) {if(root == null)return 0;int left = height(root.left);if(left == -1)return -1;int right = height(root.right);if(right == -1)return -1;if(Math.abs(left - right) > 1)return -1;return 1 + Math.max(left, right);}public boolean isBalanced(TreeNode root) {return height(root) != -1;}}Why This WorksAt every node:Recursively calculate left heightRecursively calculate right heightIf difference > 1:Tree is unbalancedPropagate failure upward immediately.Dry RunInput1/ \2 2/ \3 3/ \4 4Step 1Start from leaf nodes:4 β†’ height = 1Step 2Node:3gets:left = 1right = 1Difference:0Balanced.Height:2Step 3At node:2Left height:2Right height:0Difference:2Unbalanced.Return:-1Final ResultTree is:Not balancedReturn:falseTime Complexity AnalysisOptimized DFS SolutionTime ComplexityO(N)because every node is visited once.Space ComplexityO(H)where:H = height of treeWorst case:O(N)for skewed tree.Brute Force vs OptimizedApproachTime ComplexitySpace ComplexityBrute ForceO(NΒ²)O(H)Optimized DFSO(N)O(H)Interview ExplanationIn interviews, explain:Instead of recalculating heights repeatedly, we combine height calculation and balance checking into a single DFS traversal.This demonstrates:Optimization skillsRecursive DFS understandingBottom-up tree processingCommon Mistakes1. Recalculating Heights RepeatedlyThis causes:O(NΒ²)complexity.2. Forgetting Absolute DifferenceAlways use:Math.abs(left - right)3. Not Handling Null NodesBase case:if(root == null)return 0;is necessary.FAQsQ1. What is a balanced binary tree?A tree where left and right subtree heights differ by at most:1for every node.Q2. Why use DFS?Because height calculation naturally follows recursive depth traversal.Q3. Why return -1?It acts as a signal:Subtree already unbalancedQ4. Is this problem important for interviews?Very important.It is one of the most common tree optimization questions.ConclusionLeetCode 110 is an excellent binary tree optimization problem.It teaches:DFS traversalHeight calculationBottom-up recursionOptimization techniquesThe key insight is:Combine balance checking and height calculation in one DFS traversal.Once you understand this optimization pattern, many advanced tree problems become much easier.

LeetCodeBalanced Binary TreeJavaBinary TreeDFSTree HeightRecursionTree
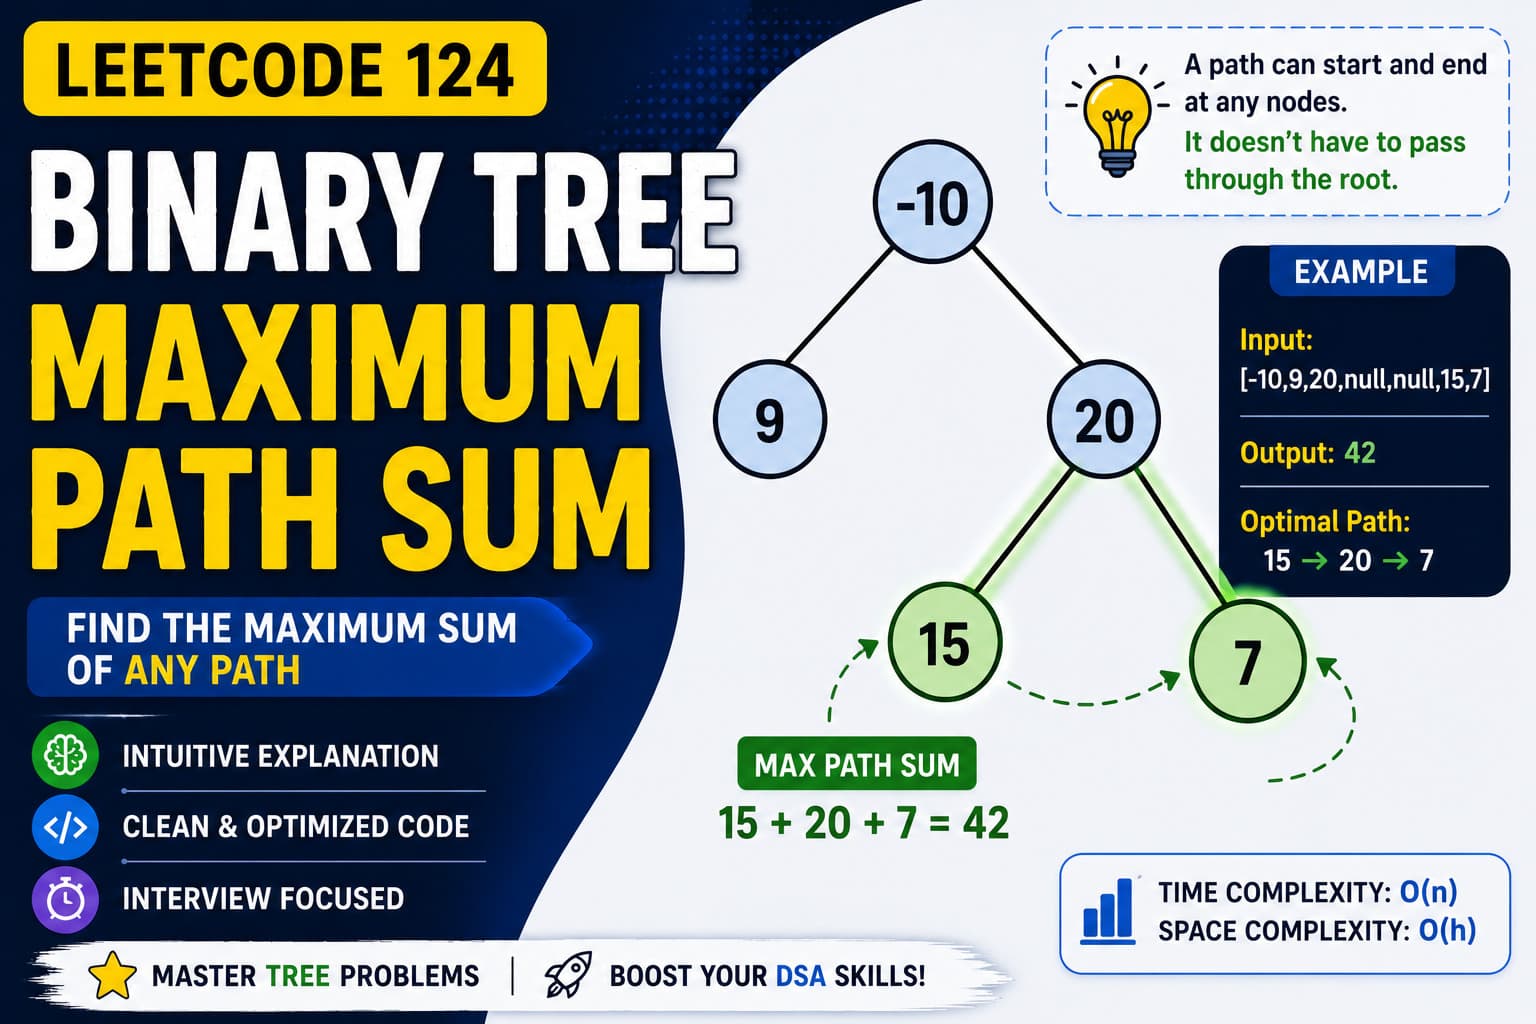
LeetCode 124: Binary Tree Maximum Path Sum – Java DFS Solution Explained

LeetCode 124: Binary Tree Maximum Path Sum – Java DFS Solution Explained

IntroductionLeetCode 124 – Binary Tree Maximum Path Sum is one of the most important and frequently asked hard-level binary tree interview problems.This problem teaches:Depth First Search (DFS)Bottom-up recursionTree Dynamic ProgrammingRecursive optimizationGlobal answer trackingIt is considered a classic interview problem because it combines:Tree traversalRecursive decision makingPath optimizationNegative value handlingMastering this problem helps in understanding advanced binary tree patterns used in:Diameter problemsTree DPMaximum path problemsGraph recursion problemsProblem LinkπŸ”— https://leetcode.com/problems/binary-tree-maximum-path-sum/Problem StatementGiven the root of a binary tree:Return:Maximum path sum of any non-empty pathA path:Can start from any nodeCan end at any nodeMust follow parent-child connectionsCannot visit a node more than onceImportant:Path does NOT need to pass through rootExample 1Inputroot = [1,2,3]Tree: 1 / \ 2 3Output6Explanation:Best path:2 β†’ 1 β†’ 3Path sum:2 + 1 + 3 = 6Example 2Inputroot = [-10,9,20,null,null,15,7]Tree: -10 / \ 9 20 / \ 15 7Output42Explanation:Best path:15 β†’ 20 β†’ 7Sum:15 + 20 + 7 = 42Key ObservationAt every node:We have two important possibilities.Possibility 1Path continues upward to parent.In this case:We can choose only:ONE sidebecause path cannot split upward.Return value becomes:node + max(left, right)Possibility 2Current node becomes:Highest point of pathThen we can use:left + node + rightThis candidate updates global maximum answer.Core Recursive IdeaAt every node:Calculate left maximum contributionCalculate right maximum contributionIgnore negative pathsUpdate global answerReturn best single-side path upwardWhy Ignore Negative Paths?Negative paths reduce total sum.So:Math.max(path, 0)ensures:Negative contribution is discardedOnly profitable paths are consideredThis is the most important optimization.Your Java Solutionclass Solution { int max = Integer.MIN_VALUE; public int solve(TreeNode roo) { if(roo == null) return 0; int left = Math.max(solve(roo.left), 0); int right = Math.max(solve(roo.right), 0); max = Math.max(max, roo.val + left + right); return roo.val + Math.max(left, right); } public int maxPathSum(TreeNode root) { solve(root); return max; }}Why This WorksFor every node:We calculate:Best path passing through current nodewhich is:left + node + rightThis path may become global maximum.But while returning upward:We can only choose:one directionbecause paths cannot split.Dry RunInput -10 / \ 9 20 / \ 15 7Step 1Leaf nodes:9 β†’ return 915 β†’ return 157 β†’ return 7Step 2At node:20Left:15Right:7Current best path:15 + 20 + 7 = 42Update:max = 42Return upward:20 + max(15,7)= 35Step 3At node:-10Left:9Right:35Candidate:9 + (-10) + 35 = 34Global maximum remains:42Final Answer42Recursive Visualizationsolve(-10) β”œβ”€β”€ solve(9) β”‚ └── solve(20) β”œβ”€β”€ solve(15) └── solve(7)Global maximum gets updated during return phase.Brute Force ApproachA brute force approach would:Generate all possible pathsCalculate sumsTrack maximumBut number of paths becomes extremely large.This is inefficient.Brute Force ComplexityTime ComplexityCan become:O(NΒ²)or worse depending on implementation.Optimized DFS ComplexityTime ComplexityO(N)because every node is visited once.Space ComplexityO(H)where:H = height of treeWorst case:O(N)for skewed tree.Important InsightTwo values exist at every node.1. Value Returned UpwardOnly one side allowed:node + max(left, right)2. Value Used for Global MaximumBoth sides allowed:left + node + rightThis distinction is the heart of the problem.Interview ExplanationIn interviews, explain:Every node acts as a potential highest point of a path. We compute the best path through that node while recursively returning the best single-side contribution upward.This demonstrates:Advanced DFS understandingTree DP conceptsRecursive optimizationHandling negative pathsCommon Mistakes1. Returning Both Sides UpwardIncorrect:left + node + rightA path cannot branch upward.2. Forgetting Negative Path HandlingAlways use:Math.max(value, 0)3. Assuming Path Must Pass RootThe path can exist entirely inside a subtree.4. Not Using Global VariableMaximum path may occur anywhere.FAQsQ1. Does path need to start from root?No.It can start and end anywhere.Q2. Why ignore negative sums?Negative paths reduce overall answer.Q3. Why can we return only one side?Because a path moving upward cannot split into two directions.Q4. Is this problem important for interviews?Extremely important.It is one of the most famous hard-level tree problems.Related ProblemsAfter mastering this problem, practice:Diameter of Binary TreeBalanced Binary TreeMaximum Depth of Binary TreeConclusionLeetCode 124 is one of the best problems for learning advanced binary tree recursion.It teaches:DFS optimizationTree dynamic programmingRecursive decision makingNegative path handlingGlobal answer trackingThe key insight is:Every node can become the highest point of a maximum path.Once this recursive pattern becomes clear, many advanced tree and graph problems become much easier to solve.

LeetCodeBinary Tree Maximum Path SumJavaBinary TreeDFSTreeRecursionDynamic Programming on TreesHard
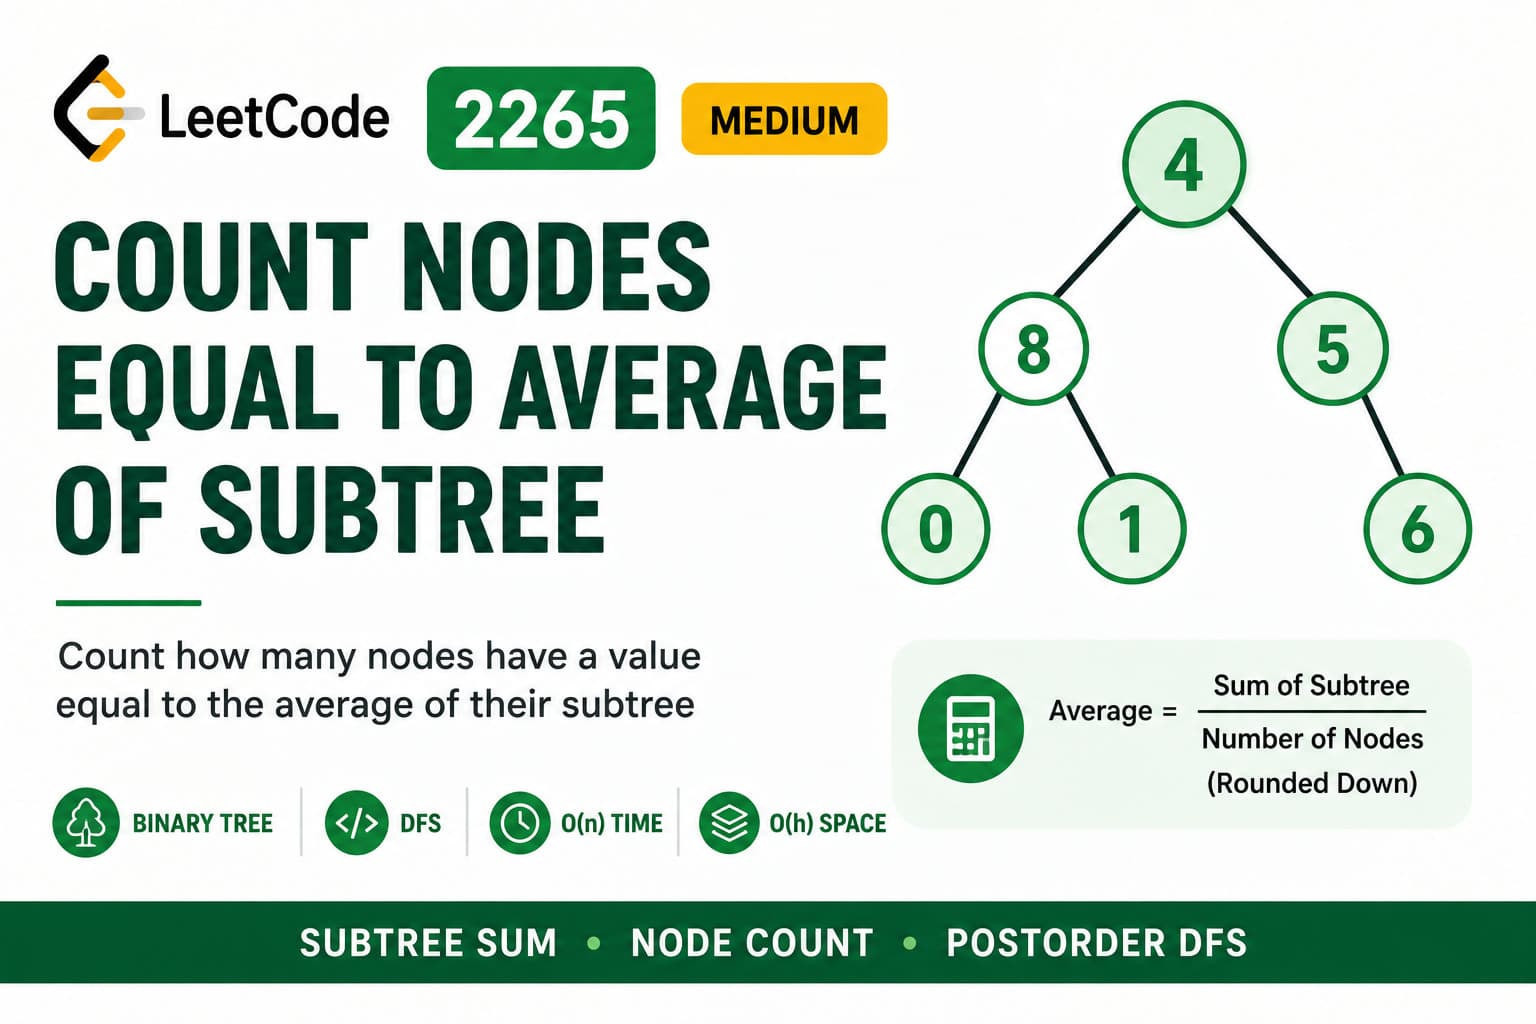
LeetCode 2265: Count Nodes Equal to Average of Subtree – Java DFS Solution

LeetCode 2265: Count Nodes Equal to Average of Subtree – Java DFS Solution

IntroductionBinary tree problems often become interesting when the answer for a node depends on everything below that node.This problem is exactly that.For every node, the task is to calculate the average of all values in its subtree and check whether that average is equal to the value of the node itself.At first, this looks like a simple DFS problem. But there is an important optimization opportunity hidden inside it.To calculate the average of a subtree, two things are required:The sum of all nodes in the subtreeThe number of nodes in the subtreeThe first approach calculates these values directly. Then, by looking at the repeated work, the solution can be improved further.Question LinkLeetCode 2265 – Count Nodes Equal to Average of SubtreeUnderstanding the ProblemFor every node:Average = Subtree Sum / Number of NodesThe average is rounded down.If the calculated average is equal to the current node's value, that node is counted.Consider this tree: 4 / \ 8 5 / \ \ 0 1 6For node 5:Subtree = [5, 6]Sum = 5 + 6 = 11Count = 2Average = 11 / 2 = 5Since the average is 5, node 5 contributes to the answer.The same calculation has to be performed for every node.The Core ObservationFor each node, the required information is:Subtree Sum+Subtree Node CountOnce these two values are available, calculating the average is straightforward.The natural question is:How can the sum and count of every subtree be calculated efficiently?A recursive DFS is a natural fit because the information of a subtree can be obtained by processing its children first.Approach 1: Calculate Subtree Sum and Count SeparatelyThe first approach is the most direct way to think about the problem.For every node:Calculate the sum of its entire subtree.Calculate the number of nodes in that subtree.Calculate the average.Compare it with the current node.Repeat for the left and right children.A separate count() function can be used to count the nodes.This approach follows the problem statement very closely, which makes it a good starting point for understanding the solution.CodeHere is the complete approach, including the separate count() idea:class Solution { int co = 0; // Calculates the sum of all nodes in the subtree public int sumdfs(TreeNode roo) { if (roo == null) { return 0; } // Leaf node contributes its value to the sum if (roo.left == null && roo.right == null) { co++; return roo.val; } int left = sumdfs(roo.left); int right = sumdfs(roo.right); // Current node is also part of its subtree co++; return roo.val + left + right; } // Separate function to count the number of nodes // in the subtree. // // This was the initial idea, but it is commented out // because the sumdfs() traversal can already count nodes. // // public int count(TreeNode roo){ // if(roo == null){ // return 0; // } // if(roo.left == null && roo.right == null){ // return 1; // } // int left = count(roo.left); // int right = count(roo.right); // return 1 + left + right; // } int am = 0; public void solve(TreeNode root) { if (root == null) { return; } // Reset count for the current subtree co = 0; // Calculate the sum of the current subtree // and count its nodes at the same time. int tot = sumdfs(root); int cot = co; // The problem requires the average to be rounded down. if (Math.floor(tot / cot) == root.val) { am++; } // Check the left subtree solve(root.left); // Check the right subtree solve(root.right); } public int averageOfSubtree(TreeNode root) { solve(root); return am; }}How This Approach WorksThe interesting part is sumdfs().Initially, a separate count() function can be used:int cot = count(root);At the same time, another traversal calculates the sum.But there is no need to traverse the same subtree again just to count its nodes.The sumdfs() function is already visiting every node, so the counter can be increased during the same traversal.That is why the following idea works:co++;Whenever a node is visited, co increases by one.After sumdfs(root) finishes:int tot = sumdfs(root);int cot = co;Now:tot = sum of subtreecot = number of nodes in subtreeand the average can be calculated.Dry RunConsider: 4 / \ 8 5 / \ \ 0 1 6Start from node 4.Node 0sum = 0count = 1average = 0 / 1 = 0So node 0 is counted.Node 1sum = 1count = 1average = 1 / 1 = 1Node 1 is counted.Node 8Its subtree is: 8 / \ 0 1Therefore:sum = 8 + 0 + 1 = 9count = 3average = 9 / 3 = 3Since:8 != 3node 8 is not counted.Node 6sum = 6count = 1average = 6Node 6 is counted.Node 5Its subtree is: 5 \ 6So:sum = 5 + 6 = 11count = 2average = 11 / 2 = 5Node 5 is counted.Node 4The complete subtree is: 4 / \ 8 5 / \ \ 0 1 6Therefore:sum = 4 + 8 + 5 + 0 + 1 + 6 = 24count = 6average = 24 / 6 = 4Node 4 is counted.The final answer is:5An Important Complexity ObservationThe co variable removes the need for a separate count() traversal.However, there is still a bigger issue.Look at what happens when solve() processes the root.It calls:sumdfs(root);which visits the entire tree.Then solve() moves to the left child and calls:sumdfs(root.left);which visits that subtree again.Then the same thing happens for the right subtree.So the same nodes can be visited many times.For example, in a skewed tree:1 \ 2 \ 3 \ 4 \ 5The first call processes:1 β†’ 2 β†’ 3 β†’ 4 β†’ 5The second processes:2 β†’ 3 β†’ 4 β†’ 5The third:3 β†’ 4 β†’ 5and so on.Therefore, although the co optimization is cleaner than using a separate count() traversal, the overall worst-case complexity can still reach:O(nΒ²)This observation leads directly to the optimal solution.Approach 2: Calculate Everything During One Postorder TraversalInstead of recalculating every subtree, the better idea is:Calculate the subtree information once and return it to the parent.For every node, the DFS can return two values:sumcountSuppose a node has:left subtree β†’ (leftSum, leftCount)right subtree β†’ (rightSum, rightCount)Then the current node can calculate:sum = root.val + leftSum + rightSumand:count = 1 + leftCount + rightCountNow the average is immediately available.After checking the current node, the pair:(sum, count)is returned to its parent.This means every node is processed exactly once.Why Postorder Traversal?The traversal order is:Left β†’ Right β†’ RootThis is called postorder traversal.It fits perfectly because the parent needs information from its children before it can calculate its own subtree information.For example: 4 / \ 8 5The algorithm first calculates information for:85and then combines them at:4This is a very common pattern in tree problems.Optimal Java SolutionA small Pair class can be used to return both the subtree sum and node count together.class Solution { int ans = 0; class Pair { int sum; int count; Pair(int sum, int count) { this.sum = sum; this.count = count; } } public Pair dfs(TreeNode root) { // Empty subtree if (root == null) { return new Pair(0, 0); } // Get sum and count from left subtree Pair left = dfs(root.left); // Get sum and count from right subtree Pair right = dfs(root.right); // Calculate information for current subtree int sum = root.val + left.sum + right.sum; int count = 1 + left.count + right.count; // Calculate subtree average int average = sum / count; // Check if current node equals its subtree average if (average == root.val) { ans++; } // Return current subtree information to parent return new Pair(sum, count); } public int averageOfSubtree(TreeNode root) { dfs(root); return ans; }}Why This Solution Is OptimalConsider node 4.Instead of recalculating its subtree from scratch, the algorithm receives:From 8:sum = 9count = 3and:From 5:sum = 11count = 2Then:sum = 4 + 9 + 11 = 24and:count = 1 + 3 + 2 = 6Therefore:average = 24 / 6 = 4The information is calculated once and passed upward.No subtree needs to be recalculated.Complexity AnalysisApproach 1The sumdfs() traversal can be repeated for every node.Time ComplexityO(nΒ²)in the worst case.Space ComplexityThe recursion stack depends on the height of the tree:O(h)Approach 2: One Postorder DFSEvery node is visited exactly once.At each node, only constant-time operations are performed.Time ComplexityO(n)Space ComplexityO(h)where h is the height of the tree.For a balanced tree:O(log n)For a skewed tree:O(n)A Small Java ImprovementThere is also a small simplification in the original code.The following expression:Math.floor(tot / cot)is unnecessary here.Because tot and cot are integers:tot / cotalready performs integer division.For example:11 / 2 = 5which is exactly the required rounded-down result because all node values are non-negative.Therefore, the comparison can simply be:if (tot / cot == root.val)The optimal solution uses:int average = sum / count;which is cleaner and easier to read.Approach ComparisonApproachMain IdeaTimeSpaceSeparate sum + countCalculate subtree information directlyO(nΒ²) worst caseO(h)Global co counterCount nodes during sum traversalO(nΒ²) worst caseO(h)One postorder DFSReturn sum + count to parentO(n)O(h)The second approach is a useful improvement over the first, but the third approach is the real optimization.What Can Be Learned From This Problem?This problem teaches an important binary-tree pattern:If a parent needs information about its entire subtree, calculate that information from the results returned by its children.Instead of repeatedly asking:"What is the sum of this subtree?""What is the count of this subtree?"the children calculate their information once and return it.The parent simply combines the results.This pattern appears in many tree problems involving:Subtree sumsSubtree sizesTree heightDiameterBalanced tree checkingMaximum path calculationsCounting nodes satisfying a conditionTree dynamic programmingA useful mental template is:Result dfs(Node root) { if (root == null) { return baseResult; } Result left = dfs(root.left); Result right = dfs(root.right); // Combine left + right + current node return result;}Once this pattern becomes familiar, many seemingly complicated tree problems become much easier to approach.Interview TipIf an interviewer asks for the straightforward solution first, it is perfectly reasonable to start with the direct recursive approach.But after getting it working, look for repeated subtree calculations.A strong follow-up thought process is:Am I visiting the same subtree multiple times? ↓Can I calculate its information once? ↓Can I return that information to the parent? ↓Postorder DFSThis is often the difference between an acceptable recursive solution and an optimal tree solution.ConclusionThe straightforward approach is a natural way to solve this problem: for each node, calculate the sum and number of nodes in its subtree, find the average, and check whether it matches the node's value.The first improvement is to notice that the same DFS used for calculating the sum can also maintain the node count using a shared counter instead of running a separate count() traversal.However, the bigger optimization comes from noticing that subtrees are still being recalculated.The optimal solution solves this by using one postorder DFS. Each node receives the sum and count from its children, calculates its own subtree information, checks the average, and passes the result to its parent.This changes the worst-case time complexity from:O(nΒ²)to:O(n)The most valuable takeaway is the pattern behind the solution:When a tree problem asks for information about a subtree, try to calculate that information once and return it upward through postorder DFS.

LeetCodeJavaBinary TreeDFSRecursionPostorder TraversalMedium
What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

Introduction β€” Why Dynamic Programming Feels Hard (And Why It Isn't)If you've ever stared at a LeetCode problem, read the solution, understood every single line, and still had absolutely no idea how someone arrived at it β€” welcome. You've just experienced the classic Dynamic Programming (DP) confusion.DP has a reputation. People treat it like some dark art reserved for competitive programmers or Google engineers. The truth? Dynamic Programming is one of the most logical, learnable, and satisfying techniques in all of computer science. Once it clicks, it really clicks.This guide will take you from zero to genuinely confident. We'll cover where DP came from, how it works, what patterns to learn, how to recognize DP problems, real-world places it shows up, LeetCode problems to practice, time complexity analysis, and the mistakes that trip up even experienced developers.Let's go.The Origin Story β€” Who Invented Dynamic Programming and Why?The term "Dynamic Programming" was coined by Richard Bellman in the early 1950s while working at RAND Corporation. Here's the funny part: the name was deliberately chosen to sound impressive and vague.Bellman was doing mathematical research that his employer β€” the US Secretary of Defense, Charles Wilson β€” would have found difficult to fund if described accurately. Wilson had a well-known distaste for the word "research." So Bellman invented a name that sounded suitably grand and mathematical: Dynamic Programming.In his autobiography, Bellman wrote that he picked the word "dynamic" because it had a precise technical meaning and was also impossible to use negatively. "Programming" referred to the mathematical sense β€” planning and decision-making β€” not computer programming.The underlying idea? Break a complex problem into overlapping subproblems, solve each subproblem once, and store the result so you never solve it twice.Bellman's foundational contribution was the Bellman Equation, which underpins not just algorithms but also economics, operations research, and modern reinforcement learning.So the next time DP feels frustrating, remember β€” even its inventor named it specifically to confuse people. You're in good company.What Is Dynamic Programming? (Simple Definition)Dynamic Programming is an algorithmic technique used to solve problems by:Breaking them down into smaller overlapping subproblemsSolving each subproblem only onceStoring the result (memoization or tabulation)Building up the final solution from those stored resultsThe key insight is overlapping subproblems + optimal substructure.Overlapping subproblems means the same smaller problems come up again and again. Instead of solving them every time (like plain recursion does), DP solves them once and caches the answer.Optimal substructure means the optimal solution to the whole problem can be built from optimal solutions to its subproblems.If a problem has both these properties β€” it's a DP problem.The Two Approaches to Dynamic Programming1. Top-Down with Memoization (Recursive + Cache)You write a recursive solution exactly as you would naturally, but add a cache (usually a dictionary or array) to store results you've already computed.fib(n):if n in cache: return cache[n]if n <= 1: return ncache[n] = fib(n-1) + fib(n-2)return cache[n]This is called memoization β€” remember what you computed so you don't repeat yourself.Pros: Natural to write, mirrors the recursive thinking, easy to reason about. Cons: Stack overhead from recursion, risk of stack overflow on large inputs.2. Bottom-Up with Tabulation (Iterative)You figure out the order in which subproblems need to be solved, then solve them iteratively from the smallest up, filling a table.fib(n):dp = [0, 1]for i from 2 to n:dp[i] = dp[i-1] + dp[i-2]return dp[n]This is called tabulation β€” fill a table, cell by cell, bottom to top.Pros: No recursion overhead, usually faster in practice, easier to optimize space. Cons: Requires thinking about the order of computation upfront.🧩 Dynamic Programming Template CodeBefore diving into how to recognize DP problems, here are ready-to-use Java templates for every major DP pattern. Think of these as your reusable blueprints β€” every DP problem you ever solve will fit into one of these structures. Just define your state, plug in your recurrence relation, and you are good to go.Template 1 β€” Top-Down (Memoization)import java.util.HashMap;import java.util.Map;public class TopDownDP {Map<Integer, Integer> memo = new HashMap<>();public int solve(int n) {// Base caseif (n <= 1) return n;// Check cacheif (memo.containsKey(n)) return memo.get(n);// Recurrence relation β€” change this part for your problemint result = solve(n - 1) + solve(n - 2);// Store in cachememo.put(n, result);return result;}}Template 2 β€” Bottom-Up (Tabulation)public class BottomUpDP {public int solve(int n) {// Create DP tableint[] dp = new int[n + 1];// Base casesdp[0] = 0;dp[1] = 1;// Fill the table bottom-upfor (int i = 2; i <= n; i++) {// Recurrence relation β€” change this part for your problemdp[i] = dp[i - 1] + dp[i - 2];}return dp[n];}}Template 3 β€” Bottom-Up with Space Optimizationpublic class SpaceOptimizedDP {public int solve(int n) {// Only keep last two values instead of full tableint prev2 = 0;int prev1 = 1;for (int i = 2; i <= n; i++) {// Recurrence relation β€” change this part for your problemint curr = prev1 + prev2;prev2 = prev1;prev1 = curr;}return prev1;}}Template 4 β€” 2D DP (Two Sequences or Grid)public class TwoDimensionalDP {public int solve(String s1, String s2) {int m = s1.length();int n = s2.length();// Create 2D DP tableint[][] dp = new int[m + 1][n + 1];// Base cases β€” first row and columnfor (int i = 0; i <= m; i++) dp[i][0] = i;for (int j = 0; j <= n; j++) dp[0][j] = j;// Fill table cell by cellfor (int i = 1; i <= m; i++) {for (int j = 1; j <= n; j++) {// Recurrence relation β€” change this part for your problemif (s1.charAt(i - 1) == s2.charAt(j - 1)) {dp[i][j] = dp[i - 1][j - 1];} else {dp[i][j] = 1 + Math.min(dp[i - 1][j],Math.min(dp[i][j - 1], dp[i - 1][j - 1]));}}}return dp[m][n];}}Template 5 β€” Knapsack Patternpublic class KnapsackDP {public int solve(int[] weights, int[] values, int capacity) {int n = weights.length;// dp[i][w] = max value using first i items with capacity wint[][] dp = new int[n + 1][capacity + 1];for (int i = 1; i <= n; i++) {for (int w = 0; w <= capacity; w++) {// Don't take item idp[i][w] = dp[i - 1][w];// Take item i if it fitsif (weights[i - 1] <= w) {dp[i][w] = Math.max(dp[i][w],values[i - 1] + dp[i - 1][w - weights[i - 1]]);}}}return dp[n][capacity];}}πŸ’‘ How to use these templates:Step 1 β€” Identify which pattern your problem fits into. Step 2 β€” Define what dp[i] or dp[i][j] means in plain English before writing any code. Step 3 β€” Write your recurrence relation on paper first. Step 4 β€” Plug it into the matching template above. Step 5 β€” Handle your specific base cases carefully.πŸŽ₯ Visual Learning Resource β€” Watch This Before Moving ForwardIf you prefer learning by watching before reading, this free full-length course by freeCodeCamp is one of the best Dynamic Programming resources on the internet. Watch it alongside this guide for maximum understanding.Credit: freeCodeCamp β€” a free, nonprofit coding education platform.How to Recognize a Dynamic Programming ProblemAsk yourself these four questions:1. Can I define the problem in terms of smaller versions of itself? If you can write a recursive formula (recurrence relation), DP might apply.2. Do the subproblems overlap? If a naive recursive solution would recompute the same thing many times, DP is the right tool.3. Is there an optimal substructure? Is the best answer to the big problem made up of best answers to smaller problems?4. Are you looking for a count, minimum, maximum, or yes/no answer? DP problems often ask: "What is the minimum cost?", "How many ways?", "Can we achieve X?"Red flag words in problem statements: minimum, maximum, shortest, longest, count the number of ways, can we reach, is it possible, fewest steps.The Core DP Patterns You Must LearnMastering DP is really about recognizing patterns. Here are the most important ones:Pattern 1 β€” 1D DP (Linear) Problems where the state depends on previous elements in a single sequence. Examples: Fibonacci, Climbing Stairs, House Robber.Pattern 2 β€” 2D DP (Grid / Two-sequence) Problems with two dimensions of state, often grids or two strings. Examples: Longest Common Subsequence, Edit Distance, Unique Paths.Pattern 3 β€” Interval DP You consider all possible intervals or subarrays and build solutions from them. Examples: Matrix Chain Multiplication, Burst Balloons, Palindrome Partitioning.Pattern 4 β€” Knapsack DP (0/1 and Unbounded) You decide whether to include or exclude items under a capacity constraint. Examples: 0/1 Knapsack, Coin Change, Partition Equal Subset Sum.Pattern 5 β€” DP on Trees State is defined per node; you combine results from children. Examples: Diameter of Binary Tree, House Robber III, Maximum Path Sum.Pattern 6 β€” DP on Subsets / Bitmask DP State includes a bitmask representing which elements have been chosen. Examples: Travelling Salesman Problem, Shortest Superstring.Pattern 7 β€” DP on Strings Matching, editing, or counting arrangements within strings. Examples: Longest Palindromic Subsequence, Regular Expression Matching, Wildcard Matching.Top LeetCode Problems to Practice Dynamic Programming (With Links)Here are the essential problems, organized by difficulty and pattern. Solve them in this order.Beginner β€” Warm UpProblemPatternLinkClimbing Stairs1D DPhttps://leetcode.com/problems/climbing-stairs/Fibonacci Number1D DPhttps://leetcode.com/problems/fibonacci-number/House Robber1D DPhttps://leetcode.com/problems/house-robber/Min Cost Climbing Stairs1D DPhttps://leetcode.com/problems/min-cost-climbing-stairs/Best Time to Buy and Sell Stock1D DPhttps://leetcode.com/problems/best-time-to-buy-and-sell-stock/Intermediate β€” Core PatternsProblemPatternLinkCoin ChangeKnapsackhttps://leetcode.com/problems/coin-change/Longest Increasing Subsequence1D DPhttps://leetcode.com/problems/longest-increasing-subsequence/Longest Common Subsequence2D DPhttps://leetcode.com/problems/longest-common-subsequence/0/1 Knapsack (via Subset Sum)Knapsackhttps://leetcode.com/problems/partition-equal-subset-sum/Unique Paths2D Grid DPhttps://leetcode.com/problems/unique-paths/Jump Game1D DP / Greedyhttps://leetcode.com/problems/jump-game/Word BreakString DPhttps://leetcode.com/problems/word-break/Decode Ways1D DPhttps://leetcode.com/problems/decode-ways/Edit Distance2D String DPhttps://leetcode.com/problems/edit-distance/Triangle2D DPhttps://leetcode.com/problems/triangle/Advanced β€” Interview LevelProblemPatternLinkBurst BalloonsInterval DPhttps://leetcode.com/problems/burst-balloons/Regular Expression MatchingString DPhttps://leetcode.com/problems/regular-expression-matching/Wildcard MatchingString DPhttps://leetcode.com/problems/wildcard-matching/Palindrome Partitioning IIInterval DPhttps://leetcode.com/problems/palindrome-partitioning-ii/Maximum Profit in Job SchedulingDP + Binary Searchhttps://leetcode.com/problems/maximum-profit-in-job-scheduling/Distinct Subsequences2D DPhttps://leetcode.com/problems/distinct-subsequences/Cherry Pickup3D DPhttps://leetcode.com/problems/cherry-pickup/Real-World Use Cases of Dynamic ProgrammingDP is not just for coding interviews. It is deeply embedded in the technology you use every day.1. Google Maps & Navigation (Shortest Path) The routing engines behind GPS apps use DP-based algorithms like Dijkstra and Bellman-Ford to find the shortest or fastest path between two points across millions of nodes.2. Spell Checkers & Autocorrect (Edit Distance) When your phone corrects "teh" to "the," it is computing Edit Distance β€” a classic DP problem β€” between what you typed and every word in the dictionary.3. DNA Sequence Alignment (Bioinformatics) Researchers use the Needleman-Wunsch and Smith-Waterman algorithms β€” both DP β€” to align DNA and protein sequences and find similarities between species or identify mutations.4. Video Compression (MPEG, H.264) Modern video codecs use DP to determine the most efficient way to encode video frames, deciding which frames to store as full images and which to store as differences from the previous frame.5. Financial Portfolio Optimization Investment algorithms use DP to find the optimal allocation of assets under risk constraints β€” essentially a variant of the knapsack problem.6. Natural Language Processing (NLP) The Viterbi algorithm β€” used in speech recognition, part-of-speech tagging, and machine translation β€” is a DP algorithm. Every time Siri or Google Assistant understands your sentence, DP played a role.7. Game AI (Chess, Checkers) Game trees and minimax algorithms with memoization use DP to evaluate board positions and find the best move without recomputing already-seen positions.8. Compiler Optimization Compilers use DP to decide the optimal order of operations and instruction scheduling to generate the most efficient machine code.9. Text Justification (Word Processors) Microsoft Word and LaTeX use DP to optimally break paragraphs into lines β€” minimizing raggedness and maximizing visual appeal.10. Resource Scheduling in Cloud Computing AWS, Google Cloud, and Azure use DP-based scheduling to assign computational tasks to servers in the most cost-efficient way possible.Time Complexity Analysis of Common DP ProblemsUnderstanding the time complexity of DP is critical for interviews and for building scalable systems.ProblemTime ComplexitySpace ComplexityNotesFibonacci (naive recursion)O(2ⁿ)O(n)Exponential β€” terribleFibonacci (DP)O(n)O(1) with optimizationLinear β€” excellentLongest Common SubsequenceO(m Γ— n)O(m Γ— n)m, n = lengths of two stringsEdit DistanceO(m Γ— n)O(m Γ— n)Can optimize space to O(n)0/1 KnapsackO(n Γ— W)O(n Γ— W)n = items, W = capacityCoin ChangeO(n Γ— amount)O(amount)Classic tabulationLongest Increasing SubsequenceO(nΒ²) or O(n log n)O(n)Binary search version is fasterMatrix Chain MultiplicationO(nΒ³)O(nΒ²)Interval DPTravelling Salesman (bitmask)O(2ⁿ Γ— nΒ²)O(2ⁿ Γ— n)Still exponential but manageable for small nThe general rule: DP trades time for space. You use memory to avoid recomputation. The time complexity equals the number of unique states multiplied by the work done per state.How to Learn and Master Dynamic Programming β€” Step by StepHere is an honest, structured path to mastery:Step 1 β€” Get recursion absolutely solid first. DP is memoized recursion at its core. If you cannot write clean recursive solutions confidently, DP will remain confusing. Practice at least 20 pure recursion problems first.Step 2 β€” Start with the classics. Fibonacci β†’ Climbing Stairs β†’ House Robber β†’ Coin Change. These teach you the core pattern of defining state and transition without overwhelming you.Step 3 β€” Learn to define state explicitly. Before writing any code, ask: "What does dp[i] represent?" Write it in plain English. "dp[i] = the minimum cost to reach step i." This single habit separates good DP thinkers from struggling ones.Step 4 β€” Write the recurrence relation before coding. On paper or in a comment. Example: dp[i] = min(dp[i-1] + cost[i-1], dp[i-2] + cost[i-2]). If you can write the recurrence, the code writes itself.Step 5 β€” Master one pattern at a time. Don't jump between knapsack and interval DP in the same week. Spend a few days on each pattern until it feels intuitive.Step 6 β€” Solve the same problem both ways. Top-down and bottom-up. This builds deep understanding of what DP is actually doing.Step 7 β€” Optimize space after getting correctness. Many 2D DP solutions can use a single row instead of a full matrix. Learn this optimization after you understand the full solution.Step 8 β€” Do timed practice under interview conditions. Give yourself 35 minutes per problem. Review what you got wrong. DP is a muscle β€” it builds with reps.Common Mistakes in Dynamic Programming (And How to Avoid Them)Mistake 1 β€” Jumping to code before defining state. The most common DP error. Always define what dp[i] or dp[i][j] means before writing a single line of code.Mistake 2 β€” Wrong base cases. A single wrong base case corrupts every answer built on top of it. Trace through your base cases manually on a tiny example before running code.Mistake 3 β€” Off-by-one errors in indexing. Whether your dp array is 0-indexed or 1-indexed must be 100% consistent throughout. This causes more bugs in DP than almost anything else.Mistake 4 β€” Confusing top-down with bottom-up state order. In bottom-up DP, you must ensure that when you compute dp[i], all values it depends on are already filled. If you compute in the wrong order, you get garbage answers.Mistake 5 β€” Memoizing in the wrong dimension. In 2D problems, some people cache only one dimension when the state actually requires two. Always identify all variables that affect the outcome.Mistake 6 β€” Using global mutable state in recursion. If you use a shared array and don't clear it between test cases, you'll get wrong answers on subsequent inputs. Always scope your cache correctly.Mistake 7 β€” Not considering the full state space. In problems like Knapsack, forgetting that the state is (item index, remaining capacity) β€” not just item index β€” leads to fundamentally wrong solutions.Mistake 8 β€” Giving up after not recognizing the pattern immediately. DP problems don't announce themselves. The skill is learning to ask "is there overlapping subproblems here?" on every problem. This takes time. Don't mistake unfamiliarity for inability.Frequently Asked Questions About Dynamic ProgrammingQ: Is Dynamic Programming the same as recursion? Not exactly. Recursion is a technique for breaking problems into smaller pieces. DP is recursion plus memoization β€” or iterative tabulation. All DP can be written recursively, but not all recursion is DP.Q: What is the difference between DP and Divide and Conquer? Divide and Conquer (like Merge Sort) breaks problems into non-overlapping subproblems. DP is used when subproblems overlap β€” meaning the same subproblem is solved multiple times in a naive approach.Q: How do I know when NOT to use DP? If the subproblems don't overlap (no repeated computation), greedy or divide-and-conquer may be better. If the problem has no optimal substructure, DP won't give a correct answer.Q: Do I need to memorize DP solutions for interviews? No. You need to recognize patterns and be able to derive the recurrence relation. Memorizing solutions without understanding them will fail you in interviews. Focus on the thinking process.Q: How long does it take to get good at DP? Most people start to feel genuinely comfortable after solving 40–60 varied DP problems with deliberate practice. The first 10 feel impossible. The next 20 feel hard. After 50, patterns start feeling obvious.Q: What programming language is best for DP? Any language works. Python is often used for learning because its dictionaries make memoization trivial. C++ is preferred in competitive programming for its speed. For interviews, use whatever language you're most comfortable in.Q: What is space optimization in DP? Many DP problems only look back one or two rows to compute the current row. In those cases, you can replace an nΓ—m table with just two arrays (or even one), reducing space complexity from O(nΓ—m) to O(m). This is called space optimization or rolling array technique.Q: Can DP be applied to graph problems? Absolutely. Shortest path algorithms like Bellman-Ford are DP. Longest path in a DAG is DP. DP on trees is a rich subfield. Anywhere you have states and transitions, DP can potentially apply.Q: Is Greedy a type of Dynamic Programming? Greedy is related but distinct. Greedy makes locally optimal choices without reconsidering. DP considers all choices and picks the globally optimal one. Some DP solutions reduce to greedy when the structure allows, but they are different techniques.Q: What resources should I use to learn DP? For structured learning: Neetcode.io (organized problem list), Striver's DP Series on YouTube, and the book "Introduction to Algorithms" (CLRS) for theoretical depth. For practice: LeetCode's Dynamic Programming study plan and Codeforces for competitive DP.Final Thoughts β€” Dynamic Programming Is a SuperpowerDynamic Programming is genuinely one of the most powerful ideas in computer science. It shows up in your GPS, your autocorrect, your streaming video, your bank's risk models, and the AI assistants you talk to daily.The path to mastering it is not memorization. It is developing the habit of asking: can I break this into smaller problems that overlap? And then learning to define state clearly, write the recurrence, and trust the process.Start with Climbing Stairs. Write dp[i] in plain English before every problem. Solve everything twice β€” top-down and bottom-up. Do 50 problems with genuine reflection, not just accepted solutions.The click moment will come. And when it does, you'll wonder why it ever felt hard.

Dynamic ProgrammingMemoizationTabulationJavaOrigin StoryRichard Bellman
Ai Assistant Kas