Search Blogs

Showing results for "Postorder Traversal"

Found 4 results

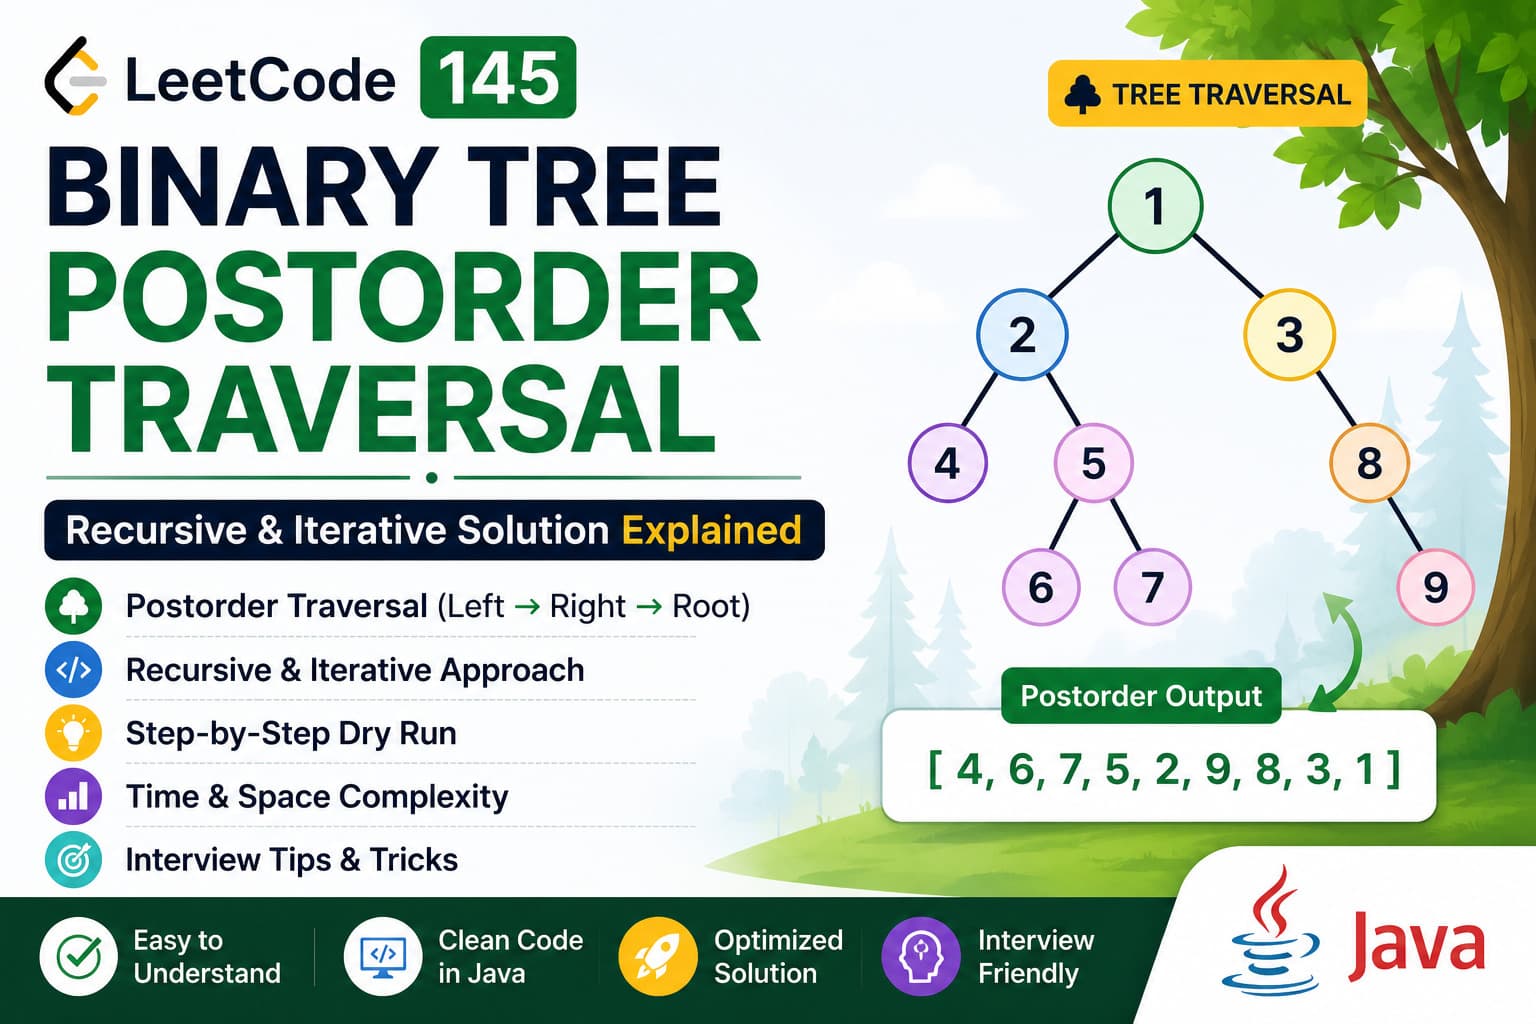
LeetCode 145: Binary Tree Postorder Traversal – Java Recursive & Iterative Solution Explained

LeetCode 145: Binary Tree Postorder Traversal – Java Recursive & Iterative Solution Explained

IntroductionLeetCode 145 – Binary Tree Postorder Traversal is one of the most important tree traversal problems for beginners learning Data Structures and Algorithms.This problem teaches:Binary Tree TraversalDepth First Search (DFS)RecursionStack-based traversalTree traversal patternsPostorder traversal is extremely useful in advanced tree problems such as:Tree deletionExpression tree evaluationBottom-up computationsDynamic programming on treesProblem LinkπŸ”— https://leetcode.com/problems/binary-tree-postorder-traversal/Problem StatementGiven the root of a binary tree, return the postorder traversal of its nodes' values.What is Postorder Traversal?In postorder traversal, nodes are visited in this order:Left β†’ Right β†’ RootUnlike preorder or inorder traversal, the root node is processed at the end.ExampleInputroot = [1,null,2,3]Tree Structure:1\2/3Postorder TraversalTraversal order:3 β†’ 2 β†’ 1Output:[3,2,1]Recursive Approach (Most Common)IntuitionIn postorder traversal:Traverse left subtreeTraverse right subtreeVisit current nodeThis naturally fits recursion because trees themselves are recursive structures.Recursive DFS VisualizationTraversal pattern:Left β†’ Right β†’ RootRecursive function:postorder(node.left)postorder(node.right)visit(node)Java Recursive Solution/*** Definition for a binary tree node.* public class TreeNode {* int val;* TreeNode left;* TreeNode right;* }*/class Solution {public void solve(List<Integer> list, TreeNode root) {if(root == null) return;solve(list, root.left);solve(list, root.right);list.add(root.val);}public List<Integer> postorderTraversal(TreeNode root) {List<Integer> list = new ArrayList<>();solve(list, root);return list;}}Dry Run – Recursive ApproachTree:1\2/3Step 1Start at:1Move left:nullReturn back.Step 2Move right to:2Move left to:3Left and right of 3 are null.Add:3Step 3Return to:2Add:2Step 4Return to:1Add:1Final Answer[3,2,1]Time Complexity – RecursiveTime ComplexityO(N)Every node is visited once.Space ComplexityO(H)Where:H = height of the treeRecursive call stack uses extra spaceWorst case:O(N)for skewed trees.Iterative Approach (Interview Follow-Up)The follow-up asks:Can you solve it iteratively?Yes.We use stacks to simulate recursion.Iterative Postorder IntuitionPostorder traversal order is:Left β†’ Right β†’ RootOne common trick is:Traverse in modified preorder:Root β†’ Right β†’ LeftReverse the result.After reversing, we get:Left β†’ Right β†’ Rootwhich is postorder traversal.Stack-Based Iterative LogicAlgorithmPush root into stack.Pop node.Add node value to answer.Push left child.Push right child.Reverse final answer.Java Iterative Solutionclass Solution {public List<Integer> postorderTraversal(TreeNode root) {LinkedList<Integer> ans = new LinkedList<>();if(root == null) return ans;Stack<TreeNode> stack = new Stack<>();stack.push(root);while(!stack.isEmpty()) {TreeNode node = stack.pop();ans.addFirst(node.val);if(node.left != null) {stack.push(node.left);}if(node.right != null) {stack.push(node.right);}}return ans;}}Dry Run – Iterative ApproachTree:1\2/3Step 1Push:1Step 2Pop:1Add at front:[1]Push right child:2Step 3Pop:2Add at front:[2,1]Push left child:3Step 4Pop:3Add at front:[3,2,1]Final Answer[3,2,1]Comparison of ApproachesApproachAdvantagesDisadvantagesRecursiveEasy to understandUses recursion stackIterativeBetter interview practiceSlightly harder logicInterview ExplanationIn interviews, explain:Postorder traversal processes nodes in Left β†’ Right β†’ Root order. Recursion naturally handles this traversal. Iteratively, we simulate recursion using a stack and reverse traversal order.This demonstrates strong tree traversal understanding.Common Mistakes1. Wrong Traversal OrderIncorrect:Root β†’ Left β†’ RightThat is preorder traversal.Correct postorder:Left β†’ Right β†’ Root2. Forgetting Null Base CaseAlways check:if(root == null) return;3. Incorrect Stack Push OrderFor iterative solution:Push left firstPush right secondbecause we reverse the result later.FAQsQ1. Why is postorder traversal useful?It is used in:Tree deletionExpression tree evaluationBottom-up dynamic programmingCalculating subtree informationQ2. Which approach is preferred in interviews?Recursive is simpler.Iterative is often asked as a follow-up.Q3. Can postorder traversal be done without stack or recursion?Yes.Using Morris Traversal.Q4. What is the difference between preorder, inorder, and postorder?TraversalOrderPreorderRoot β†’ Left β†’ RightInorderLeft β†’ Root β†’ RightPostorderLeft β†’ Right β†’ RootBonus: Morris Postorder TraversalMorris traversal performs tree traversal using:O(1)extra space.This is considered an advanced interview topic.ConclusionLeetCode 145 is an excellent beginner-friendly tree traversal problem.It teaches:DFS traversalRecursionStack simulationBinary tree fundamentalsThe key postorder pattern is:Left β†’ Right β†’ RootMastering this traversal helps in solving many advanced tree problems such as:Tree DPTree deletionExpression evaluationSubtree calculationsAdvanced DFS problems
LeetCodeBinary Tree Postorder TraversalBinary TreeTree TraversalJavaDFSStackRecursionEasy
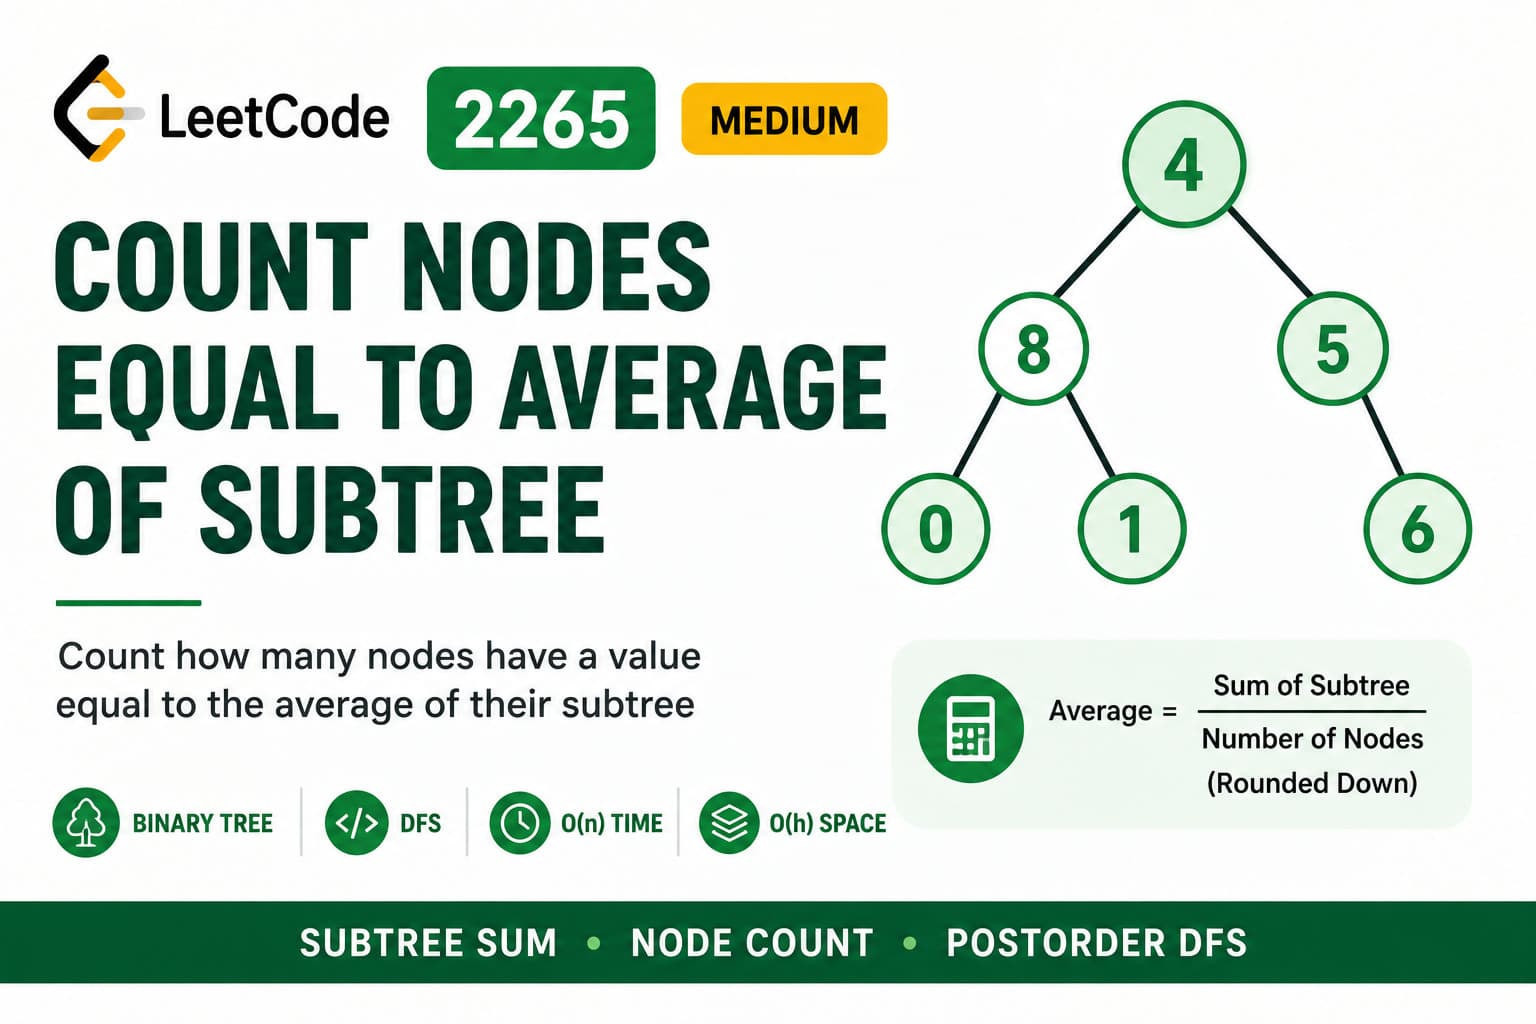
LeetCode 2265: Count Nodes Equal to Average of Subtree – Java DFS Solution

LeetCode 2265: Count Nodes Equal to Average of Subtree – Java DFS Solution

IntroductionBinary tree problems often become interesting when the answer for a node depends on everything below that node.This problem is exactly that.For every node, the task is to calculate the average of all values in its subtree and check whether that average is equal to the value of the node itself.At first, this looks like a simple DFS problem. But there is an important optimization opportunity hidden inside it.To calculate the average of a subtree, two things are required:The sum of all nodes in the subtreeThe number of nodes in the subtreeThe first approach calculates these values directly. Then, by looking at the repeated work, the solution can be improved further.Question LinkLeetCode 2265 – Count Nodes Equal to Average of SubtreeUnderstanding the ProblemFor every node:Average = Subtree Sum / Number of NodesThe average is rounded down.If the calculated average is equal to the current node's value, that node is counted.Consider this tree: 4 / \ 8 5 / \ \ 0 1 6For node 5:Subtree = [5, 6]Sum = 5 + 6 = 11Count = 2Average = 11 / 2 = 5Since the average is 5, node 5 contributes to the answer.The same calculation has to be performed for every node.The Core ObservationFor each node, the required information is:Subtree Sum+Subtree Node CountOnce these two values are available, calculating the average is straightforward.The natural question is:How can the sum and count of every subtree be calculated efficiently?A recursive DFS is a natural fit because the information of a subtree can be obtained by processing its children first.Approach 1: Calculate Subtree Sum and Count SeparatelyThe first approach is the most direct way to think about the problem.For every node:Calculate the sum of its entire subtree.Calculate the number of nodes in that subtree.Calculate the average.Compare it with the current node.Repeat for the left and right children.A separate count() function can be used to count the nodes.This approach follows the problem statement very closely, which makes it a good starting point for understanding the solution.CodeHere is the complete approach, including the separate count() idea:class Solution { int co = 0; // Calculates the sum of all nodes in the subtree public int sumdfs(TreeNode roo) { if (roo == null) { return 0; } // Leaf node contributes its value to the sum if (roo.left == null && roo.right == null) { co++; return roo.val; } int left = sumdfs(roo.left); int right = sumdfs(roo.right); // Current node is also part of its subtree co++; return roo.val + left + right; } // Separate function to count the number of nodes // in the subtree. // // This was the initial idea, but it is commented out // because the sumdfs() traversal can already count nodes. // // public int count(TreeNode roo){ // if(roo == null){ // return 0; // } // if(roo.left == null && roo.right == null){ // return 1; // } // int left = count(roo.left); // int right = count(roo.right); // return 1 + left + right; // } int am = 0; public void solve(TreeNode root) { if (root == null) { return; } // Reset count for the current subtree co = 0; // Calculate the sum of the current subtree // and count its nodes at the same time. int tot = sumdfs(root); int cot = co; // The problem requires the average to be rounded down. if (Math.floor(tot / cot) == root.val) { am++; } // Check the left subtree solve(root.left); // Check the right subtree solve(root.right); } public int averageOfSubtree(TreeNode root) { solve(root); return am; }}How This Approach WorksThe interesting part is sumdfs().Initially, a separate count() function can be used:int cot = count(root);At the same time, another traversal calculates the sum.But there is no need to traverse the same subtree again just to count its nodes.The sumdfs() function is already visiting every node, so the counter can be increased during the same traversal.That is why the following idea works:co++;Whenever a node is visited, co increases by one.After sumdfs(root) finishes:int tot = sumdfs(root);int cot = co;Now:tot = sum of subtreecot = number of nodes in subtreeand the average can be calculated.Dry RunConsider: 4 / \ 8 5 / \ \ 0 1 6Start from node 4.Node 0sum = 0count = 1average = 0 / 1 = 0So node 0 is counted.Node 1sum = 1count = 1average = 1 / 1 = 1Node 1 is counted.Node 8Its subtree is: 8 / \ 0 1Therefore:sum = 8 + 0 + 1 = 9count = 3average = 9 / 3 = 3Since:8 != 3node 8 is not counted.Node 6sum = 6count = 1average = 6Node 6 is counted.Node 5Its subtree is: 5 \ 6So:sum = 5 + 6 = 11count = 2average = 11 / 2 = 5Node 5 is counted.Node 4The complete subtree is: 4 / \ 8 5 / \ \ 0 1 6Therefore:sum = 4 + 8 + 5 + 0 + 1 + 6 = 24count = 6average = 24 / 6 = 4Node 4 is counted.The final answer is:5An Important Complexity ObservationThe co variable removes the need for a separate count() traversal.However, there is still a bigger issue.Look at what happens when solve() processes the root.It calls:sumdfs(root);which visits the entire tree.Then solve() moves to the left child and calls:sumdfs(root.left);which visits that subtree again.Then the same thing happens for the right subtree.So the same nodes can be visited many times.For example, in a skewed tree:1 \ 2 \ 3 \ 4 \ 5The first call processes:1 β†’ 2 β†’ 3 β†’ 4 β†’ 5The second processes:2 β†’ 3 β†’ 4 β†’ 5The third:3 β†’ 4 β†’ 5and so on.Therefore, although the co optimization is cleaner than using a separate count() traversal, the overall worst-case complexity can still reach:O(nΒ²)This observation leads directly to the optimal solution.Approach 2: Calculate Everything During One Postorder TraversalInstead of recalculating every subtree, the better idea is:Calculate the subtree information once and return it to the parent.For every node, the DFS can return two values:sumcountSuppose a node has:left subtree β†’ (leftSum, leftCount)right subtree β†’ (rightSum, rightCount)Then the current node can calculate:sum = root.val + leftSum + rightSumand:count = 1 + leftCount + rightCountNow the average is immediately available.After checking the current node, the pair:(sum, count)is returned to its parent.This means every node is processed exactly once.Why Postorder Traversal?The traversal order is:Left β†’ Right β†’ RootThis is called postorder traversal.It fits perfectly because the parent needs information from its children before it can calculate its own subtree information.For example: 4 / \ 8 5The algorithm first calculates information for:85and then combines them at:4This is a very common pattern in tree problems.Optimal Java SolutionA small Pair class can be used to return both the subtree sum and node count together.class Solution { int ans = 0; class Pair { int sum; int count; Pair(int sum, int count) { this.sum = sum; this.count = count; } } public Pair dfs(TreeNode root) { // Empty subtree if (root == null) { return new Pair(0, 0); } // Get sum and count from left subtree Pair left = dfs(root.left); // Get sum and count from right subtree Pair right = dfs(root.right); // Calculate information for current subtree int sum = root.val + left.sum + right.sum; int count = 1 + left.count + right.count; // Calculate subtree average int average = sum / count; // Check if current node equals its subtree average if (average == root.val) { ans++; } // Return current subtree information to parent return new Pair(sum, count); } public int averageOfSubtree(TreeNode root) { dfs(root); return ans; }}Why This Solution Is OptimalConsider node 4.Instead of recalculating its subtree from scratch, the algorithm receives:From 8:sum = 9count = 3and:From 5:sum = 11count = 2Then:sum = 4 + 9 + 11 = 24and:count = 1 + 3 + 2 = 6Therefore:average = 24 / 6 = 4The information is calculated once and passed upward.No subtree needs to be recalculated.Complexity AnalysisApproach 1The sumdfs() traversal can be repeated for every node.Time ComplexityO(nΒ²)in the worst case.Space ComplexityThe recursion stack depends on the height of the tree:O(h)Approach 2: One Postorder DFSEvery node is visited exactly once.At each node, only constant-time operations are performed.Time ComplexityO(n)Space ComplexityO(h)where h is the height of the tree.For a balanced tree:O(log n)For a skewed tree:O(n)A Small Java ImprovementThere is also a small simplification in the original code.The following expression:Math.floor(tot / cot)is unnecessary here.Because tot and cot are integers:tot / cotalready performs integer division.For example:11 / 2 = 5which is exactly the required rounded-down result because all node values are non-negative.Therefore, the comparison can simply be:if (tot / cot == root.val)The optimal solution uses:int average = sum / count;which is cleaner and easier to read.Approach ComparisonApproachMain IdeaTimeSpaceSeparate sum + countCalculate subtree information directlyO(nΒ²) worst caseO(h)Global co counterCount nodes during sum traversalO(nΒ²) worst caseO(h)One postorder DFSReturn sum + count to parentO(n)O(h)The second approach is a useful improvement over the first, but the third approach is the real optimization.What Can Be Learned From This Problem?This problem teaches an important binary-tree pattern:If a parent needs information about its entire subtree, calculate that information from the results returned by its children.Instead of repeatedly asking:"What is the sum of this subtree?""What is the count of this subtree?"the children calculate their information once and return it.The parent simply combines the results.This pattern appears in many tree problems involving:Subtree sumsSubtree sizesTree heightDiameterBalanced tree checkingMaximum path calculationsCounting nodes satisfying a conditionTree dynamic programmingA useful mental template is:Result dfs(Node root) { if (root == null) { return baseResult; } Result left = dfs(root.left); Result right = dfs(root.right); // Combine left + right + current node return result;}Once this pattern becomes familiar, many seemingly complicated tree problems become much easier to approach.Interview TipIf an interviewer asks for the straightforward solution first, it is perfectly reasonable to start with the direct recursive approach.But after getting it working, look for repeated subtree calculations.A strong follow-up thought process is:Am I visiting the same subtree multiple times? ↓Can I calculate its information once? ↓Can I return that information to the parent? ↓Postorder DFSThis is often the difference between an acceptable recursive solution and an optimal tree solution.ConclusionThe straightforward approach is a natural way to solve this problem: for each node, calculate the sum and number of nodes in its subtree, find the average, and check whether it matches the node's value.The first improvement is to notice that the same DFS used for calculating the sum can also maintain the node count using a shared counter instead of running a separate count() traversal.However, the bigger optimization comes from noticing that subtrees are still being recalculated.The optimal solution solves this by using one postorder DFS. Each node receives the sum and count from its children, calculates its own subtree information, checks the average, and passes the result to its parent.This changes the worst-case time complexity from:O(nΒ²)to:O(n)The most valuable takeaway is the pattern behind the solution:When a tree problem asks for information about a subtree, try to calculate that information once and return it upward through postorder DFS.

LeetCodeJavaBinary TreeDFSRecursionPostorder TraversalMedium
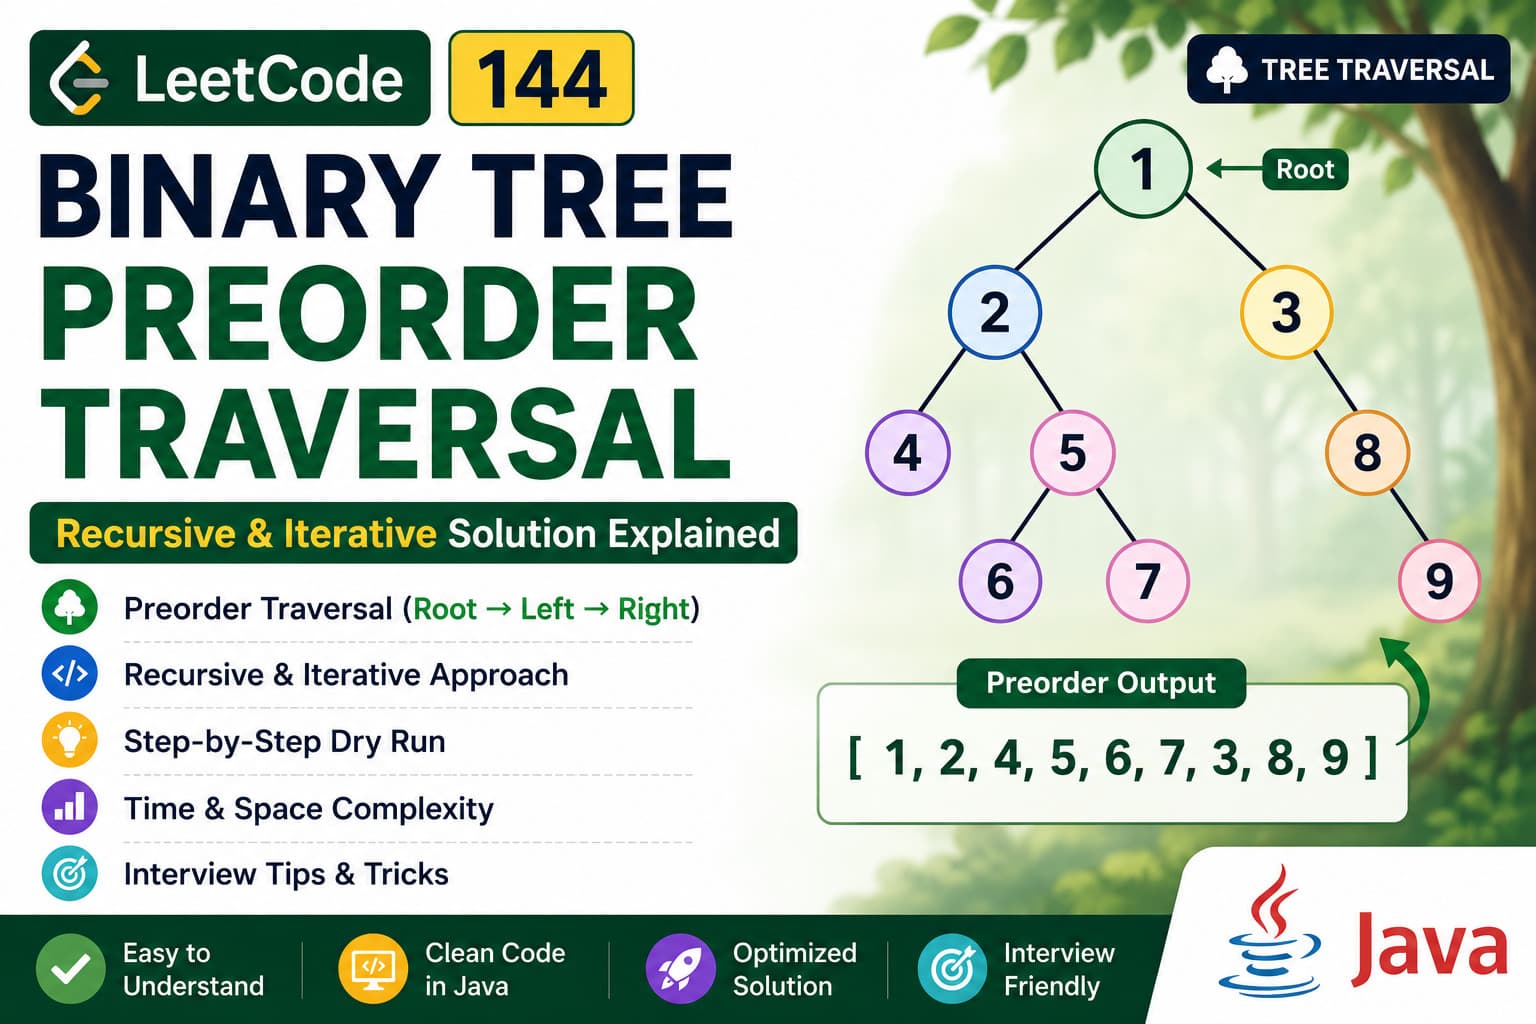
LeetCode 144: Binary Tree Preorder Traversal – Java Recursive & Iterative Solution Explained

LeetCode 144: Binary Tree Preorder Traversal – Java Recursive & Iterative Solution Explained

IntroductionLeetCode 144 – Binary Tree Preorder Traversal is one of the most important beginner-friendly tree traversal problems in Data Structures and Algorithms.This problem helps you understand:Binary Tree TraversalDepth First Search (DFS)RecursionStack-based traversalTree traversal patternsPreorder traversal is widely used in:Tree copyingSerializationExpression treesDFS-based problemsHierarchical data processingIt is also one of the most commonly asked tree problems in coding interviews.Problem LinkπŸ”— ProblemLeetCode 144: Binary Tree Preorder TraversalOfficial Problem:LeetCode Problem LinkProblem StatementGiven the root of a binary tree, return the preorder traversal of its nodes' values.What is Preorder Traversal?In preorder traversal, nodes are visited in this order:Root β†’ Left β†’ RightThe root node is processed first before traversing subtrees.ExampleInputroot = [1,null,2,3]Tree Structure:1\2/3Preorder TraversalTraversal order:1 β†’ 2 β†’ 3Output:[1,2,3]Recursive Approach (Most Common)IntuitionIn preorder traversal:Visit current nodeTraverse left subtreeTraverse right subtreeThis naturally fits recursion because trees themselves are recursive structures.Recursive DFS VisualizationTraversal pattern:Root β†’ Left β†’ RightRecursive function:visit(node)preorder(node.left)preorder(node.right)Java Recursive Solution/*** Definition for a binary tree node.* public class TreeNode {* int val;* TreeNode left;* TreeNode right;* }*/class Solution {public void solve(List<Integer> list, TreeNode root) {if(root == null) return;list.add(root.val);solve(list, root.left);solve(list, root.right);}public List<Integer> preorderTraversal(TreeNode root) {List<Integer> list = new ArrayList<>();solve(list, root);return list;}}Dry Run – Recursive ApproachTree:1\2/3Step 1Start at:1Add:1Move right to:2Step 2Add:2Move left to:3Step 3Add:3Final Answer[1,2,3]Time Complexity – RecursiveTime ComplexityO(N)Every node is visited once.Space ComplexityO(H)Where:H = height of treeRecursive call stack uses extra spaceWorst case:O(N)for skewed trees.Iterative Approach (Interview Follow-Up)The follow-up asks:Can you solve it iteratively?Yes.We use a stack to simulate recursion.Iterative Preorder IntuitionPreorder traversal order is:Root β†’ Left β†’ RightUsing a stack:Process current node immediatelyPush right child firstPush left child secondWhy?Because stacks follow:Last In First Out (LIFO)So left subtree gets processed first.Stack-Based Iterative LogicAlgorithmPush root into stack.Pop node.Add node value.Push right child.Push left child.Repeat until stack becomes empty.Java Iterative Solutionclass Solution {public List<Integer> preorderTraversal(TreeNode root) {List<Integer> ans = new ArrayList<>();if(root == null) return ans;Stack<TreeNode> stack = new Stack<>();stack.push(root);while(!stack.isEmpty()) {TreeNode node = stack.pop();ans.add(node.val);if(node.right != null) {stack.push(node.right);}if(node.left != null) {stack.push(node.left);}}return ans;}}Dry Run – Iterative ApproachTree:1\2/3Step 1Push:1Step 2Pop:1Add:[1]Push right child:2Step 3Pop:2Add:[1,2]Push left child:3Step 4Pop:3Add:[1,2,3]Final Answer[1,2,3]Comparison of ApproachesApproachAdvantagesDisadvantagesRecursiveEasy to understandUses recursion stackIterativeBetter interview practiceSlightly harder logicInterview ExplanationIn interviews, explain:Preorder traversal processes nodes in Root β†’ Left β†’ Right order. Recursion naturally handles this traversal. Iteratively, we use a stack and push the right child before the left child so the left subtree gets processed first.This demonstrates strong DFS and stack understanding.Common Mistakes1. Wrong Traversal OrderIncorrect:Left β†’ Root β†’ RightThat is inorder traversal.Correct preorder:Root β†’ Left β†’ Right2. Forgetting Null Base CaseAlways check:if(root == null) return;3. Wrong Stack Push OrderFor iterative traversal:Push right firstPush left secondOtherwise traversal order becomes incorrect.FAQsQ1. Why is preorder traversal useful?It is heavily used in:Tree cloningSerializationDFS traversalExpression treesQ2. Which approach is preferred in interviews?Recursive is simpler.Iterative is often asked as a follow-up.Q3. Can preorder traversal be done without stack or recursion?Yes.Using Morris Traversal.Q4. What is the difference between preorder, inorder, and postorder?TraversalOrderPreorderRoot β†’ Left β†’ RightInorderLeft β†’ Root β†’ RightPostorderLeft β†’ Right β†’ RootBonus: Morris Preorder TraversalMorris traversal performs preorder traversal using:O(1)extra space.This is considered an advanced interview topic.ConclusionLeetCode 144 is one of the most fundamental binary tree traversal problems.It teaches:DFS traversalRecursionStack simulationBinary tree fundamentalsThe key preorder pattern is:Root β†’ Left β†’ RightMastering this traversal builds a strong foundation for advanced tree problems such as:Tree serializationDFS-based problemsTree reconstructionExpression treesMorris traversal

LeetCodeBinary Tree Preorder TraversalBinary TreeTree TraversalJavaDFSStackRecursionEasy
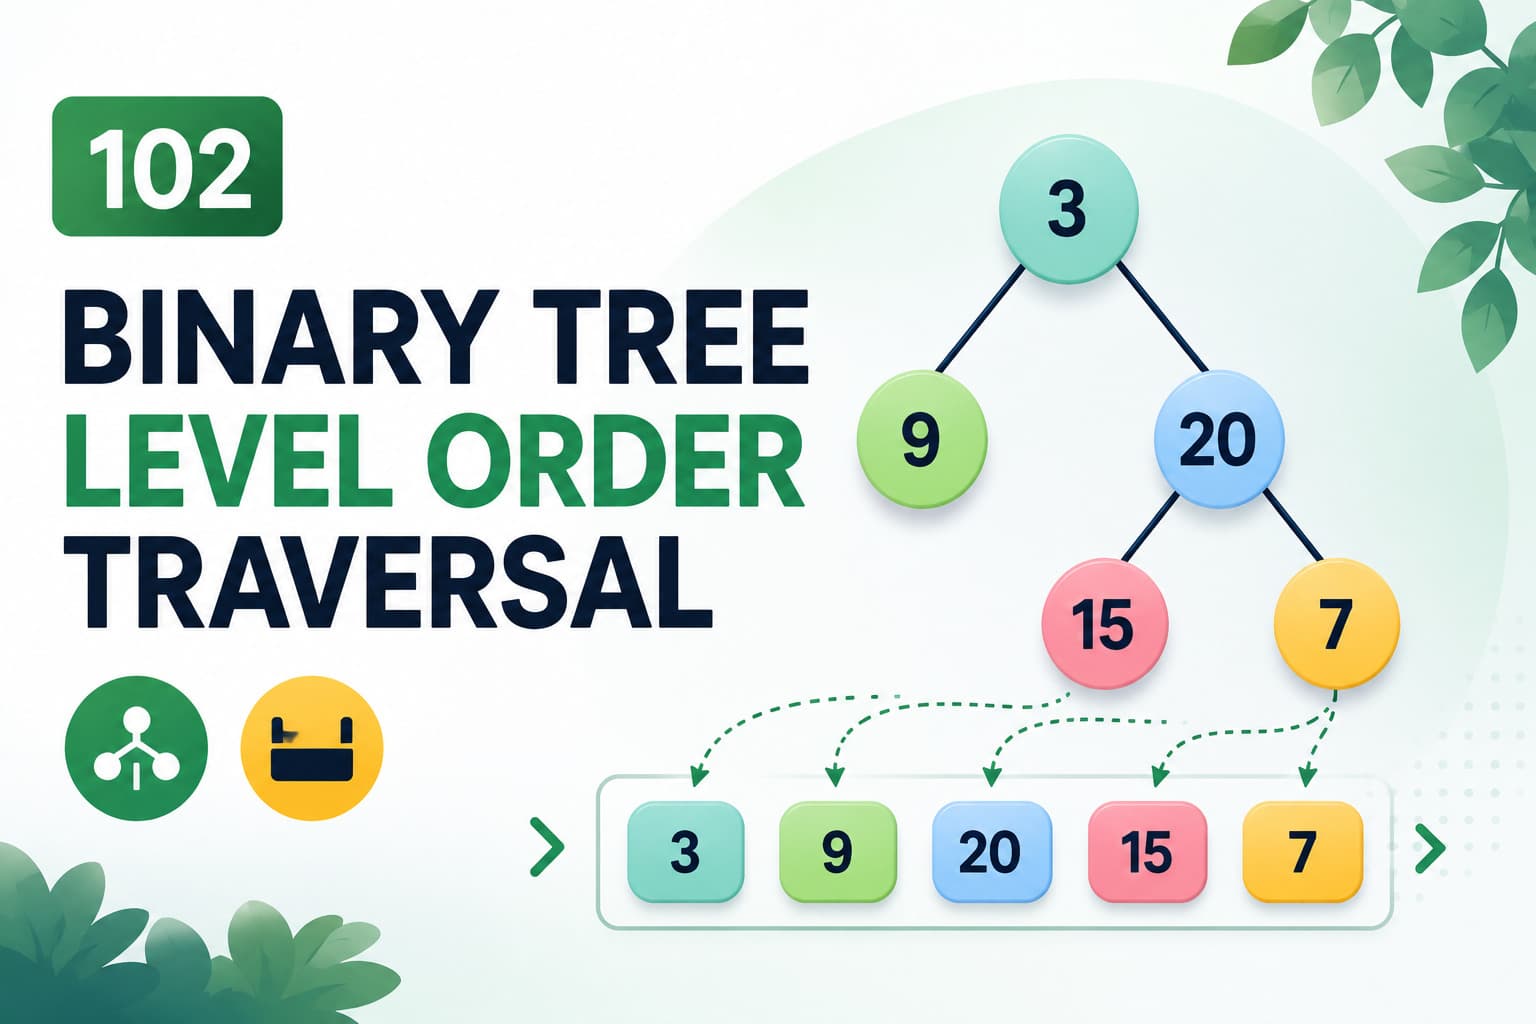
LeetCode 102: Binary Tree Level Order Traversal – Java BFS Solution Explained

LeetCode 102: Binary Tree Level Order Traversal – Java BFS Solution Explained

IntroductionLeetCode 102 – Binary Tree Level Order Traversal is one of the most important Binary Tree traversal problems for coding interviews.This problem introduces:Breadth First Search (BFS)Queue data structureLevel-by-level traversalTree traversal patternsInterview-level BFS thinkingUnlike DFS traversals like preorder, inorder, and postorder, this problem explores the tree level by level.This traversal is widely used in:Graph traversalShortest path problemsTree serializationZigzag traversalBFS-based interview questionsProblem LinkπŸ”— https://leetcode.com/problems/binary-tree-level-order-traversal/Problem StatementGiven the root of a binary tree, return the level order traversal of its nodes' values.Traversal should happen:Level by levelLeft to rightExampleInputroot = [3,9,20,null,null,15,7]Tree Structure: 3 / \ 9 20 / \ 15 7Level Order TraversalLevel 1:[3]Level 2:[9,20]Level 3:[15,7]Final Output:[[3],[9,20],[15,7]]Understanding the ProblemThe main challenge is:Process nodes level by level.This is exactly what:Breadth First Search (BFS)is designed for.Why Queue is Used?A queue follows:First In First Out (FIFO)This ensures:Nodes are processed in insertion orderParent nodes are processed before child nodesLevels are traversed correctlyBrute Force IntuitionOne brute force idea is:Calculate height of treeTraverse each level separatelyStore nodes level by levelBrute Force ComplexityThis approach becomes inefficient because:Each level traversal may revisit nodesComplexity may become:O(NΒ²)for skewed trees.Optimal BFS IntuitionInstead of traversing each level separately:Use a queueProcess nodes level by level naturallyAt every level:Store queue sizeProcess exactly those many nodesAdd children into queueMove to next levelKey BFS ObservationBefore processing a level:int size = queue.size();This tells us:How many nodes belong to the current level.BFS AlgorithmSteps1. Initialize QueueInsert root node.2. Process Until Queue Becomes EmptyWhile queue is not empty:Find current level sizeTraverse current levelStore valuesPush child nodes3. Store Current LevelAfter processing one level:ans.add(levelList);Java BFS Solution/** * Definition for a binary tree node. * public class TreeNode { * int val; * TreeNode left; * TreeNode right; * } */class Solution { public List<List<Integer>> levelOrder(TreeNode root) { List<List<Integer>> ans = new ArrayList<>(); Queue<TreeNode> queue = new LinkedList<>(); if(root == null) return ans; queue.offer(root); while(!queue.isEmpty()) { int size = queue.size(); List<Integer> level = new ArrayList<>(); for(int i = 0; i < size; i++) { root = queue.poll(); level.add(root.val); if(root.left != null) queue.offer(root.left); if(root.right != null) queue.offer(root.right); } ans.add(level); } return ans; }}Dry RunInputroot = [3,9,20,null,null,15,7]Tree: 3 / \ 9 20 / \ 15 7Initial Queue[3]Level 1Queue size:1Process:3Add children:9, 20Level result:[3]Queue now:[9,20]Level 2Queue size:2Process:9, 20Add children:15, 7Level result:[9,20]Queue now:[15,7]Level 3Queue size:2Process:15, 7Level result:[15,7]Queue becomes empty.Final Answer[[3],[9,20],[15,7]]Time Complexity AnalysisTime ComplexityO(N)Every node is visited exactly once.Space ComplexityO(N)Queue may store an entire level of nodes.DFS Alternative ApproachThis problem can also be solved using DFS recursion.Idea:Pass current level during recursionCreate new list when level appears first timeAdd node into correct level listJava DFS Solutionclass Solution { public void dfs(TreeNode root, int level, List<List<Integer>> ans) { if(root == null) return; if(level == ans.size()) { ans.add(new ArrayList<>()); } ans.get(level).add(root.val); dfs(root.left, level + 1, ans); dfs(root.right, level + 1, ans); } public List<List<Integer>> levelOrder(TreeNode root) { List<List<Integer>> ans = new ArrayList<>(); dfs(root, 0, ans); return ans; }}BFS vs DFS for Level Order TraversalApproachAdvantagesDisadvantagesBFSNatural level traversalUses queueDFSRecursive solutionSlightly harder intuitionInterview ExplanationIn interviews, explain:Level order traversal is a BFS problem because we process nodes level by level. A queue naturally supports this traversal order.This demonstrates strong BFS understanding.Common Mistakes1. Forgetting Queue SizeWithout storing:int size = queue.size();levels cannot be separated correctly.2. Using DFS IncorrectlySimple DFS alone does not guarantee level ordering.3. Forgetting Null CheckAlways handle:if(root == null)FAQsQ1. Why is BFS preferred here?Because BFS naturally processes nodes level by level.Q2. Can this problem be solved recursively?Yes.Using DFS with level tracking.Q3. What data structure is mainly used?Queue.Q4. Is Level Order Traversal important?Yes.It is one of the most frequently asked BFS tree problems.Related ProblemsAfter mastering this problem, practice:Binary Tree Zigzag Level Order TraversalAverage of Levels in Binary TreeRight Side View of Binary TreeBinary Tree Vertical Order TraversalMaximum Depth of Binary TreeConclusionLeetCode 102 is one of the most important BFS tree traversal problems.It teaches:BFS traversalQueue usageLevel-by-level processingTree traversal fundamentalsThe key idea is:Use queue size to separate levels.Once this intuition becomes clear, many BFS-based tree interview problems become much easier.

LeetCodeBinary Tree Level Order TraversalBFSQueueBinary TreeJavaTree TraversalMedium
Ai Assistant Kas