Search Blogs

Showing results for "DSA"

Found 26 results

Count the Number of Good Subarrays – Apple OA DSA Problem & Java Solution

Count the Number of Good Subarrays – Apple OA DSA Problem & Java Solution

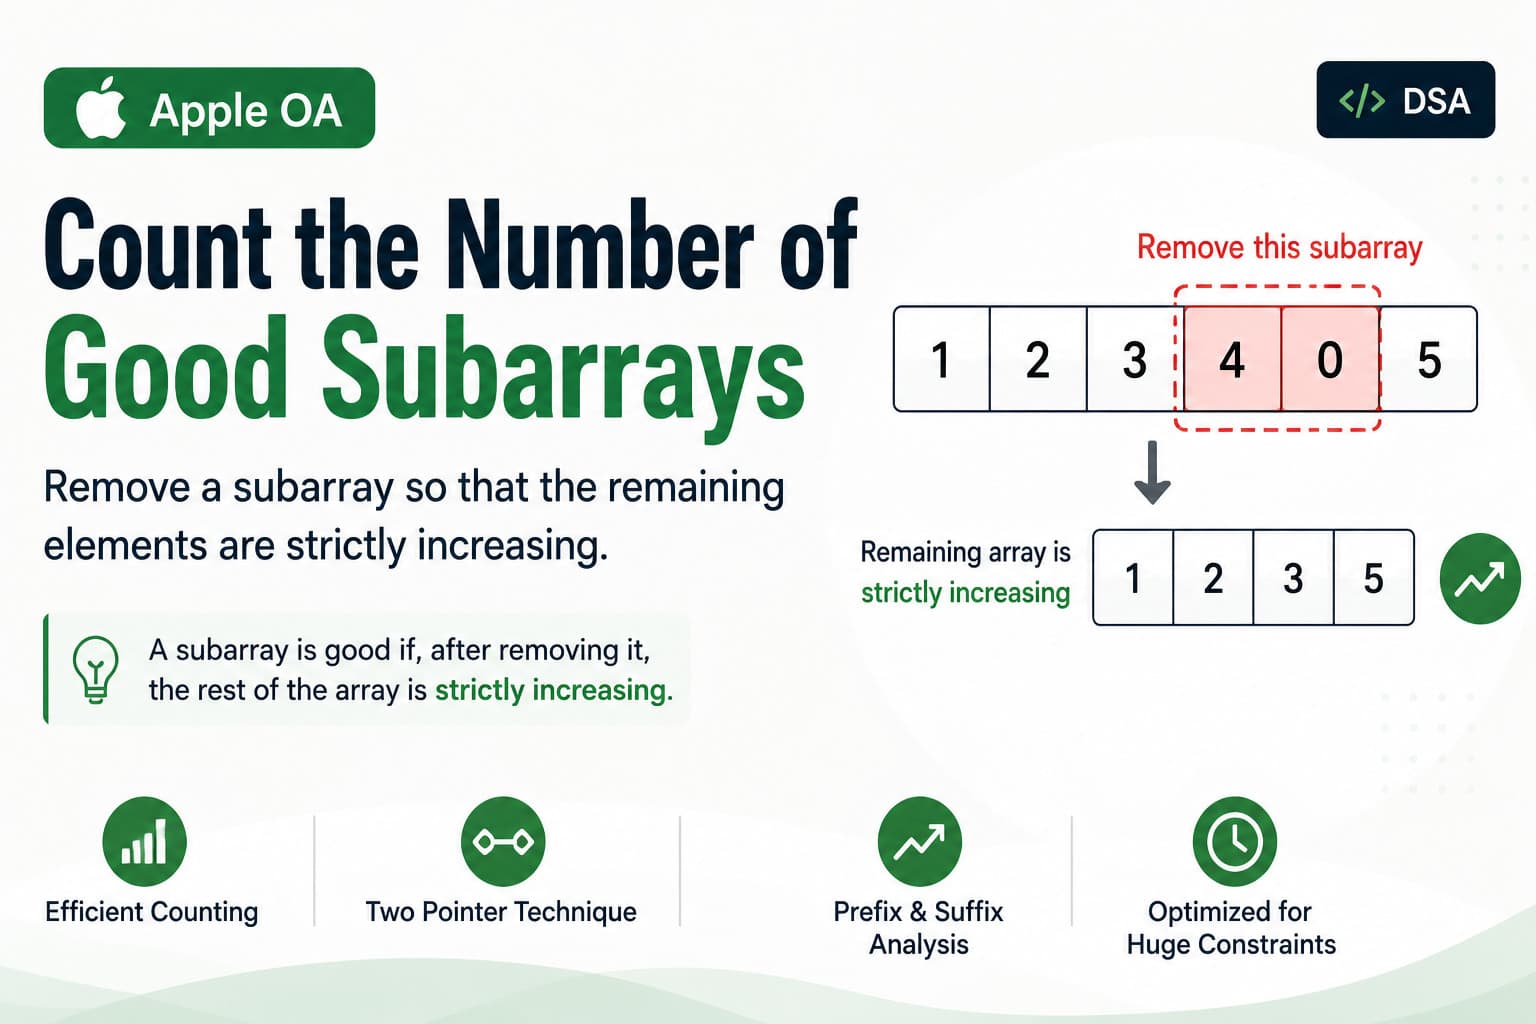
IntroductionThis is an interesting question asked in the Apple OA because the condition is slightly different from the usual subarray problems.Instead of asking whether a subarray itself satisfies some property, the task is to remove a subarray and check whether the elements left behind are strictly increasing.The challenge is to count every possible contiguous subarray whose removal leaves a strictly increasing sequence.With n as large as 10⁵, a direct brute-force solution becomes extremely expensive, making this a good problem for thinking about how the structure of the array can be exploited.Problem StatementGiven an integer array arr of size n, find the number of good subarrays.A subarray arr[l...r] is called good if, after removing all elements from index l through r, the remaining elements form a strictly increasing array.In other words, after removing:arr[l], arr[l+1], ..., arr[r]the elements before l and after r are joined together.The resulting array must satisfy:remaining[i] < remaining[i + 1]for every pair of adjacent elements.Constraints1 ≤ n ≤ 10⁵-10⁹ ≤ arr[i] ≤ 10⁹ExampleConsider:arr = [1, 2, 3, 4, 0, 5]There are 10 good subarrays.Some valid removals are:[0][0, 5][4, 0][4, 0, 5][3, 4, 0][3, 4, 0, 5][2, 3, 4, 0][2, 3, 4, 0, 5][1, 2, 3, 4, 0][1, 2, 3, 4]For example, removing:[3, 4, 0]from:[1, 2, 3, 4, 0, 5]leaves:[1, 2, 5]which is strictly increasing.Therefore, [3,4,0] is a good subarray.Similarly, removing:[0,5]leaves:[1,2,3,4]which is also strictly increasing.Hence:Answer = 10Key ObservationThe array:[1, 2, 3, 4, 0, 5]is already strictly increasing except around:4 → 0Removing a suitable contiguous section containing this problematic portion can reconnect two increasing parts.For example:[1, 2, 3, 4] [0, 5]Removing [0] gives:[1, 2, 3, 4, 5]Removing [4,0] gives:[1, 2, 3, 5]Removing [3,4,0] gives:[1, 2, 5]The important condition is therefore not just whether the removed part is valid. The remaining left and right portions must also connect correctly.Brute-Force Backtracking ApproachA straightforward way to explore the problem is to generate possible selections of indices using recursion.The recursive function maintains:currwhich contains the indices currently selected for removal.For every index, there are two choices:Include the index in the selected set.Do not include the index.Once a selection is created, the ch2() function removes those selected positions and checks whether the remaining array is strictly increasing.A HashSet is also used to avoid counting the same index selection more than once.Checking a CandidateThe ch2() function performs the validation.It first creates an array containing the elements that were not selected for removal.For example:Original:[1, 2, 3, 4, 0, 5]Selected indices:[2, 3, 4]Remaining:[1, 2, 5]Then the remaining array is scanned.If any adjacent pair violates:arr[i] < arr[i + 1]the candidate is rejected.Otherwise, it is considered good.Java SolutionThe following is the provided recursive implementation, with comments added to make the logic easier to follow.public class question {// Stores already counted selections.static int an = 0;static HashSet<List<Integer>> msl = new HashSet<>();// Checks whether removing the selected indices// leaves a strictly increasing array.public static boolean ch2(List<Integer> lis, int[] arr) {// No selected elements means nothing is removed.if (lis.size() == 0) {return false;}// If the entire array is removed,// this implementation does not count it.int[] dum = new int[arr.length - lis.size()];if (dum.length == 0) {return false;}// Store the selected indices.HashSet<Integer> ms = new HashSet<>();for (int a : lis) {ms.add(a);}int c = 0;// Construct the remaining array.for (int i = 0; i < arr.length; i++) {// Keep only indices that were not selected.if (!ms.contains(i)) {dum[c] = arr[i];c++;}}// Check whether the remaining array// is strictly increasing.for (int i = 0; i < dum.length - 1; i++) {if (dum[i] > dum[i + 1]) {return false;}}return true;}public static void main(String[] args) {int[] arr = {1, 2, 3, 4, 0, 5};List<Integer> lis = new ArrayList<>();if (arr.length == 1) {System.out.println(1);}// Explore both possibilities for the first index.sol2(arr, 0, lis, true);sol2(arr, 0, lis, false);System.out.println(an);}// Generates different selections using recursion.public static void sol2(int[] arr,int ind,List<Integer> lis,boolean boo) {// All indices have been processed.if (ind == arr.length) {// Check whether this selection is good// and has not already been counted.if (!msl.contains(lis) && ch2(lis, arr)) {an++;// Store a copy because the original list// continues changing during backtracking.msl.add(new ArrayList<>(lis));System.out.println(lis);}return;}// Check the current selection as well.if (!msl.contains(lis) && ch2(lis, arr)) {an++;msl.add(new ArrayList<>(lis));System.out.println(lis);}// Include the current index.if (boo) {lis.add(ind);}// Continue recursively.sol2(arr, ind + 1, lis, true);// Backtrack and remove the last selected index.if (lis.size() != 0) {lis.remove(lis.size() - 1);}// Explore the branch where the current index// is not selected.sol2(arr, ind + 1, lis, false);}}Dry RunFor:[1, 2, 3, 4, 0, 5]Suppose the selected indices are:[4]Index 4 contains 0.Removing it gives:[1, 2, 3, 4, 5]This is strictly increasing.Therefore:[0]is counted.Now consider:[3, 4]Removing indices 2 and 3 gives:[1, 2, 0, 5]Since:2 > 0the remaining array is not increasing.Therefore, this candidate is rejected.Another candidate:[2, 3, 4]removes:[3, 4, 0]and leaves:[1, 2, 5]which is strictly increasing.So this candidate is counted.The recursion continues until all possible selections have been explored.Important Detail: Subarray vs SubsetThere is an important distinction worth understanding when reviewing this implementation.The problem asks for a subarray, which means the removed elements must be contiguous.For example:[2, 3, 4]is a subarray.But:[2, 4]is not a subarray if the original array contains another element between them.The recursive code, however, chooses individual indices independently. Therefore, it explores subsets of indices rather than explicitly restricting the selection to contiguous ranges.This is an important conceptual difference.For a production or interview solution, the recursion should be changed to work directly with:left indexright indexso that only contiguous removals are considered.Why This Approach Is Not Suitable for n = 10⁵For every index, the recursion can make two choices:includeexcludeThis creates approximately:2ⁿpossible selections.Furthermore, each candidate is checked by constructing another array and scanning it.Therefore, the brute-force approach grows exponentially and cannot handle:n = 100000efficiently.This makes the problem much more interesting: the real challenge is finding the structure that allows the count to be obtained without examining every possible subarray individually.Toward an Optimized SolutionA useful way to analyze the problem is to split the remaining array into two parts.After removing arr[l...r], the remaining array is:arr[0...l-1] + arr[r+1...n-1]For this combined array to be strictly increasing, three things must be true:Left part must be increasingarr[0...l-1]must already be strictly increasing.Right part must be increasingarr[r+1...n-1]must already be strictly increasing.The two parts must connectIf both parts exist:arr[l-1] < arr[r+1]must hold.This observation removes the need to construct the remaining array for every candidate.The Main PatternThe problem can therefore be viewed as:Increasing Prefix|| removed subarray↓Increasing SuffixThe only difficult part is determining whether the last element of the prefix can connect to the first element of the suffix.This is the key observation that leads from brute force toward an efficient two-pointer/prefix-suffix based solution.Complexity of the Provided SolutionThe recursive generation can explore up to:O(2ⁿ)different index selections.For every candidate, ch2() may also scan the entire array.Therefore, the overall worst-case complexity is approximately:O(n × 2ⁿ)with substantial additional memory for the recursion and stored selections.This is only practical for very small arrays and should be considered a brute-force exploration, not a solution for the stated n = 10⁵ constraint.Interview TakeawayThis problem teaches an important DSA lesson:Before optimizing code, identify exactly what the problem is asking for.There is a significant difference between:subsetand:subarrayA subset can select arbitrary indices, while a subarray must be contiguous.Once the problem is represented correctly, the next question becomes:What must be true about the array remaining after removing [l...r]?That leads directly to the prefix/suffix observation:Left side increasing+Right side increasing+Left boundary < Right boundaryThis type of transformation is often much more valuable in an OA than trying to optimize an exponential recursion line by line.ConclusionThis Apple OA-style problem combines subarray reasoning, recursion, and array properties in an interesting way.The provided solution takes a brute-force route by recursively exploring possible index selections and checking whether the remaining elements form a strictly increasing sequence.Although this approach is useful for understanding the problem and verifying small test cases, the constraint of 10⁵ requires a much more efficient strategy.The major insight is to stop thinking about the removed portion itself and instead analyze the increasing prefix and increasing suffix that remain after the removal.That shift in perspective turns an exponential search problem into one that can be approached using prefix/suffix preprocessing and two-pointer techniques.
Apple OAArraysSubarraysRecursionBacktrackingHashSetBrute ForceJavaContignous Array
Recursion in Java - Complete Guide With Examples and Practice Problems

Recursion in Java - Complete Guide With Examples and Practice Problems

IntroductionIf there is one topic in programming that confuses beginners more than anything else, it is recursion. Most people read the definition, nod their head, and then immediately freeze when they have to write recursive code themselves.The problem is not that recursion is genuinely hard. The problem is that most explanations start with code before building the right mental model. Once you have the right mental model, recursion clicks permanently and you start seeing it everywhere — in tree problems, graph problems, backtracking, dynamic programming, divide and conquer, and more.This guide covers everything from the ground up. What recursion is, how the call stack works, how to identify base cases and recursive cases, every type of recursion, common patterns, time and space complexity analysis, the most common mistakes, and the top LeetCode problems to practice.By the end of this article, recursion will not feel like magic anymore. It will feel like a natural tool you reach for confidently.What Is Recursion?Recursion is when a function calls itself to solve a smaller version of the same problem.That is the complete definition. But let us make it concrete.Imagine you want to count down from 5 to 1. One way is a loop. Another way is — print 5, then solve the exact same problem for counting down from 4 to 1. Then print 4, solve for 3. And so on until you reach the base — there is nothing left to count down.void countDown(int n) { if (n == 0) return; // stop here System.out.println(n); countDown(n - 1); // solve the smaller version}The function countDown calls itself with a smaller input each time. Eventually it reaches 0 and stops. That stopping condition is the most important part of any recursive function — the base case.The Two Parts Every Recursive Function Must HaveEvery correctly written recursive function has exactly two parts. Without both, the function either gives wrong answers or runs forever.Part 1: Base CaseThe base case is the condition under which the function stops calling itself and returns a direct answer. It is the smallest version of the problem that you can solve without any further recursion.Without a base case, recursion never stops and you get a StackOverflowError — Java's way of telling you the call stack ran out of memory.Part 2: Recursive CaseThe recursive case is where the function calls itself with a smaller or simpler input — moving closer to the base case with each call. If your recursive case does not make the problem smaller, you have an infinite loop.Think of it like a staircase. The base case is the ground floor. The recursive case is each step going down. Every step must genuinely bring you one level closer to the ground.How Recursion Works — The Call StackThis is the mental model that most explanations skip, and it is the reason recursion confuses people.Every time a function is called in Java, a new stack frame is created and pushed onto the call stack. This frame stores the function's local variables, parameters, and where to return to when the function finishes.When a recursive function calls itself, a new frame is pushed on top. When that call finishes, its frame is popped and execution returns to the previous frame.Let us trace countDown(3) through the call stack:countDown(3) called → frame pushed prints 3 calls countDown(2) → frame pushed prints 2 calls countDown(1) → frame pushed prints 1 calls countDown(0) → frame pushed n == 0, return → frame popped back in countDown(1), return → frame popped back in countDown(2), return → frame popped back in countDown(3), return → frame poppedOutput: 3, 2, 1The call stack grows as calls go deeper, then shrinks as calls return. This is why recursion uses O(n) space for n levels deep — each level occupies one stack frame in memory.Your First Real Recursive Function — FactorialFactorial is the classic first recursion example. n! = n × (n-1) × (n-2) × ... × 1Notice the pattern — n! = n × (n-1)!. The factorial of n is n times the factorial of n-1. That recursive structure makes it perfect for recursion.public int factorial(int n) { // base case if (n == 0 || n == 1) return 1; // recursive case return n * factorial(n - 1);}Dry Run — factorial(4)factorial(4)= 4 * factorial(3)= 4 * 3 * factorial(2)= 4 * 3 * 2 * factorial(1)= 4 * 3 * 2 * 1= 24The call stack builds up going in, then multiplications happen coming back out. This "coming back out" phase is called the return phase or unwinding of the stack.Time Complexity: O(n) — n recursive calls Space Complexity: O(n) — n frames on the call stackThe Two Phases of RecursionEvery recursive function has two phases and understanding both is critical.Phase 1: The Call Phase (Going In)This happens as the function keeps calling itself with smaller inputs. Things you do before the recursive call happen in this phase — in order from the outermost call to the innermost.Phase 2: The Return Phase (Coming Back Out)This happens as each call finishes and returns to its caller. Things you do after the recursive call happen in this phase — in reverse order, from the innermost call back to the outermost.This distinction explains why the output order can be surprising:void printBothPhases(int n) { if (n == 0) return; System.out.println("Going in: " + n); // call phase printBothPhases(n - 1); System.out.println("Coming out: " + n); // return phase}For printBothPhases(3):Going in: 3Going in: 2Going in: 1Coming out: 1Coming out: 2Coming out: 3This two-phase understanding is what makes problems like reversing a string or printing a linked list backwards via recursion feel natural.Types of RecursionRecursion is not one-size-fits-all. There are several distinct types and knowing which type applies to a problem shapes how you write the solution.1. Direct RecursionThe function calls itself directly. This is the most common type — what we have seen so far.void direct(int n) { if (n == 0) return; direct(n - 1); // calls itself}2. Indirect RecursionFunction A calls Function B which calls Function A. They form a cycle.void funcA(int n) { if (n <= 0) return; System.out.println("A: " + n); funcB(n - 1);}void funcB(int n) { if (n <= 0) return; System.out.println("B: " + n); funcA(n - 1);}Used in: state machines, mutual recursion in parsers, certain mathematical sequences.3. Tail RecursionThe recursive call is the last operation in the function. Nothing happens after the recursive call returns — no multiplication, no addition, nothing.// NOT tail recursive — multiplication happens after returnint factorial(int n) { if (n == 1) return 1; return n * factorial(n - 1); // multiply after return — not tail}// Tail recursive — recursive call is the last thingint factorialTail(int n, int accumulator) { if (n == 1) return accumulator; return factorialTail(n - 1, n * accumulator); // last operation}Why does tail recursion matter? In languages that support tail call optimization (like Scala, Kotlin, and many functional languages), tail recursive functions can be converted to iteration internally — no stack frame accumulation, O(1) space. Java does NOT perform tail call optimization, but understanding tail recursion is still important for interviews and functional programming concepts.4. Head RecursionThe recursive call happens first, before any other processing. All processing happens in the return phase.void headRecursion(int n) { if (n == 0) return; headRecursion(n - 1); // call first System.out.println(n); // process after}// Output: 1 2 3 4 5 (processes in reverse order of calls)5. Tree RecursionThe function makes more than one recursive call per invocation. This creates a tree of calls rather than a linear chain. Fibonacci is the classic example.int fibonacci(int n) { if (n <= 1) return n; return fibonacci(n - 1) + fibonacci(n - 2); // TWO recursive calls}The call tree for fibonacci(4): fib(4) / \ fib(3) fib(2) / \ / \ fib(2) fib(1) fib(1) fib(0) / \ fib(1) fib(0)Time Complexity: O(2ⁿ) — exponential! Each call spawns two more. Space Complexity: O(n) — maximum depth of the call treeThis is why memoization (caching results) is so important for tree recursion — it converts O(2ⁿ) to O(n) by never recomputing the same subproblem twice.6. Mutual RecursionA specific form of indirect recursion where two functions call each other alternately to solve a problem. Different from indirect recursion in that the mutual calls are the core mechanism of the solution.// Check if a number is even or odd using mutual recursionboolean isEven(int n) { if (n == 0) return true; return isOdd(n - 1);}boolean isOdd(int n) { if (n == 0) return false; return isEven(n - 1);}Common Recursion Patterns in DSAThese are the patterns you will see over and over in interview problems. Recognizing them is more important than memorizing solutions.Pattern 1: Linear Recursion (Do Something, Recurse on Rest)Process the current element, then recurse on the remaining problem.// Sum of arrayint arraySum(int[] arr, int index) { if (index == arr.length) return 0; // base case return arr[index] + arraySum(arr, index + 1); // current + rest}Pattern 2: Divide and Conquer (Split Into Two Halves)Split the problem into two halves, solve each recursively, combine results.// Merge Sortvoid mergeSort(int[] arr, int left, int right) { if (left >= right) return; // base case — single element int mid = (left + right) / 2; mergeSort(arr, left, mid); // sort left half mergeSort(arr, mid + 1, right); // sort right half merge(arr, left, mid, right); // combine}Pattern 3: Backtracking (Try, Recurse, Undo)Try a choice, recurse to explore it, undo the choice when backtracking.// Generate all subsetsvoid subsets(int[] nums, int index, List<Integer> current, List<List<Integer>> result) { if (index == nums.length) { result.add(new ArrayList<>(current)); return; } // Choice 1: include nums[index] current.add(nums[index]); subsets(nums, index + 1, current, result); current.remove(current.size() - 1); // undo // Choice 2: exclude nums[index] subsets(nums, index + 1, current, result);}Pattern 4: Tree Recursion (Left, Right, Combine)Recurse on left subtree, recurse on right subtree, combine or process results.// Height of binary treeint height(TreeNode root) { if (root == null) return 0; // base case int leftHeight = height(root.left); // solve left int rightHeight = height(root.right); // solve right return 1 + Math.max(leftHeight, rightHeight); // combine}Pattern 5: Memoization (Cache Recursive Results)Store results of recursive calls so the same subproblem is never solved twice.Map<Integer, Integer> memo = new HashMap<>();int fibonacci(int n) { if (n <= 1) return n; if (memo.containsKey(n)) return memo.get(n); // return cached int result = fibonacci(n - 1) + fibonacci(n - 2); memo.put(n, result); // cache before returning return result;}This converts Fibonacci from O(2ⁿ) to O(n) time with O(n) space — a massive improvement.Recursion vs Iteration — When to Use WhichThis is one of the most common interview questions about recursion. Here is a clear breakdown:Use Recursion when:The problem has a naturally recursive structure (trees, graphs, divide and conquer)The solution is significantly cleaner and easier to understand recursivelyThe problem involves exploring multiple paths or choices (backtracking)The depth of recursion is manageable (not too deep to cause stack overflow)Use Iteration when:The problem is linear and a loop is equally clearMemory is a concern (iteration uses O(1) stack space vs O(n) for recursion)Performance is critical and function call overhead mattersJava's stack size limit could be hit (default around 500-1000 frames for deep recursion)The key rule: Every recursive solution can be converted to an iterative one (usually using an explicit stack). But recursive solutions for tree and graph problems are almost always cleaner to write and understand.Time and Space Complexity of Recursive FunctionsAnalyzing complexity for recursive functions requires a specific approach.The Recurrence Relation MethodExpress the time complexity as a recurrence relation and solve it.Factorial:T(n) = T(n-1) + O(1) = T(n-2) + O(1) + O(1) = T(1) + n×O(1) = O(n)Fibonacci (naive):T(n) = T(n-1) + T(n-2) + O(1) ≈ 2×T(n-1) = O(2ⁿ)Binary Search:T(n) = T(n/2) + O(1) = O(log n) [by Master Theorem]Merge Sort:T(n) = 2×T(n/2) + O(n) = O(n log n) [by Master Theorem]Space Complexity Rule for RecursionSpace complexity of a recursive function = maximum depth of the call stack × space per frameLinear recursion (factorial, sum): O(n) spaceBinary recursion (Fibonacci naive): O(n) space (maximum depth, not number of nodes)Divide and conquer (merge sort): O(log n) space (depth of recursion tree)Memoized Fibonacci: O(n) space (memo table + call stack)Classic Recursive Problems With SolutionsProblem 1: Reverse a StringString reverse(String s) { if (s.length() <= 1) return s; // base case // last char + reverse of everything before last char return s.charAt(s.length() - 1) + reverse(s.substring(0, s.length() - 1));}Dry run for "hello":reverse("hello") = 'o' + reverse("hell")reverse("hell") = 'l' + reverse("hel")reverse("hel") = 'l' + reverse("he")reverse("he") = 'e' + reverse("h")reverse("h") = "h"Unwinding: "h" → "he" → "leh" → "lleh" → "olleh" ✅Problem 2: Power Function (x^n)double power(double x, int n) { if (n == 0) return 1; // base case if (n < 0) return 1.0 / power(x, -n); // handle negative if (n % 2 == 0) { double half = power(x, n / 2); return half * half; // x^n = (x^(n/2))^2 } else { return x * power(x, n - 1); }}This is the fast power algorithm — O(log n) time instead of O(n).Problem 3: Fibonacci With Memoizationint[] memo = new int[100];Arrays.fill(memo, -1);int fib(int n) { if (n <= 1) return n; if (memo[n] != -1) return memo[n]; memo[n] = fib(n - 1) + fib(n - 2); return memo[n];}Time: O(n) — each value computed once Space: O(n) — memo array + call stackProblem 4: Tower of HanoiThe classic recursion teaching problem. Move n disks from source to destination using a helper rod.void hanoi(int n, char source, char destination, char helper) { if (n == 1) { System.out.println("Move disk 1 from " + source + " to " + destination); return; } // Move n-1 disks from source to helper hanoi(n - 1, source, helper, destination); // Move the largest disk from source to destination System.out.println("Move disk " + n + " from " + source + " to " + destination); // Move n-1 disks from helper to destination hanoi(n - 1, helper, destination, source);}Time Complexity: O(2ⁿ) — minimum moves required is 2ⁿ - 1 Space Complexity: O(n) — call stack depthProblem 5: Generate All Subsets (Power Set)void generateSubsets(int[] nums, int index, List<Integer> current, List<List<Integer>> result) { result.add(new ArrayList<>(current)); // add current subset for (int i = index; i < nums.length; i++) { current.add(nums[i]); // include generateSubsets(nums, i + 1, current, result); // recurse current.remove(current.size() - 1); // exclude (backtrack) }}For [1, 2, 3] — generates all 8 subsets: [], [1], [1,2], [1,2,3], [1,3], [2], [2,3], [3]Time: O(2ⁿ) — 2ⁿ subsets Space: O(n) — recursion depthProblem 6: Binary Search Recursivelyint binarySearch(int[] arr, int target, int left, int right) { if (left > right) return -1; // base case — not found int mid = left + (right - left) / 2; if (arr[mid] == target) return mid; else if (arr[mid] < target) return binarySearch(arr, target, mid + 1, right); else return binarySearch(arr, target, left, mid - 1);}Time: O(log n) — halving the search space each time Space: O(log n) — log n frames on the call stackRecursion on Trees — The Natural HabitatTrees are where recursion truly shines. Every tree problem becomes elegant with recursion because a tree is itself a recursive structure — each node's left and right children are trees themselves.// Maximum depth of binary treeint maxDepth(TreeNode root) { if (root == null) return 0; return 1 + Math.max(maxDepth(root.left), maxDepth(root.right));}// Check if tree is symmetricboolean isSymmetric(TreeNode left, TreeNode right) { if (left == null && right == null) return true; if (left == null || right == null) return false; return left.val == right.val && isSymmetric(left.left, right.right) && isSymmetric(left.right, right.left);}// Path sum — does any root-to-leaf path sum to target?boolean hasPathSum(TreeNode root, int target) { if (root == null) return false; if (root.left == null && root.right == null) return root.val == target; return hasPathSum(root.left, target - root.val) || hasPathSum(root.right, target - root.val);}Notice the pattern in all three — base case handles null, recursive case handles left and right subtrees, result combines both.How to Think About Any Recursive Problem — Step by StepThis is the framework you should apply to every new recursive problem you encounter:Step 1 — Identify the base case What is the smallest input where you know the answer directly without any recursion? For arrays it is usually empty array or single element. For trees it is null node. For numbers it is 0 or 1.Step 2 — Trust the recursive call Assume your function already works correctly for smaller inputs. Do not trace through the entire recursion mentally — just trust it. This is the Leap of Faith and it is what makes recursion feel natural.Step 3 — Express the current problem in terms of smaller problems How does the answer for size n relate to the answer for size n-1 (or n/2, or subtrees)? This relationship is your recursive case.Step 4 — Make sure each call moves toward the base case The input must become strictly smaller with each call. If it does not, you have infinite recursion.Step 5 — Write the base case first, then the recursive case Always. Writing the recursive case first leads to bugs because you have not defined when to stop.Common Mistakes and How to Avoid ThemMistake 1: Missing or wrong base case The most common mistake. Missing the base case causes StackOverflowError. Wrong base case causes wrong answers.Always ask — what is the simplest possible input, and what should the function return for it? Write that case first.Mistake 2: Not moving toward the base case If you call factorial(n) inside factorial(n) without reducing n, you loop forever. Every recursive call must make the problem strictly smaller.Mistake 3: Trusting your brain to trace deep recursion Do not try to trace 10 levels of recursion in your head. Trust the recursive call, verify the base case, and check that each call reduces the problem. That is all you need.Mistake 4: Forgetting to return the recursive result// WRONG — result is computed but not returnedint sum(int n) { if (n == 0) return 0; sum(n - 1) + n; // computed but discarded!}// CORRECTint sum(int n) { if (n == 0) return 0; return sum(n - 1) + n;}Mistake 5: Modifying shared state without backtracking In backtracking problems, if you add something to a list before a recursive call, you must remove it after the call returns. Forgetting to backtrack leads to incorrect results and is one of the trickiest bugs to find.Mistake 6: Recomputing the same subproblems Naive Fibonacci computes fib(3) multiple times when computing fib(5). Use memoization whenever you notice overlapping subproblems in your recursion tree.Top LeetCode Problems on RecursionThese are organized by pattern — work through them in this order for maximum learning:Pure Recursion Basics:509. Fibonacci Number — Easy — start here, implement with and without memoization344. Reverse String — Easy — recursion on arrays206. Reverse Linked List — Easy — recursion on linked list50. Pow(x, n) — Medium — fast power with recursionTree Recursion (Most Important):104. Maximum Depth of Binary Tree — Easy — simplest tree recursion112. Path Sum — Easy — decision recursion on tree101. Symmetric Tree — Easy — mutual recursion on tree110. Balanced Binary Tree — Easy — bottom-up recursion236. Lowest Common Ancestor of a Binary Tree — Medium — classic tree recursion124. Binary Tree Maximum Path Sum — Hard — advanced tree recursionDivide and Conquer:148. Sort List — Medium — merge sort on linked list240. Search a 2D Matrix II — Medium — divide and conquerBacktracking:78. Subsets — Medium — generate all subsets46. Permutations — Medium — generate all permutations77. Combinations — Medium — generate combinations79. Word Search — Medium — backtracking on grid51. N-Queens — Hard — classic backtrackingMemoization / Dynamic Programming:70. Climbing Stairs — Easy — Fibonacci variant with memoization322. Coin Change — Medium — recursion with memoization to DP139. Word Break — Medium — memoized recursionRecursion Cheat Sheet// Linear recursion templatereturnType solve(input) { if (baseCase) return directAnswer; // process current return solve(smallerInput);}// Tree recursion templatereturnType solve(TreeNode root) { if (root == null) return baseValue; returnType left = solve(root.left); returnType right = solve(root.right); return combine(left, right, root.val);}// Backtracking templatevoid backtrack(choices, current, result) { if (goalReached) { result.add(copy of current); return; } for (choice : choices) { make(choice); // add to current backtrack(...); // recurse undo(choice); // remove from current }}// Memoization templateMap<Input, Output> memo = new HashMap<>();returnType solve(input) { if (baseCase) return directAnswer; if (memo.containsKey(input)) return memo.get(input); returnType result = solve(smallerInput); memo.put(input, result); return result;}FAQs — People Also AskQ1. What is recursion in Java with a simple example? Recursion is when a function calls itself to solve a smaller version of the same problem. A simple example is factorial — factorial(5) = 5 × factorial(4) = 5 × 4 × factorial(3) and so on until factorial(1) returns 1 directly.Q2. What is the difference between recursion and iteration? Iteration uses loops (for, while) and runs in O(1) space. Recursion uses function calls and uses O(n) stack space for n levels deep. Recursion is often cleaner for tree and graph problems. Iteration is better when memory is a concern or the problem is inherently linear.Q3. What causes StackOverflowError in Java recursion? StackOverflowError happens when recursion goes too deep — too many frames accumulate on the call stack before any of them return. This is caused by missing base case, wrong base case, or input too large for Java's default stack size limit.Q4. What is the difference between recursion and dynamic programming? Recursion solves a problem by breaking it into subproblems. Dynamic programming is recursion plus memoization — storing results of subproblems so they are never computed twice. DP converts exponential recursive solutions into polynomial ones by eliminating redundant computation.Q5. What is tail recursion and does Java support tail call optimization? Tail recursion is when the recursive call is the absolute last operation in the function. Java does NOT support tail call optimization — Java always creates a new stack frame for each call even if it is tail recursive. Languages like Scala and Kotlin (on the JVM) do support it with the tailrec keyword.Q6. How do you convert recursion to iteration? Every recursive solution can be converted to iterative using an explicit stack data structure. The call stack's behavior is replicated manually — push the initial call, loop while stack is not empty, pop, process, and push sub-calls. Tree traversals are a common example of this conversion.ConclusionRecursion is not magic. It is a systematic way of solving problems by expressing them in terms of smaller versions of themselves. Once you internalize the two parts (base case and recursive case), understand the call stack mentally, and learn to trust the recursive call rather than trace it completely, everything clicks.The learning path from here is clear — start with simple problems like Fibonacci and array sum. Move to tree problems where recursion is most natural. Then tackle backtracking. Finally add memoization to bridge into dynamic programming.Every hour you spend understanding recursion deeply pays dividends across the entire rest of your DSA journey. Trees, graphs, divide and conquer, backtracking, dynamic programming — all of them build on this foundation.

RecursionJavaBase CaseCall StackBacktrackingDynamic Programming
LeetCode 2553: Separate the Digits in an Array – Java Solution Explained (2 Easy Approaches)

LeetCode 2553: Separate the Digits in an Array – Java Solution Explained (2 Easy Approaches)

IntroductionIn coding interviews and competitive programming, many problems test how well you can manipulate numbers and arrays together. One such beginner-friendly problem is LeetCode 2553 – Separate the Digits in an Array.In this problem, we are given an integer array, and we need to separate every digit of every number while maintaining the original order.This problem is excellent for practicing:Array traversalDigit extractionReverse processingArrayList usage in JavaThinking about order preservationProblem Link🔗 ProblemLeetCode 2553: Separate the Digits in an ArrayProblem StatementGiven an array of positive integers nums, return an array containing all digits of each integer in the same order they appear.ExampleInput:nums = [13,25,83,77]Output:[1,3,2,5,8,3,7,7]IntuitionThe main challenge is:Extract digits from each numberPreserve the original left-to-right orderNormally, extracting digits using % 10 gives digits in reverse order.Example:83 → 3 → 8So we need a way to restore the correct order.Approach 1 – Using String ConversionIdeaConvert every number into a string and then traverse each character.This is the simplest and most beginner-friendly approach.AlgorithmTraverse every number in the array.Convert the number into a string.Traverse each character of the string.Convert character back to integer.Store digits into ArrayList.Convert ArrayList to array.Java Code – String Approachclass Solution { public int[] separateDigits(int[] nums) { ArrayList<Integer> list = new ArrayList<>(); for (int num : nums) { String str = String.valueOf(num); for (char ch : str.toCharArray()) { list.add(ch - '0'); } } int[] ans = new int[list.size()]; for (int i = 0; i < list.size(); i++) { ans[i] = list.get(i); } return ans; }}Dry Run (String Approach)Input:nums = [13,25]Step 113 → "13"Digits added:1, 3Step 225 → "25"Digits added:2, 5Final Array:[1,3,2,5]Time Complexity & Space ComplexityTime ComplexityO(N × D)Where:N = number of elementsD = number of digitsSpace ComplexityO(N × D)For storing digits.Approach 2 – Mathematical Digit Extraction (Optimal Without String)This is the approach you implemented in your code.Instead of converting numbers into strings, we extract digits mathematically using:digit = num % 10num = num / 10But digits come in reverse order.To fix this:Traverse the original array from back to frontStore extracted digitsReverse the final resultThis avoids string conversion completely.Intuition Behind Reverse TraversalSuppose:nums = [13,25]If we traverse from the end:25 → 5,213 → 3,1Stored list:[5,2,3,1]Now reverse the list:[1,3,2,5]Correct answer achieved.Java Code – Mathematical Approachclass Solution { public int[] separateDigits(int[] nums) { ArrayList<Integer> list = new ArrayList<>(); for (int i = nums.length - 1; i >= 0; i--) { if (nums[i] < 10) { list.add(nums[i]); } else { int val = nums[i]; while (val != 0) { int digit = val % 10; val = val / 10; list.add(digit); } } } int[] ans = new int[list.size()]; int k = 0; for (int i = list.size() - 1; i >= 0; i--) { ans[k++] = list.get(i); } return ans; }}Dry Run (Mathematical Approach)Input:nums = [13,25,83]Traverse from Back83Digits extracted:3, 8List:[3,8]25Digits extracted:5,2List:[3,8,5,2]13Digits extracted:3,1List:[3,8,5,2,3,1]Reverse Final List[1,3,2,5,8,3]Correct answer.Time Complexity Analysis & Space ComplexityTime ComplexityO(N × D)Because every digit is processed once.Space ComplexityO(N × D)For storing final digits.Which Approach is Better?ApproachAdvantagesDisadvantagesString ConversionEasy to understandUses extra string conversionMathematical ExtractionBetter DSA practiceSlightly harder logicInterview PerspectiveIn interviews:Beginners should first explain the string approach.Then discuss optimization using mathematical extraction.Interviewers like when candidates:Understand digit manipulationThink about order preservationCompare multiple approachesCommon Mistakes1. Forgetting Reverse OrderUsing % 10 extracts digits backward.Example:123 → 3,2,1You must reverse later.2. Not Handling Single Digit NumbersSingle digit numbers should directly be added.3. Character Conversion MistakeWrong:list.add(ch);Correct:list.add(ch - '0');Frequently Asked Questions (FAQs)Q1. Why do digits come in reverse order?Because % 10 always extracts the last digit first.Example:123 % 10 = 3Q2. Can we solve this without ArrayList?Yes, but ArrayList makes dynamic storage easier.Q3. Which approach is more optimal?Both have similar complexity.Mathematical extraction avoids string conversion and is preferred in interviews.Q4. Is this problem important for interviews?Yes. It teaches:Number manipulationOrder handlingArray traversalBasic optimization thinkingConclusionLeetCode 2553 is a simple yet valuable beginner problem for understanding:Digit extractionArray handlingReverse traversalOrder preservationYou learned two approaches:String Conversion ApproachMathematical Digit Extraction ApproachThe mathematical solution is especially useful because it strengthens core DSA concepts and improves problem-solving skills for interviews.If you're preparing for coding interviews in Java, this is a great problem to master before moving to harder digit manipulation questions.

ArrayEasyLeetcodeDigit ExtractionJava
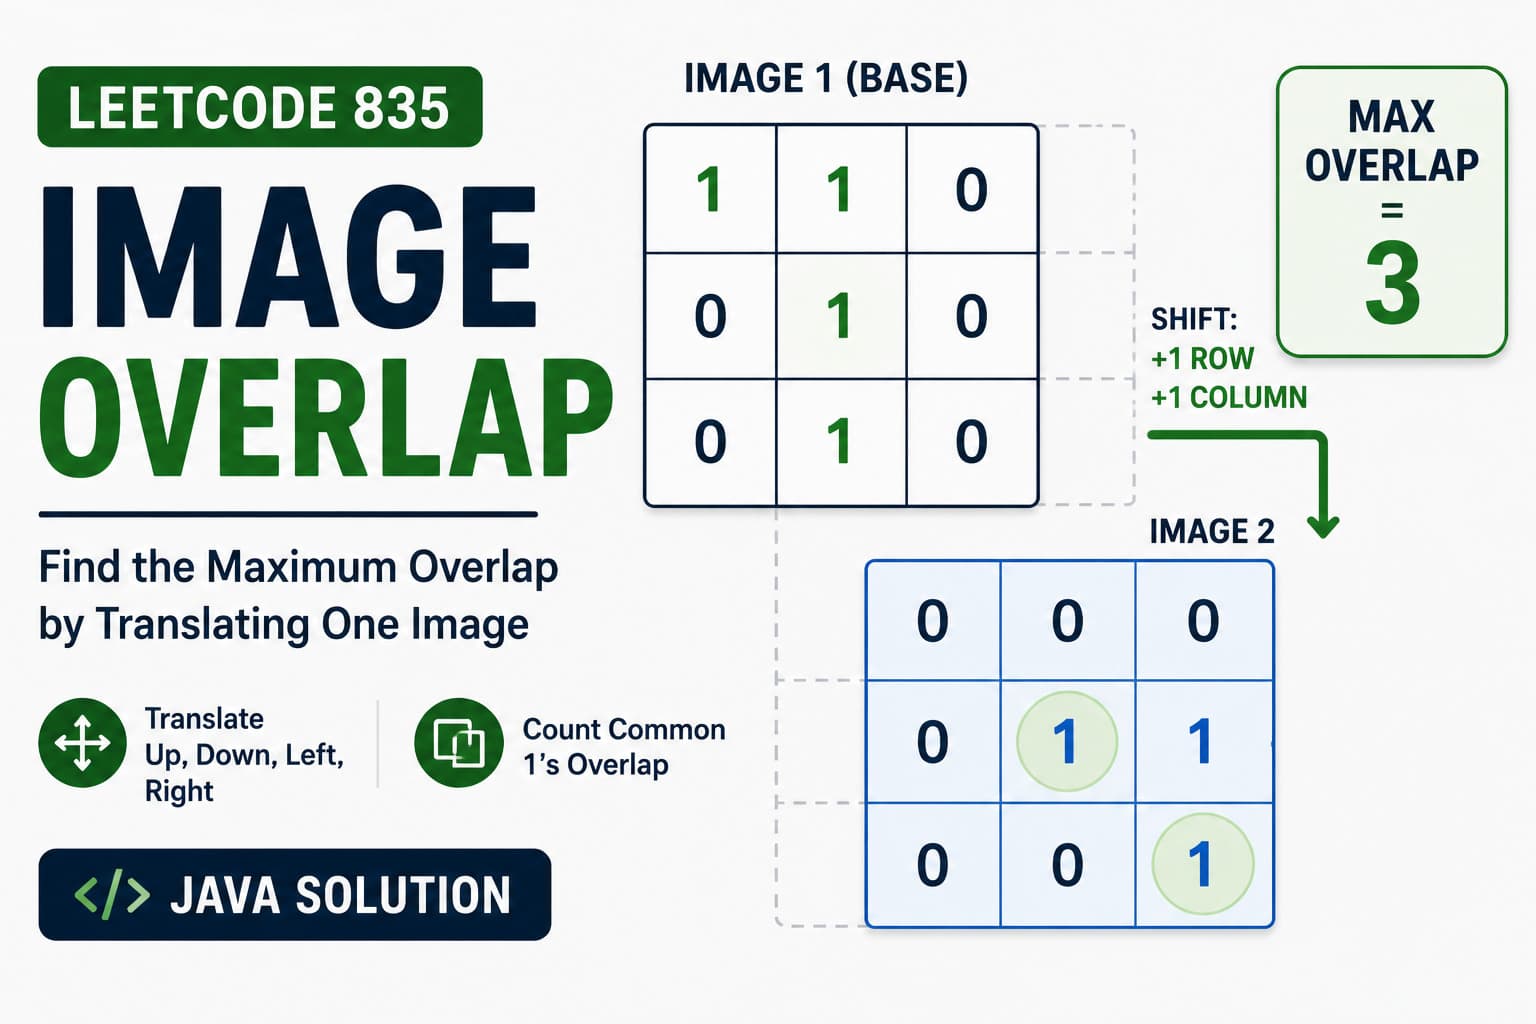
LeetCode 835: Image Overlap – Java Matrix Translation Solution

LeetCode 835: Image Overlap – Java Matrix Translation Solution

IntroductionWhat happens when one binary image is shifted over another and the goal is to find the position where the two images overlap the most?That is exactly the idea behind LeetCode 835: Image Overlap.Each image is represented as an n × n binary matrix containing only 0s and 1s. One image can be moved left, right, up, or down, but it cannot be rotated.After every possible translation, the number of positions containing 1 in both images is calculated. The maximum value among all translations is the answer.Since n is at most 30, a direct simulation of every possible translation is practical.Question LinkLeetCode 835 – Image OverlapUnderstanding the ProblemConsider two images:Image 11 1 00 1 00 1 0and:Image 20 0 00 1 10 0 1The first image can be translated.For example, shifting Image 1:Right → 1Down → 1can align several 1s from the two images.The objective is to find the translation that produces the largest number of overlapping 1s.Key ObservationA translation can be represented using two values:row offsetcolumn offsetFor example:row offset = 1column offset = 1means that a cell from Image 2 at:(i, j)is compared with Image 1 at:(i + 1, j + 1)The algorithm tries every possible row and column offset.For an n × n matrix, each offset ranges from:-(n - 1) to (n - 1)This covers every possible way the two images can overlap without requiring rotation.ApproachThe solution is divided into two parts.Generate Every TranslationThe largestOverlap() function generates every possible pair of row and column offsets.for(int i = -n + 1; i < n; i++)handles vertical movement.for(int j = -n + 1; j < n; j++)handles horizontal movement.For every pair:(rowOffset, columnOffset)the helper function ch() calculates the overlap.Count the Overlapping OnesFor every cell in img2, the translated position inside img1 is calculated:int tarrow = i + rowo;int tarcol = j + colo;The position is counted only when:It is still inside img1.img2[i][j] == 1.img1[tarrow][tarcol] == 1.Every such position contributes 1 to the overlap.Java Solutionclass Solution { // Calculates the overlap for one particular translation. public int ch(int[][] im1, int[][] im2, int rowo, int colo) { int max = 0; // Traverse every cell of img2. for (int i = 0; i < im2.length; i++) { for (int j = 0; j < im2.length; j++) { // Apply the row and column translation. int tarrow = i + rowo; int tarcol = j + colo; // Make sure the translated position // is still inside img1. if (tarrow >= 0 && tarcol >= 0 && tarrow < im1.length && tarcol < im1.length && im2[i][j] == 1 && im1[tarrow][tarcol] == 1) { // Both images contain 1 at this position. max++; } } } return max; } public int largestOverlap(int[][] img1, int[][] img2) { int n = img1.length; // Stores the maximum overlap found so far. int an = 0; // Try every possible row translation. for (int i = -n + 1; i < n; i++) { // Try every possible column translation. for (int j = -n + 1; j < n; j++) { // Calculate overlap for this translation. int max = 0; max = ch(img1, img2, i, j); // Keep the best overlap. an = Math.max(max, an); } } return an; }}Visual Dry RunConsider:img1 =1 1 00 1 00 1 0img2 =0 0 00 1 10 0 1One useful translation is:row offset = 1column offset = 1The idea is to move Image 2 relative to Image 1 and compare the positions containing 1.How offset move on matrix?The visual makes the important idea immediately clear: translation changes the positions being compared, while rotation is never performed.How the Translation WorksSuppose:rowo = 1colo = 1For a cell in img2:(i, j)the corresponding position in img1 becomes:(i + 1, j + 1)For example:img2[1][1]is compared with:img1[2][2]If both contain 1, the overlap count increases.The boundary check is important because some translations move cells outside the matrix.For example, a large positive offset could produce:tarrow >= im1.lengthIn that case, the translated cell is outside the image and must not be counted.Dry Run of the Helper FunctionSuppose the translation is:rowo = 1colo = 1For every (i, j) in img2, the code calculates:tarrow = i + rowo;tarcol = j + colo;Then it checks:img2[i][j] == 1and:img1[tarrow][tarcol] == 1Only when both are true does the overlap increase.Conceptually:Image 2 cell ↓Apply translation ↓Corresponding Image 1 cell ↓Are both values 1? ↓Yes → overlap++After checking every cell, ch() returns the overlap for that particular translation.Exploring All Possible TranslationsFor a matrix of size n, the row offset is explored from:-(n - 1)to:n - 1The same is done for the column offset.For example, when:n = 3the possible offsets are:-2, -1, 0, 1, 2Therefore, all combinations are tested:(-2,-2) (-2,-1) (-2,0) ...(-1,-2) (-1,-1) (-1,0) ...( 0,-2) ( 0,-1) ( 0,0) ......Each pair represents one possible translation.The largest overlap among all of them becomes the final answer.Why Boundary Checking Is NecessaryImagine shifting an image to the right.Some cells will move beyond the right edge of the matrix.Those cells effectively disappear.The same happens when moving:leftupdownTherefore, before accessing:im1[tarrow][tarcol]the solution verifies:tarrow >= 0tarcol >= 0tarrow < im1.lengthtarcol < im1.lengthThis prevents an ArrayIndexOutOfBoundsException and correctly handles pixels that move outside the image.Why Rotation Is Not NeededThe problem allows only translation.That means the relative structure of the 1s never changes.For example:1 00 1can move:← →↑ ↓but it cannot become:0 11 0through rotation.This is why simply testing row and column offsets is enough.Complexity AnalysisThere are:(2n - 1)possible row offsets and the same number of column offsets.Therefore, the number of translations is:(2n - 1)²For every translation, the entire n × n matrix is scanned.That takes:O(n²)So the overall complexity is:O((2n - 1)² × n²)which simplifies to:O(n⁴)Space ComplexityThe solution uses only a few variables apart from the input matrices.Therefore, the extra space is:O(1)Why O(n⁴) Is Acceptable HereAt first glance, O(n⁴) may look expensive.However, the constraint is:n ≤ 30This is a relatively small matrix.The number of translations is at most:(2 × 30 - 1)² = 59² = 3481and each translation checks at most:30 × 30 = 900cells.So the total amount of work remains manageable.This is a good example of an important DSA principle:The best algorithm depends not only on the Big-O notation, but also on the actual constraints.Interview TipWhen dealing with two matrices or grids and the problem allows one of them to move, a useful first question is:Can the movement be represented using coordinates or offsets?Here, every possible movement can be represented with:(row offset, column offset)Once that representation is identified, the problem becomes a straightforward simulation.A good mental pattern is:Movement ↓Represent movement as coordinates ↓Try every valid movement ↓Compare overlapping positions ↓Keep the maximumThis pattern can also appear in problems involving:Grid matchingPattern alignment2D simulationsImage processingCoordinate transformationsConclusionLeetCode 835 is a useful matrix simulation problem that demonstrates how a seemingly visual problem can be converted into simple coordinate calculations.The main idea is to represent every possible translation using a row offset and column offset. For each translation, every cell of the second image is mapped to its corresponding position in the first image, and overlapping 1s are counted.Because the matrix size is limited to 30 × 30, the O(n⁴) brute-force simulation is practical and keeps the implementation straightforward.The most important takeaway is the coordinate-based way of thinking: when an object moves on a grid, represent that movement as an offset and systematically test the valid positions.

LeetCodeJavaMatrixArraysSimulation2D ArraysMatrix TraversalMedium
Intersection of Two Linked Lists – The Smart Trick Most People Miss (LeetCode 160)

Intersection of Two Linked Lists – The Smart Trick Most People Miss (LeetCode 160)

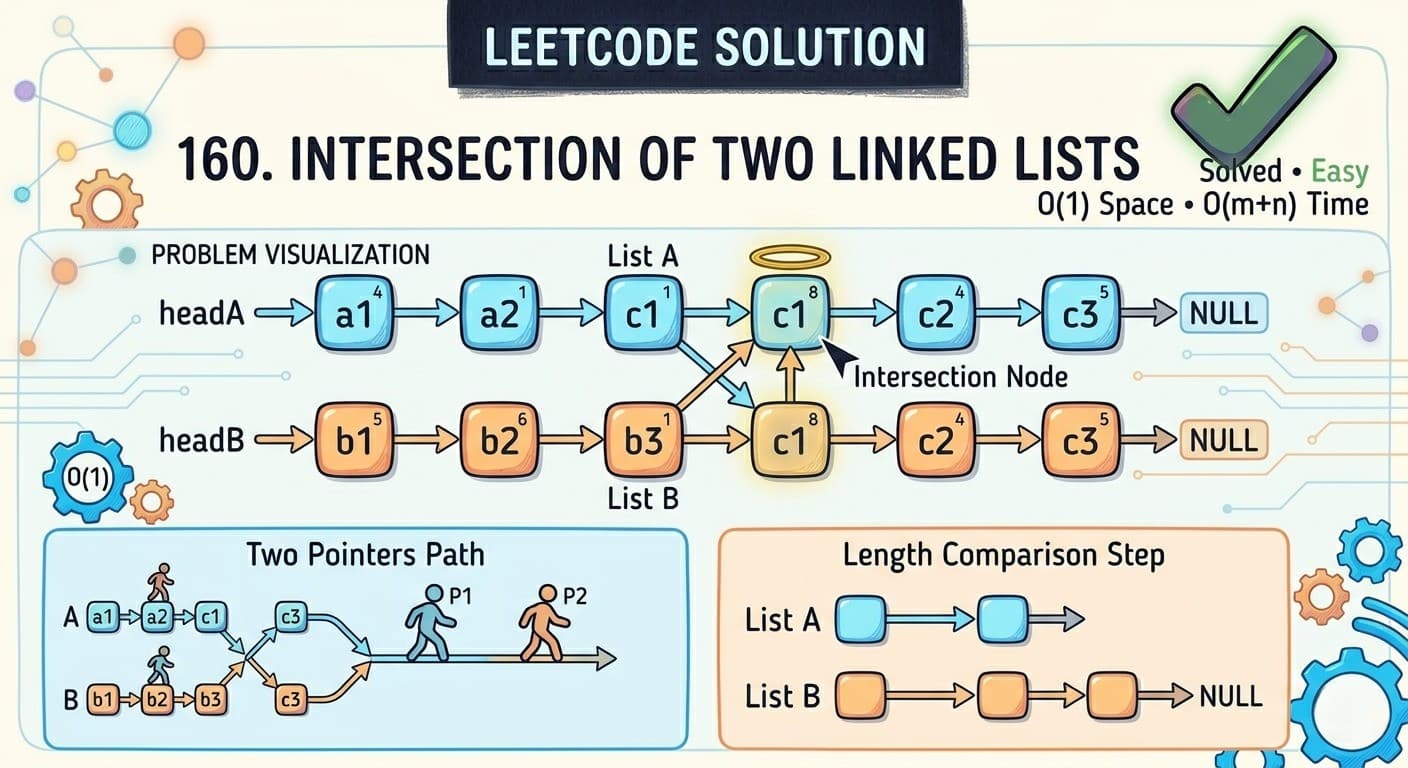
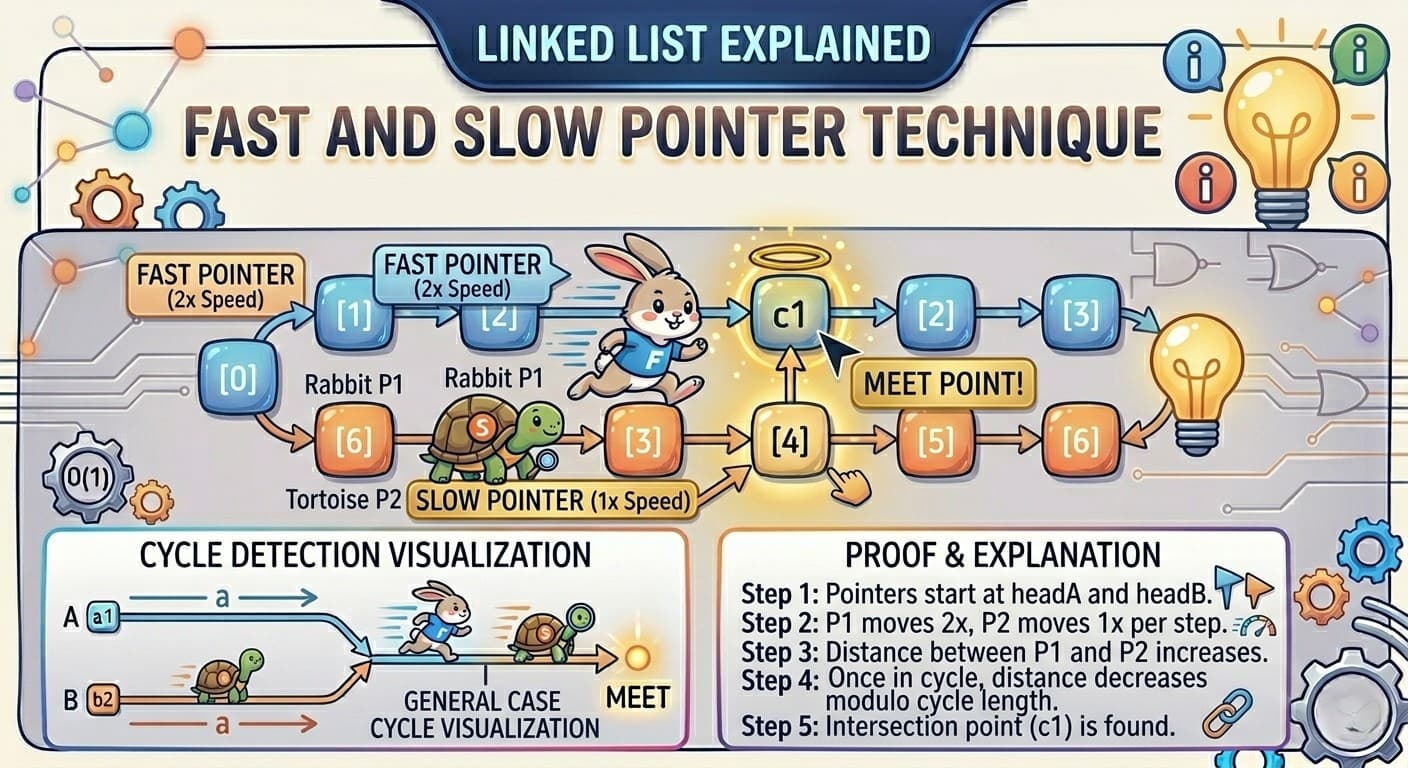
🚀 Try the ProblemPractice here:https://leetcode.com/problems/intersection-of-two-linked-lists/🤔 Let’s Start With a ThoughtImagine two roads:Road A: 4 → 1 → 8 → 4 → 5 Road B: 5 → 6 → 1 → 8 → 4 → 5At some point… both roads merge into one.👉 That merging point is the intersection node🧠 Problem in Simple WordsYou are given:Head of List AHead of List B👉 Find the node where both linked lists intersect👉 If no intersection exists → return null⚠️ Important Clarification👉 Intersection means:Same memory node (same reference)NOT:Same value ❌📌 Example InsightList A: 1 → 9 → 1 → 2 → 4 List B: 3 → 2 → 4Even though both lists have 2 and 4:👉 They intersect ONLY if they point to the same node in memory📦 Constraints1 <= m, n <= 3 * 10^41 <= Node.val <= 10^5No cycles in the list🔍 First Thought (Brute Force)IdeaFor every node in List A:👉 Traverse entire List B and check if nodes matchComplexityTime: O(m * n) ❌Space: O(1)Too slow.🧩 Better Approach: Length Difference MethodIdeaFind length of both listsMove the longer list ahead by the differenceNow traverse both togetherWhy This Works👉 After skipping extra nodes, both pointers are equally far from intersectionComplexityTime: O(m + n)Space: O(1)🚀 Optimal Approach: Two Pointer Switching TrickNow comes the most beautiful trick 🔥🧠 Core IdeaWe use two pointers:pointerA → starts from headApointerB → starts from headB🎯 The Magic Trick👉 When a pointer reaches end → switch it to the other list🔄 VisualizationLet’s say:Length A = mLength B = nPointer paths:pointerA travels: A → BpointerB travels: B → ASo both travel:m + n distance💡 Why They Meet👉 If intersection exists → they meet at intersection👉 If not → both reach null at same time🔥 Step-by-Step ExampleA: 4 → 1 → 8 → 4 → 5 B: 5 → 6 → 1 → 8 → 4 → 5Iteration:A pointer: 4 → 1 → 8 → 4 → 5 → null → 5 → 6 → 1 → 8 B pointer: 5 → 6 → 1 → 8 → 4 → 5 → null → 4 → 1 → 8👉 They meet at 8💻 Clean Java Code (Optimal Solution)public class Solution { public ListNode getIntersectionNode(ListNode headA, ListNode headB) { ListNode tempa = headA; ListNode tempb = headB; // Traverse until both pointers meet while(tempa != tempb){ // Move pointer A if(tempa != null) tempa = tempa.next; else tempa = headB; // Move pointer B if(tempb != null) tempb = tempb.next; else tempb = headA; } // Either intersection node OR null return tempa; }}⏱️ ComplexityTime ComplexityO(m + n)Space ComplexityO(1)⚖️ Approach ComparisonApproachTimeSpaceNotesBrute ForceO(m*n)O(1)Too slowLength DifferenceO(m+n)O(1)GoodTwo Pointer SwitchO(m+n)O(1)Best & elegant❌ Common MistakesComparing values instead of nodes ❌Forgetting to switch listsNot handling null correctlyAssuming intersection always exists🔥 Interview InsightThis is one of the most clever pointer problems.It teaches:👉 How to equalize paths without extra memory👉 How pointer switching solves alignment problems🧠 Final ThoughtAt first, this trick feels like magic…But actually it’s just:Equalizing path lengths🚀 ConclusionThe Intersection of Two Linked Lists problem is a perfect example of:Smart thinking > brute forceClean logic > complex code👉 Tip: Whenever two lists need alignment, think:"Can I make both pointers travel equal distance?"That’s where the magic begins ✨

Linked ListTwo PointersIntersectionPointer SwitchingDSALeetCodeEasy
Delete Middle Element of Stack Without Extra Space | Java Recursive Solution

Delete Middle Element of Stack Without Extra Space | Java Recursive Solution

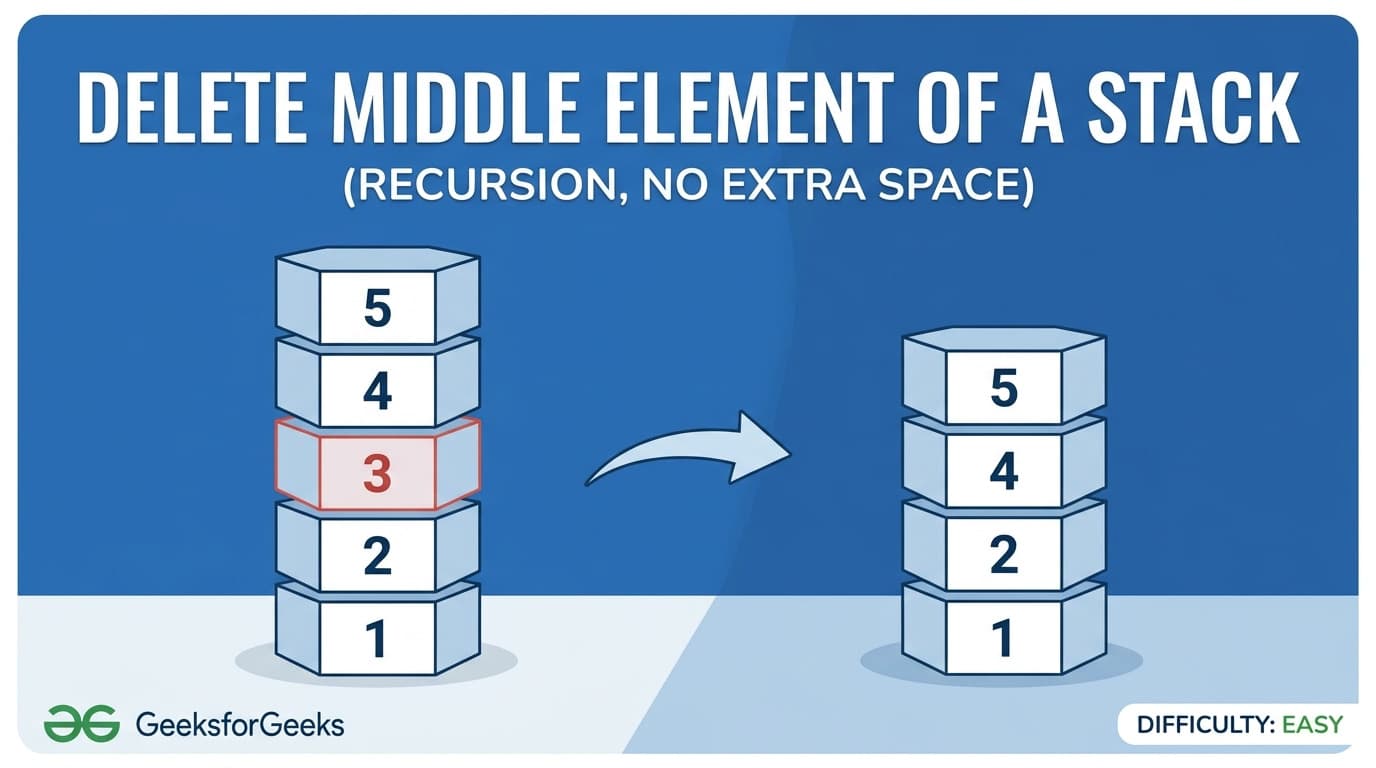
IntroductionStack-based problems are a core part of data structures and algorithms (DSA) interviews. One such interesting and frequently asked question is deleting the middle element of a stack without using any additional data structure.At first glance, this problem may seem tricky because stacks only allow access to the top element. However, with the help of recursion, it becomes an elegant and intuitive solution.In this article, we will break down the problem, build the intuition, and implement an efficient recursive approach step by step.Link of Problem: GeeksforGeeks – Delete Middle of a StackProblem StatementGiven a stack s, delete the middle element of the stack without using any additional data structure.Definition of Middle ElementThe middle element is defined as:floor((size_of_stack + 1) / 2)Indexing starts from the bottom of the stack (1-based indexing)ExamplesExample 1Input:s = [10, 20, 30, 40, 50]Output:[50, 40, 20, 10]Explanation:Middle index = (5+1)/2 = 3Middle element = 30 → removedExample 2Input:s = [10, 20, 30, 40]Output:[40, 30, 10]Explanation:Middle index = (4+1)/2 = 2Middle element = 20 → removedKey InsightStacks follow LIFO (Last In, First Out), meaning:You can only access/remove the top elementYou cannot directly access the middleSo how do we solve it?We use recursion to:Pop elements until we reach the middleRemove the middle elementPush back all other elementsThis way, no extra data structure is used—just the recursion call stack.Approach: Recursive SolutionIdeaCalculate the middle positionRecursively remove elements from the topWhen the middle is reached → delete itWhile returning, push elements backCode (Java)import java.util.Stack;class Solution {void findMid(Stack<Integer> s, int mid) {// When current stack size equals middle positionif (s.size() == mid) {s.pop(); // delete middle elementreturn;}int temp = s.pop(); // remove top element// Recursive callfindMid(s, mid);// Push element back after recursions.push(temp);}// Function to delete middle element of a stackpublic void deleteMid(Stack<Integer> s) {int mid = (s.size() + 1) / 2;findMid(s, mid);}}Step-by-Step Dry RunLet’s take:Stack (bottom → top): [10, 20, 30, 40, 50]Middle index = 3Recursion pops: 50 → 40Now stack size = 3 → remove 30Push back: 40 → 50Final Stack:[10, 20, 40, 50]Complexity AnalysisTime Complexity: O(n)Each element is removed and added onceAuxiliary Space: O(n)Due to recursion call stackWhy This Approach WorksRecursion simulates stack behaviorNo extra data structures like arrays or lists are usedMaintains original order after deletionEfficient and interview-friendly solutionKey TakeawaysDirect access to middle is not possible in a stackRecursion is the key to solving such constraintsAlways think of breaking + rebuilding for stack problemsThis pattern is useful in many stack-based interview questionsWhen This Problem Is AskedThis problem is commonly seen in:Technical interviewsCoding platforms like GeeksforGeeksStack and recursion-based problem setsIt evaluates:Understanding of stack operationsRecursive thinkingProblem-solving under constraintsConclusionDeleting the middle element of a stack without extra space is a classic example of using recursion effectively. While the problem may seem restrictive, the recursive approach provides a clean and optimal solution.Mastering this concept will help you tackle more advanced stack and recursion problems with confidence.Frequently Asked Questions (FAQs)1. Can this be solved without recursion?Not efficiently without using another data structure. Recursion is the best approach under given constraints.2. Why not use an array or list?The problem explicitly restricts the use of additional data structures.3. What is the best approach?The recursive approach is optimal with O(n) time and space complexity.

GeeksofGeeksEasyStackRecursionJava
Reverse a Stack — GFG Problem Solved (3 Approaches Explained)

Reverse a Stack — GFG Problem Solved (3 Approaches Explained)

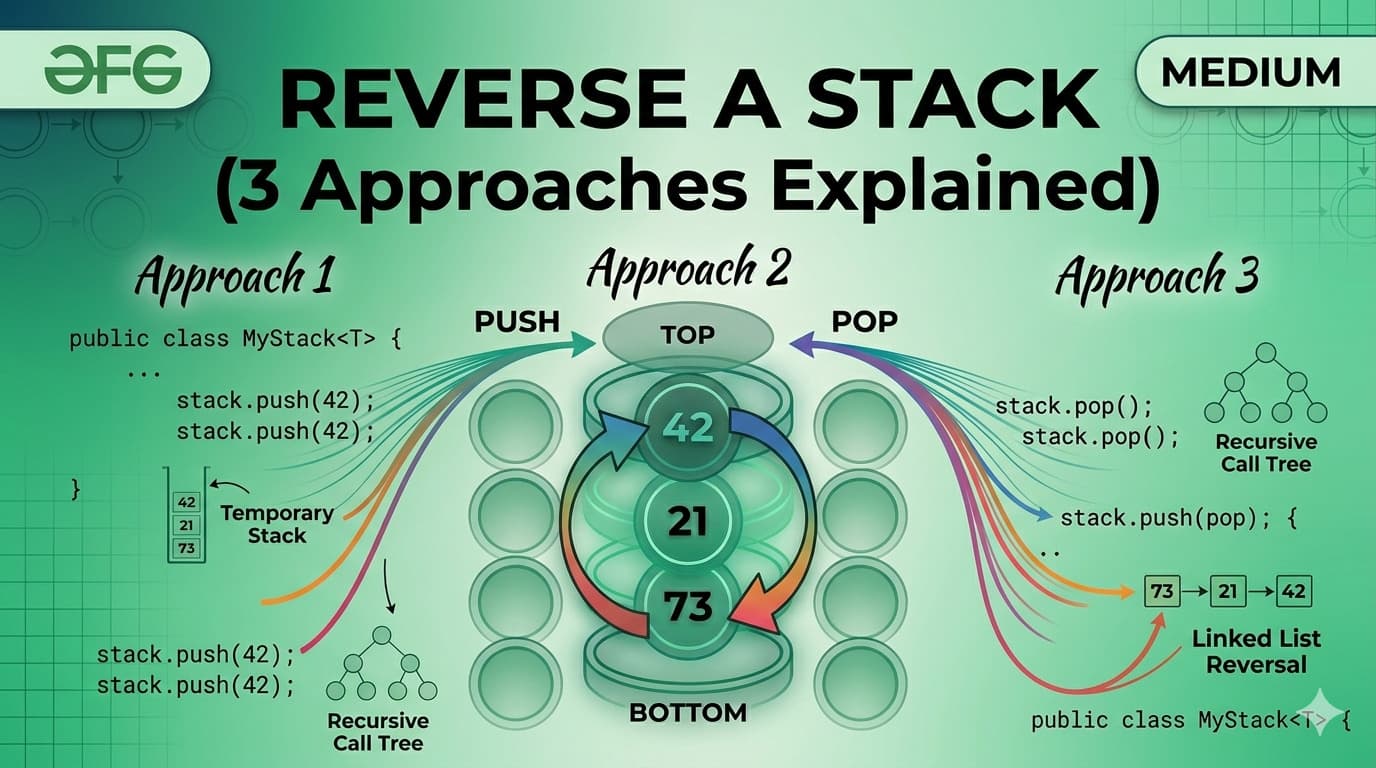
What Is This Problem About?This is a classic stack problem from GeeksForGeeks — "Reverse a Stack" (Medium | 4 Points). You can find it on GFG by Reverse a Stack.You are given a stack. Your job is simple — reverse it. The element that was at the bottom should now be at the top, and vice versa.Example:Input: [1, 2, 3, 4] → bottom to top, so 4 is on topOutput: [1, 2, 3, 4] → after reversal, 1 is on topWait — the input and output look the same? That is because GFG displays the result top to bottom after reversal. So after reversing, 1 comes to the top, and printing top to bottom gives [1, 2, 3, 4]. The stack is indeed reversed internally.Approach 1 — Using Two Extra StacksIntuition: Pop everything from the original stack into Stack 1 — this reverses the order once. Then pop everything from Stack 1 into Stack 2 — this reverses it again, back to original order. Now push everything from Stack 2 back into the original stack. The result? The original stack is reversed.Why does this work? Two reversals cancel each other out to give you... wait, that sounds wrong. Let us trace it:Original: [1, 2, 3, 4] → top is 4After → S1: [4, 3, 2, 1] → top is 1After → S2: [1, 2, 3, 4] → top is 4Push S2 back → st: [1, 2, 3, 4] → top is 4Hmm, that brings it back to the same thing. This approach with two stacks actually does NOT work correctly — it ends up restoring the original order. This is why the approach was commented out in the original code. Good observation to catch in an interview.Lesson: Two full reversals = no change. One reversal = what we want. Keep this in mind.Approach 2 — Using an ArrayList (Clean & Simple) ✅Intuition: Pop all elements from the stack into an ArrayList. At this point, the ArrayList holds elements in reverse order (because popping reverses). Then push them back from index 0 to end. This is the clean, working solution.Stack: [1, 2, 3, 4] → top is 4Pop into ArrayList: [4, 3, 2, 1]Push back index 0→end: push 4 → st: [4] push 3 → st: [4, 3] push 2 → st: [4, 3, 2] push 1 → st: [4, 3, 2, 1] → top is now 1 ✓The stack is now reversed. 1 is on top.public static void reverseStack(Stack<Integer> st) { if (st.empty()) return; ArrayList<Integer> list = new ArrayList<>(); // Pop all elements — goes in reverse order into list while (!st.empty()) { list.add(st.pop()); } // Push back from index 0 — restores in reversed order for (int i = 0; i < list.size(); i++) { st.push(list.get(i)); }}Time Complexity: O(n) — one pass to pop, one pass to push.Space Complexity: O(n) — for the ArrayList.Why this works: When you pop all elements into a list, the top element (last inserted) goes to index 0. When you push back from index 0, that element goes in first and ends up at the bottom. The bottom element (first inserted) was popped last, sits at the end of the list, and gets pushed last — ending up on top. That is a perfect reversal.Approach 3 — Using Recursion (No Extra Space) ✅This is the most elegant approach and the one interviewers love to ask about.Intuition: Use two recursive functions:reverseStack — pops the top element, recursively reverses the rest, then inserts the popped element at the bottom.insertAtBottom — holds all elements out while inserting one element at the very bottom, then restores everything.// Insert an item at the bottom of the stackstatic void insertAtBottom(Stack<Integer> st, int item) { if (st.empty()) { st.push(item); return; } int top = st.pop(); insertAtBottom(st, item); st.push(top);}// Reverse the stackpublic static void reverseStack(Stack<Integer> st) { if (st.empty()) return; int top = st.pop(); reverseStack(st); // reverse remaining stack insertAtBottom(st, top); // put popped element at the bottom}```**Dry Run with [1, 2, 3]:**```reverseStack([1,2,3]) → pop 3, reverseStack([1,2]) reverseStack([1,2]) → pop 2, reverseStack([1]) reverseStack([1]) → pop 1, reverseStack([]) base case → return insertAtBottom([], 1) → push 1 → [1] insertAtBottom([1], 2) → 2 < 1? no → pop 1, insert 2, push 1 → [2,1]insertAtBottom([2,1], 3) → pop 1, pop 2, push 3, push 2, push 1 → [3,2,1]Final stack top → 3... wait, let us recheck display.Top is 3, which was originally at bottom. ✓ Reversed!Time Complexity: O(n²) — for each of n elements, insertAtBottom takes O(n).Space Complexity: O(n) — recursive call stack.Which Approach Should You Use?ApproachTimeSpaceSimplicityInterview ValueTwo Extra Stacks❌ Does not workO(n)SimpleLowArrayListO(n)O(n)Very EasyMediumRecursionO(n²)O(n)ModerateHighFor a coding interview, always mention the recursive approach — it shows you understand stack mechanics deeply. For production code, the ArrayList approach is cleaner and faster.Key TakeawayReversing a stack is fundamentally about understanding LIFO. Because a stack only allows access from the top, you need a systematic way to invert the order — whether that is using auxiliary storage like an ArrayList, or using the call stack itself via recursion. Both are valid. Both teach you something different about how stacks behave.The next time you see a problem that involves reversing, reordering, or inserting at the bottom of a stack — your first instinct should be recursion with insertAtBottom. It is a pattern that appears again and again in DSA.And if you want to understand Stack from Scratch?If you are just getting started with stacks or want a complete reference — I have written a detailed in-depth guide on the Stack Data Structure in Java covering everything from what a stack is, how LIFO works, all three implementations (Array, ArrayList, LinkedList), every operation explained with code, time complexity, advantages, disadvantages, real-world use cases, and six practice problems with full solutions.Check it out here → Stack Data Structure in Java: The Complete GuideIt is the perfect companion to this problem walkthrough — start there if you want the full picture, then come back here for the problem-solving side.

StackProblemsJavaMediumGeeksForGeeksReverseStack
LeetCode 121 — Best Time to Buy and Sell Stock I | Two Pointer / Sliding Window Explained

LeetCode 121 — Best Time to Buy and Sell Stock I | Two Pointer / Sliding Window Explained

🚀 Try This Problem First!Before reading the solution, attempt it yourself on LeetCode — you'll retain the concept far better.🔗 Problem Link: https://leetcode.com/problems/best-time-to-buy-and-sell-stock/Understanding the ProblemYou are given an array prices where prices[i] is the stock price on day i. You can buy on one day and sell on a later day. You want to maximize your profit.Goal: Return the maximum profit possible. If no profit can be made, return 0.Key Rules:You must buy before you sell — no going back in time.You can only make one transaction (one buy, one sell).If prices only go down, profit is impossible — return 0.Constraints:1 ≤ prices.length ≤ 10⁵0 ≤ prices[i] ≤ 10⁴Understanding the Problem With a Real-World AnalogyImagine you're watching a stock ticker for a week. You want to pick the single best day to buy and a later day to sell. You can't predict the future — you just have historical prices. The question is: looking back at all the prices, what was the best single buy-sell pair you could have chosen?Key Observation (Before Writing a Single Line of Code)The profit on any given pair of days is:profit = prices[sell_day] - prices[buy_day]To maximize profit, for every potential sell day, we want the lowest possible buy price seen so far to the left of it. This is the core insight that drives the efficient solution.If at any point the current price is lower than our tracked minimum, there is no point keeping the old minimum — the new one is strictly better for any future sell day.Intuition — The Two Pointer ApproachWe use two pointers i (buy pointer) and j (sell pointer), both starting at the beginning with i = 0 and j = 1.At every step we ask: is prices[j] greater than prices[i]?If yes → this is a profitable pair. Compute the profit and update the maximum if it's better.If no → prices[j] is cheaper than prices[i]. There's no reason to keep i where it is — any future sell day would be better served by buying at j instead. So we move i to j.Either way, j always moves forward by 1 until it reaches the end of the array.Why Moving i to j is CorrectThis is the most important conceptual point. When prices[j] < prices[i], you might wonder — why not just skip j and move on? Why move i?Because for any future day k > j, the profit buying at j is:prices[k] - prices[j]And the profit buying at i is:prices[k] - prices[i]Since prices[j] < prices[i], buying at j will always give a higher or equal profit for the same sell day k. So we update i = j — there is no scenario where keeping the old i is better.Dry Run — Example 1 (Step by Step)Input: prices = [7, 1, 5, 3, 6, 4]We start with i = 0, j = 1, maxP = 0.Step 1: i = 0, j = 1 → prices[i] = 7, prices[j] = 17 > 1 → prices[j] is cheaper. Move i to j. i = 1, j moves to 2. maxP = 0.Step 2: i = 1, j = 2 → prices[i] = 1, prices[j] = 51 < 5 → Profitable! profit = 5 - 1 = 4. 4 > 0 → update maxP = 4. j moves to 3.Step 3: i = 1, j = 3 → prices[i] = 1, prices[j] = 31 < 3 → Profitable! profit = 3 - 1 = 2. 2 < 4 → maxP stays 4. j moves to 4.Step 4: i = 1, j = 4 → prices[i] = 1, prices[j] = 61 < 6 → Profitable! profit = 6 - 1 = 5. 5 > 4 → update maxP = 5. j moves to 5.Step 5: i = 1, j = 5 → prices[i] = 1, prices[j] = 41 < 4 → Profitable! profit = 4 - 1 = 3. 3 < 5 → maxP stays 5. j moves to 6. j = 6 = prices.length → loop ends.Output: maxP = 5 ✅ (Buy at day 2 price=1, sell at day 5 price=6)Dry Run — Example 2 (Step by Step)Input: prices = [7, 6, 4, 3, 1]We start with i = 0, j = 1, maxP = 0.Step 1: i = 0, j = 1 → prices[i] = 7, prices[j] = 67 > 6 → Move i to j. i = 1, j moves to 2. maxP = 0.Step 2: i = 1, j = 2 → prices[i] = 6, prices[j] = 46 > 4 → Move i to j. i = 2, j moves to 3. maxP = 0.Step 3: i = 2, j = 3 → prices[i] = 4, prices[j] = 34 > 3 → Move i to j. i = 3, j moves to 4. maxP = 0.Step 4: i = 3, j = 4 → prices[i] = 3, prices[j] = 13 > 1 → Move i to j. i = 4, j moves to 5. j = 5 = prices.length → loop ends.Output: maxP = 0 ✅ (Prices only went down, no profitable transaction exists)The Code — Implementationclass Solution {public int maxProfit(int[] prices) {int i = 0; // Buy pointer — points to the current minimum price dayint j = 1; // Sell pointer — scans forward through the arrayint maxP = 0; // Tracks the maximum profit seen so far// j scans from day 1 to the end of the arraywhile (i < j && j < prices.length) {if (prices[i] > prices[j]) {// prices[j] is cheaper than current buy price// Move buy pointer to j — buying here is strictly better// for any future sell dayi = j;} else {// prices[j] > prices[i] — this is a profitable pair// Calculate profit and update maxP if it's the best so farint profit = prices[j] - prices[i];if (profit > maxP) {maxP = profit;}}// Always move the sell pointer forwardj++;}// If no profitable transaction was found, maxP remains 0return maxP;}}Code Walkthrough — Step by StepInitialization: i = 0 acts as our buy day pointer (always pointing to the lowest price seen so far). j = 1 is our sell day pointer scanning forward. maxP = 0 is our answer — defaulting to 0 handles the case where no profit is possible.The loop condition: i < j ensures we never sell before buying. j < prices.length ensures we don't go out of bounds.When prices[i] > prices[j]: The current sell day price is cheaper than our buy day. We update i = j, because buying at j dominates buying at i for all future sell days.When prices[j] >= prices[i]: We have a potential profit. We compute it and update maxP if it beats the current best.j always increments: Regardless of which branch we take, j++ moves the sell pointer forward every iteration — this is what drives the loop to completion.Common Mistakes to AvoidNot returning 0 for no-profit cases: If prices are strictly decreasing, maxP never gets updated and stays 0. The initialization maxP = 0 handles this correctly — never initialize it to a negative number.Using a nested loop (brute force): A common first instinct is two nested loops checking every pair. That is O(N²) and will TLE on large inputs. The two pointer approach solves it in O(N).Thinking you need to sort: Sorting destroys the order of days, which is fundamental to the problem. Never sort the prices array here.Moving i forward by 1 instead of to j: When prices[j] < prices[i], some people write i++ instead of i = j. This is wrong — you might miss the new minimum entirely and waste iterations.Complexity AnalysisTime Complexity: O(N) The j pointer traverses the array exactly once from index 1 to the end. The i pointer only moves forward and never exceeds j. So the entire algorithm is a single linear pass — O(N).Space Complexity: O(1) No extra arrays, maps, or stacks are used. Only three integer variables — i, j, and maxP.Alternative Way to Think About It (Min Tracking)Some people write this problem using a minPrice variable instead of two pointers. Both approaches are equivalent — the two pointer framing is slightly more intuitive visually, but here is the min-tracking version for reference:int minPrice = Integer.MAX_VALUE;int maxProfit = 0;for (int price : prices) {if (price < minPrice) {minPrice = price;} else if (price - minPrice > maxProfit) {maxProfit = price - minPrice;}}return maxProfit;The logic is the same — always track the cheapest buy day seen so far, and for each day compute what profit would look like if you sold today.Similar Problems (Build on This Foundation)LeetCode 122 — Best Time to Buy and Sell Stock II (multiple transactions allowed) [ Blog is also avaliable on this - Read Now ]LeetCode 123 — Best Time to Buy and Sell Stock III (at most 2 transactions) [ Blog is also avaliable on this - Read Now ]LeetCode 188 — Best Time to Buy and Sell Stock IV (at most k transactions)LeetCode 309 — Best Time to Buy and Sell Stock with CooldownLeetCode 714 — Best Time to Buy and Sell Stock with Transaction FeeLeetCode 121 is the foundation. Master this one deeply before moving to the others — they all build on the same core idea.Key Takeaways✅ For every potential sell day, the best buy day is always the minimum price seen to its left — this drives the whole approach.✅ When the sell pointer finds a cheaper price than the buy pointer, always move the buy pointer there — it strictly dominates the old buy day for all future sells.✅ Initialize maxP = 0 so that no-profit scenarios (prices only going down) are handled automatically.✅ The two pointer approach solves this in a single linear pass — O(N) time and O(1) space.✅ j always increments every iteration — i only moves when a cheaper price is found.Happy Coding! If this clicked for you, the entire Stock series on LeetCode will feel much more approachable.

LeetCodeTwo PointersEasyJavaDSA
Quick Sort Algorithm Explained | Java Implementation, Partition Logic & Complexity

Quick Sort Algorithm Explained | Java Implementation, Partition Logic & Complexity

IntroductionQuick Sort is one of the most powerful and widely used sorting algorithms in computer science. It follows the Divide and Conquer approach and is known for its excellent average-case performance.What makes Quick Sort special is:It sorts in-place (no extra array required)It is faster in practice than many O(n log n) algorithms like Merge SortIt is heavily used in real-world systems and librariesIn this article, we’ll go deep into:Intuition behind Quick SortPartition logic (most important part)Step-by-step dry runJava implementation with commentsTime complexity analysisCommon mistakes and optimizations🔗 Problem LinkGeeksforGeeks: Quick SortProblem StatementGiven an array arr[], sort it in ascending order using Quick Sort.Requirements:Use Divide and ConquerChoose pivot elementPlace pivot in correct positionElements smaller → left sideElements greater → right sideExamplesExample 1Input:arr = [4, 1, 3, 9, 7]Output:[1, 3, 4, 7, 9]Example 2Input:arr = [2, 1, 6, 10, 4, 1, 3, 9, 7]Output:[1, 1, 2, 3, 4, 6, 7, 9, 10]Core Idea of Quick SortPick a pivot → Place it correctly → Recursively sort left & right🔥 Key Insight (Partition is Everything)Quick Sort depends entirely on partitioning:👉 After partition:Pivot is at its correct sorted positionLeft side → smaller elementsRight side → larger elementsIntuition (Visual Understanding)Consider:[4, 1, 3, 9, 7]Step 1: Choose PivotLet’s say pivot = 4Step 2: Rearrange Elements[1, 3] 4 [9, 7]Now:Left → smallerRight → largerStep 3: Apply RecursivelyLeft: [1, 3]Right: [9, 7]Final result:[1, 3, 4, 7, 9]Partition Logic (Most Important)Your implementation uses:Pivot = first elementTwo pointers:i → moves forwardj → moves backwardJava Codeclass Solution { public void quickSort(int[] arr, int low, int high) { // Base case: if array has 1 or 0 elements if (low < high) { // Partition array and get pivot index int pivotInd = partition(arr, low, high); // Sort left part quickSort(arr, low, pivotInd - 1); // Sort right part quickSort(arr, pivotInd + 1, high); } } // Function to swap two elements void swap(int[] arr, int i, int j) { int temp = arr[i]; arr[i] = arr[j]; arr[j] = temp; } private int partition(int[] arr, int low, int high) { int pivot = arr[low]; // choosing first element as pivot int i = low + 1; // start from next element int j = high; // start from end while (i <= j) { // Move i forward until element > pivot while (i <= high && arr[i] <= pivot) { i++; } // Move j backward until element <= pivot while (j >= low && arr[j] > pivot) { j--; } // Swap if pointers haven't crossed if (i < j) { swap(arr, i, j); } } // Place pivot at correct position swap(arr, low, j); return j; // return pivot index }}Step-by-Step Dry RunInput:[4, 1, 3, 9, 7]Execution:Pivot = 4i → moves until element > 4j → moves until element ≤ 4Swaps happen → pivot placed correctlyFinal partition:[1, 3, 4, 9, 7]Complexity AnalysisTime ComplexityCaseComplexityBest CaseO(n log n)Average CaseO(n log n)Worst CaseO(n²)Why Worst Case Happens?When array is:Already sortedReverse sortedPivot always becomes smallest/largest.Space ComplexityO(log n) (recursion stack)❌ Common MistakesWrong partition logicInfinite loops in while conditionsIncorrect pivot placementNot handling duplicates properly⚡ Optimizations1. Random PivotAvoid worst-case:int pivotIndex = low + new Random().nextInt(high - low + 1);swap(arr, low, pivotIndex);2. Median of ThreeChoose better pivot:median(arr[low], arr[mid], arr[high])Quick Sort vs Merge SortFeatureQuick SortMerge Sort link to get moreSpaceO(log n)O(n)SpeedFaster (practical)StableWorst CaseO(n²)O(n log n)Why Quick Sort is PreferredCache-friendlyIn-place sortingFaster in real-world scenariosKey TakeawaysPartition is the heart of Quick SortPivot must be placed correctlyRecursion splits problem efficientlyAvoid worst case using random pivotWhen to Use Quick SortLarge arraysMemory constraints (in-place)Performance-critical applicationsConclusionQuick Sort is one of the most efficient and practical sorting algorithms. Mastering its partition logic is crucial for solving advanced problems and performing well in coding interviews.Understanding how pointers move and how pivot is placed will make this algorithm intuitive and powerful.Frequently Asked Questions (FAQs)1. Is Quick Sort stable?No, it is not stable.2. Why is Quick Sort faster than Merge Sort?Because it avoids extra space and is cache-efficient.3. What is the most important part?👉 Partition logic

MediumJavaSortingQuick SortGeeksofGeeks
Queue Data Structure Complete Guide - Java Explained With All Operations

Queue Data Structure Complete Guide - Java Explained With All Operations

IntroductionIf you have been learning Data Structures and Algorithms, you have probably already spent time with arrays, linked lists, and stacks. Now it is time to meet one of the most important and widely used data structures in computer science — the Queue.Queue is not just a theoretical concept. It powers some of the most critical systems you use every day — from how your printer handles jobs, to how your CPU schedules tasks, to how Google Maps finds the shortest path between two locations. Understanding Queue deeply means understanding how real systems work.In this complete guide we will cover absolutely everything — what a Queue is, how it differs from a Stack, every type of Queue, all operations with code, Java implementations, time and space complexity, common interview questions, and the most important LeetCode problems that use Queue.What Is a Queue?A Queue is a linear data structure that follows the FIFO principle — First In First Out. This means the element that was added first is the one that gets removed first.Think of it exactly like a real-world queue (a line of people). The person who joined the line first gets served first. No cutting in line, no serving from the back — strict order from front to back.This is the fundamental difference between a Queue and a Stack:Stack → LIFO (Last In First Out) — like a stack of plates, you take from the topQueue → FIFO (First In First Out) — like a line of people, you serve from the frontReal Life Examples of QueueBefore writing a single line of code, let us understand where queues appear in real life. This will make every technical concept feel natural.Printer Queue — when you send multiple documents to print, they print in the order they were sent. The first document sent prints first.CPU Task Scheduling — your operating system manages running processes in a queue. Tasks get CPU time in the order they arrive (in basic scheduling).Customer Service Call Center — when you call a helpline and are put on hold, you are placed in a queue. The first caller on hold gets connected first.WhatsApp Messages — messages are delivered in the order they are sent. The first message sent is the first one received.BFS (Breadth First Search) — every time you use Google Maps or any navigation app to find the shortest path, it uses BFS internally which is entirely powered by a Queue.Ticket Booking Systems — online booking portals process requests in the order they arrive. First come first served.Queue Terminology — Key Terms You Must KnowBefore diving into code, let us get the vocabulary right:Front — the end from which elements are removed (dequeued). This is where the "first person in line" stands.Rear (or Back) — the end at which elements are added (enqueued). New arrivals join here.Enqueue — the operation of adding an element to the rear of the queue. Like joining the back of a line.Dequeue — the operation of removing an element from the front of the queue. Like the first person in line being served and leaving.Peek (or Front) — looking at the front element without removing it. Like seeing who is first in line without serving them yet.isEmpty — checking whether the queue has no elements.isFull — relevant for fixed-size queues, checking whether no more elements can be added.Types of QueuesThis is where most beginners get confused. There is not just one type of Queue — there are several variations each designed to solve specific problems.1. Simple Queue (Linear Queue)The most basic form. Elements enter from the rear and leave from the front. Strict FIFO, nothing fancy.Enqueue → [ 1 | 2 | 3 | 4 | 5 ] → Dequeue rear frontProblem with Simple Queue: In array-based implementation, once elements are dequeued from the front, those slots cannot be reused even if there is space. This wastes memory. This is why Circular Queue was invented.2. Circular QueueIn a Circular Queue, the rear wraps around to the front when it reaches the end of the array. The last position connects back to the first, forming a circle. This solves the wasted space problem of simple queues. [1] [2] [3] / \ [6] [4] \ / [5] ← rearUsed in: CPU scheduling, memory management, traffic light systems, streaming buffers.3. Double Ended Queue (Deque)A Deque (pronounced "deck") allows insertion and deletion from both ends — front and rear. It is the most flexible queue type.Enqueue Front → [ 1 | 2 | 3 | 4 | 5 ] → Dequeue FrontEnqueue Rear → [ 1 | 2 | 3 | 4 | 5 ] → Dequeue RearTwo subtypes:Input Restricted Deque — insertion only at rear, deletion from both endsOutput Restricted Deque — deletion only at front, insertion at both endsUsed in: browser history (back and forward), undo-redo operations, sliding window problems.4. Priority QueueElements are not served in FIFO order — instead each element has a priority and the element with the highest priority is served first regardless of when it was added.Think of an emergency room. A patient with a critical injury jumps ahead of someone with a minor cut even if they arrived later.Two types:Max Priority Queue — highest value = highest priorityMin Priority Queue — lowest value = highest priorityUsed in: Dijkstra's shortest path, Huffman encoding, A* search algorithm, task scheduling with priorities.5. Blocking QueueA thread-safe queue used in multi-threading. If the queue is empty, a thread trying to dequeue will wait (block) until an element is available. If the queue is full, a thread trying to enqueue will wait until space is available.Used in: Producer-Consumer problems, thread pool implementations, Java's java.util.concurrent package.Queue Operations and Time ComplexityEvery queue operation has a specific time complexity that you must know cold for interviews.OperationDescriptionTime ComplexityEnqueueAdd element to rearO(1)DequeueRemove element from frontO(1)Peek/FrontView front elementO(1)isEmptyCheck if queue is emptyO(1)SizeNumber of elementsO(1)SearchFind a specific elementO(n)Space Complexity: O(n) — where n is the number of elements stored.All core queue operations are O(1). This is what makes Queue so powerful — no matter how many elements are in the queue, adding and removing always takes constant time.Implementing Queue in Java — All WaysJava gives you multiple ways to use a Queue. Let us go through each one.Way 1: Using LinkedList (Most Common)LinkedList implements the Queue interface in Java. This is the most commonly used Queue implementation.import java.util.LinkedList;import java.util.Queue;Queue<Integer> queue = new LinkedList<>();// Enqueue — add to rearqueue.offer(10);queue.offer(20);queue.offer(30);// Peek — view front without removingSystem.out.println(queue.peek()); // 10// Dequeue — remove from frontSystem.out.println(queue.poll()); // 10System.out.println(queue.poll()); // 20// Check emptySystem.out.println(queue.isEmpty()); // false// SizeSystem.out.println(queue.size()); // 1offer() vs add() — both add to the queue. add() throws an exception if the queue is full (for bounded queues). offer() returns false instead. Always prefer offer().poll() vs remove() — both remove from front. remove() throws an exception if queue is empty. poll() returns null. Always prefer poll().peek() vs element() — both view the front. element() throws exception if empty. peek() returns null. Always prefer peek().Way 2: Using ArrayDeque (Fastest)ArrayDeque is faster than LinkedList for Queue operations because it uses a resizable array internally with no node allocation overhead.import java.util.ArrayDeque;import java.util.Queue;Queue<Integer> queue = new ArrayDeque<>();queue.offer(1);queue.offer(2);queue.offer(3);System.out.println(queue.peek()); // 1System.out.println(queue.poll()); // 1System.out.println(queue.size()); // 2When to use ArrayDeque over LinkedList? Use ArrayDeque whenever possible for Queue or Stack operations. It is faster because it avoids the overhead of node objects that LinkedList creates for every element. In competitive programming and interviews, ArrayDeque is the preferred choice.Way 3: Using Deque (Double Ended Queue)import java.util.ArrayDeque;import java.util.Deque;Deque<Integer> deque = new ArrayDeque<>();// Add to frontdeque.offerFirst(10);// Add to reardeque.offerLast(20);deque.offerLast(30);// Remove from frontSystem.out.println(deque.pollFirst()); // 10// Remove from rearSystem.out.println(deque.pollLast()); // 30// Peek front and rearSystem.out.println(deque.peekFirst()); // 20System.out.println(deque.peekLast()); // 20Way 4: Using PriorityQueueimport java.util.PriorityQueue;// Min Heap — smallest element has highest priorityPriorityQueue<Integer> minPQ = new PriorityQueue<>();minPQ.offer(30);minPQ.offer(10);minPQ.offer(20);System.out.println(minPQ.poll()); // 10 — smallest comes out first// Max Heap — largest element has highest priorityPriorityQueue<Integer> maxPQ = new PriorityQueue<>((a, b) -> b - a);maxPQ.offer(30);maxPQ.offer(10);maxPQ.offer(20);System.out.println(maxPQ.poll()); // 30 — largest comes out firstWay 5: Implementing Queue From Scratch Using ArrayUnderstanding the underlying implementation helps you in interviews when asked to build one from scratch.class MyQueue { private int[] arr; private int front; private int rear; private int size; private int capacity; public MyQueue(int capacity) { this.capacity = capacity; arr = new int[capacity]; front = 0; rear = -1; size = 0; } public void enqueue(int val) { if (size == capacity) { System.out.println("Queue is full!"); return; } rear = (rear + 1) % capacity; // circular wrapping arr[rear] = val; size++; } public int dequeue() { if (isEmpty()) { System.out.println("Queue is empty!"); return -1; } int val = arr[front]; front = (front + 1) % capacity; // circular wrapping size--; return val; } public int peek() { if (isEmpty()) return -1; return arr[front]; } public boolean isEmpty() { return size == 0; } public int size() { return size; }}Notice the % capacity in enqueue and dequeue — that is what makes it a Circular Queue. Without this, once the rear reaches the end of the array, you cannot add more even if front has moved forward and freed up space.Way 6: Implementing Queue Using Two StacksThis is a very popular interview question — implement a Queue using two stacks. The idea is to use one stack for enqueue and another for dequeue.class QueueUsingTwoStacks { Stack<Integer> s1 = new Stack<>(); // for enqueue Stack<Integer> s2 = new Stack<>(); // for dequeue public void enqueue(int val) { s1.push(val); // always push to s1 } public int dequeue() { if (s2.isEmpty()) { // transfer all elements from s1 to s2 // this reverses the order, giving FIFO behavior while (!s1.isEmpty()) { s2.push(s1.pop()); } } return s2.pop(); } public int peek() { if (s2.isEmpty()) { while (!s1.isEmpty()) { s2.push(s1.pop()); } } return s2.peek(); } public boolean isEmpty() { return s1.isEmpty() && s2.isEmpty(); }}Why does this work?When you transfer elements from s1 to s2, the order reverses. The element that was added first to s1 ends up on top of s2 — which means it gets dequeued first. FIFO achieved using two LIFOs!Amortized time complexity: Each element is pushed and popped at most twice (once in s1, once in s2). So dequeue is O(1) amortized even though individual calls might take O(n).This is LeetCode 232 — Implement Queue using Stacks.Queue vs Stack — Side by SideFeatureQueueStackPrincipleFIFO — First In First OutLIFO — Last In First OutInsert atRearTopRemove fromFrontTopReal lifeLine of peopleStack of platesJava classLinkedList, ArrayDequeStack, ArrayDequeMain useBFS, schedulingDFS, backtracking, parsingPeekFront elementTop elementBFS — The Most Important Application of QueueBreadth First Search (BFS) is the single most important algorithm that uses a Queue. Understanding BFS is why Queue matters so much in DSA.BFS explores a graph or tree level by level — all nodes at distance 1 first, then all at distance 2, and so on. A Queue naturally enforces this level-by-level behavior.public void bfs(int start, List<List<Integer>> graph) { Queue<Integer> queue = new LinkedList<>(); boolean[] visited = new boolean[graph.size()]; queue.offer(start); visited[start] = true; while (!queue.isEmpty()) { int node = queue.poll(); // process front node System.out.print(node + " "); for (int neighbor : graph.get(node)) { if (!visited[neighbor]) { visited[neighbor] = true; queue.offer(neighbor); // add unvisited neighbors to rear } } }}Why Queue and not Stack for BFS? Queue ensures you process all neighbors of a node before going deeper. Stack would take you deep into one path first — that is DFS, not BFS. The FIFO property is what guarantees level-by-level exploration.BFS with Queue is used in:Shortest path in unweighted graphsLevel order traversal of treesFinding connected componentsWord ladder problemsRotten oranges, flood fill, and matrix BFS problemsLevel Order Traversal — BFS on TreesOne of the most common Queue problems in interviews is Level Order Traversal of a binary tree.public List<List<Integer>> levelOrder(TreeNode root) { List<List<Integer>> result = new ArrayList<>(); if (root == null) return result; Queue<TreeNode> queue = new LinkedList<>(); queue.offer(root); while (!queue.isEmpty()) { int levelSize = queue.size(); // number of nodes at current level List<Integer> level = new ArrayList<>(); for (int i = 0; i < levelSize; i++) { TreeNode node = queue.poll(); level.add(node.val); if (node.left != null) queue.offer(node.left); if (node.right != null) queue.offer(node.right); } result.add(level); } return result;}The key trick here is using queue.size() at the start of each while loop iteration to know exactly how many nodes belong to the current level. Process exactly that many nodes, then move to the next level.This is LeetCode 102 — Binary Tree Level Order Traversal.Sliding Window Maximum — Monotonic DequeOne of the most impressive Queue applications is the Sliding Window Maximum problem using a Monotonic Deque. This is the queue equivalent of the Monotonic Stack pattern you saw in stack problems.The idea — maintain a deque that stores indices of elements in decreasing order. The front always holds the index of the maximum element in the current window.public int[] maxSlidingWindow(int[] nums, int k) { Deque<Integer> deque = new ArrayDeque<>(); // stores indices int[] result = new int[nums.length - k + 1]; int idx = 0; for (int i = 0; i < nums.length; i++) { // remove indices that are out of the current window while (!deque.isEmpty() && deque.peekFirst() < i - k + 1) { deque.pollFirst(); } // remove indices whose values are smaller than current // they can never be the maximum for any future window while (!deque.isEmpty() && nums[deque.peekLast()] < nums[i]) { deque.pollLast(); } deque.offerLast(i); // window is fully formed, record maximum (front of deque) if (i >= k - 1) { result[idx++] = nums[deque.peekFirst()]; } } return result;}This gives O(n) time for what would otherwise be an O(n×k) problem. This is LeetCode 239 — Sliding Window Maximum.Java Queue Interface — Complete Method ReferenceHere is every method you will ever need from Java's Queue and Deque interfaces:Queue Methods:offer(e) — add to rear, returns false if full (preferred over add) poll() — remove from front, returns null if empty (preferred over remove) peek() — view front without removing, returns null if empty (preferred over element) isEmpty() — returns true if no elements size() — returns number of elements contains(o) — returns true if element existsDeque Additional Methods:offerFirst(e) — add to front offerLast(e) — add to rear pollFirst() — remove from front pollLast() — remove from rear peekFirst() — view front peekLast() — view rearPriorityQueue Specific:offer(e) — add with natural ordering or custom comparator poll() — remove element with highest priority peek() — view highest priority element without removingCommon Interview Questions About QueueThese are the questions interviewers ask to test your understanding of queues conceptually — not just coding.Q1. What is the difference between Queue and Stack? Queue is FIFO — elements are removed in the order they were added. Stack is LIFO — the most recently added element is removed first. Queue removes from the front, Stack removes from the top.Q2. Why is ArrayDeque preferred over LinkedList for Queue in Java? ArrayDeque uses a resizable array internally and has better cache locality and no node allocation overhead. LinkedList creates a new node object for every element added, which means more garbage collection pressure. ArrayDeque is faster in practice for most Queue use cases.Q3. When would you use a PriorityQueue instead of a regular Queue? When the order of processing depends on priority rather than arrival order. For example in a hospital, critical patients are treated before minor cases regardless of when they arrived. Or in Dijkstra's algorithm, always processing the shortest known distance first.Q4. How is Queue used in BFS? BFS uses a Queue to explore nodes level by level. The starting node is enqueued first. Each time a node is dequeued, all its unvisited neighbors are enqueued. Since Queue is FIFO, all neighbors of a node are processed before going deeper — guaranteeing level-by-level exploration.Q5. What is the difference between poll() and remove() in Java Queue? Both remove the front element. remove() throws NoSuchElementException if the queue is empty. poll() returns null instead of throwing. Always use poll() for safer code.Q6. Can a Queue have duplicates? Yes. Queue does not have any restriction on duplicate values unlike Sets. The same value can appear multiple times in a Queue.Q7. What is a Blocking Queue and when is it used? A Blocking Queue is a thread-safe Queue used in multi-threaded applications. When a thread tries to dequeue from an empty queue, it blocks (waits) until an element is available. When a thread tries to enqueue into a full queue, it blocks until space is available. Used in Producer-Consumer patterns.Top LeetCode Problems on QueueHere are the most important LeetCode problems that use Queue — organized from beginner to advanced:Beginner Level:232. Implement Queue using Stacks — implement Queue with two stacks, classic interview question225. Implement Stack using Queues — reverse of 232, implement Stack using Queue933. Number of Recent Calls — sliding window with QueueIntermediate Level:102. Binary Tree Level Order Traversal — BFS on tree, must know107. Binary Tree Level Order Traversal II — same but bottom up994. Rotting Oranges — multi-source BFS on grid1091. Shortest Path in Binary Matrix — BFS shortest path542. 01 Matrix — multi-source BFS, distance to nearest 0127. Word Ladder — BFS on word graph, classicAdvanced Level:239. Sliding Window Maximum — monotonic deque, must know862. Shortest Subarray with Sum at Least K — monotonic deque with prefix sums407. Trapping Rain Water II — 3D BFS with priority queue787. Cheapest Flights Within K Stops — BFS with constraintsQueue Cheat Sheet — Everything at a GlanceCreate a Queue:Queue<Integer> q = new LinkedList<>(); // standardQueue<Integer> q = new ArrayDeque<>(); // faster, preferredDeque<Integer> dq = new ArrayDeque<>(); // double endedPriorityQueue<Integer> pq = new PriorityQueue<>(); // min heapPriorityQueue<Integer> pq = new PriorityQueue<>((a,b) -> b-a); // max heapCore Operations:q.offer(x); // enqueueq.poll(); // dequeueq.peek(); // front elementq.isEmpty(); // check emptyq.size(); // number of elementsDeque Operations:dq.offerFirst(x); // add to frontdq.offerLast(x); // add to reardq.pollFirst(); // remove from frontdq.pollLast(); // remove from reardq.peekFirst(); // view frontdq.peekLast(); // view rearBFS Template:Queue<Integer> queue = new LinkedList<>();queue.offer(start);visited[start] = true;while (!queue.isEmpty()) { int node = queue.poll(); for (int neighbor : graph.get(node)) { if (!visited[neighbor]) { visited[neighbor] = true; queue.offer(neighbor); } }}ConclusionQueue is one of those data structures that appears simple on the surface but has incredible depth once you start exploring its variations and applications. From the basic FIFO concept to Circular Queues, Deques, Priority Queues, Monotonic Deques, and BFS — each layer adds a new tool to your problem-solving arsenal.Here is the learning path to follow based on everything covered in this guide:Start with understanding FIFO vs LIFO and when each applies. Then get comfortable with Java's Queue interface — offer, poll, peek. Practice the BFS template until it feels automatic. Then move to Level Order Traversal problems. Once BFS clicks, tackle multi-source BFS problems like Rotting Oranges. Finally learn the Monotonic Deque pattern for sliding window problems.Master these and you will handle every Queue problem in any coding interview with confidence.

QueueData StructureJavaBFSDequePriority QueueCircular Queue
LeetCode 258 — Add Digits | Brute Force to O(1) Digital Root Trick Explained in Java

LeetCode 258 — Add Digits | Brute Force to O(1) Digital Root Trick Explained in Java

IntroductionSome problems on LeetCode look too simple to teach you anything meaningful. LeetCode 258 — Add Digits is one of those problems that tricks you with its simplicity. The simulation is beginner-friendly and easy to code in five minutes, but hiding right underneath the surface is a beautiful piece of number theory that lets you solve the entire thing in a single arithmetic expression — no loops, no recursion, pure O(1) math.Whether you are just starting your DSA journey or preparing for coding interviews, this problem is worth understanding deeply. Not just for the answer, but for the mathematical intuition that produces it. By the end of this article, you will not just know the formula — you will understand exactly why it works, where it comes from, and how to derive it yourself even if you forget it during an interview.Problem LinkLeetCode 258 — Add Digits https://leetcode.com/problems/add-digits/Problem StatementGiven an integer num, repeatedly add all its digits until the result has only one digit, and return it.The follow-up asks: can you solve this in O(1) time without any loop or recursion?Approach 1 — Simulation (The Intuitive Way)IntuitionThe problem statement itself tells you exactly what to do. Keep summing the digits of the number until you are left with a single digit. You simulate this literally using nested loops.To extract digits from any integer, two operations do all the work:num % 10 isolates the rightmost digit. For 38, that gives 8.num / 10 removes the rightmost digit. For 38, that leaves 3.You accumulate the digits into a sum, replace num with that sum, and repeat the whole process until num drops below 10.Dry Runnum = 38Outer loop iteration 1:38 % 10 = 8 → sum = 8, num = 33 % 10 = 3 → sum = 11, num = 0Inner loop ends. num = 11Outer loop iteration 2:11 % 10 = 1 → sum = 1, num = 11 % 10 = 1 → sum = 2, num = 0Inner loop ends. num = 2num < 10 → outer loop exits → return 2 ✅Codeclass Solution { public int addDigits(int num) { // If already a single digit, return immediately — no work needed if (num < 10) return num; // Keep repeating the digit sum process until num becomes single digit while (num >= 10) { int sum = 0; // Extract each digit from right to left using modulo and division while (num > 0) { int dig = num % 10; // isolate the last digit num = num / 10; // strip the last digit off sum = sum + dig; // accumulate into running sum } // Replace num with the sum of its digits and check again num = sum; } return num; }}ComplexityTime Complexity: O(log n) — Each iteration reduces the number to the sum of its digits, shrinking it dramatically. The number of passes is very small even for large inputs.Space Complexity: O(1) — Only a handful of integer variables. No extra memory allocated.This passes all test cases cleanly. But the follow-up challenges you to eliminate the loop entirely. That is where things get genuinely interesting.Approach 2 — O(1) Digital Root Formula (The Mathematical Way)Starting With ObservationBefore jumping to the formula, let us build the intuition from scratch the way a mathematician would — by looking at small cases and hunting for a pattern.Let us compute the result for every number from 0 to 27 manually:num → result0 → 01 → 12 → 23 → 34 → 45 → 56 → 67 → 78 → 89 → 910 → 1 (1+0)11 → 2 (1+1)12 → 3 (1+2)13 → 4 (1+3)14 → 5 (1+4)15 → 6 (1+5)16 → 7 (1+6)17 → 8 (1+7)18 → 9 (1+8)19 → 1 (1+9=10, then 1+0=1)20 → 2 (2+0)21 → 3 (2+1)22 → 4 (2+2)23 → 5 (2+3)24 → 6 (2+4)25 → 7 (2+5)26 → 8 (2+6)27 → 9 (2+7)The pattern is impossible to miss. After 0, the results cycle through 1, 2, 3, 4, 5, 6, 7, 8, 9 and then repeat, endlessly, with a period of exactly 9.Now the question is — why? Why does the digit sum cycle with period 9? To understand that, we need to talk about what happens to a number modulo 9.The Core Mathematical Property — Why Digits and Modulo 9 Are ConnectedHere is the fundamental theorem that powers this entire solution:Any positive integer is congruent to the sum of its digits modulo 9.In plain English: if you take a number, divide it by 9, and note the remainder — that remainder is the same as the remainder you get when you divide the sum of its digits by 9.Let us prove this properly so it actually makes sense rather than just being a thing you memorize.Take any two-digit number. You can write it as:num = 10a + bWhere a is the tens digit and b is the units digit. For example, 38 = 10(3) + 8.Now notice that 10 = 9 + 1, so:num = (9 + 1)a + b = 9a + a + bWhen you compute num % 9:num % 9 = (9a + a + b) % 9 = (9a % 9) + (a + b) % 9 = 0 + (a + b) % 9 = (a + b) % 9And a + b is exactly the digit sum. So num % 9 = digitSum % 9. They share the same remainder modulo 9.This same logic extends to three-digit numbers. Write num = 100a + 10b + c. Since 100 = 99 + 1 and 10 = 9 + 1:num = (99 + 1)a + (9 + 1)b + c = 99a + 9b + a + b + cWhen you take % 9, the 99a and 9b parts vanish because they are divisible by 9, and you are left with (a + b + c) % 9 — which is again just the digit sum modulo 9.This pattern holds for numbers of any length. Every power of 10 is just 1 more than a multiple of 9 — 10 = 9+1, 100 = 99+1, 1000 = 999+1 — so all the place-value multipliers disappear modulo 9, leaving only the digit sum behind.This is the reason the digit sum process produces the same final result as the original number modulo 9. The digit sum operation preserves the residue modulo 9 at every step.Why the Cycle Has Period 9Now that we know num ≡ digitSum (mod 9), the cycling pattern makes total sense.Every time you apply the digit sum operation, the result changes but the residue modulo 9 stays the same. You keep applying it until you hit a single digit. The single-digit numbers are 0 through 9. Among those, the residue modulo 9 of each single digit is just the digit itself — except 9, whose residue is 0.So the final single digit you land on is determined entirely by what num % 9 is:num % 9 == 0 → result is 9 (for any positive num)num % 9 == 1 → result is 1num % 9 == 2 → result is 2...num % 9 == 8 → result is 8The only exception is num = 0 itself, which is a genuine zero, not a nine.Translating This Into a FormulaIf we tried to write this directly as num % 9, there is one problem: multiples of 9 like 9, 18, 27 give a remainder of 0, but the correct answer for all of them is 9, not 0.We need a formula that maps every positive integer to a value in 1..9 cyclically, rather than 0..8.The standard trick for shifting a zero-indexed cycle to a one-indexed cycle is to subtract 1 before taking the modulo and add 1 after:result = 1 + (num - 1) % 9Let us verify this on a few cases:num = 9: 1 + (9-1) % 9 = 1 + 8 % 9 = 1 + 8 = 9 ✅num = 18: 1 + (18-1) % 9 = 1 + 17 % 9 = 1 + 8 = 9 ✅num = 1: 1 + (1-1) % 9 = 1 + 0 = 1 ✅num = 10: 1 + (10-1) % 9 = 1 + 9 % 9 = 1 + 0 = 1 ✅num = 38: 1 + (38-1) % 9 = 1 + 37 % 9 = 1 + 1 = 2 ✅The only number this formula does not cover is num = 0, which is a special case handled separately since 0 has no digit sum cycle — it simply returns 0.Connecting It Back to the ObservationNow look at the table we built earlier through the lens of this formula. Numbers 1 through 9 map to themselves. Then 10 gives 1 + 0 = 1, same as 1. Numbers 10 through 18 are just 1 through 9 offset by 9. Then 19 wraps back to 1. The cycle length of 9 follows directly from the modulo-9 arithmetic. It is not a coincidence at all — it is the inevitable consequence of how place-value and modular arithmetic interact.Codeclass Solution { public int addDigits(int num) { // Special case: 0 is not part of the 1-9 cycle, it simply returns 0 if (num == 0) return 0; // Digital root formula derived from the congruence property modulo 9. // (num - 1) % 9 maps the range to 0..8 instead of the raw 0..8 cycle // that would make multiples of 9 return 0 incorrectly. // Adding 1 at the end shifts it back to the correct 1..9 range. return 1 + (num - 1) % 9; }}ComplexityTime Complexity: O(1) — A fixed number of arithmetic operations regardless of the size of num.Space Complexity: O(1) — No variables, no data structures, nothing allocated.Approach ComparisonApproachTimeSpaceLoop / RecursionSimulationO(log n)O(1)YesDigital Root FormulaO(1)O(1)NoBoth approaches are entirely correct and both pass all test cases. The simulation is more readable and immediately obvious to anyone reading the code. The digital root formula is what an interviewer is hoping you know when they ask the follow-up — and more importantly, if you understand the modulo-9 proof above, you can derive it on the spot rather than hoping you remembered it.Key TakeawaysThe most important thing this problem teaches you is not the formula itself. It is the habit of asking a deeper question when you see a repeated process: is there a closed-form mathematical pattern hiding inside this repetition?The digit sum operation looks like pure computation at first glance. But underneath it is modular arithmetic, and modular arithmetic has structure that can often be collapsed into a direct formula. That same insight — that repeated digit operations connect to modulo 9 — shows up in divisibility rules you learned in school. A number is divisible by 9 if and only if its digit sum is divisible by 9. A number is divisible by 3 if and only if its digit sum is divisible by 3. Both of those rules are the exact same theorem we used to derive the digital root formula here.Once you internalize this connection between digit sums and modulo 9, you will recognize it surfacing in other problems across number theory, checksum algorithms, and competitive programming. The formula is a one-liner. The understanding behind it is something you carry with you permanently.

Digital RootLeetCode EasyJavaNumber TheoryMath
Amazon OA: Find the Element Occurring Less Than K Times in a Sorted Array – Java Solution

Amazon OA: Find the Element Occurring Less Than K Times in a Sorted Array – Java Solution

IntroductionThis is a sorted array frequency problem that can appear in coding assessments and online assessments such as an Amazon OA.You are given a sorted array B of size N. Every distinct element occurs exactly K times except for one element, whose frequency is less than K.The task is to find that element.Because the array is sorted, all occurrences of the same element are located together. This allows us to process the array sequentially and keep track of the current element and its frequency.For example:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3Here:2 → 3 times3 → 2 times4 → 3 times5 → 3 timesTherefore, the answer is:3because 3 occurs fewer than K = 3 times.QuestionYou are given a sorted array B of size N.Every element in the array occurs exactly K times except one element, which occurs fewer than K times.Find that element.It is guaranteed that there is exactly one element whose frequency is less than K.ConstraintsN <= 100000K >= 21 <= B[i] <= 10000000000Since B[i] can be as large as 10^10, a Java long should be used to safely store the array values.ExampleConsider:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3Frequency table:Element Frequency2 33 24 35 3Only 3 occurs fewer than K times.Therefore:Output: 3Understanding the Sorted ArrayThe most important property of this problem is that the array is sorted.Because of that, identical elements always appear consecutively.For example:1 1 1 2 2 2 3 3 4 4 4We never have to search the entire array to count the occurrences of an element.We can simply scan from left to right.When the value changes, the frequency of the previous value is known.For example:1 1 1When we encounter 2, we know that:1 occurred 3 timesWe can compare this frequency with K.If it is less than K, then 1 is the required answer.Approach: Track the Current Element and Its FrequencyWe can maintain two variables:int cand;int count;where:cand represents the current element.count represents how many times that element has appeared so far.Initially:cand = arr[0];count = 1;Then we scan the remaining elements.There are three important situations.Case 1: Same ElementIf:cand == arr[i]then the current element is still being counted.So:count++;Case 2: Element Changes and Frequency Is KIf:cand != arr[i] && count == kthen the previous element occurred exactly K times.Therefore, we can start counting the new element:cand = arr[i];count = 1;Case 3: Element Changes and Frequency Is Less Than KIf:cand != arr[i] && count < kthen the previous element is the unique element whose frequency is less than K.So we can immediately stop.Java SolutionThe same logic can be implemented more cleanly as follows:class Main { public static void main(String[] args) { int[] arr = {1, 1, 2, 2, 2, 3, 3, 3}; int k = 3; int cand = arr[0]; int count = 1; for (int i = 1; i < arr.length; i++) { // Current element is still the same if (cand == arr[i]) { count++; } // Current element changed else { // Previous element occurred less than K times if (count < k) { break; } // Start counting the new element cand = arr[i]; count = 1; } } // The incomplete-frequency element may be the last element if (count < k) { System.out.println(cand); } }}Dry RunConsider:arr = [1, 1, 2, 2, 2, 3, 3, 3]k = 3Initially:cand = 1count = 1Now process the array.Step 1Current value:arr[1] = 1It is the same as cand.count = 2Step 2Current value:arr[2] = 2The value changed.Before moving to 2, we check the frequency of 1:count = 2k = 3Since:2 < 3we have found the answer.Therefore:Output: 1Another ExampleConsider:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3We start with:cand = 2count = 1After processing the three 2s:cand = 2count = 3The next value is 3.Since:count == Kwe move to the next candidate:cand = 3count = 1After processing the second 3:cand = 3count = 2The next value is 4.Now:count < Kbecause:2 < 3Therefore:3is the required answer.Important Edge Case: Answer at the EndThere is one important case to handle.Suppose the incomplete element is the last element in the array.For example:arr = [1, 1, 1, 2, 2]K = 3When the loop finishes, there is no next element that causes the value to change.So the condition:if (cand != arr[i])will never execute for the final 2.We therefore need one final check after the loop:if (count < k) { System.out.println(cand);}This handles the case where the answer is at the end.Complexity AnalysisWe scan the array only once.For every element, we perform constant-time operations.Therefore:Time Complexity:O(N)Space Complexity:O(1)This is efficient enough for:N <= 100000and does not require an additional HashMap or frequency array.Why Does the Sorted Property Matter?Without the sorted property, the same element could appear at different positions.For example:2 3 2 4 3 2In that case, simply maintaining the frequency of the current consecutive value would not work.We would need another approach such as a HashMap.But because the input is sorted:2 2 2 3 3 4 4 4all occurrences of an element form one continuous block.That is what allows us to solve the problem with:O(N) timeO(1) extra spaceA Simpler AlternativeBecause the array is sorted, another straightforward solution is to count consecutive equal values.For example:class Main { public static void main(String[] args) { int[] arr = {2, 2, 2, 3, 3, 4, 4, 4}; int k = 3; int count = 1; for (int i = 1; i <= arr.length; i++) { if (i < arr.length && arr[i] == arr[i - 1]) { count++; } else { if (count < k) { System.out.println(arr[i - 1]); break; } count = 1; } } }}This version focuses directly on counting each consecutive group.The idea is:Read same values ↓Count them ↓Value changes ↓Check count < K ↓If yes → answer foundInterview TipWhen an interview or OA problem gives you a sorted array, always ask yourself:What does sorting allow me to avoid?Here, sorting means all equal values are adjacent.Instead of using:HashMapor sorting the array again, we can simply maintain a running frequency.The important pattern is:Current value+Consecutive frequency+Check when value changesThis pattern is useful in many array problems involving duplicate or repeated elements.ConclusionThis Amazon OA-style problem can be solved efficiently by taking advantage of the fact that the input array is sorted.Since equal elements appear consecutively, we only need to maintain:current elementcurrent frequencyWhenever the element changes, we check whether its frequency was less than K.The solution requires:Time: O(N)Space: O(1)The main takeaway is that the sorted property removes the need for additional frequency data structures and lets us find the unique incomplete-frequency element with a single linear scan.

Amazon OAAmazon Online AssessmentJavaArraysFrequency CountingSorted ArrayDSAArray Problems
Search in a Binary Search Tree (LeetCode 700) Java Solution with Explanation and Dry Run

Search in a Binary Search Tree (LeetCode 700) Java Solution with Explanation and Dry Run

IntroductionBinary Search Tree (BST) is one of the most important data structures frequently asked in coding interviews and competitive programming. LeetCode 700 - Search in a Binary Search Tree is a beginner-friendly problem that helps developers understand how BST properties can be utilized to perform efficient searches.In this article, we will discuss the problem statement, understand the BST property, develop an intuition, analyze the recursive solution, perform a dry run, and evaluate the time and space complexity.Problem StatementGiven the root of a Binary Search Tree (BST) and an integer value val, find the node whose value equals val and return the subtree rooted at that node.If the value does not exist in the BST, return null.Problem LinkLeetCode 700 - Search in a Binary Search TreeExample 1Input:root = [4,2,7,1,3]val = 2Output:[2,1,3]Explanation:The node with value 2 exists in the BST. Therefore, we return the subtree rooted at node 2.Example 2Input:root = [4,2,7,1,3]val = 5Output:[]Explanation:Value 5 does not exist in the BST, so we return null.Understanding the Binary Search Tree PropertyA Binary Search Tree follows these rules:All values in the left subtree are smaller than the root node.All values in the right subtree are greater than the root node.Both left and right subtrees are also BSTs.Example: 4 / \ 2 7 / \1 3Suppose we need to search for value 3:Start at 4.Since 3 < 4, move left.Reach node 2.Since 3 > 2, move right.Reach node 3.Value found.Instead of traversing every node, BST allows us to eliminate half of the search space at each step.IntuitionThe BST property gives us a clear direction while searching:If the current node's value equals val, return the node.If val is smaller than the current node's value, search in the left subtree.If val is greater than the current node's value, search in the right subtree.If we reach a null node, the value does not exist.This naturally leads to a recursive solution.ApproachAlgorithmIf the current node is null, return null.If the current node value equals val, return the node.If val is smaller than the current node value, recursively search the left subtree.Otherwise, recursively search the right subtree.Return the result obtained from recursion.Java Solutionclass Solution { public TreeNode solve(TreeNode root, int val) { if (root == null) return root; if (root.val == val) return root; if (root.val > val) { return solve(root.left, val); } else { return solve(root.right, val); } } public TreeNode searchBST(TreeNode root, int val) { if (root == null) return root; if (root.val == val) return root; return solve(root, val); }}Code ExplanationHelper Function: solve()This function recursively searches for the target value.if(root == null) return root;If the node is null, the value is not present.if(root.val == val) return root;If the value matches, return the current node.if(root.val > val) return solve(root.left, val);When the target value is smaller, move to the left subtree.return solve(root.right, val);When the target value is larger, move to the right subtree.Main Function: searchBST()if(root == null) return root;Handles the empty tree case.if(root.val == val) return root;If the root itself contains the target value, return immediately.return solve(root,val);Otherwise, begin recursive searching.Dry RunInput:root = [4,2,7,1,3]val = 2Tree: 4 / \ 2 7 / \1 3Step 1Current Node = 44 > 2Move to left subtree.Step 2Current Node = 22 == 2Target found.Return subtree: 2 / \1 3Output:[2,1,3]Another Dry RunInput:root = [4,2,7,1,3]val = 5Step 1Current Node = 45 > 4Move right.Step 2Current Node = 75 < 7Move left.Step 3Current Node = nullValue not found.Return null.Complexity AnalysisTime ComplexityBest Case:O(1)When the root itself contains the target value.Average Case:O(log n)For a balanced BST, each comparison reduces the search space by half.Worst Case:O(n)When the BST becomes skewed like a linked list.Space ComplexityO(h)Where h is the height of the tree due to recursive function calls.Balanced BST:O(log n)Skewed BST:O(n)Why This Solution WorksThe solution efficiently utilizes the Binary Search Tree property instead of performing a full tree traversal.At every node:Left subtree is searched only when necessary.Right subtree is searched only when necessary.Unnecessary branches are ignored.This significantly improves performance compared to a normal binary tree search.Interview TipsWhen solving BST search problems in interviews:Always mention the BST property first.Explain why only one subtree needs to be explored.Discuss both balanced and skewed tree scenarios.Mention iterative optimization if asked about reducing recursion stack space.ConclusionLeetCode 700 - Search in a Binary Search Tree is a fundamental BST problem that demonstrates how the ordered structure of a BST enables efficient searching. By leveraging BST properties, we can quickly locate a target node without traversing the entire tree.The recursive approach is simple, clean, and highly intuitive, making it an excellent solution for coding interviews and DSA practice. Understanding this problem builds a strong foundation for more advanced BST operations such as insertion, deletion, validation, and range queries.

LeetCodeBinary Search TreeJavaBSTEasyTreeRecursion
Fast and Slow Pointer Technique in Linked List: Cycle Detection, Proof, and Complete Explanation

Fast and Slow Pointer Technique in Linked List: Cycle Detection, Proof, and Complete Explanation

🚀 Before We StartTry these problems (optional but helpful):https://leetcode.com/problems/linked-list-cycle/https://leetcode.com/problems/linked-list-cycle-ii/🤔 Let’s Talk Honestly…When you first learn this technique, you’re told:👉 “Slow moves 1 step, fast moves 2 steps”👉 “If they meet → cycle exists”But your brain asks:❓ Why 2 steps?❓ Why do they meet at all?❓ Why does resetting pointer find cycle start?❓ Is this magic or logic?👉 Let’s answer each doubt one by one.🧩 Doubt 1: Why do we even use two pointers?❓ Question:Why not just use one pointer?✅ Answer:With one pointer:You can only move forwardYou cannot detect loops efficiently👉 Two pointers create a relative motionThat relative motion is the key.🧩 Doubt 2: Why fast = 2 steps and slow = 1 step?❓ Question:Why exactly 2 and 1?✅ Answer:We need:Fast speed > Slow speedSo that:👉 Fast catches up to slow🧠 Think like this:If both move same speed:Slow → 1 stepFast → 1 step👉 They will NEVER meet ❌If:Slow → 1 stepFast → 2 steps👉 Fast gains 1 node every step🔥 Key Insight:Relative speed = fast - slow = 1👉 This means fast is closing the gap by 1 node every step🧩 Doubt 3: Why do they ALWAYS meet in a cycle?❓ Question:Okay, fast is faster… but why guaranteed meeting?🧠 Imagine a Circular TrackInside a cycle, the list behaves like:Circle of length = λNow:Slow moves 1 stepFast moves 2 steps🔄 Gap BehaviorEach step:Gap = Gap - 1Because fast is catching up.Eventually:Gap = 0👉 They meet 🎯💡 Simple AnalogyTwo runners on a circular track:One is fasterOne is slower👉 Faster runner will lap and meet slower runner🧩 Doubt 4: What if there is NO cycle?❓ Question:Why does this fail without cycle?✅ Answer:If no cycle:List ends → fast reaches null👉 No loop → no meeting🧩 Doubt 5: Where do they meet?❓ Question:Do they meet at cycle start?❌ Answer:No, not necessarily.They meet somewhere inside the cycle🧩 Doubt 6: Then how do we find the cycle start?Now comes the most important part.🎯 SetupLet’s define:a = distance from head to cycle startb = distance from cycle start to meeting pointc = remaining cycleCycle length:λ = b + c🧠 What happens when they meet?Slow distance:a + bFast distance:2(a + b)Using relation:2(a + b) = a + b + kλSolve:a + b = kλ=> a = kλ - b=> a = (k-1)λ + (λ - b)💥 Final Meaninga = distance from meeting point to cycle start🔥 BIG CONCLUSION👉 Distance from head → cycle start👉 = Distance from meeting point → cycle start🧩 Doubt 7: Why resetting pointer works?❓ Question:Why move one pointer to head?✅ Answer:Because:One pointer is a away from startOther is also a away (via cycle)👉 Move both 1 step:They meet at:Cycle Start 🎯🔄 VisualizationHead → → → Cycle Start → → Meeting Point → → back to StartBoth pointers:One from headOne from meeting point👉 Same distance → meet at start🧩 Doubt 8: Can we use fast = 3 steps?❓ Question:Will this work?✅ Answer:Yes, BUT:Math becomes complexHarder to reasonNo extra benefit👉 So we use simplest:2 : 1 ratio🧠 Final Mental ModelThink in 3 steps:1. Different SpeedsFast moves faster → gap reduces2. Circular StructureCycle → positions repeat3. Guaranteed MeetingFinite positions + relative motion → collision🧩 TEMPLATE 1: Detect CycleListNode slow = head;ListNode fast = head;while(fast != null && fast.next != null){ slow = slow.next; fast = fast.next.next; if(slow == fast){ return true; }}return false;🧩 TEMPLATE 2: Find Cycle StartListNode slow = head;ListNode fast = head;while(fast != null && fast.next != null){ slow = slow.next; fast = fast.next.next; if(slow == fast){ slow = head; while(slow != fast){ slow = slow.next; fast = fast.next; } return slow; }}return null;🧩 TEMPLATE 3: Find Middle of Linked List❓ ProblemFind the middle node of a linked list.🧠 IntuitionFast moves twice as fast:When fast reaches end → slow reaches half👉 Slow = middle💻 CodeListNode slow = head;ListNode fast = head;while(fast != null && fast.next != null){ slow = slow.next; fast = fast.next.next;}return slow;⚠️ Even Length Case1 → 2 → 3 → 4 → 5 → 6👉 Returns 4 (second middle)❓ How to Get First Middle?while(fast.next != null && fast.next.next != null){ slow = slow.next; fast = fast.next.next;}return slow;🧩 Where Else This Technique Is Used?Detect cycleFind cycle startFind middle nodeCheck palindrome (linked list)Split list (merge sort)Intersection problems⚙️ Time & Space ComplexityTime: O(n)Space: O(1)❌ Common MistakesForgetting fast.next != nullThinking meeting point = cycle start ❌Not resetting pointer properly🧠 Final Mental ModelThink in 3 steps:1. Speed DifferenceFast moves faster → gap reduces2. Circular NatureCycle → repeated positions3. Guaranteed MeetingFinite nodes + relative motion → collision🔥 One Line to RememberFast catches slow because it reduces the gap inside a loop.🚀 ConclusionNow you understand:✅ Why fast moves faster✅ Why they meet✅ Why meeting proves cycle✅ Why reset gives cycle start✅ How to find middle using same logic👉 This is not just a trick…It’s a mathematical guarantee based on motion and cycles.💡 Master this once, and you’ll solve multiple linked list problems easily.

Linked ListFast & Slow PointerTwo Pointer TechniqueFloyd AlgorithmDSA PatternsDeep Intuition
LeetCode 844: Backspace String Compare — Java Solution With All Approaches Explained

LeetCode 844: Backspace String Compare — Java Solution With All Approaches Explained

IntroductionLeetCode 844 Backspace String Compare is a fantastic problem that shows up frequently in coding interviews. It combines string manipulation, stack simulation, and even has a follow-up that challenges you to solve it in O(1) space — which is what separates a good candidate from a great one.Here is the Link of Question -: LeetCode 844In this article we cover a plain English explanation, real life analogy, 3 Java approaches including the O(1) space two pointer solution, dry runs, complexity analysis, common mistakes, and FAQs.What Is the Problem Really Asking?You are given two strings s and t. Both contain lowercase letters and # characters. Think of # as the backspace key on your keyboard — it deletes the character just before it. If there is nothing to delete, it does nothing.Process both strings through these backspace operations and check if the resulting strings are equal. Return true if equal, false otherwise.Quick Example:s = "ab#c" → # deletes b → becomes "ac"t = "ad#c" → # deletes d → becomes "ac"Both equal "ac" → return true ✅Real Life Analogy — The Keyboard TypoYou are typing a message. You type "ab", realize you made a typo, hit backspace, and type "c". Your friend types "ad", hits backspace, and types "c". Even though you both typed differently, the final message on screen is the same — "ac".That is exactly what this problem is about. Two people typing differently but ending up with the same result.Approach 1: StringBuilder as Stack (Optimal & Clean) ✅The IdeaThis is your own solution and the best O(n) approach. Process each string independently using a StringBuilder as a stack:Letter → append to StringBuilder (push)# → delete last character if StringBuilder is not empty (pop)Then simply compare the two resulting StringBuilders.public boolean backspaceCompare(String s, String t) { return process(s).equals(process(t));}private String process(String str) { StringBuilder sb = new StringBuilder(); for (int i = 0; i < str.length(); i++) { char c = str.charAt(i); if (c == '#') { if (sb.length() > 0) { sb.deleteCharAt(sb.length() - 1); } } else { sb.append(c); } } return sb.toString();}Notice how extracting a process() helper method makes the code cleaner and avoids repeating the same loop twice — a great habit to show in interviews!Dry Run — s = "ab##", t = "c#d#"Processing s = "ab##":a → append → "a"b → append → "ab"# → delete last → "a"# → delete last → ""Processing t = "c#d#":c → append → "c"# → delete last → ""d → append → "d"# → delete last → ""Both result in "" → return true ✅Time Complexity: O(n + m) — where n and m are lengths of s and t Space Complexity: O(n + m) — two StringBuilders storing processed stringsApproach 2: Stack Based Solution (Interview Classic)The IdeaSame logic as above but using explicit Stack<Character> objects. Great for explaining your thought process clearly in an interview even though StringBuilder is cleaner.public boolean backspaceCompare(String s, String t) { return processStack(s).equals(processStack(t));}private String processStack(String str) { Stack<Character> st = new Stack<>(); for (int i = 0; i < str.length(); i++) { char c = str.charAt(i); if (c == '#') { if (!st.empty()) { st.pop(); } } else { st.push(c); } } StringBuilder sb = new StringBuilder(); while (!st.empty()) { sb.append(st.pop()); } return sb.reverse().toString();}Dry Run — s = "a#c", t = "b"Processing s = "a#c":a → push → stack: [a]# → pop → stack: []c → push → stack: [c]Result: "c"Processing t = "b":b → push → stack: [b]Result: "b""c" does not equal "b" → return false ✅Time Complexity: O(n + m) Space Complexity: O(n + m)Approach 3: Two Pointer — O(1) Space (Follow-Up Solution) 🔥This is the follow-up the problem asks about — can you solve it in O(n) time and O(1) space? This means no extra StringBuilder or Stack allowed.The IdeaInstead of building processed strings, traverse both strings from right to left simultaneously. Keep a count of pending backspaces. Skip characters that would be deleted and compare characters that survive.Why right to left? Because # affects characters to its left, so processing from the end lets us know upfront how many characters to skip.public boolean backspaceCompare(String s, String t) { int i = s.length() - 1; int j = t.length() - 1; int skipS = 0, skipT = 0; while (i >= 0 || j >= 0) { // Find next valid character in s while (i >= 0) { if (s.charAt(i) == '#') { skipS++; i--; } else if (skipS > 0) { skipS--; i--; } else { break; } } // Find next valid character in t while (j >= 0) { if (t.charAt(j) == '#') { skipT++; j--; } else if (skipT > 0) { skipT--; j--; } else { break; } } // Compare the valid characters if (i >= 0 && j >= 0) { if (s.charAt(i) != t.charAt(j)) { return false; } } else if (i >= 0 || j >= 0) { return false; // one string still has chars, other doesn't } i--; j--; } return true;}Dry Run — s = "ab#c", t = "ad#c"Starting from the right end of both strings:Round 1:s[3] = 'c' → valid, no skips → stopt[3] = 'c' → valid, no skips → stopCompare 'c' == 'c' ✅ → move both pointers leftRound 2:s[2] = '#' → skipS = 1, move lefts[1] = 'b' → skipS > 0, skipS = 0, move lefts[0] = 'a' → valid, stopt[2] = '#' → skipT = 1, move leftt[1] = 'd' → skipT > 0, skipT = 0, move leftt[0] = 'a' → valid, stopCompare 'a' == 'a' ✅ → move both pointers leftBoth pointers exhausted → return true ✅Time Complexity: O(n + m) — each character visited at most once Space Complexity: O(1) — only pointer and counter variables, no extra storage!Approach ComparisonThe StringBuilder approach is the easiest to write and explain. The Stack approach is slightly more verbose but shows clear intent. The Two Pointer approach is the hardest to code but the most impressive — it solves the follow-up and uses zero extra space.In an interview, start with the StringBuilder solution, explain it clearly, then mention the Two Pointer approach as the O(1) space optimization if asked.How This Fits the Stack Simulation PatternYou have now seen this same pattern across four problems:3174 Clear Digits — digit deletes closest left non-digit 2390 Removing Stars — star deletes closest left non-star 1047 Remove Adjacent Duplicates — character cancels matching top of stack 844 Backspace String Compare — # deletes closest left character, then compare two stringsAll four use the same StringBuilder-as-stack core. The only differences are the trigger character and what you do with the result. This is the power of pattern recognition in DSA.Common Mistakes to AvoidNot handling backspace on empty string When # appears but the StringBuilder is already empty, do nothing. Always guard with sb.length() > 0 before calling deleteCharAt. The problem explicitly states backspace on empty text keeps it empty.Using Stack and forgetting to handle # when stack is empty In the Stack approach, only pop if the stack is not empty. Pushing # onto the stack when it is empty is a common bug that gives wrong answers.In Two Pointer, comparing before both pointers find valid characters Make sure both inner while loops fully complete before comparing. Comparing too early is the most common mistake in the O(1) space solution.FAQs — People Also AskQ1. What is the best approach for LeetCode 844 in Java? For most interviews, the StringBuilder approach is the best — clean, readable, and O(n) time. If the interviewer asks for O(1) space, switch to the Two Pointer approach traversing from right to left.Q2. How does the O(1) space solution work for LeetCode 844? It uses two pointers starting from the end of both strings, keeping a skip counter to track pending backspaces. Characters that would be deleted are skipped, and only surviving characters are compared.Q3. What is the time complexity of LeetCode 844? All three approaches run in O(n + m) time where n and m are the lengths of the two strings. The Two Pointer approach achieves this with O(1) space instead of O(n + m).Q4. Why traverse from right to left in the Two Pointer approach? Because # affects characters to its left. Scanning from the right lets you know upfront how many characters to skip before you reach them, avoiding the need to store anything.Q5. Is LeetCode 844 asked in Google interviews? Yes, it is commonly used as a warmup or screening problem. The follow-up O(1) space solution is what makes it interesting for senior-level interviews.Similar LeetCode Problems to Practice Next1047. Remove All Adjacent Duplicates In String — Easy — same stack pattern2390. Removing Stars From a String — Medium — star as backspace3174. Clear Digits — Easy — digit as backspace1209. Remove All Adjacent Duplicates in String II — Medium — k adjacent duplicates678. Valid Parenthesis String — Medium — stack with wildcardsConclusionLeetCode 844 Backspace String Compare is a well-rounded problem that tests string manipulation, stack simulation, and space optimization all in one. The StringBuilder solution is your go-to for interviews. But always be ready to explain the Two Pointer O(1) space follow-up — that is what shows real depth of understanding.Check out these problems alongside 1047, 2390, and 3174 and you will have the entire stack simulation pattern locked down for any coding interview.

StringStackTwo PointerString Builder
Subsets Problem (LeetCode 78) Explained | Recursion, Iterative & Bit Manipulation

Subsets Problem (LeetCode 78) Explained | Recursion, Iterative & Bit Manipulation

IntroductionThe Subsets problem (LeetCode 78) is one of the most fundamental and frequently asked questions in coding interviews. It introduces the concept of generating a power set, which is a core idea in recursion, backtracking, and combinatorics.Mastering this problem helps in solving a wide range of advanced problems like combinations, permutations, and decision-based recursion.In this article, we will explore:Intuition behind subsetsRecursive (backtracking) approachIterative (loop-based) approachBit manipulation approachTime and space complexity analysisProblem StatementGiven an integer array nums of unique elements, return all possible subsets (the power set).Key PointsEach element can either be included or excludedNo duplicate subsetsReturn subsets in any orderExamplesExample 1Input:nums = [1, 2, 3]Output:[[], [1], [2], [1,2], [3], [1,3], [2,3], [1,2,3]]Example 2Input:nums = [0]Output:[[], [0]]Key InsightFor each element, there are two choices:Include it OR Exclude itSo total subsets:2^nThis makes it a binary decision tree problem, very similar to:Permutation with SpacesBinary choices recursionBacktracking problemsApproach 1: Recursion + Backtracking (Most Important)IntuitionAt each index:Skip the elementInclude the elementBuild subsets step by step and backtrack.Java Code (With Explanation)import java.util.*;class Solution { List<List<Integer>> liss = new ArrayList<>(); void solve(int[] an, int ind, List<Integer> lis) { // Base case: reached end → one subset formed if (ind == an.length) { liss.add(new ArrayList<>(lis)); // store copy return; } // Choice 1: Do NOT include current element solve(an, ind + 1, lis); // Choice 2: Include current element lis.add(an[ind]); solve(an, ind + 1, lis); // Backtrack: remove last added element lis.remove(lis.size() - 1); } public List<List<Integer>> subsets(int[] nums) { List<Integer> lis = new ArrayList<>(); solve(nums, 0, lis); return liss; }}Dry Run (nums = [1,2])Start: [] → skip 1 → [] → skip 2 → [] → take 2 → [2] → take 1 → [1] → skip 2 → [1] → take 2 → [1,2]Final Output:[], [2], [1], [1,2]Approach 2: Iterative (Loop-Based)IntuitionStart with an empty subset:[ [] ]For each element:Add it to all existing subsetsCodeimport java.util.*;class Solution { public List<List<Integer>> subsets(int[] nums) { List<List<Integer>> result = new ArrayList<>(); result.add(new ArrayList<>()); for (int num : nums) { int size = result.size(); for (int i = 0; i < size; i++) { List<Integer> temp = new ArrayList<>(result.get(i)); temp.add(num); result.add(temp); } } return result; }}How It WorksFor [1,2,3]:Start: [[]]Add 1 → [[], [1]]Add 2 → [[], [1], [2], [1,2]]Add 3 → [[], [1], [2], [1,2], [3], [1,3], [2,3], [1,2,3]]Approach 3: Bit ManipulationIntuitionEach subset can be represented using a binary number:For n = 3:000 → []001 → [1]010 → [2]011 → [1,2]...Codeimport java.util.*;class Solution { public List<List<Integer>> subsets(int[] nums) { List<List<Integer>> result = new ArrayList<>(); int n = nums.length; int total = 1 << n; // 2^n for (int i = 0; i < total; i++) { List<Integer> subset = new ArrayList<>(); for (int j = 0; j < n; j++) { if ((i & (1 << j)) != 0) { subset.add(nums[j]); } } result.add(subset); } return result; }}Complexity AnalysisApproachTime ComplexitySpace ComplexityRecursionO(2^n)O(n) stackIterativeO(2^n)O(2^n)Bit ManipulationO(2^n)O(2^n)Why All Approaches Are O(2ⁿ)Because:Total subsets = 2ⁿEach subset takes up to O(n) to constructWhen to Use Which ApproachRecursion / Backtracking → Best for interviews (easy to explain)Iterative → Clean and beginner-friendlyBit Manipulation → Best for optimization & advanced understandingKey TakeawaysSubsets = power set problemEvery element → 2 choicesThink in terms of decision treesBacktracking = build + undo (add/remove)Common Interview VariationsSubsets with duplicatesCombination sumPermutationsK-sized subsetsConclusionThe Subsets problem is a foundational DSA concept that appears across many interview questions. Understanding all approaches—especially recursion and iterative expansion—gives a strong base for solving complex backtracking problems.If you master this pattern, you unlock a whole category of problems in recursion and combinatorics.Frequently Asked Questions (FAQs)1. Why are there 2ⁿ subsets?Because each element has 2 choices: include or exclude.2. Which approach is best for interviews?Recursion + backtracking is the most preferred.3. Is bit manipulation important?Yes, it helps in optimizing and understanding binary patterns.

LeetCodeMediumJavaRecursionBacktracking
LeetCode 1807: Evaluate the Bracket Pairs of a String – Java Solution & Explanation

LeetCode 1807: Evaluate the Bracket Pairs of a String – Java Solution & Explanation

IntroductionLeetCode 1807, Evaluate the Bracket Pairs of a String, is a string-processing problem that combines two common techniques:Using a HashMap for fast key-value lookupTraversing a string while keeping track of whether the current characters belong to a bracket pairThe string contains ordinary characters as well as bracketed keys such as:(name)(age)(city)A separate knowledge list provides the value associated with each known key.For every bracket pair:If the key exists in knowledge, replace the entire pair with its value.If the key is not present, replace the entire pair with ?.For example:s = "(name)is(age)yearsold"with:knowledge = [ ["name", "bob"], ["age", "two"]]becomes:bobistwoyearsoldThe main challenge is identifying exactly which characters belong to a bracketed key while keeping the characters outside brackets unchanged.Question LinkLeetCode 1807 – Evaluate the Bracket Pairs of a StringUnderstanding the ProblemConsider:s = "(name)is(age)yearsold"The bracket pairs are:(name)(age)The text outside the brackets is:isyearsoldSuppose:name → bobage → twoThen the transformation is:(name) → bob(age) → twoSo the final result becomes:bobistwoyearsoldThe characters outside brackets should not be interpreted as keys.For example:s = "(a)(a)aaa"with:a → yesproduces:yesyesaaaThe final aaa remains unchanged because those characters are not inside brackets.ApproachThe solution can be divided into two parts.Store the Knowledge in a HashMapThe knowledge array contains pairs such as:["name", "bob"]["age", "two"]These pairs are stored in a HashMap:HashMap<String, String> mp = new HashMap<>();for(int i = 0; i < knowledge.size(); i++){ mp.put( knowledge.get(i).get(0), knowledge.get(i).get(1) );}This gives direct access to a value using its key.For example:mp.get("name")returns:bobAnd:mp.containsKey("unknown")can be used to determine whether a key exists.Because each key appears at most once in knowledge, there is no need to handle duplicate key definitions.Detecting a Bracketed KeyThe solution uses a boolean variable:boolean bo = false;This represents whether the current position is inside a bracket pair.When the character immediately before the current character is '(':if(i > 0 && s.charAt(i - 1) == '('){ key = ""; bo = true;}the solution starts collecting a new key.For example:(name) ^Once n is reached, the previous character is '(', so the solution begins collecting:nnanamnameWhen ')' is encountered:if(s.charAt(i) == ')'){ bo = false;}the key is complete.The solution can then look it up in the map.Replacing the KeyWhen the closing bracket is found, the code checks whether the collected key exists:if(mp.containsKey(key)){ an += mp.get(key); key = "";}else{ an += "?"; key = "";}If the key is known:(name) → bobIf the key is unknown:(address) → ?This directly follows the problem statement.Keeping Characters Outside BracketsCharacters that are not part of a bracketed key are added directly to the result:if(!bo && (s.charAt(i) != ')' && s.charAt(i) != '(')){ an += s.charAt(i);}This is important because ordinary characters must remain unchanged.For:hi(name)the characters:hiare outside the brackets and are therefore copied directly.The key:nameis evaluated separately.Java SolutionHere is the submitted solution with comments explaining the important parts:class Solution { public String evaluate(String s, List<List<String>> knowledge) { // Store key -> value mappings HashMap<String, String> mp = new HashMap<>(); for(int i = 0; i < knowledge.size(); i++){ mp.put( knowledge.get(i).get(0), knowledge.get(i).get(1) ); } String key = ""; // true when we are currently reading a key boolean bo = false; String an = ""; for(int i = 0; i < s.length(); i++){ // The character after '(' starts a new key if(i > 0 && s.charAt(i - 1) == '('){ key = ""; bo = true; } // ')' means the current key is complete if(s.charAt(i) == ')'){ bo = false; } // Characters outside brackets are copied directly if(!bo && s.charAt(i) != ')' && s.charAt(i) != '('){ an += s.charAt(i); } // Characters inside brackets are collected as the key if(bo){ key += s.charAt(i); } // Evaluate the completed key if(key.length() > 0 && s.charAt(i) == ')'){ if(mp.containsKey(key)){ an += mp.get(key); key = ""; } else{ an += "?"; key = ""; } } } return an; }}Dry RunConsider:s = "(name)is(age)"and:knowledge = [ ["name", "bob"], ["age", "two"]]Initially:an = ""Reading (name)The scanner encounters '('.The next characters are collected as the key:nnanamnameWhen ')' is reached:key = "name"The map contains "name":name → bobSo:an = "bob"Reading isThese characters are outside brackets:isThey are copied directly:an = "bobis"Reading (age)The key is collected:aagageAt the closing bracket:key = "age"The map contains:age → twoSo:an = "bobistwo"The final result is:bobistwoHandling an Unknown KeyConsider:s = "hi(name)"with:knowledge = [["a", "b"]]The map contains only:a → bWhen the scanner reaches:(name)the collected key is:nameBut:mp.containsKey("name")is false.Therefore the entire bracket pair is replaced with:?The result becomes:hi?This is an important part of the problem because unknown keys should not remain in the output.Why a HashMap Works WellThe knowledge list can contain up to 10^5 entries.Searching through the entire list for every bracket pair would be unnecessarily expensive.Instead, the solution converts it into:key → valueusing a HashMap.Then a lookup is expected O(1).This makes the solution efficient even when the knowledge list is large.A Small Implementation ImprovementThe submitted solution uses:String an = "";and repeatedly performs:an += ...Java String objects are immutable, so repeatedly concatenating strings can create many intermediate objects.A StringBuilder is more appropriate when constructing a result character by character.The same approach can therefore be written as:class Solution { public String evaluate(String s, List<List<String>> knowledge) { HashMap<String, String> mp = new HashMap<>(); for(List<String> pair : knowledge){ mp.put(pair.get(0), pair.get(1)); } StringBuilder ans = new StringBuilder(); StringBuilder key = new StringBuilder(); boolean inside = false; for(int i = 0; i < s.length(); i++){ char ch = s.charAt(i); if(ch == '('){ inside = true; key.setLength(0); } else if(ch == ')'){ inside = false; String k = key.toString(); if(mp.containsKey(k)){ ans.append(mp.get(k)); } else{ ans.append('?'); } } else if(inside){ key.append(ch); } else{ ans.append(ch); } } return ans.toString(); }}This version expresses the parsing states more directly:'(' → start keyinside brackets → collect key')' → evaluate keyoutside brackets → copy characterComplexity AnalysisLet:n = length of sk = number of entries in knowledgeBuilding the HashMap requires:Time: O(k)The string is scanned once:Time: O(n)Therefore, the overall expected complexity is:Time Complexity: O(n + k)The HashMap stores all known keys and values.Space Complexity: O(k + n)The O(n) component accounts for the output and temporary string-building structures.Interview TipThis problem is a good example of a state-based string traversal.Instead of trying to manipulate the entire string repeatedly, scan it once and maintain a small amount of state:Outside brackets ↓ '(' ↓Inside bracket → collect key ↓ ')' ↓Look up key ↓Append value / '?' ↓Outside bracketsWhen a string contains delimiters such as:(...)[...]{...}a similar state-based approach can often simplify the implementation.The second important pattern is recognizing when a HashMap is appropriate: whenever many lookups need to be performed using a unique key.ConclusionLeetCode 1807 is primarily a string parsing + HashMap lookup problem.The solution first converts the knowledge list into a key-value map. It then scans the string and distinguishes between characters inside and outside brackets.For every bracketed key:known key → corresponding valueunknown key → ?The important implementation ideas are:Use a HashMap for fast key lookup.Track whether the scanner is inside a bracket pair.Collect characters between '(' and ')'.Preserve characters outside brackets.Return the first available result after processing the complete string.The submitted approach follows this logic correctly. For production-quality Java code, StringBuilder is preferable to repeated String concatenation when constructing the result.

LeetCodeJavaStringHashMapString ManipulationMediumDSA
LeetCode 3550: Smallest Index With Digit Sum Equal to Index – Java Solution & Explanation

LeetCode 3550: Smallest Index With Digit Sum Equal to Index – Java Solution & Explanation

IntroductionLeetCode 3550, Smallest Index With Digit Sum Equal to Index, combines two simple ideas:Traversing an array using its indexFinding the sum of the digits of an integerFor every index i, the task is to check whether:sum of digits of nums[i] = iThe smallest valid index should be returned.If no index satisfies the condition, the answer is -1.Although the problem is easy, it is a good exercise for understanding how an array index can be compared with a property calculated from the corresponding value.Question LinkLeetCode 3550 – Smallest Index With Digit Sum Equal to IndexUnderstanding the ProblemConsider:nums = [1, 10, 11]Check every index from left to right.Index 0nums[0] = 1Digit sum:1Compare with index:1 != 0So index 0 does not work.Index 1nums[1] = 10Digit sum:1 + 0 = 1Now:digit sum = index1 = 1Therefore, index 1 satisfies the condition.Because the array is checked from left to right, this is automatically the smallest valid index.Answer = 1ApproachThe solution follows a simple left-to-right traversal.For every index i:Take nums[i].Calculate the sum of its digits.Compare that sum with i.Return i immediately when they are equal.If the complete array is checked without finding a match, return -1.The early return is important because the problem asks for the smallest index.There is no need to continue searching after finding the first valid index.Finding the Digit SumThe helper method so() calculates the sum of the digits.public int so(int n){ int su = 0; while(n != 0){ int dig = n % 10; n /= 10; su += dig; } return su;}Two operations are especially useful here.Extracting the last digitn % 10For example:123 % 10 = 3So the last digit is obtained.Removing the last digitn /= 10For example:123 / 10 = 12Since integer division is being used, the decimal part is discarded.Repeating these two operations gives every digit.For:123the process is:123 % 10 → 3123 / 10 → 1212 % 10 → 212 / 10 → 11 % 10 → 11 / 10 → 0Therefore:Digit Sum = 3 + 2 + 1 = 6Checking Each IndexThe main method traverses the array:for(int i = 0; i < nums.length; i++){For a single-digit number, the submitted solution directly compares the value with the index:if(nums[i] < 10){ if(i == nums[i]){ return i; }}For numbers containing multiple digits, it calculates their digit sum:else{ int su = so(nums[i]); if(su == i){ return i; }}This works correctly for the given constraints.Java SolutionHere is the submitted approach with clearer comments:class Solution { // Returns the sum of all digits of n public int so(int n){ int su = 0; while(n != 0){ // Extract the last digit int dig = n % 10; // Remove the last digit n /= 10; // Add the digit to the sum su += dig; } return su; } public int smallestIndex(int[] nums){ // Traverse from the smallest index for(int i = 0; i < nums.length; i++){ // Single-digit numbers can be compared directly if(nums[i] < 10){ if(i == nums[i]){ return i; } }else{ // Calculate digit sum for multi-digit numbers int su = so(nums[i]); if(su == i){ return i; } } } // No valid index was found return -1; }}Dry RunConsider:nums = [1, 3, 2]The indices are:0 1 2Index 0nums[0] = 1Digit sum:1Comparison:1 != 0Not valid.Index 1nums[1] = 3Digit sum:3Comparison:3 != 1Not valid.Index 2nums[2] = 2Digit sum:2Comparison:2 = 2A valid index is found.Therefore:Answer = 2The function immediately returns 2.Another ExampleConsider:nums = [1, 10, 11]IndexValueDigit SumMatch?011No1101Yes2112YesBoth indices 1 and 2 satisfy the condition.However, index 1 appears first.Therefore:Answer = 1This demonstrates why traversing from left to right and returning immediately is enough to find the smallest valid index.A Small SimplificationThe special case for single-digit numbers is not actually necessary.The digit-sum method can also handle a single-digit number.For example:so(7)returns:7So the main logic can simply calculate the digit sum for every element.A slightly cleaner version is:class Solution { public int digitSum(int n){ int sum = 0; while(n > 0){ sum += n % 10; n /= 10; } return sum; } public int smallestIndex(int[] nums){ for(int i = 0; i < nums.length; i++){ if(digitSum(nums[i]) == i){ return i; } } return -1; }}This version expresses the core idea directly:digit sum of nums[i] == iThere is no need to treat single-digit and multi-digit numbers differently.Why Does the First Match Give the Smallest Index?The array is traversed in increasing order:0 → 1 → 2 → 3 → ...The moment a valid index is found, every smaller index has already been checked.Therefore, the first match must be the smallest possible answer.This is a common pattern in array problems:When the problem asks for the smallest index satisfying a condition, scan from left to right and return the first match.Complexity AnalysisLet:n = length of the arrayd = number of digits in an elementEach array element is visited once, and calculating its digit sum takes O(d) time.Therefore:Time Complexity: O(n × d)Under the given constraints, nums[i] <= 1000, so each number contains at most 4 digits. This makes d effectively bounded by a small constant, giving:Effective Time Complexity: O(n)The digit-sum calculation uses only a few integer variables.Space Complexity: O(1)Interview TipWhen a problem asks for the digit sum of an integer, remember this standard pattern:while(n > 0){ sum += n % 10; n /= 10;}The two operations have very specific purposes:n % 10 → extract the last digitn / 10 → remove the last digitAlso, when a problem asks for the smallest index, checking elements from left to right often allows an immediate return as soon as the condition is satisfied.ConclusionLeetCode 3550 is a small problem, but it combines several useful programming fundamentals:Array traversalIndex-based conditionsDigit extractionInteger divisionEarly returnConstant-space problem solvingThe main condition is simple:digitSum(nums[i]) == iBy scanning the array from left to right, the first matching index is automatically the smallest one.The solution runs in O(n × d) time, which is effectively O(n) for the given constraints, and uses O(1) extra space.

LeetCodeJavaArraysMathEasyDSA
LeetCode 1569: Number of Ways to Reorder Array to Get Same BST – Java Solution & Explanation

LeetCode 1569: Number of Ways to Reorder Array to Get Same BST – Java Solution & Explanation

IntroductionImagine inserting a sequence of numbers into a Binary Search Tree (BST). The first number becomes the root, smaller values move to the left subtree, and larger values move to the right subtree.Now consider an interesting question: Can the numbers be rearranged into a different order while producing exactly the same BST?The answer is yes.For example, the arrays [2, 1, 3] and [2, 3, 1] produce the same BST. The root remains 2, while 1 belongs to the left subtree and 3 belongs to the right subtree. The insertion order between those two subtrees can change without changing the final tree.This is the central idea behind LeetCode 1569 – Number of Ways to Reorder Array to Get Same BST.The challenge is that the number of possible reorderings can grow rapidly. Generating every permutation would be far too expensive. Instead, we can count valid arrangements mathematically using combinations, then combine those counts recursively for the left and right subtrees.There is one more problem: calculating combinations repeatedly using factorials can lead to unnecessary work and large intermediate numbers. Pascal’s Triangle provides a convenient way to precompute the required combination values.Let's build the solution from the beginning.Problem StatementProblem Link - Number of Ways to Reorder Array to Get Same BSTGiven an array nums containing a permutation of the integers from 1 to n, insert its elements in order into an initially empty BST.Return the number of different reorderings of nums that produce exactly the same BST as the original array.The original ordering itself is included in the total, but the answer must count only the other reorderings, so the original arrangement must be subtracted once.Since the answer may be large, return it modulo:1,000,000,007Example 1Input: nums = [2, 1, 3]Output: 1The original array creates this BST:2/ \1 3The array [2, 3, 1] creates the same tree.There are two valid arrangements in total, including the original one. After excluding the original ordering, the answer is 1.Example 2Input: nums = [3, 4, 5, 1, 2]Output: 5There are six valid arrangements in total, including the original sequence. Subtracting the original arrangement gives 5.Example 3Input: nums = [1, 2, 3]Output: 0The BST is a right-skewed tree. Every value must appear in increasing order to produce that same tree, so no alternative ordering exists.Step 1: The First Element Always Becomes the RootThe first observation comes directly from how a BST is constructed.Consider:nums = [3, 1, 2, 4, 5]The first element, 3, becomes the root.Every remaining value is divided into two groups:Values smaller than 3 go to the left subtree.Values greater than 3 go to the right subtree.The groups are:Left: [1, 2]Right: [4, 5]The resulting BST is:3/ \1 4\ \2 5The root must remain 3 in every valid reordering because the first inserted value determines the root.However, the left and right subtree elements do not necessarily need to appear in one fixed interleaving.For example, these sequences preserve the same relative order within each subtree:[3, 1, 2, 4, 5][3, 1, 4, 2, 5][3, 4, 1, 2, 5]The left-subtree sequence remains 1, 2, and the right-subtree sequence remains 4, 5.The elements from the two groups can be mixed together in different ways, provided that the relative insertion order within each group is preserved.This gives us the first major insight:Count the valid arrangements of the left subtree, count those of the right subtree, and then count the ways to interleave the two groups.Step 2: Why Do We Need Combinations (nCr)?Suppose a node has:L elements in its left subtree.R elements in its right subtree.After choosing the root, there are L + R remaining positions to fill.We need to choose which of those positions will contain the left-subtree elements. Once those positions are selected, the remaining positions automatically belong to the right subtree.The number of ways to choose L positions from L + R positions is: [(L+RL)][ \binom{L+R}{L} ][(LL+R​)] This is the familiar combinations formula, also written as nCr.The recursive count becomes: [ways=(L+RL)×waysLeft×waysRight][ ways = \binom{L+R}{L} \times waysLeft \times waysRight ][ways=(LL+R​)×waysLeft×waysRight] Here:waysLeft counts valid reorderings inside the left subtree.waysRight counts valid reorderings inside the right subtree.The combination term counts the possible interleavings of the two groups.All three factors are necessary.A small exampleConsider the tree formed by:nums = [2, 1, 3]There is one element on the left and one on the right.Therefore: [(21)=2][ \binom{2}{1}=2 ][(12​)=2] The two interleavings are:[1, 3][3, 1]Both produce the same BST when placed after root 2.Since each subtree contains only one element, each has exactly one valid arrangement.Thus: [ways=2×1×1=2][ ways = 2 \times 1 \times 1 = 2 ][ways=2×1×1=2] This count includes the original array. The final answer is: [2−1=1][ 2-1=1 ][2−1=1] The subtraction is performed only once, after the complete recursive count is calculated.Step 3: Calculating nCr EfficientlyNow we know how combinations fit into the solution. But how should the values of nCr be calculated?The mathematical formula is: [(nr)=n!r!(n−r)!][ \binom{n}{r}=\frac{n!}{r!(n-r)!} ][(rn​)=r!(n−r)!n!​] For example: [(42)=4!2!,2!=6][ \binom{4}{2}=\frac{4!}{2!,2!}=6 ][(24​)=2!,2!4!​=6] One approach is to calculate factorials repeatedly. However, the recursive solution needs combination values at many different subtree sizes. Recalculating factorials again and again adds unnecessary work.We can instead precompute all the required combinations using Pascal’s Triangle.The Pascal’s Triangle observationEvery value in Pascal’s Triangle is obtained by adding the two values directly above it: [(n−1r−1)+(n−1r)][\binom{n-1}{r-1} + \binom{n-1}{r} ][(r−1n−1​)+(rn−1​)] The boundary values are always 1: [(n0)=(nn)=1][ \binom{n}{0}=\binom{n}{n}=1 ][(0n​)=(nn​)=1] The first few rows look like this:11 11 2 11 3 3 11 4 6 4 11 5 10 10 5 1For example, the value 6 is calculated as:3 + 3 = 6It represents: [(42)=6][ \binom{4}{2}=6 ][(24​)=6] The same idea can be implemented using a two-dimensional list or array.Instead of calculating factorials whenever the recursive function needs a combination, we build the table once and look up the required value in constant time.How the submitted code builds the tableYour solution uses the list liss to store the rows of Pascal’s Triangle.for (int i = 0; i < nums.length; i++) {List<Integer> lis = new ArrayList<>();for (int j = 0; j < i + 1; j++) {if (i - 1 >= 0 && j - 1 >= 0 && j != i) {long sum = (liss.get(i - 1).get(j)+ liss.get(i - 1).get(j - 1));lis.add((int) (sum % mod));} else {lis.add(1);}}liss.add(new ArrayList<>(lis));}Each iteration builds one row.The first and last values of each row are 1. Every interior value is calculated by adding the two entries from the previous row.For instance, the row representing n = 4 contains:[1, 4, 6, 4, 1]So when the recursive function needs to choose positions for a left subtree of size 2 from a total of 4 elements, it can retrieve the value 6 directly.The table is built once before recursion begins.Step 4: Recursively Count the Left and Right SubtreesWith the combination table ready, the remaining work is recursive.Your sol() method starts by selecting the first element as the root:int root = nums.get(0);It then separates all remaining elements into two lists:List<Integer> left = new ArrayList<>();List<Integer> right = new ArrayList<>();for (int i = 1; i < n; i++) {if (nums.get(i) < root) {left.add(nums.get(i));} else {right.add(nums.get(i));}}Because the input contains distinct values, values smaller than the root belong to the left subtree, while larger values belong to the right subtree.For example:nums = [3, 4, 5, 1, 2]Root: 3Left: [1, 2]Right: [4, 5]Next, the function recursively counts the arrangements for both subtrees:long x = (sol(left)) % mod;long y = (sol(right)) % mod;The base case is:if (nums.size() <= 1) {return 1;}A subtree containing zero or one element has exactly one arrangement. There is nothing to reorder.Finally, the combination table is used to count the interleavings:long z = (liss.get(n - 1).get(left.size())) % mod;Here:n - 1 is the number of elements remaining after choosing the root.left.size() is the number of positions that must be assigned to the left subtree.z is the number of ways to choose those positions.The recursive result is then:return (int) ((((x * y) % mod) * z) % mod);In mathematical form: [ways=waysLeft×waysRight×(n−1leftSize)][ ways = waysLeft \times waysRight \times \binom{n-1}{leftSize} ][ways=waysLeft×waysRight×(leftSizen−1​)] The modulo operation keeps the intermediate result within manageable bounds.Complete Java SolutionThe following is the submitted solution, with formatting and explanatory comments added.class Solution {long mod = 1000000007;List<List<Integer>> liss = new ArrayList<>();public int sol(List<Integer> nums) {if (nums.size() <= 1) {return 1;}int root = nums.get(0);int n = nums.size();List<Integer> left = new ArrayList<>();List<Integer> right = new ArrayList<>();// Divide the remaining values by the current root.for (int i = 1; i < n; i++) {if (nums.get(i) < root) {left.add(nums.get(i));} else {right.add(nums.get(i));}}// Count valid arrangements of both subtrees.long x = sol(left) % mod;long y = sol(right) % mod;// Choose positions for the left-subtree elements.long z = liss.get(n - 1).get(left.size()) % mod;// Combine subtree arrangements and their interleavings.return (int) ((((x * y) % mod) * z) % mod);}public int numOfWays(int[] nums) {int n = nums.length;// Build Pascal's Triangle modulo 1,000,000,007.for (int i = 0; i < n; i++) {List<Integer> lis = new ArrayList<>();for (int j = 0; j <= i; j++) {if (i > 0 && j > 0 && j < i) {long sum = (long) liss.get(i - 1).get(j)+ liss.get(i - 1).get(j - 1);lis.add((int) (sum % mod));} else {lis.add(1);}}liss.add(lis);}List<Integer> num = new ArrayList<>();for (int value : nums) {num.add(value);}// Includes the original ordering.int ans = sol(num);// Exclude the original ordering.return ans - 1;}}Dry Run: How the Pieces Work TogetherConsider:nums = [2, 1, 3]1. Select the rootThe first element is 2.Root = 2Left = [1]Right = [3]2. Count the subtree arrangementsBoth subtrees contain one element.waysLeft = 1waysRight = 1The base case returns 1 for each subtree.3. Find the number of interleavingsThere are two remaining elements, and one belongs to the left subtree.The required combination is: [(21)=2][ \binom{2}{1}=2 ][(12​)=2] Pascal’s Triangle gives this value directly.4. Combine the results [ways=1×1×2=2][ ways = 1 \times 1 \times 2=2 ][ways=1×1×2=2] The two possible arrays are:[2, 1, 3][2, 3, 1]Both generate the same BST.5. Exclude the original orderingThe function initially counts all valid arrangements, including the input array.Therefore:Answer = 2 - 1 = 1The final output is 1, matching the expected result.Complexity AnalysisLet n be the length of nums.Building Pascal’s Triangle:There are (O(n^2)) entries, and each entry is calculated in constant time.Time: (O(n^2))Space: (O(n^2))Recursive BST counting:At each recursive call, the elements are divided into left and right lists. Across each level of the recursion, the elements processed total at most (n). In a highly unbalanced BST, the recursion can reach depth (n), and repeatedly scanning and copying the sublists can result in (O(n^2)) total work.Worst-case time: (O(n^2))Additional recursive and sublist space: up to (O(n^2)) across an unbalanced recursion, excluding the combination table.Therefore, the overall worst-case time complexity of this implementation is:O(n²)The Pascal’s Triangle table itself requires:O(n²) spaceThese bounds are suitable for the problem constraint of n <= 1000.Important Detail: Why Do We Subtract One?The recursive function counts all sequences that generate the same BST, including the original input sequence.However, the problem asks for the number of different reorderings, excluding the original ordering.That is why the final line is:return ans - 1;This subtraction should happen only once, after the full recursive count has been calculated. Subtracting one inside each recursive call would incorrectly exclude arrangements from individual subtrees.Interview TakeawayThis problem combines three ideas that are useful in more advanced algorithm questions:Recursive decomposition: The left and right subtrees can be solved independently.Combinatorics: The elements of the two subtrees can be interleaved in (\binom{L+R}{L}) ways.Dynamic programming: Pascal’s Triangle precomputes combination values so they can be reused instead of recalculated.The most important insight is that the left and right subtree sequences must each preserve their own relative order. Only their positions relative to one another can change.Once that restriction is understood, the counting formula follows naturally.ConclusionLeetCode 1569 looks difficult because it asks for the number of valid reorderings of an array, and the number of possible permutations grows extremely quickly.The solution becomes manageable when the problem is viewed through the structure of the BST. The first element fixes the root, smaller and larger elements form the left and right subtrees, and the two groups can be interleaved without changing the resulting tree.Recursion counts the valid arrangements inside each subtree, while combinations count the possible interleavings. Pascal’s Triangle makes those combination values available efficiently, and modular arithmetic keeps the calculations within the required range.The central formula to remember is:Ways =Left subtree ways× Right subtree ways× Ways to interleave both subtreesThis is the key to turning a seemingly enormous permutation problem into a structured recursive calculation.

LeetCodeJavaBinary Search TreeBSTRecursionCombinatoricsPascal TriangleDynamic ProgrammingDSAHard
LeetCode 2089: Find Target Indices After Sorting Array – Java Solution & Explanation

LeetCode 2089: Find Target Indices After Sorting Array – Java Solution & Explanation

IntroductionFinding an element in an array is a common programming task, but what happens when the required answer is not the element itself, but every position where it appears after sorting?In LeetCode 2089 – Find Target Indices After Sorting Array, the array must first be arranged in non-decreasing order. After sorting, the goal is to return the indices where the specified target value appears. If the target occurs multiple times, every matching index must be included in the result.The solution is straightforward: sort the array, scan it from left to right, and store each index whose value matches the target. Because the array is already sorted, the collected indices naturally appear in increasing order.Problem StatementGiven a zero-indexed integer array nums and an integer target, return a list containing all indices i such that nums[i] == target after sorting nums in non-decreasing order.If the target does not appear in the array, return an empty list.Problem link: LeetCode 2089 – Find Target Indices After Sorting ArrayExample 1Input: nums = [1, 2, 5, 2, 3]target = 2Output: [1, 2]After sorting, the array becomes:[1, 2, 2, 3, 5]The target 2 appears at indices 1 and 2, so the result is [1, 2].Example 2Input: nums = [1, 2, 5, 2, 3]target = 3Output: [3]After sorting, the value 3 appears at index 3.Example 3Input: nums = [1, 2, 5, 2, 3]target = 5Output: [4]The largest value, 5, appears at index 4 after sorting.Approach: Sort the Array and Find Matching IndicesThe main observation is that the target's position can change when the array is sorted. Therefore, checking the original array without sorting would not necessarily return the required indices.The solution uses two simple steps.Step 1: Sort the arrayArrays.sort(nums);Java's Arrays.sort() arranges the integers in ascending order. Equal values become adjacent, making it easy to identify every occurrence of the target.Step 2: Traverse the sorted arrayfor (int i = 0; i < nums.length; i++) { if (nums[i] == target) { lis.add(i); }}The loop checks every position. Whenever the current value equals target, its index is added to the result list.Since the traversal moves from index 0 toward the end of the array, the resulting indices are automatically in increasing order. There is no need to sort the result list separately.Java SolutionThe following implementation uses the submitted approach with Arrays.sort() and an ArrayList to collect the matching indices.class Solution { public List<Integer> targetIndices(int[] nums, int target) { Arrays.sort(nums); List<Integer> lis = new ArrayList<>(); for (int i = 0; i < nums.length; i++) { if (nums[i] == target) { lis.add(i); } } return lis; }}Step-by-Step Dry RunConsider the following input:nums = [1, 2, 5, 2, 3]target = 21. Sort the arrayAfter calling Arrays.sort(nums), the array becomes:Index: 0 1 2 3 4Value: [1, 2, 2, 3, 5]The result list is initially empty:lis = []2. Check each indexIndex inums[i]Matches target?Result list01No[]12Yes[1]22Yes[1, 2]33No[1, 2]45No[1, 2]Both occurrences of 2 are collected.The final result is:[1, 2]What If the Target Is Missing?Suppose the sorted array is:[1, 2, 2, 3, 5]and the target is 4.No element matches the target, so the loop never adds an index to the list. The method returns:[]This also handles the case where the target appears only once or appears multiple times.Complexity AnalysisLet n be the number of elements in the array.Time complexity: O(n log n)Sorting the array takes O(n log n) time.Traversing the array takes O(n) time.Sorting dominates the overall time complexity, making the total O(n log n).Auxiliary space: The result list requires O(k) space, where k is the number of target occurrences. Java's sorting implementation may also use additional internal space.Interview TipWhen a problem asks for indices after sorting, first determine whether the positions refer to the original array or the sorted array. In this problem, the indices belong to the sorted array.Also, repeated target values must all be included. A solution that returns immediately after finding the first match would fail when the target occurs more than once.For this implementation, a full traversal is simple and reliable. Because equal values are grouped together after sorting, a binary-search-based solution could also identify the target's first and last positions, although that additional complexity is unnecessary for the given constraints.ConclusionLeetCode 2089 is a useful exercise in sorting, array traversal, and handling duplicate values. By sorting the array first and collecting every index where nums[i] == target, the solution produces the required result without needing additional index-ordering logic.The key takeaway is to perform operations in the order required by the problem: sort first, then find and return all matching indices.

LeetCodeJavaArraysSortingLinear SearchDSAEasy
LeetCode 17: Letter Combinations of a Phone Number — Java Solution and Backtracking Explained

LeetCode 17: Letter Combinations of a Phone Number — Java Solution and Backtracking Explained

IntroductionHave you ever wondered how a phone number can represent multiple possible words? On a traditional telephone keypad, each digit from 2 to 9 is associated with three or four letters. For example, 2 represents a, b, and c, while 3 represents d, e, and f.Now imagine entering the digits "23". For every letter represented by 2, we can combine it with every letter represented by 3. This produces nine possible combinations, including "ad", "ae", "af", "bd", and "cf".This is the central idea behind LeetCode 17: Letter Combinations of a Phone Number. The challenge is to generate every possible combination without missing any valid result.In this article, we will explore a recursive Java solution, understand how the keypad mapping is built, and trace how the recursive calls generate the final list.Problem link: LeetCode 17 — Letter Combinations of a Phone NumberUnderstanding the ProblemYou are given a string digits containing numbers from 2 to 9. Each digit corresponds to a group of letters on a telephone keypad.Your task is to return all possible strings that can be formed by choosing exactly one letter for each digit.For example, if the input is "23":Digit 2 can contribute a, b, or c.Digit 3 can contribute d, e, or f.Each letter selected from the first group must be paired with every letter in the second group.The resulting combinations are:["ad", "ae", "af", "bd", "be", "bf", "cd", "ce", "cf"]The order of the returned combinations does not matter.One important detail is that the digits 0 and 1 are not included in the input constraints because they do not map to letters in this problem.Approach: Recursion with Phone Keypad MappingThe key observation is that each digit represents a choice, and recursion explores every available choice at the current position.For example, when processing "23", we first select a letter from digit 2. After that, we move to digit 3 and try all its letters. Once we have selected one letter for each digit, we have completed a valid combination.Our solution uses three main components.1. Build the digit-to-letter mappingWe create a list of character lists called arr.Each position represents a digit, and the corresponding list contains its letters. For instance:arr.get(2) contains a, b, c.arr.get(3) contains d, e, f.arr.get(7) contains p, q, r, s.arr.get(9) contains w, x, y, z.We begin with two empty lists at indices 0 and 1, so the mapping for a digit can be accessed directly using its numeric value.The variable charnum starts at 97, the ASCII value of lowercase a. We convert consecutive numeric values into characters and advance the counter by three or four letters, depending on the digit.This lets us construct the entire keypad mapping programmatically rather than writing each group manually.2. Recursively build each combinationThe helper method sol() receives four parameters:arr: the phone keypad mapping.ind: the current position in the input string.dig: the original digit string.sb: the combination constructed so far, represented as a string.At each recursive call, we examine the current digit and iterate over its available letters.For every letter, we make another recursive call with that letter appended to the current combination. This continues until every digit has contributed one letter.3. Stop when a complete combination is formedThe base condition is:if (sb.length() == dig.length())When the constructed string has the same length as the input digit string, we have selected one letter for every digit. We add that combination to the result list and return from the current call.The recursive process then continues exploring the remaining choices.This is the essential stopping condition that prevents the recursion from continuing beyond the number of input digits.Java SolutionHere is the recursive solution, preserving your approach while making two small improvements:Use a StringBuilder when adding a letter instead of repeatedly creating intermediate strings.Handle an empty input and keep the result list local to the method, so repeated calls do not accidentally reuse results from a previous invocation.import java.util.ArrayList;import java.util.List;class Solution {public void sol(List<List<Character>> arr,int ind,String digits,StringBuilder sb,List<String> lis) {if (ind == digits.length()) {lis.add(sb.toString());return;}int digit = digits.charAt(ind) - '0';for (char ch : arr.get(digit)) {sb.append(ch);sol(arr, ind + 1, digits, sb, lis);sb.deleteCharAt(sb.length() - 1);}}public List<String> letterCombinations(String digits) {List<String> lis = new ArrayList<>();if (digits.isEmpty()) {return lis;}List<List<Character>> arr = new ArrayList<>();arr.add(new ArrayList<>());arr.add(new ArrayList<>());int charnum = 97;for (int i = 0; i < 8; i++) {List<Character> li = new ArrayList<>();int count = (i == 5 || i == 7) ? 4 : 3;for (int j = 0; j < count; j++) {li.add((char) (charnum + j));}arr.add(li);charnum += count;}sol(arr, 0, digits, new StringBuilder(), lis);return lis;}}Why use StringBuilder and remove the last character?Your original code uses sb + arr.get(...).get(i) to create a new string for each recursive call. This is valid Java, but repeated string concatenation creates additional string objects.The improved version modifies a single StringBuilder:append(ch) adds the chosen letter.The recursive call explores the combinations that begin with that letter.deleteCharAt(sb.length() - 1) removes the letter after returning, allowing the next letter to be tried.This pattern is called backtracking. We make a choice, explore its consequences, and undo the choice before exploring another branch.It is especially useful when generating permutations, combinations, subsets, and other possible arrangements.Dry Run: digits = "23"Let's trace the recursion to see exactly how the combinations are generated.Initially, the current string is empty, and the current index is 0.Current choiceNext digit choiceCombination producedadadaeaeafafbdbdbebebfbfcdcdcececfcfThe process follows this sequence:Select a from digit 2.Explore all choices from digit 3, producing ad, ae, and af.Return to the first digit and replace a with b.Explore digit 3 again, producing bd, be, and bf.Repeat with c, producing cd, ce, and cf.The final result contains nine combinations.Why nine? The first digit has three choices, and the second digit also has three choices. Therefore, the total number of combinations is 3 × 3 = 9.Complexity AnalysisLet n be the length of the input string, and let R be the total number of generated combinations.Every digit has either three or four possible letters. The maximum number of combinations is therefore 4^n.Time complexity: O(n × R)There are R complete combinations, each containing n characters. Constructing and storing all these strings requires O(n × R) total time. Since R can be as large as 4^n, the worst-case time complexity is O(n × 4^n).Auxiliary space complexity: O(n)The recursion depth is at most n, and the StringBuilder holds at most n characters. The keypad mapping contains a fixed number of letters, so its space usage is constant with respect to the input length.Output space: O(n × R)The result list stores R strings, each of length n. This output memory is separate from the auxiliary space used by the algorithm.Because the constraints limit the input to at most four digits, the number of generated combinations remains small.Common Mistakes to Avoid1. Forgetting to advance to the next digitEvery recursive call must process the next position. If the index is not incremented, recursion will keep processing the same digit.2. Using an incorrect base conditionThe recursion should stop after processing all digits. Checking whether the current string has the same length as the input works, but checking ind == digits.length() directly makes the relationship between the index and the stopping condition clearer.3. Forgetting to undo a choiceWhen using a shared StringBuilder, remember to remove the character after the recursive call. Otherwise, letters from one branch may incorrectly carry over into another.4. Reusing a result list across separate callsIn your original implementation, lis is a class-level field. If the same Solution instance is used for multiple calls, previous results can remain in the list. Creating the result list inside letterCombinations() avoids this issue.5. Ignoring empty inputThe provided constraints guarantee at least one digit, but returning an empty list for an empty input is a useful defensive behavior. It also avoids accidentally treating the empty string as a valid result.Interview Tip: Recognize the Backtracking PatternWhenever a problem asks you to generate every possible arrangement from several groups of choices, consider recursion or backtracking.A useful way to design the solution is to ask:What choices are available at the current position?What state should be passed to the next recursive call?When is a complete answer formed?What needs to be undone before exploring the next choice?For this problem, the choices are the letters associated with the current digit, the state is the current combination and digit index, and a complete answer is reached after processing all digits.The same reasoning can help with problems such as generating subsets, permutations, combination sums, and other recursive search problems.ConclusionLeetCode 17, Letter Combinations of a Phone Number, is a useful introduction to recursive backtracking in Java. The phone keypad gives us a set of choices for every digit, and recursion explores every possible sequence of those choices.The most important part is not the keypad mapping itself. It is learning how to explore one choice completely, return to the previous state, and then try the next choice without mixing results between branches.Once this pattern becomes familiar, many combination-generation problems become easier to approach and explain in coding interviews.Key takeaway: Build the keypad mapping, choose one letter per digit, stop when every digit has been processed, and backtrack to explore the remaining possibilities.

LeetCodeJavaBacktrackingRecursionStringArrayListDSAMediumCombination
LeetCode 1254: Number of Closed Islands — Finding the Idea Before Writing the Code (Java)

LeetCode 1254: Number of Closed Islands — Finding the Idea Before Writing the Code (Java)

The Honest Beginning: I Understood the Question, but I Didn't Know How to Solve ItProblem: LeetCode 1254 — Number of Closed IslandsWhen I first read this question, I understood the basic meaning of the input. We have a grid containing 0s and 1s. Zero represents land, and one represents water.But understanding the input and knowing how to solve the problem are two completely different things.The question asks us to count closed islands. What exactly is an island here? How do we decide whether several zeroes belong to the same island? And how can we tell whether an island is closed?I didn't immediately think of DFS, recursion, or connected components. Honestly, I didn't even know which direction to take.So instead of jumping straight into a solution, let's start with something familiar and build the intuition from there.Step 1: Imagine Looking for Land on a MapImagine that you are looking at a small map made up of land and water.0 means land.1 means water.Suppose several pieces of land are touching each other horizontally or vertically. Even if that land occupies many grid cells, we consider it one connected island.For example, look at this grid:1 1 1 1 11 0 0 1 11 1 0 1 11 1 1 1 1There are three land cells, but they are not three separate islands.The two zeroes in the second row are connected. The zero directly below the second zero is also connected to them.Therefore, all three cells form one island.This gives us our first important observation:We should not count every zero individually. We need to discover groups of zeroes connected in four directions: up, down, left, and right.Notice that diagonal contact does not count. Two land cells touching only at their corners are not connected under this problem's rules.But we still haven't answered the most important question: how do we discover an entire group?Step 2: How Do We Explore All the Connected Land?Suppose we find a zero at position (1, 1).What should we do next?We can inspect its four neighboring cells:Left: (1, 0)Right: (1, 2)Up: (0, 1)Down: (2, 1)If a neighboring cell contains land, we should explore that cell too. Then we should inspect its neighbors, and continue until there is no more unvisited land connected to our starting point.Think about exploring a maze. You enter a room, check the available paths, enter another room, and continue exploring. Whenever you reach a dead end or a path you have already visited, you return and try another direction.That is very close to what recursion does.We can write a function that explores a cell and calls itself for the four neighboring cells. This technique is commonly called Depth-First Search (DFS).I initially found the recursive calls confusing because it felt as if the function would keep calling itself forever. The missing piece is that we need a way to remember which cells have already been explored.In this problem, we can use the grid itself.Whenever we visit a land cell, we change its value from 0 to 1. Since we have finished treating that cell as unvisited land, we won't explore it again.This prevents us from repeatedly visiting the same cells and getting stuck in an infinite recursive loop.Step 3: Exploring an Island Is Not Enough — Is It Closed?At this point, we can discover an island. But the problem doesn't ask us to count every island. It asks us to count only closed islands.Imagine two pieces of land.In the first case, land is surrounded by water on every side. It is completely enclosed.In the second case, some land reaches the edge of the map. This island is open because it is not completely surrounded by water.The important distinction is that an island touching the boundary of the grid cannot be closed.For example:1 1 1 1 11 0 0 1 11 1 0 1 11 1 1 1 1The island is surrounded by water, so it is closed.Now consider:0 0 1 1 11 0 0 1 11 1 1 1 1The land group touches the top edge of the grid. It is not closed, even though some of its cells have water around them.This gives us the second important observation:An island is closed only if none of its connected land cells touches the boundary of the grid.We now have the complete plan:Find an unvisited land cell.Explore every land cell connected to it.Determine whether that entire island touches the boundary.Count it only if it is closed.Continue looking for other unvisited islands.The remaining challenge is implementing this logic without losing information about whether the island is open or closed.Step 4: Translating the Idea into RecursionLet's design a recursive function called sol().It receives the grid and the current row and column. It returns a boolean:true means the explored land group is closed.false means the group touches the grid boundary and is not closed.The function needs to handle three situations.Case 1: We reach waterIf the current cell contains 1, we have reached water. This direction does not lead to additional land outside the island.We return true because this particular direction does not make the island open.Case 2: We reach the grid boundaryIf the current cell is land and lies on the outermost row or column, the island touches the boundary.That means the island is not closed, so this exploration must eventually return false.However, there is a subtle implementation detail here: we must still mark and explore the boundary-connected land correctly. If we stop immediately at the first boundary cell without exploring the rest of that connected group, some of the island's cells may remain unvisited. A later scan could then mistake part of that same open island for a separate closed island.We will address this in the final implementation.Case 3: We reach unvisited interior landThis is where recursion does the real work.We mark the current cell as visited by changing it to 1. Then we explore all four directions.The island is closed only if every direction confirms that it does not connect to the outside boundary.In boolean terms, the results must be combined using logical AND (&&).If even one path reaches boundary-connected land, the whole island is open.Step 5: Connecting the Recursive Function to the Main LoopWe need a way to start exploring islands.The simplest approach is to scan the grid using two nested loops.The outer loop moves through the rows, and the inner loop moves through the columns. Whenever we find an unvisited land cell, we call our recursive function.If the function confirms that the island is closed, we increment our answer.Why can we modify the grid instead of creating a separate visited matrix?Because the original problem only requires us to return the count. We don't need to preserve the original grid, so changing visited land into water is a convenient way to remember our progress.We also need to avoid counting the same island twice. Once an entire connected island has been explored and marked, its cells will no longer trigger another DFS call from the main loop.Java SolutionHere is the complete implementation. It follows the recursive DFS approach described above and handles boundary-connected islands correctly.class Solution {public boolean sol(int[][] grid, int row, int col) {// Reaching outside the grid means this island is open.if (row < 0 || row >= grid.length ||col < 0 || col >= grid[0].length) {return false;}// Water does not make the island open.if (grid[row][col] == 1) {return true;}// Mark this land cell as visited.grid[row][col] = 1;// Explore all four directions.boolean left = sol(grid, row, col - 1);boolean right = sol(grid, row, col + 1);boolean top = sol(grid, row - 1, col);boolean bottom = sol(grid, row + 1, col);return left && right && top && bottom;}public int closedIsland(int[][] grid) {int rows = grid.length;int cols = grid[0].length;int ans = 0;for (int i = 0; i < rows; i++) {for (int j = 0; j < cols; j++) {if (grid[i][j] == 0) {if (sol(grid, i, j)) {ans++;}}}}return ans;}}What changed from my first attempt?My original code checked whether the current cell was water before checking whether it was on the boundary. It also returned immediately when isperim() detected a boundary land cell.That creates a subtle problem: the boundary cell remains unvisited, and the DFS does not continue through it to explore the rest of the connected island. Consequently, land connected through the boundary can be left behind and potentially counted incorrectly later.The revised code uses a different strategy:It checks whether the coordinates are outside the grid before accessing grid[row][col].It treats water as a successful direction.It marks every visited land cell, including boundary land.It explores all four directions before combining their results.This ensures that the whole connected island is visited, even when it is open.One more detail matters: we store the results of all four recursive calls in separate variables. This is intentional. Writing a short-circuit expression that skips later calls after the first false could leave some cells unexplored.Step 6: Dry RunConsider this grid:1 1 1 1 11 0 0 1 11 1 0 1 11 1 1 1 1The main loop scans the grid until it finds the first zero at (1, 1).First, we start DFS at (1, 1).The cell is land, so we mark it as visited. The function explores its left, right, top, and bottom neighbors.The right neighbor (1, 2) is also land. The DFS visits it and explores its neighbors.The cell (2, 2) is land as well, so the exploration continues there.Eventually, every connected land cell has been visited.Next, we check the four directions.All paths eventually reach water or the outside of the grid through no unvisited land. Because no connected land cell reaches the boundary, the recursive result is true.We increment the answer:ans = 1The main loop continues scanning. Since the three land cells have already been changed to 1, they are not counted again.There are no other land cells, so the final answer is:1This small example demonstrates the entire mechanism: one DFS call discovers the complete island, marks it visited, and returns whether it is closed.A More Important Edge Case: One Island Touching the BoundaryConsider this grid:0 0 1 1 11 0 0 1 11 1 1 1 1The connected land group touches the top boundary.When DFS starts from one of its land cells, it will eventually reach a coordinate outside the grid. That recursive call returns false.The false result propagates through the recursive calls, so the complete island is classified as open and is not counted.Because the DFS still explores all four directions and marks every land cell, the main loop cannot later count another portion of this same island as a closed island.The answer is 0.This is why visiting the complete connected group matters just as much as deciding whether it is closed.Complexity AnalysisLet m be the number of rows and n be the number of columns.Time complexity: O(m × n)Each cell is visited at most once because every visited land cell is changed from 0 to 1. The grid scan also examines every cell. Therefore, the total time complexity is O(m × n).Auxiliary space complexity: O(m × n) in the worst case.The recursive DFS can reach a depth proportional to the number of cells if a large island is connected throughout the grid. The recursion call stack can therefore use O(m × n) space in the worst case.The algorithm modifies the input grid directly and does not require a separate visited matrix.What I Learned from This ProblemThe biggest lesson was that I didn't need to know the term “connected component” before starting. I needed to understand what the problem was asking me to discover.First, I noticed that individual zeroes were not the answer; groups of connected zeroes were. That led to the idea of exploring neighbors.Then I realized that exploring one neighbor should lead to exploring its neighbors too. Recursion gave me a way to express that repeated process.Finally, I understood that a closed island was not just a group of land cells. It was a group that never reached the boundary.The difficult part was not writing four recursive calls. It was making sure the function explored the entire island and correctly communicated whether any part of it touched the boundary.That distinction is worth remembering in future DFS problems: discovering a connected group and evaluating a property of that group are two related, but separate, tasks.Final TakeawayLeetCode 1254 becomes easier to reason about once we stop thinking of it as a mysterious graph problem and start thinking of it as exploring connected land on a map.Use DFS to explore the entire island.Mark visited land so it cannot be counted twice.Treat a path that reaches outside the grid as evidence that the island is open.Count an island only when every explored direction confirms that it is closed.If you struggled to find this approach on your first attempt, that is a normal part of learning DSA. The goal is not to recognize every pattern immediately. It is to learn how to turn an unfamiliar problem into a sequence of smaller, understandable decisions.

LeetCodeJavaRecursionBacktrackingMatrixDFSMedium
LeetCode 1047: Remove All Adjacent Duplicates In String — Java Solution With All Approaches Explained

LeetCode 1047: Remove All Adjacent Duplicates In String — Java Solution With All Approaches Explained

Introduction: What Is LeetCode 1047 Remove All Adjacent Duplicates In String?If you are grinding LeetCode for coding interviews at companies like Google, Amazon, or Microsoft, LeetCode 1047 Remove All Adjacent Duplicates In String is a problem you cannot skip. It is one of the most elegant examples of the stack simulation pattern and appears frequently as a warmup or follow-up question in technical rounds.In this article we will cover everything you need — plain English explanation, real life analogy, 3 Java approaches with dry runs, complexity analysis, common mistakes, FAQs, and similar problems to practice next.Here is the problem link-: Leetcode 1047 What Is the Problem Really Asking?You are given a string. Keep scanning it and whenever you find two same letters sitting next to each other, remove both of them. After removing, the letters around them might now become adjacent and form a new pair — so you keep doing this until no more adjacent duplicates exist.Example walkthrough for "abbaca":"abbaca" → bb are adjacent duplicates → remove → "aaca""aaca" → aa are adjacent duplicates → remove → "ca""ca" → no adjacent duplicates → done!✅ Output: "ca"Real Life Analogy — Think of Popping BubblesImagine a row of colored bubbles. Whenever two bubbles of the same color are next to each other, they pop and disappear. After they pop, the bubbles on either side might now touch each other — and if they are the same color, they pop too! You keep going until no two same-colored bubbles are touching.That chain reaction is exactly what this problem simulates. And the best tool to handle that chain reaction? A stack.Approach 1: Brute Force (Beginner Friendly)The IdeaScan the string repeatedly. Every time you find two adjacent equal characters, remove them. Keep doing this until a full pass finds nothing to remove.public String removeDuplicates(String s) { StringBuilder sb = new StringBuilder(s); boolean found = true; while (found) { found = false; for (int i = 0; i < sb.length() - 1; i++) { if (sb.charAt(i) == sb.charAt(i + 1)) { sb.deleteCharAt(i); sb.deleteCharAt(i); found = true; break; } } } return sb.toString();}This is easy to understand but very slow. For each pair found, you restart the entire scan. With n up to 100,000, this will get Time Limit Exceeded on LeetCode. Use it only to build intuition.Time Complexity: O(n²) — repeated passes over the string Space Complexity: O(n) — StringBuilder storageApproach 2: Stack Based Solution (Classic Interview Approach)The IdeaA stack is perfect here because of one key observation — when you remove a pair, the character that was before the pair is now adjacent to the character after the pair. That is a Last In First Out situation, which is exactly what a stack handles naturally.Algorithm:If the current character matches the top of the stack → pop (they cancel each other)Otherwise → push the current character onto the stackAt the end, the stack contains your final answerpublic String removeDuplicates(String s) { Stack<Character> st = new Stack<>(); StringBuilder sb = new StringBuilder(); for (int i = 0; i < s.length(); i++) { char c = s.charAt(i); if (!st.empty() && c == st.peek()) { st.pop(); // adjacent duplicate found, cancel both } else { st.push(c); } } while (!st.empty()) { sb.append(st.pop()); } return sb.reverse().toString();}Dry Run — "abbaca"We go character by character and check against the top of the stack:a → stack empty, push → stack: [a]b → top is a, not equal, push → stack: [a, b]b → top is b, equal! pop → stack: [a]a → top is a, equal! pop → stack: []c → stack empty, push → stack: [c]a → top is c, not equal, push → stack: [c, a]Stack remaining: [c, a] → reverse → ✅ "ca"Notice how after removing bb, the two as automatically become adjacent and get caught — the stack handles this chain reaction naturally without any extra logic!Time Complexity: O(n) — single pass through the string Space Complexity: O(n) — stack holds up to n charactersApproach 3: StringBuilder as Stack (Optimal Solution) ✅The IdeaThis is your own solution and the best one! Instead of using a separate Stack<Character>, we use StringBuilder itself as a stack:sb.append(c) acts as pushsb.deleteCharAt(sb.length() - 1) acts as popsb.charAt(sb.length() - 1) acts as peekNo extra data structure, no boxing of char into Character objects, and no reversal needed at the end. Clean, fast, and minimal.public String removeDuplicates(String s) { StringBuilder sb = new StringBuilder(); for (int i = 0; i < s.length(); i++) { char c = s.charAt(i); if (sb.length() != 0 && c == sb.charAt(sb.length() - 1)) { sb.deleteCharAt(sb.length() - 1); // adjacent duplicate, remove both } else { sb.append(c); } } return sb.toString();}Dry Run — "azxxzy"a → sb empty, append → "a"z → last char is a, not equal, append → "az"x → last char is z, not equal, append → "azx"x → last char is x, equal! delete → "az"z → last char is z, equal! delete → "a"y → last char is a, not equal, append → "ay"✅ Final Answer: "ay"Again, notice the chain reaction — after xx was removed, z and z became adjacent and got removed too. The StringBuilder handles this perfectly in a single pass!Time Complexity: O(n) — one pass, every character processed exactly once Space Complexity: O(n) — StringBuilder storageWhy StringBuilder Beats Stack in JavaWhen you use Stack<Character> in Java, every char primitive gets auto-boxed into a Character object. That means extra memory allocation for every single character. With StringBuilder, you work directly on the underlying char array — faster and leaner. Plus you skip the reversal step entirely.For an interview, the Stack approach is great for explaining your thought process clearly. But for the final submitted solution, StringBuilder is the way to go.Common Mistakes to AvoidNot checking sb.length() != 0 before peeking If the StringBuilder is empty and you call sb.charAt(sb.length() - 1), you will get a StringIndexOutOfBoundsException. Always guard this check — even if the problem guarantees valid input, it shows clean coding habits.Thinking you need multiple passes Many beginners think you need to scan the string multiple times because of chain reactions. The stack handles chain reactions automatically in a single pass. Trust the process!Forgetting to reverse when using Stack Since a stack gives you characters in reverse order when you pop them, you must call .reverse() at the end. With StringBuilder you do not need this.How This Fits Into the Stack Simulation PatternBy now you might be noticing a theme across multiple problems:LeetCode 3174 Clear Digits — digit acts as backspace, deletes closest left non-digit LeetCode 2390 Removing Stars — star acts as backspace, deletes closest left non-star LeetCode 1047 Remove Adjacent Duplicates — character cancels itself if it matches the top of stackAll three use the exact same StringBuilder-as-stack pattern. The only difference is the condition that triggers a deletion. This is why pattern recognition is the real skill — once you internalize this pattern, you can solve a whole family of problems in minutes.FAQs — People Also AskQ1. What is the best approach for LeetCode 1047 in Java? The StringBuilder approach is the best. It runs in O(n) time, uses O(n) space, requires no extra data structure, and avoids the reversal step needed with a Stack.Q2. Why does a stack work for removing adjacent duplicates? Because whenever you remove a pair, the characters around them become the new neighbors. A stack naturally keeps track of the most recently seen character, so it catches these chain reactions without any extra logic.Q3. What is the time complexity of LeetCode 1047? The optimal solution runs in O(n) time and O(n) space, where n is the length of the input string.Q4. Is LeetCode 1047 asked in coding interviews? Yes, it is commonly asked as a warmup problem or follow-up at companies like Google, Amazon, and Adobe. It tests your understanding of stack-based string manipulation.Q5. What is the difference between LeetCode 1047 and LeetCode 1209? LeetCode 1047 removes pairs of adjacent duplicates. LeetCode 1209 is the harder version — it removes groups of k adjacent duplicates, requiring you to store counts alongside characters in the stack.Similar LeetCode Problems to Practice Next2390. Removing Stars From a String — Medium — star as backspace3174. Clear Digits — Easy — digit as backspace844. Backspace String Compare — Easy — compare two strings after backspaces1209. Remove All Adjacent Duplicates in String II — Medium — harder version with k duplicates735. Asteroid Collision — Medium — stack simulation with collision logicConclusionLeetCode 1047 Remove All Adjacent Duplicates In String is a beautiful problem that teaches you one of the most powerful and reusable patterns in DSA — stack simulation. The moment you spot that a removal can cause a chain reaction of more removals, you know a stack is your best friend.The StringBuilder solution is clean, optimal, and interview-ready. Master it, understand why it works, and you will be able to tackle the entire family of stack simulation problems with confidence.Found this helpful? Share it with friends preparing for coding interviews

LeetCodeJavaStackStringEasy
The Voltage Regulator Problem: Find The Longest Stable Subarray With One Change – Java Solution

The Voltage Regulator Problem: Find The Longest Stable Subarray With One Change – Java Solution

The Problem: Keeping Our Servers StableImagine that you are a software engineer at KodeSword, responsible for a row of servers. Each server operates at a particular voltage, represented by an integer array called voltages.For safety, a group of neighboring servers is considered stable if the difference between its highest and lowest voltages is at most K.In simple terms:maximum voltage - minimum voltage <= KBut there is a twist. You have one voltage regulator that can change the voltage of any one server to any integer value you choose.Your task is to find the maximum length of a contiguous group of servers that can be made stable using the regulator at most once.You cannot rearrange the servers or select servers from different parts of the array. The group must remain contiguous.Example 1: Can We Save the Entire Group?Input:voltages = [2, 15, 6, 3]K = 4Output: 4Without changing anything, the maximum voltage is 15, and the minimum is 2.The difference is 15 - 2 = 13, which exceeds K = 4. Therefore, the entire group is initially unstable.But we have a regulator. What if we change the voltage 15 to 4?Before: [2, 15, 6, 3]After: [2, 4, 6, 3]Now the minimum is 2, and the maximum is 6.6 - 2 = 4The group is stable, and its length is 4. Since the array has only four elements, we cannot obtain a longer group.Answer: 4At first glance, this looks like a simple example. But how do we know which server to change when the array contains thousands of values? And how do we find the longest valid group without checking every possible subarray?That's where the actual problem-solving begins.Try It YourselfBefore reading the solution, take a moment to think about the problem.Can you find a way to determine whether a group can be made stable without trying every possible replacement voltage?Try to design an algorithm that works for an array of up to 100,000 elements.Start Challenge -: Let's Solve ItStep 1: What Does the Regulator Actually Change?At first, we might think we need to try many possible replacement values for every server.For example, if we choose the server with voltage 15, should we change it to 4, 5, 6, or something else?The key observation is that we do not need to try every possible replacement value.Suppose we temporarily ignore the server we want to change. If the remaining voltages have a maximum-minus-minimum difference of at most K, we can set the changed server's voltage to a value between their minimum and maximum.For our example:Original group: [2, 15, 6, 3]Ignore 15: [2, 6, 3]The remaining minimum is 2, and the maximum is 6.Their difference is 6 - 2 = 4, so replacing 15 with any integer between 2 and 6 makes the group stable.We are not actually deleting a server from the final answer. We are only ignoring its original voltage while checking whether a replacement can work.This transforms the problem into a simpler question:What is the longest contiguous subarray whose voltage range becomes at most K after ignoring at most one element?Step 2: Which Element Should We Change?Consider this group:[2, 6, 15, 18]Its range is 18 - 2 = 16.If K = 4, the group is unstable.Which element should we change?Changing a middle value such as 6 will not help because the minimum and maximum remain 2 and 18.Therefore, if the range exceeds K, we only need to consider two possibilities:Change the minimum voltage.Change the maximum voltage.If neither the minimum nor the maximum is changed, the range stays exactly the same.For [2, 6, 15, 18]:Change the minimum: the remaining range is 18 - 6 = 12.Change the maximum: the remaining range is 15 - 2 = 13.Neither is at most 4, so the group cannot be fixed with one adjustment.This observation helps us avoid testing every element in the group.Step 3: What If an Extreme Value Appears Multiple Times?Consider:[2, 2, 6, 15]If we change one occurrence of 2, another 2 remains. The minimum does not change.Similarly, changing one occurrence of a repeated maximum leaves the other occurrence in the group.Therefore, when the range exceeds K, changing the minimum can help only if the minimum occurs exactly once. The same rule applies to the maximum.We also need to know the next distinct minimum or maximum after changing a unique extreme.For example:[2, 6, 15, 18]If we ignore 2, the next minimum is 6. If we ignore 18, the next maximum is 15.This is why tracking only the current minimum and maximum is not enough. We also need their frequencies and access to the next distinct values.Step 4: Use a Sliding WindowWe want the longest valid contiguous group, so let's maintain a window with a left boundary and a right boundary.Start with an empty window. Move the right boundary forward one element at a time, adding each new voltage.After adding a value, check whether the current window can be made stable.If it can, keep expanding.If it cannot, move the left boundary forward until the window becomes valid again.For the original example:voltages = [2, 15, 6, 3]K = 4The window grows as follows:[2] is valid without any adjustment.[2, 15] can be fixed by changing one of its values.[2, 15, 6] can be fixed by changing 15.[2, 15, 6, 3] can also be fixed by changing 15 to 4.The final window has length 4.An important property makes this approach work: if a window is valid, every smaller contiguous window inside it is also valid. We can always keep the same replacement if the changed element remains in the smaller window, or leave the smaller window unchanged if it does not.This allows us to shrink invalid windows instead of starting over.Step 5: Maintain the Window With a TreeMapWe need to efficiently track:The minimum voltage.The maximum voltage.The frequency of each extreme.The next distinct minimum and maximum.Java's TreeMap stores keys in sorted order and keeps a count for each voltage.For example, the window [2, 6, 6, 15] can be represented as:Voltage: 2 6 15Count: 1 2 1The first key is the minimum, and the last key is the maximum.The higherKey() method retrieves the next distinct key above a given value. The lowerKey() method retrieves the previous distinct key below a given value.Whenever a voltage enters or leaves the window, we update its count. If its count becomes zero, we remove that key from the map.This gives us the information required to check whether the window is valid.Java Solutionimport java.util.TreeMap;class Solution {private boolean isValid(TreeMap<Integer, Integer> map, int k) {int min = map.firstKey();int max = map.lastKey();// Already stable.if ((long) max - min <= k) {return true;}// Try changing the unique minimum.if (map.get(min) == 1) {int secondMin = map.higherKey(min);if ((long) max - secondMin <= k) {return true;}}// Try changing the unique maximum.if (map.get(max) == 1) {int secondMax = map.lowerKey(max);if ((long) secondMax - min <= k) {return true;}}return false;}public int maxStableGroup(int[] voltages, int k) {TreeMap<Integer, Integer> map = new TreeMap<>();int left = 0;int ans = 0;for (int right = 0; right < voltages.length; right++) {int value = voltages[right];map.put(value, map.getOrDefault(value, 0) + 1);while (!isValid(map, k)) {int removed = voltages[left];map.put(removed, map.get(removed) - 1);if (map.get(removed) == 0) {map.remove(removed);}left++;}ans = Math.max(ans, right - left + 1);}return ans;}}The method name maxStableGroup is specific to this custom problem. If you use the solution on a platform that requires a particular method signature, adjust the name and parameters accordingly.Additional Test Cases: Can You Predict the Output?Try these examples before reading their explanations. They cover a single extreme value, decreasing values, an already-stable array, and repeated spikes.Test Case 2: One Extreme Voltage SurgeInput:voltages = [10, 12, 100, 11, 13]K = 3Output: 5The value 100 creates a range that is too large. But we can change that single value to 12:[10, 12, 12, 11, 13]The maximum is 13, and the minimum is 10.13 - 10 = 3The entire array is stable, so the answer is 5.Think about it: What makes this case easier than the next one? There is only one extreme value that needs to be corrected.Test Case 3: Decreasing VoltagesInput:voltages = [50, 40, 30, 20, 10]K = 15Output: 3Consider the first three elements:[50, 40, 30]Their range is 50 - 30 = 20, which exceeds 15.We can change 50 to 35, giving:[35, 40, 30]Now the range is 40 - 30 = 10, which is valid. The group has length 3.We can also select [40, 30, 20] or [30, 20, 10], each of which has a range of 20. Changing one extreme can make either group valid.No group of length 4 can be made stable with just one adjustment, so the answer is 3.Think about it: The values are already ordered. Does that mean we can skip checking whether the group is valid? No. We still need to consider the range and the single permitted adjustment.Test Case 4: No Regulator NeededInput:voltages = [5, 7, 6, 8, 5, 7]K = 5Output: 6The entire array has a minimum of 5 and a maximum of 8.8 - 5 = 3Since 3 <= 5, the entire array is already stable. We don't need to use the regulator.The answer is 6, the full array length.Think about it: The regulator is available, but does that mean we must use it? No. The problem allows us to use it at most once.Test Case 5: Alternating Voltage SpikesInput:voltages = [1, 20, 2, 20, 3, 20]K = 2Output: 3Consider the first three elements:[1, 20, 2]We can change 20 to 2, giving:[1, 2, 2]The range is 2 - 1 = 1, which is valid. Therefore, a group of length 3 is possible.Now consider a window of length 4:[1, 20, 2, 20]There are two occurrences of 20. Changing only one of them leaves the other 20 in the group, and the range remains too large.No length-four window in this array can be made stable with one adjustment. Therefore, the maximum length is 3.Think about it: Why does the regulator fail here even though the array contains a fixable three-element group? Because one adjustment cannot eliminate two extreme spikes.Complexity AnalysisLet N be the length of the array.Time complexity: O(N log N)Each element enters the sliding window once and leaves it at most once. Updating the TreeMap takes O(log N) time, and checking the window's validity also takes O(log N) time.Therefore, the overall time complexity is O(N log N).Auxiliary space complexity: O(N)In the worst case, the TreeMap can store up to N distinct voltage values.Final TakeawayThe most important part of this problem is understanding what the regulator can actually fix.If the range is already within K, we keep the window. Otherwise, changing a middle value cannot reduce the range. We need to check whether changing the unique minimum or maximum makes the remaining range valid.A TreeMap helps us track those extreme values, while a sliding window lets us find the longest valid contiguous group efficiently.The broader lesson is simple: when a problem allows one modification, first ask which part of the condition that modification can affect. A good observation can eliminate a huge number of unnecessary possibilities.

JavaSliding WindowArraysTreeMapDSA
Reverse LinkedList (LeetCode 206) – The One Trick That Changes Everything

Reverse LinkedList (LeetCode 206) – The One Trick That Changes Everything

🚀 Try the ProblemPractice here:https://leetcode.com/problems/reverse-linked-list/🤔 Let’s Start With a Simple Question…What happens if you take this:1 → 2 → 3 → 4 → 5…and try to reverse it?You want:5 → 4 → 3 → 2 → 1Sounds easy, right?But here’s the catch:👉 You can only move forward in a linked list👉 There is no backward pointerSo how do we reverse something that only goes one way?🧠 The Core Problem (In Simple Words)You are given the head of a linked list.👉 Reverse the list👉 Return the new head📦 Constraints0 <= number of nodes <= 5000-5000 <= Node.val <= 5000🔍 Before Jumping to Code — Think Like ThisWhen solving this, your brain might go:Can I store values somewhere and reverse? ❌ (extra space)Can I rebuild the list? ❌ (unnecessary)Can I just change links? ✅ (YES, THIS IS THE KEY)⚡ The Breakthrough Idea👉 Instead of moving nodes👉 We reverse the direction of pointers🎯 Visual Intuition (Very Important)Let’s take:1 → 2 → 3 → 4 → nullWe want:null ← 1 ← 2 ← 3 ← 4But how?🧩 The 3-Pointer Magic TrickWe use 3 pointers:prev → stores previous nodecurr → current nodenext → stores next node🔄 Step-by-Step TransformationInitial State:prev = nullcurr = 1 → 2 → 3 → 4Step 1:Save next nodeReverse linkf = 21 → nullMove pointers:prev = 1curr = 2Step 2:f = 32 → 1Move:prev = 2curr = 3Continue…Eventually:4 → 3 → 2 → 1 → null💡 Final Insight👉 Each step reverses one link👉 At the end, prev becomes the new head✅ Clean Java Code (Iterative Approach)class Solution {public ListNode reverseList(ListNode head) {// Previous pointer starts as nullListNode prev = null;// Current pointer starts from headListNode curr = head;while (curr != null) {// Store next nodeListNode f = curr.next;// Reverse the linkcurr.next = prev;// Move prev forwardprev = curr;// Move curr forwardcurr = f;}// New head is prevreturn prev;}}⏱️ ComplexityTime ComplexityO(n)We traverse the list once.Space ComplexityO(1)No extra space used.🔁 Another Way: Recursive ApproachNow let’s think differently…👉 What if we reverse the rest of the list first, then fix the current node?🧠 Recursive IdeaFor:1 → 2 → 3 → 4We:Reverse from 2 → 3 → 4Then fix 1💻 Recursive Codeclass Solution {public ListNode reverseList(ListNode head) {// Base caseif(head == null || head.next == null)return head;// Reverse restListNode newHead = reverseList(head.next);// Fix current nodehead.next.next = head;head.next = null;return newHead;}}⚖️ Iterative vs RecursiveApproachProsConsIterativeFast, O(1) spaceSlightly tricky to understandRecursiveElegant, clean logicUses stack (O(n) space)❌ Common MistakesForgetting to store next nodeLosing reference to rest of listNot updating pointers correctlyReturning wrong node🔥 Real Interview InsightThis problem is not just about reversing a list.It teaches:👉 Pointer manipulation👉 In-place updates👉 Thinking in steps👉 Breaking problems into small operations🧠 Final ThoughtAt first, this problem feels tricky…But once you understand this line:curr.next = prev👉 Everything clicks.🚀 ConclusionThe Reverse Linked List problem is one of the most important foundational problems in DSA.Mastering it will:Boost your confidenceStrengthen pointer logicHelp in many advanced problems👉 Tip: Practice this until you can visualize pointer movement in your head — that’s when you truly master linked lists.

Linked ListPointer ManipulationIterative ApproachRecursionLeetCodeEasy
LeetCode 123 — Best Time to Buy and Sell Stock III | At Most Two Transactions Explained

LeetCode 123 — Best Time to Buy and Sell Stock III | At Most Two Transactions Explained

🚀 Try This Problem First!Before reading the solution, attempt it yourself on LeetCode — you will learn much more that way.🔗 Problem Link: https://leetcode.com/problems/best-time-to-buy-and-sell-stock-iii/What Is the Problem Asking?You have a list of stock prices, one for each day. You are allowed to buy and sell the stock, but with one important restriction — you can make at most two transactions in total. A transaction means one buy followed by one sell.You cannot hold two stocks at the same time, meaning you must sell whatever you are holding before you buy again.Your job is to find the maximum profit you can make by doing at most two transactions. If there is no way to make any profit, return 0.Example to build intuition: prices = [3, 3, 5, 0, 0, 3, 1, 4]If you buy on day 4 (price 0) and sell on day 6 (price 3), profit = 3. Then buy on day 7 (price 1) and sell on day 8 (price 4), profit = 3. Total profit = 6. That is the best you can do.Constraints:1 ≤ prices.length ≤ 10⁵0 ≤ prices[i] ≤ 10⁵Why Is This Harder Than the Previous Stock Problems?In LeetCode 121, you could only make one transaction — so you just found the best single buy-sell pair.In LeetCode 122, you could make unlimited transactions — so you greedily collected every upward price movement.Here, you are limited to exactly two transactions. Greedy does not work anymore because sometimes skipping a small profit early on allows you to make a much bigger combined profit across two trades. You need a smarter strategy.The Big Idea Behind the SolutionHere is a simple way to think about it.If you are allowed two transactions, you can imagine drawing a dividing line somewhere in the price array. The first transaction happens entirely on the left side of that line. The second transaction happens entirely on the right side.So the problem becomes:For every possible dividing position, find the best profit on the left side and the best profit on the right side.Add them together.The maximum sum across all dividing positions is your answer.The challenge is doing this efficiently without checking every position with a nested loop, which would be O(N²) and too slow.Approach 1 — Left-Right Prefix DPThe idea:Instead of trying every split point from scratch, precompute the answers in advance.Build a leftProfit array where leftProfit[i] stores the best single transaction profit you can make using prices from day 0 to day i.Build a rightProfit array where rightProfit[i] stores the best single transaction profit you can make using prices from day i to the last day.Then for every index i, the answer if you split at i is simply leftProfit[i] + rightProfit[i]. Take the maximum across all indices.How to build leftProfit:Go left to right. Keep track of the minimum price seen so far. At each day i, the best profit you could make ending at or before day i is either the same as the day before, or selling today at today's price minus the minimum price seen so far. Take whichever is larger.How to build rightProfit:Go right to left. Keep track of the maximum price seen so far from the right. At each day i, the best profit you could make starting at or after day i is either the same as the day after, or buying today at today's price and selling at the maximum price seen to the right. Take whichever is larger.Dry Run — prices = [3, 3, 5, 0, 0, 3, 1, 4]Building leftProfit left to right, tracking minimum price seen:Day 0 → min=3, leftProfit[0] = 0 (nothing to compare yet) Day 1 → min=3, best profit = 3-3 = 0, leftProfit[1] = max(0, 0) = 0 Day 2 → min=3, best profit = 5-3 = 2, leftProfit[2] = max(0, 2) = 2 Day 3 → min=0, best profit = 0-0 = 0, leftProfit[3] = max(2, 0) = 2 Day 4 → min=0, best profit = 0-0 = 0, leftProfit[4] = max(2, 0) = 2 Day 5 → min=0, best profit = 3-0 = 3, leftProfit[5] = max(2, 3) = 3 Day 6 → min=0, best profit = 1-0 = 1, leftProfit[6] = max(3, 1) = 3 Day 7 → min=0, best profit = 4-0 = 4, leftProfit[7] = max(3, 4) = 4leftProfit = [0, 0, 2, 2, 2, 3, 3, 4]Building rightProfit right to left, tracking maximum price seen:Day 7 → max=4, rightProfit[7] = 0 (nothing to compare yet) Day 6 → max=4, best profit = 4-1 = 3, rightProfit[6] = max(0, 3) = 3 Day 5 → max=4, best profit = 4-3 = 1, rightProfit[5] = max(3, 1) = 3 Day 4 → max=4, best profit = 4-0 = 4, rightProfit[4] = max(3, 4) = 4 Day 3 → max=4, best profit = 4-0 = 4, rightProfit[3] = max(4, 4) = 4 Day 2 → max=5, best profit = 5-5 = 0, rightProfit[2] = max(4, 0) = 4 Day 1 → max=5, best profit = 5-3 = 2, rightProfit[1] = max(4, 2) = 4 Day 0 → max=5, best profit = 5-3 = 2, rightProfit[0] = max(4, 2) = 4rightProfit = [4, 4, 4, 4, 4, 3, 3, 0]Combining at each index: Index 0 → 0 + 4 = 4 Index 1 → 0 + 4 = 4 Index 2 → 2 + 4 = 6 Index 3 → 2 + 4 = 6 Index 4 → 2 + 4 = 6 Index 5 → 3 + 3 = 6 Index 6 → 3 + 3 = 6 Index 7 → 4 + 0 = 4Maximum = 6 ✅Implementation code:class Solution { public int maxProfit(int[] prices) { int lefProf[] = new int[prices.length]; int rigProf[] = new int[prices.length]; int j = 1; int i = 0; int coL = 1; while (i < j && j < prices.length) { if (prices[i] > prices[j]) { i = j; if (coL - 1 != -1) { lefProf[coL] = lefProf[coL - 1]; } coL++; } else { int max = prices[j] - prices[i]; if (coL - 1 != -1) { lefProf[coL] = Math.max(lefProf[coL - 1], max); coL++; } else { lefProf[coL] = max; coL++; } } j++; } int ii = prices.length - 2; int jj = prices.length - 1; int coR = prices.length - 2; while (ii >= 0) { if (prices[ii] > prices[jj]) { jj = ii; if (coR + 1 < prices.length) { rigProf[coR] = rigProf[coR + 1]; } coR--; } else { int max = prices[jj] - prices[ii]; if (coR + 1 < prices.length) { rigProf[coR] = Math.max(rigProf[coR + 1], max); coR--; } else { rigProf[coR] = max; coR--; } } ii--; } int maxAns = 0; for (int k = 0; k < lefProf.length; k++) { maxAns = Math.max(maxAns, lefProf[k] + rigProf[k]); } return maxAns; }}The approach here is exactly right. You are building the left and right profit arrays using a two pointer scanning technique — the same idea as LeetCode 121 but applied twice, once going forward and once going backward. The manual counters coL and coR make it a bit harder to follow, but the logic underneath is solid.Here is the same approach written in a cleaner way so it is easier to read and debug:class Solution { public int maxProfit(int[] prices) { int n = prices.length; int[] leftProfit = new int[n]; int[] rightProfit = new int[n]; int minPrice = prices[0]; for (int i = 1; i < n; i++) { minPrice = Math.min(minPrice, prices[i]); leftProfit[i] = Math.max(leftProfit[i - 1], prices[i] - minPrice); } int maxPrice = prices[n - 1]; for (int i = n - 2; i >= 0; i--) { maxPrice = Math.max(maxPrice, prices[i]); rightProfit[i] = Math.max(rightProfit[i + 1], maxPrice - prices[i]); } int maxProfit = 0; for (int i = 0; i < n; i++) { maxProfit = Math.max(maxProfit, leftProfit[i] + rightProfit[i]); } return maxProfit; }}Time Complexity: O(N) — three separate linear passes through the array. Space Complexity: O(N) — two extra arrays of size N.Approach 2 — Four Variable State Machine DPThe idea:Instead of building arrays, what if you could track everything in just four variables and solve it in a single pass?Think about what is happening at any point in time as you go through the prices. You are always in one of these situations:You have bought your first stock and are currently holding it. You have sold your first stock and are sitting on that profit. You have bought your second stock (using the profit from the first sale) and are holding it. You have sold your second stock and collected your total profit.These four situations are your four states. For each one, you always want to know — what is the best possible profit I could have in this state up to today?Here is how each state updates as you look at a new price:buy1 — This represents the best outcome after buying the first stock. Buying costs money, so this is negative. As you see each new price, you ask: is it better to have bought on some earlier day, or to buy today? You keep whichever gives you the least cost, which means the highest value of negative price.sell1 — This represents the best profit after completing the first transaction. As you see each new price, you ask: is it better to have sold on some earlier day, or to sell today using the best buy1 we have? Selling today means adding today's price on top of buy1.buy2 — This represents the best outcome after buying the second stock. The key insight here is that you are not starting from zero — you already have the profit from the first transaction in your pocket. So buying the second stock costs today's price but you subtract it from sell1. As you see each new price, you ask: is it better to have bought the second stock earlier, or to buy today using the profit from sell1?sell2 — This is your final answer. It represents the best total profit after completing both transactions. As you see each new price, you ask: is it better to have completed both transactions earlier, or to sell the second stock today using the best buy2 we have?The beautiful thing is that all four updates happen in order on every single day, in one pass through the array. Each variable feeds into the next — buy1 feeds sell1, sell1 feeds buy2, buy2 feeds sell2.Dry Run — prices = [3, 3, 5, 0, 0, 3, 1, 4]We start with buy1 and buy2 as very negative (not yet bought anything) and sell1 and sell2 as 0 (no profit yet).Day 0, price = 3: buy1 = max(-∞, -3) = -3. Best cost to buy first stock is spending 3. sell1 = max(0, -3+3) = 0. Selling immediately gives no profit. buy2 = max(-∞, 0-3) = -3. Best cost to buy second stock after first sale is 3. sell2 = max(0, -3+3) = 0. No total profit yet.Day 1, price = 3: Nothing changes — same price as day 0.Day 2, price = 5: buy1 = max(-3, -5) = -3. Still best to have bought at price 3. sell1 = max(0, -3+5) = 2. Selling today at 5 after buying at 3 gives profit 2. buy2 = max(-3, 2-5) = -3. Buying second stock today costs too much relative to first profit. sell2 = max(0, -3+5) = 2. Completing both trades gives 2 so far.Day 3, price = 0: buy1 = max(-3, -0) = 0. Buying today at price 0 is the best possible first buy. sell1 = max(2, 0+0) = 2. Selling today at 0 gives nothing — keep the 2 from before. buy2 = max(-3, 2-0) = 2. Using the profit of 2 and buying today at 0 gives buy2 = 2. sell2 = max(2, 2+0) = 2. Selling second stock today at 0 gives nothing extra.Day 4, price = 0: Nothing changes — same price as day 3.Day 5, price = 3: buy1 = max(0, -3) = 0. Still best to have bought at price 0. sell1 = max(2, 0+3) = 3. Selling today at 3 after buying at 0 gives profit 3. buy2 = max(2, 3-3) = 2. Buying second stock today at 3 using sell1=3 gives 0. Keep 2. sell2 = max(2, 2+3) = 5. Selling second stock today at 3 after buy2=2 gives total 5.Day 6, price = 1: buy1 = max(0, -1) = 0. Still best to have bought at 0. sell1 = max(3, 0+1) = 3. Selling today at 1 gives less than 3 — no change. buy2 = max(2, 3-1) = 2. Buying second stock at 1 using sell1=3 gives 2 — same as before. sell2 = max(5, 2+1) = 5. No improvement yet.Day 7, price = 4: buy1 = max(0, -4) = 0. No change. sell1 = max(3, 0+4) = 4. Selling today at 4 after buying at 0 gives profit 4 — new best. buy2 = max(2, 4-4) = 2. No improvement. sell2 = max(5, 2+4) = 6. Selling second stock today at 4 with buy2=2 gives total 6 — new best.Output: 6 ✅class Solution { public int maxProfit(int[] prices) { int buy1 = Integer.MIN_VALUE; int sell1 = 0; int buy2 = Integer.MIN_VALUE; int sell2 = 0; for (int price : prices) { buy1 = Math.max(buy1, -price); sell1 = Math.max(sell1, buy1 + price); buy2 = Math.max(buy2, sell1 - price); sell2 = Math.max(sell2, buy2 + price); } return sell2; }}Time Complexity: O(N) — single pass through the array. Space Complexity: O(1) — only four integer variables, no extra arrays.Approach 3 — Generalizing to At Most K TransactionsOnce you understand Approach 2, there is a natural question — what if instead of two transactions, you were allowed K transactions? That is exactly LeetCode 188.Instead of four hardcoded variables, you use two arrays of size K. buy[j] tracks the best outcome after the j-th buy and sell[j] tracks the best outcome after the j-th sell. The logic is identical to Approach 2, just in a loop.For this problem set K = 2 and it gives the same answer:class Solution { public int maxProfit(int[] prices) { int k = 2; int[] buy = new int[k]; int[] sell = new int[k]; Arrays.fill(buy, Integer.MIN_VALUE); for (int price : prices) { for (int j = 0; j < k; j++) { buy[j] = Math.max(buy[j], (j == 0 ? 0 : sell[j - 1]) - price); sell[j] = Math.max(sell[j], buy[j] + price); } } return sell[k - 1]; }}Time Complexity: O(N × K) — for K=2 this is effectively O(N). Space Complexity: O(K) — two small arrays of size K.If you understand this, LeetCode 188 becomes a five minute problem.Comparing All Three ApproachesApproach 1 — Left-Right Prefix DP (Your Approach)You build two arrays — one scanning left to right, one scanning right to left — and combine them. This is the most visual and intuitive approach. It is easy to explain because you are essentially solving LeetCode 121 twice from opposite ends and adding the results. The downside is it uses O(N) extra space for the two arrays.Approach 2 — Four Variable State MachineYou solve the entire problem in a single pass using just four variables. No arrays, no extra memory. This is the most efficient and elegant solution. Once you understand what each variable represents, the code almost writes itself. This is what most interviewers are hoping to see.Approach 3 — General K-Transaction DPThis is Approach 2 extended to handle any number of transactions using arrays instead of hardcoded variables. Solving LeetCode 123 with this approach means you have already solved LeetCode 188 as a bonus.Mistakes That Catch Most PeopleTrying to use the greedy approach from LeetCode 122: Adding every upward price movement does not work when you are limited to two transactions. You need to pick the two best non-overlapping windows, not collect everything.Buying twice without selling in between: The state machine prevents this naturally — buy2 depends on sell1, so you can never enter the second buy before completing the first sell.Initializing buy variables to 0: Both buy1 and buy2 must start at Integer.MIN_VALUE. Setting them to 0 implies you bought a stock for free, which is wrong and will give inflated profits.Returning the wrong variable: Always return sell2, not buy2 or sell1. sell2 is the only variable that represents a completed two-transaction profit.Where This Fits in the Stock SeriesLeetCode 121 — One transaction only. Find the single best buy-sell pair. [ Blog is also avaliable on this - Read Now ]LeetCode 122 — Unlimited transactions. Collect every upward price movement greedily. [ Blog is also avaliable on this - Read Now ]LeetCode 188 — At most K transactions. Direct extension of Approach 3 above.LeetCode 309 — Unlimited transactions but with a cooldown day after every sale.LeetCode 714 — Unlimited transactions but with a fee charged on every transaction.Each problem adds one new constraint on top of the previous one. If you understand LeetCode 123 deeply — especially Approach 2 — every other problem in this series becomes a small modification of the same framework.Key Takeaways✅ When you are limited to two transactions, greedy fails. You need to find two non-overlapping windows that together give maximum profit.✅ The left-right prefix DP approach is the most intuitive — precompute the best single transaction from both ends, then combine at every split point.✅ The four variable state machine solves it in one pass with O(1) space. Each variable tracks the best outcome for one state — buy1 feeds sell1, sell1 feeds buy2, buy2 feeds sell2.✅ Always initialize buy variables to Integer.MIN_VALUE to represent "not yet bought anything."✅ Understanding Approach 3 here means LeetCode 188 is already solved — just change the hardcoded 2 to K.Happy Coding! This problem is the turning point in the stock series where DP becomes unavoidable — once you crack it, the rest of the series feels manageable. 🚀

LeetCodeDynamic ProgrammingHardJavaDSAPrefix DPArraysStock Series
Ai Assistant Kas