Search Blogs

Showing results for "Linear Search"

Found 21 results

Ceil in a Sorted Array – Binary Search Explained with Story & Visuals | GeeksforGeeks

Ceil in a Sorted Array – Binary Search Explained with Story & Visuals | GeeksforGeeks

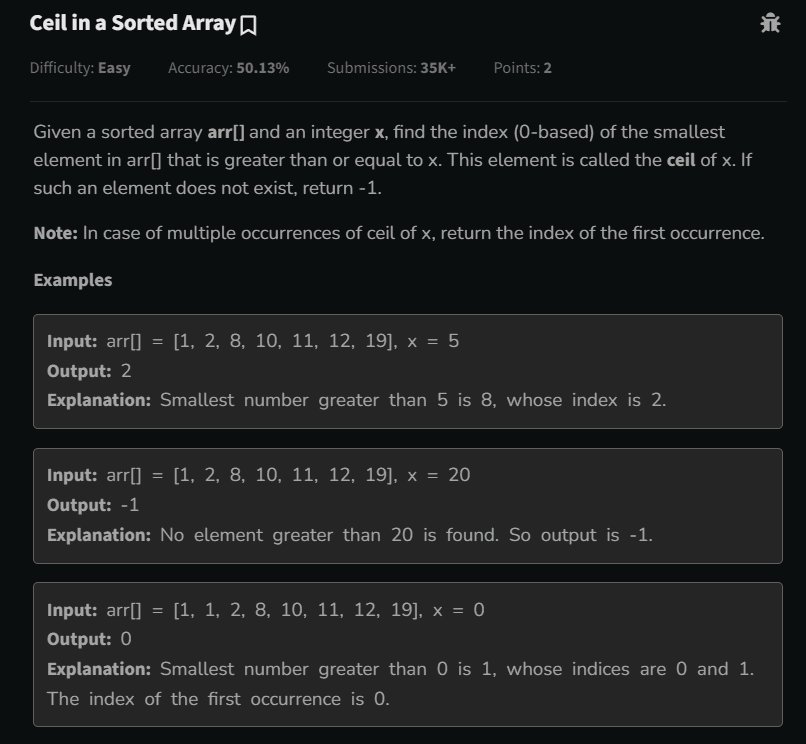
Try This Problem FirstPlatform: GeeksforGeeksπŸ‘‰ Try this problem here: Ceil in a Sorted Array – GeeksforGeeksProblem StatementYou are given a sorted array arr[] and an integer x. Your task is to find the index of the smallest element in the array that is greater than or equal to x.If no such element exists, return -1.If multiple elements equal the ceil, return the first occurrence.Example:Input: arr = [1, 2, 8, 10, 11, 12, 19], x = 5Output: 2Explanation: Smallest element β‰₯ 5 is 8 at index 2.IntuitionThink of the problem as finding the first step you can reach without falling short:The ceil of x is the smallest number β‰₯ x.Since the array is sorted, we can use binary search to quickly locate the answer instead of checking each element.Linear search is simple but slow for large arrays. Binary search gives an efficient O(log n) solution.Multiple Approaches1️⃣ Linear Search (Easy to Understand)int ans = -1;for(int i = 0; i < arr.length; i++){if(arr[i] >= x){ans = i; // first occurrencebreak;}}return ans;Time Complexity: O(n)Space Complexity: O(1)βœ… Works for small arrays❌ Slow for large arrays2️⃣ Binary Search (Optimized & Fast)int ans = -1;int low = 0, high = arr.length - 1;while(low <= high){int mid = low + (high - low)/2;if(arr[mid] == x){ans = mid;high = mid - 1; // move left for first occurrence} else if(arr[mid] > x){ans = mid; // candidate ceilhigh = mid - 1; // move left} else {low = mid + 1; // arr[mid] < x β†’ move right}}return ans;Time Complexity: O(log n)Space Complexity: O(1)βœ… Efficient for large arraysβœ… Automatically returns first occurrenceDry RunInput: arr = [1, 2, 8, 10, 11, 12, 19], x = 5Steplowhighmidarr[mid]ansAction1063103arr[mid] > x β†’ move left202123arr[mid] < x β†’ move right322282arr[mid] > x β†’ move left421--2low > high β†’ stop, return 2βœ… Binary search finds ceil = 8 at index 2.Why This Problem is ImportantTeaches binary search for first occurrenceStrengthens understanding of ceil/floor conceptsVisualization through story improves understanding and retentionPrepares for coding interviews and competitive programmingConclusionLinear search: simple but slow (O(n))Binary search: fast and efficient (O(log n))Story-based visualization helps learn, not just memorizeUsing numbers on books in images makes abstract concepts concrete
GeeksForGeeksEasyBinary SearchSorted Array
Mastering Binary Search – LeetCode 704 Explained

Mastering Binary Search – LeetCode 704 Explained

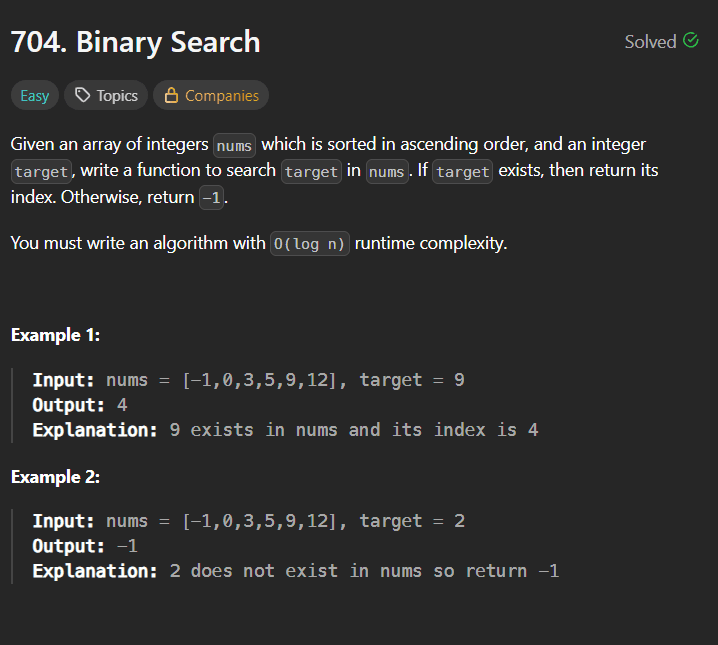
IntroductionBinary Search is one of the most fundamental and powerful algorithms in computer science. If you're preparing for coding interviews, mastering Binary Search is absolutely essential.In this blog, we’ll break down LeetCode 704 – Binary Search, explain the algorithm in detail, walk through your Java implementation, analyze complexity, and recommend additional problems to strengthen your understanding.You can try this problem -: Problem LinkπŸ“Œ Problem OverviewYou are given:A sorted array of integers nums (ascending order)An integer targetYour task is to return the index of target if it exists in the array. Otherwise, return -1.Example 1Input: nums = [-1,0,3,5,9,12], target = 9Output: 4Example 2Input: nums = [-1,0,3,5,9,12], target = 2Output: -1Constraints1 <= nums.length <= 10⁴All integers are uniqueThe array is sorted in ascending orderRequired Time Complexity: O(log n)πŸš€ Understanding the Binary Search AlgorithmBinary Search works only on sorted arrays.Instead of checking each element one by one (like Linear Search), Binary Search:Finds the middle element.Compares it with the target.Eliminates half of the search space.Repeats until the element is found or the search space is empty.Why is it Efficient?Every iteration cuts the search space in half.If the array size is n, the number of operations becomes:logβ‚‚(n)This makes it extremely efficient compared to linear search (O(n)).🧠 Step-by-Step AlgorithmInitialize two pointers:low = 0high = nums.length - 1While low <= high:Calculate middle index:mid = low + (high - low) / 2If nums[mid] == target, return midIf target > nums[mid], search right half β†’ low = mid + 1Else search left half β†’ high = mid - 1If loop ends, return -1πŸ’» Your Java Code ExplainedHere is your implementation:class Solution {public int search(int[] nums, int target) {int high = nums.length-1;int low = 0;while(low <= high){int mid = low+(high-low)/2;if(target == nums[mid] ){return mid;}else if(target > nums[mid]){low = mid+1;}else{high = mid-1;}}return -1;}}πŸ” Code Breakdown1️⃣ Initialize Boundariesint high = nums.length - 1;int low = 0;You define the search space from index 0 to n-1.2️⃣ Loop Conditionwhile(low <= high)The loop continues as long as there is a valid search range.3️⃣ Safe Mid Calculationint mid = low + (high - low) / 2;This is preferred over:(low + high) / 2Why?Because (low + high) may cause integer overflow in large arrays.Your approach prevents that.4️⃣ Comparison Logicif(target == nums[mid])If found β†’ return index.else if(target > nums[mid])low = mid + 1;Search in right half.elsehigh = mid - 1;Search in left half.5️⃣ Not Found Casereturn -1;If the loop finishes without finding the target.⏱ Time and Space ComplexityTime Complexity: O(log n)Each iteration halves the search space.Space Complexity: O(1)No extra space used β€” purely iterative.πŸ”₯ Why This Problem Is ImportantLeetCode 704 is:The foundation of all Binary Search problemsA template questionFrequently asked in interviewsRequired to understand advanced problems like:Search in Rotated Sorted ArrayFind First and Last PositionPeak ElementBinary Search on AnswerπŸ“š Recommended Binary Search Practice ProblemsAfter solving this, practice these in order:🟒 Easy35. Search Insert Position69. Sqrt(x)278. First Bad Version🟑 Medium34. Find First and Last Position of Element in Sorted Array33. Search in Rotated Sorted Array74. Search a 2D Matrix875. Koko Eating Bananas (Binary Search on Answer)πŸ”΄ Advanced Pattern Practice1011. Capacity To Ship Packages Within D Days410. Split Array Largest SumThese will help you master:Lower bound / upper boundBinary search on monotonic functionsSearching in rotated arraysSearching in 2D matricesBinary search on answer pattern🎯 Final ThoughtsBinary Search is not just a single algorithm β€” it’s a pattern.If you truly understand:How the search space shrinksWhen to move left vs rightHow to calculate mid safelyLoop conditions (low <= high vs low < high)You can solve 50+ interview problems easily.LeetCode 704 is the perfect starting point.Master this template, and you unlock an entire category of problems.

Binary SearchLeetCodeEasy
Floor in a Sorted Array – Binary Search Explained with Story & Visuals | GeeksforGeeks

Floor in a Sorted Array – Binary Search Explained with Story & Visuals | GeeksforGeeks

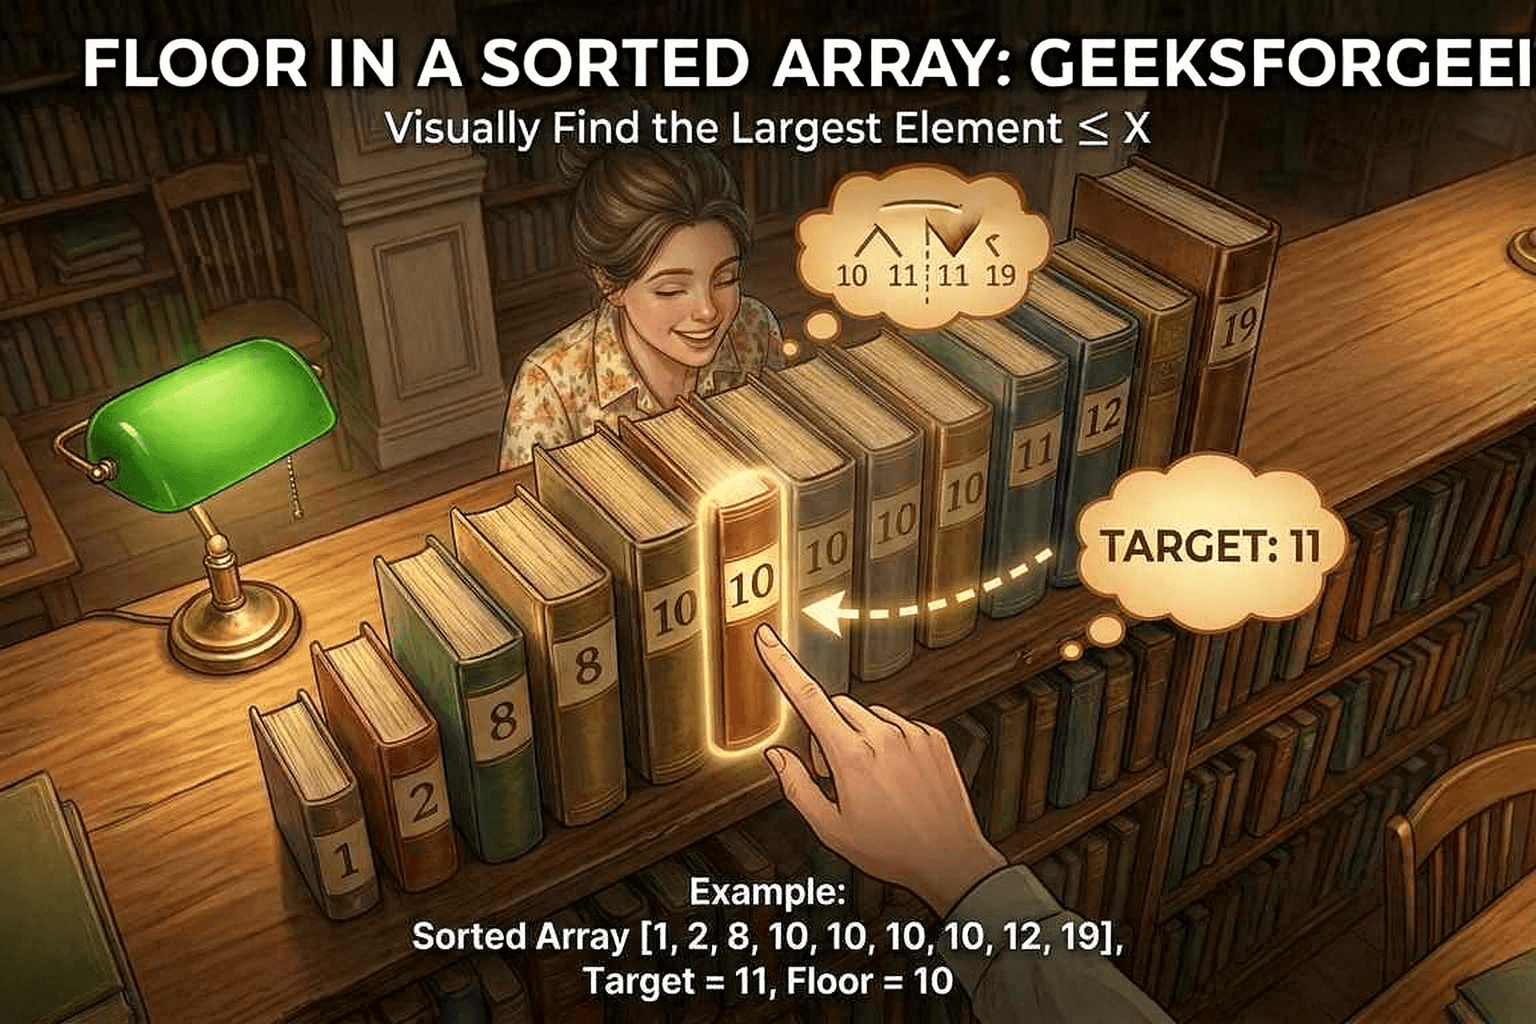
Problem StatementPlatform: GeeksforGeeksYou are given a sorted array arr[] and an integer x. Your task is to find the index of the largest element in the array that is less than or equal to x.Return -1 if no such element exists.If multiple elements equal the floor, return the last occurrence.Example:Input: arr = [1, 2, 8, 10, 10, 12, 19], x = 11Output: 4βœ… The largest element ≀ 11 is 10. The last occurrence is at index 4.πŸ‘‰ Try this problem here: GeeksforGeeks – Floor in a Sorted ArrayIntuition: What is β€œFloor” and Why It MattersImagine climbing stairs:You want to step as high as possible without going past a certain height.That step is your floor – the largest number ≀ x.In arrays:The floor of x is the largest number smaller than or equal to x.Because the array is sorted, we can search efficiently with binary search instead of checking every element.This is faster and helps you handle large arrays with millions of elements.Multiple Approaches1️⃣ Linear Search (Easy but Slow)Check each element from left to right. If it’s ≀ x, update the answer.int ans = -1;for(int i = 0; i < arr.length; i++){if(arr[i] <= x){ans = i; // store last occurrence}}return ans;Time Complexity: O(n) – slow for large arraysSpace Complexity: O(1) – constant memory2️⃣ Binary Search (Fast & Efficient)Binary search cuts the search space in half at every step.int ans = -1;int low = 0, high = arr.length - 1;while(low <= high){int mid = low + (high - low)/2;if(arr[mid] == x){ans = mid; // candidate floorlow = mid + 1; // move right for last occurrence} else if(arr[mid] < x){ans = mid; // candidate floorlow = mid + 1;} else {high = mid - 1; // too large, move left}}return ans;Time Complexity: O(log n) – very fastSpace Complexity: O(1) – no extra spaceDry Run / Step-by-StepInput: arr = [1, 2, 8, 10, 10, 12, 19], x = 11Steplowhighmidarr[mid]ansAction1063103arr[mid] < x β†’ move right2465123arr[mid] > x β†’ move left3444104arr[mid] < x β†’ move right454--4low > high β†’ stop, return 4βœ… Finds floor = 10 at index 4.Code Explanation in Simple Wordsans = -1 β†’ stores best candidate for floor.Use low and high as binary search boundaries.mid = low + (high - low)/2 β†’ safe midpoint.If arr[mid] <= x, it can be the floor β†’ move right to find last occurrence.If arr[mid] > x, move left β†’ floor is smaller.Loop ends when low > high, return ans.Edge Cases to Rememberx < arr[0] β†’ return -1 (floor doesn’t exist)x β‰₯ arr[n-1] β†’ return last index (floor is last element)Duplicates β†’ always return last occurrenceStory-Based Visual Example: β€œAlice’s Book Shelf Adventure” πŸ“šScenario:Alice is a librarian.Books are arranged by height on a shelf.She has a new book and wants to place it next to the tallest book shorter than or equal to hers.Instead of checking each book, she uses a binary search approach to find the position quickly."Alice is scanning the bookshelf, which represents a sorted array: [1, 2, 8, 10, 10, 12, 19]. She is thinking where to place her new book labeled 11. This step represents the initial step of the floor algorithm, understanding the array elements.""Alice places the book labeled 11 right after the last 10 on the shelf. This demonstrates finding the floor: the largest number ≀ 11 is 10, and the book is positioned next to it, illustrating the last occurrence logic.""From a top view, Alice is scanning all the books. This shows how binary search would conceptually divide the array: she quickly decides which section the book 11 belongs to without checking every book, demonstrating efficient search.""Alice has successfully placed the book 11 at the correct position. The floor of 11 is 10 (index 4). This visual confirms the algorithm’s result: the new element is positioned immediately after the last element ≀ x, exactly as binary search would determine."Why This Problem is ImportantStrengthens binary search skillsTeaches last occurrence / boundary conditions handlingMakes you think algorithmically, not just about numbersStory-based learning improves retention and understandingConclusionLinear search: easy but slow (O(n))Binary search: fast, elegant (O(log n))Multiple dry run steps make it easy to followStory-based images make abstract concepts concrete and memorable
GeeksforGeeksBinary SearchEasy
Find First and Last Position in Sorted Array – From Brute Force to Binary Search (LeetCode 34)

Find First and Last Position in Sorted Array – From Brute Force to Binary Search (LeetCode 34)

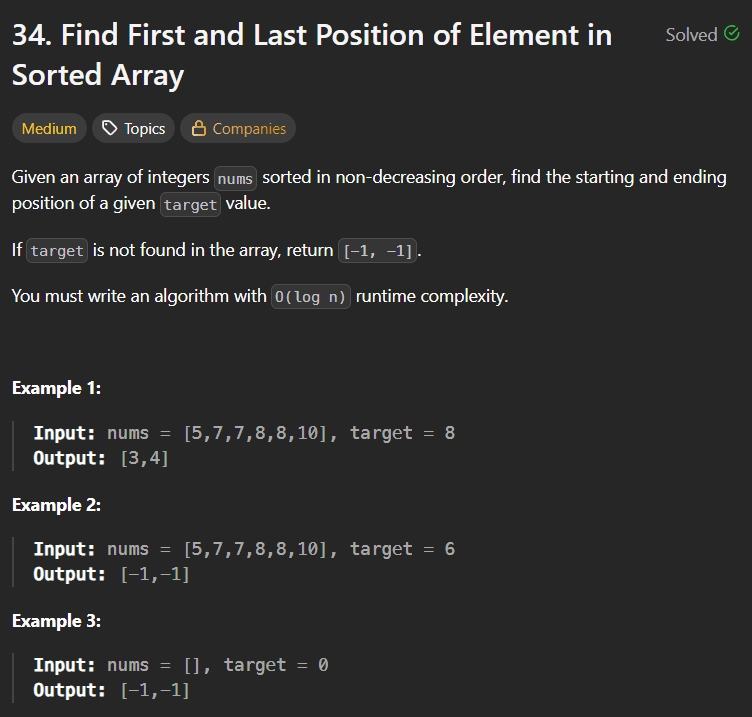
Problem LinkLeetCode 34 – Find First and Last Position of Element in Sorted Array πŸ‘‰ https://leetcode.com/problems/find-first-and-last-position-of-element-in-sorted-array/πŸ“Œ Problem OverviewYou are given a sorted array (non-decreasing order) and a target value.Your task:Return the starting and ending index of the target.If target does not exist β†’ return [-1, -1]Required Time Complexity: O(log n)Example 1Input: nums = [5,7,7,8,8,10], target = 8 Output: [3,4]Example 2Input: nums = [5,7,7,8,8,10], target = 6 Output: [-1,-1]🧠 My First Intuition – Brute Force (O(n))When I first saw this problem, my thinking was simple:"Since the array is sorted, I just need to find the first occurrence and the last occurrence."So I used two loops:One loop from left β†’ to find first occurrenceOne loop from right β†’ to find last occurrenceHere is my submitted solution:class Solution { public int[] searchRange(int[] nums, int t) { int arr[] = new int[2]; arr[0] = -1; arr[1] = -1; for(int i = nums.length-1;i >=0 ;i--){ if(nums[i] == t){ arr[1] = i; break; } } for(int i = 0;i <nums.length ;i++){ if(nums[i] == t){ arr[0] = i; break; } } return arr; }}βœ… Why This WorksSince the array is sorted, occurrences of the same number are grouped together.First loop (reverse) finds last occurrence.Second loop (forward) finds first occurrence.❌ Problem with This ApproachTime Complexity = O(n)Worst case:Target is not presentWe scan entire array twiceBut the problem clearly states:You must write an algorithm with O(log n) runtime complexity.That means: We must use Binary Search.πŸš€ Optimized Approach – Binary Search (O(log n))πŸ’‘ Key IntuitionIf the array is sorted:We can use Binary Search to find the first occurrenceWe can use Binary Search again to find the last occurrenceInstead of stopping when we find the target:For first occurrence β†’ continue searching leftFor last occurrence β†’ continue searching right🧠 Idea Breakdown1️⃣ Find First OccurrenceWhen we find target at mid:Store indexMove left β†’ high = mid - 1Because there might be another occurrence before it2️⃣ Find Last OccurrenceWhen we find target at mid:Store indexMove right β†’ low = mid + 1Because there might be another occurrence after itπŸ’» Optimized Code (Binary Search Approach)class Solution { public int[] searchRange(int[] nums, int target) { int[] result = new int[2]; result[0] = findFirst(nums, target); result[1] = findLast(nums, target); return result; } private int findFirst(int[] nums, int target) { int low = 0, high = nums.length - 1; int index = -1; while (low <= high) { int mid = low + (high - low) / 2; if (nums[mid] == target) { index = mid; high = mid - 1; // move left } else if (nums[mid] < target) { low = mid + 1; } else { high = mid - 1; } } return index; } private int findLast(int[] nums, int target) { int low = 0, high = nums.length - 1; int index = -1; while (low <= high) { int mid = low + (high - low) / 2; if (nums[mid] == target) { index = mid; low = mid + 1; // move right } else if (nums[mid] < target) { low = mid + 1; } else { high = mid - 1; } } return index; }}πŸ” Why This WorksBinary Search normally stops when target is found.Here, we modify it slightly:Keep searching even after finding target.Narrow the search space toward the boundary we want.This guarantees:First occurrence β†’ leftmost indexLast occurrence β†’ rightmost index⏱ Complexity AnalysisBrute Force ApproachTime: O(n)Space: O(1)Binary Search ApproachTime: O(log n)Space: O(1)This satisfies the problem constraint.🎯 Key Learning from This ProblemThis problem teaches an important pattern:When array is sorted and you need boundaries β†’ Think Binary Search.It is not just about finding the element.It is about finding:First occurrence (Lower Bound)Last occurrence (Upper Bound)This pattern appears in many interview problems.πŸ“š Similar Problems to Practicehttps://leetcode.com/problems/binary-search/https://leetcode.com/problems/search-insert-position/https://leetcode.com/problems/search-in-rotated-sorted-array/https://leetcode.com/problems/find-minimum-in-rotated-sorted-array/https://leetcode.com/problems/sqrtx/🏁 Final ThoughtsMy journey solving this problem:First thought β†’ Use two loops (works but O(n))Then realized constraint β†’ Must be O(log n)Optimized using two Binary SearchesThis is how problem solving improves:Start with correct solution.Then optimize.Then recognize patterns.LeetCode 34 is one of the most important Binary Search boundary problems.If you master this, you unlock an entire category of advanced Binary Search questions.

Binary SearchLeetCodeMedium
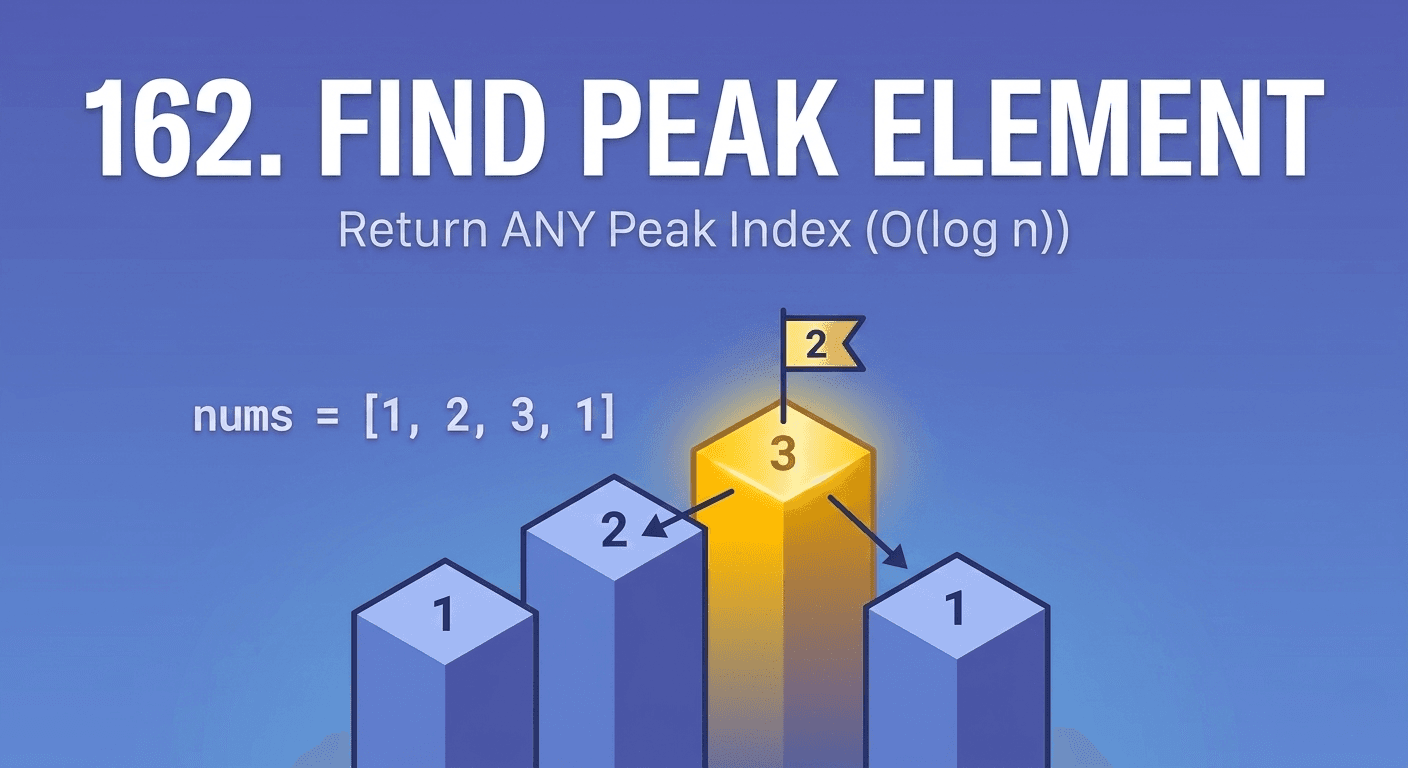
Peak Index in a Mountain Array – Brute Force to Binary Search (LeetCode 852)

Peak Index in a Mountain Array – Brute Force to Binary Search (LeetCode 852)

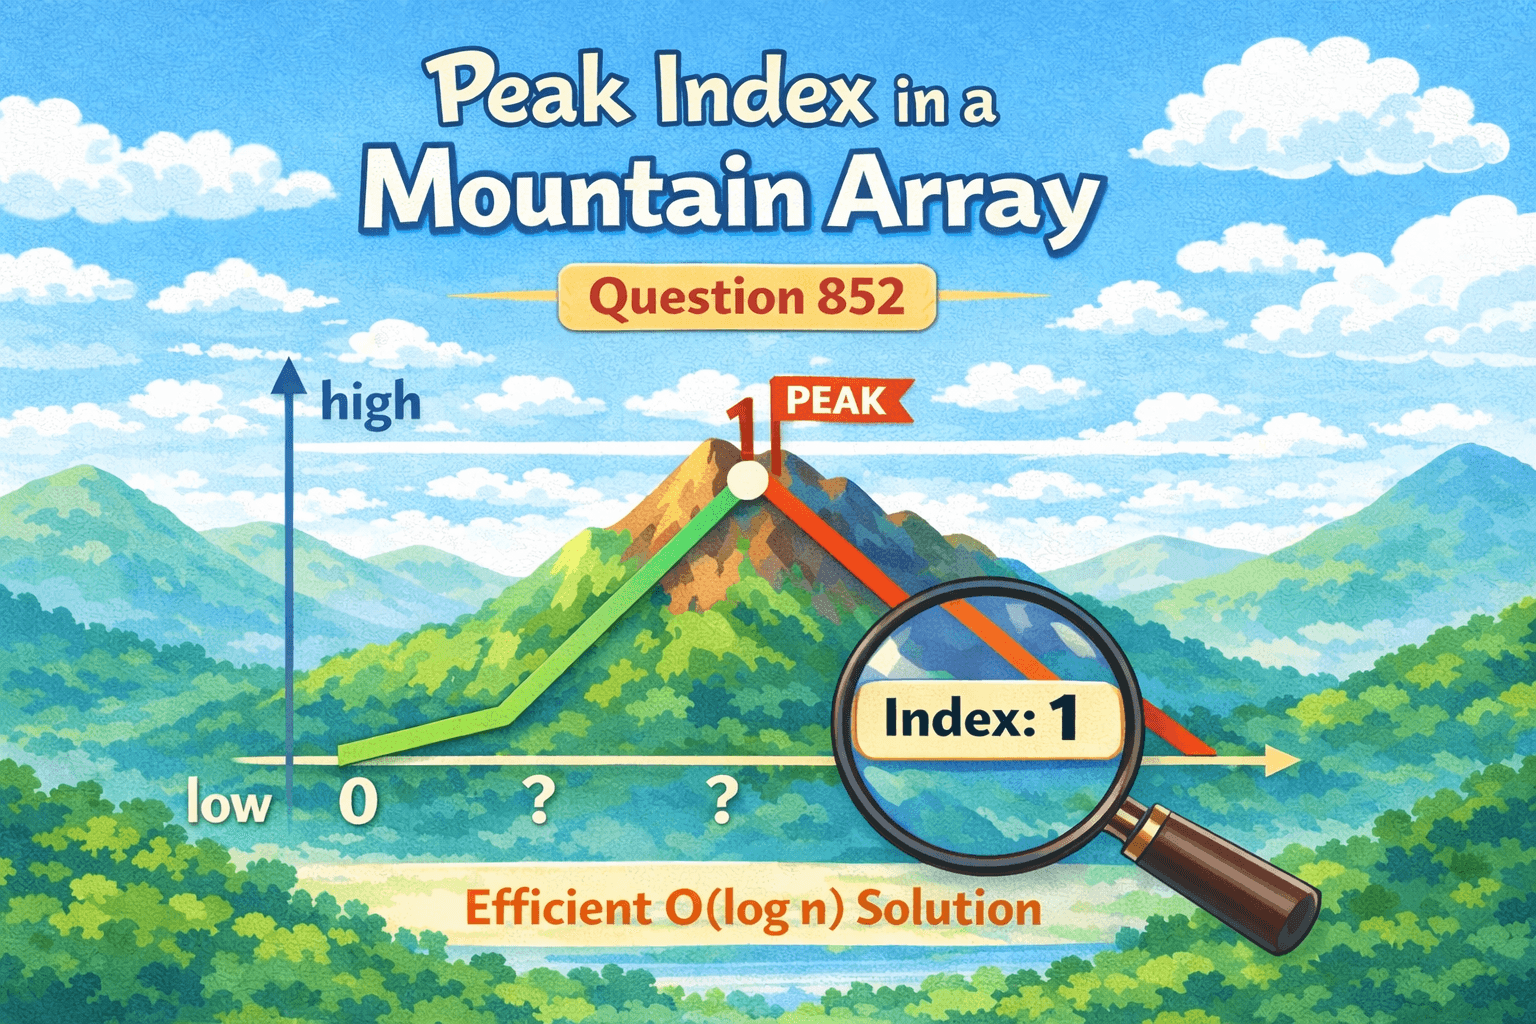
Try the QuestionBefore reading the explanation, try solving the problem yourself:πŸ‘‰ https://leetcode.com/problems/peak-index-in-a-mountain-array/Solving it first helps strengthen your problem-solving intuition, especially for binary search problems.Problem StatementYou are given an integer array arr that is guaranteed to be a mountain array.A mountain array is defined as an array where:Elements strictly increase until a peak element.After the peak, elements strictly decrease.Example:[0, 2, 5, 7, 6, 3, 1] ^ peakYour task is to return the index of the peak element.Constraints3 <= arr.length <= 10^50 <= arr[i] <= 10^6arr is guaranteed to be a mountain arrayImportant implications:The peak always exists.There will be exactly one peak.The array strictly increases before the peak and strictly decreases after it.Example WalkthroughExample 1Inputarr = [0,1,0]Visualization0 1 0 ^Output1Example 2Inputarr = [0,2,1,0]Visualization0 2 1 0 ^Output1Example 3Inputarr = [0,10,5,2]Visualization0 10 5 2 ^Output1Understanding the Mountain Array StructureA mountain array always looks like this:increasing β†’ peak β†’ decreasingGraphically: peak /\ / \ / \Because of this structure:Before the peak β†’ numbers increaseAfter the peak β†’ numbers decreaseThis property makes the problem perfect for binary search.Approach 1 β€” Brute Force (Check Every Element)The simplest way is to check every element and determine if it is greater than its neighbors.AlgorithmTraverse the array from index 1 to n-2.For each element check:arr[i] > arr[i-1] AND arr[i] > arr[i+1]If true, return i.Implementationpublic int peakIndexInMountainArray(int[] arr) { for(int i = 1; i < arr.length - 1; i++){ if(arr[i] > arr[i-1] && arr[i] > arr[i+1]){ return i; } } return -1;}Time ComplexityO(n)We may need to check every element.Space ComplexityO(1)Approach 2 β€” Linear Scan Using Increasing TrendSince the array first increases then decreases, we can detect where the increase stops.Key IdeaTraverse the array and check when:arr[i] > arr[i+1]This means we reached the peak.Implementationpublic int peakIndexInMountainArray(int[] arr) { for(int i = 0; i < arr.length - 1; i++){ if(arr[i] > arr[i+1]){ return i; } } return -1;}Example0 2 5 7 6 3 1 ^At index 3:7 > 6So index 3 is the peak.Time ComplexityO(n)Space ComplexityO(1)Approach 3 β€” Modified Binary Search (Optimal Solution)Because the array has a mountain structure, binary search can be used.Core IntuitionCompare:arr[mid]arr[mid+1]Two situations are possible.Case 1 β€” Increasing Slopearr[mid] < arr[mid+1]Example:1 3 5 7 ^This means the peak is on the right side.Move the search space to the right.left = mid + 1Case 2 β€” Decreasing Slopearr[mid] > arr[mid+1]Example:7 5 3 1 ^This means the peak lies on the left side including mid.right = midOptimal Java Implementationclass Solution { public int peakIndexInMountainArray(int[] arr) { int i = 0; int j = arr.length - 1; while(i < j){ int mid = i + (j - i) / 2; if(arr[mid] < arr[mid + 1]){ i = mid + 1; } else{ j = mid; } } return i; }}Step-by-Step ExampleArray[0,2,5,7,6,3,1]Iteration 1mid = 3arr[mid] = 7arr[mid+1] = 6Decreasing slope β†’ move left.Iteration 2Search space narrows until:peak index = 3Time ComplexityO(log n)Binary search halves the search space each iteration.Space ComplexityO(1)No extra memory is required.Why Binary Search Works HereBecause the array behaves like a mountain curve.If you are standing at index mid:If the right side is higher, go right.If the left side is higher, go left.Eventually you will reach the top of the mountain (the peak).Key Takeawaysβœ” A mountain array increases then decreasesβœ” There is exactly one peakβœ” Brute force and linear scan work in O(n) timeβœ” Binary search exploits the mountain structureβœ” Optimal solution runs in O(log n) timeFinal ThoughtsThis problem is a classic example of binary search applied to array patterns rather than sorted values.Understanding the slope comparison technique used here will help solve other problems such as:Find Peak ElementMountain Array SearchBitonic Array ProblemsMastering these patterns significantly improves binary search problem-solving skills for coding interviews.

LeetCodeBinary SearchMountain ArrayMediumJava
LeetCode 2089: Find Target Indices After Sorting Array – Java Solution & Explanation

LeetCode 2089: Find Target Indices After Sorting Array – Java Solution & Explanation

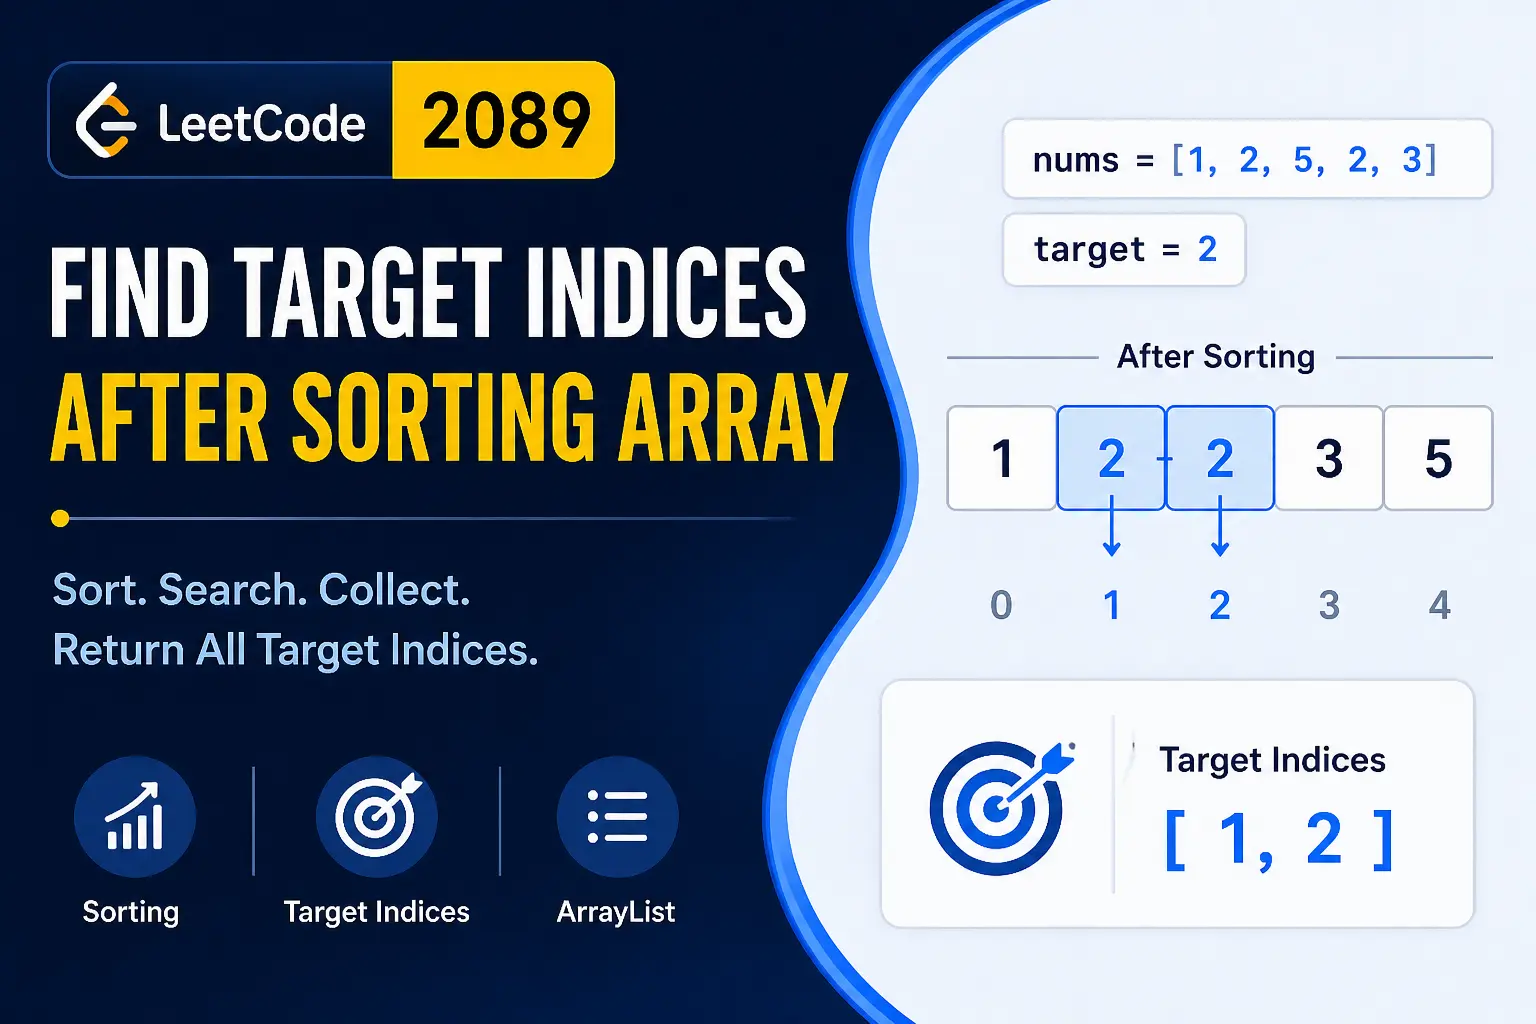
IntroductionFinding an element in an array is a common programming task, but what happens when the required answer is not the element itself, but every position where it appears after sorting?In LeetCode 2089 – Find Target Indices After Sorting Array, the array must first be arranged in non-decreasing order. After sorting, the goal is to return the indices where the specified target value appears. If the target occurs multiple times, every matching index must be included in the result.The solution is straightforward: sort the array, scan it from left to right, and store each index whose value matches the target. Because the array is already sorted, the collected indices naturally appear in increasing order.Problem StatementGiven a zero-indexed integer array nums and an integer target, return a list containing all indices i such that nums[i] == target after sorting nums in non-decreasing order.If the target does not appear in the array, return an empty list.Problem link: LeetCode 2089 – Find Target Indices After Sorting ArrayExample 1Input: nums = [1, 2, 5, 2, 3]target = 2Output: [1, 2]After sorting, the array becomes:[1, 2, 2, 3, 5]The target 2 appears at indices 1 and 2, so the result is [1, 2].Example 2Input: nums = [1, 2, 5, 2, 3]target = 3Output: [3]After sorting, the value 3 appears at index 3.Example 3Input: nums = [1, 2, 5, 2, 3]target = 5Output: [4]The largest value, 5, appears at index 4 after sorting.Approach: Sort the Array and Find Matching IndicesThe main observation is that the target's position can change when the array is sorted. Therefore, checking the original array without sorting would not necessarily return the required indices.The solution uses two simple steps.Step 1: Sort the arrayArrays.sort(nums);Java's Arrays.sort() arranges the integers in ascending order. Equal values become adjacent, making it easy to identify every occurrence of the target.Step 2: Traverse the sorted arrayfor (int i = 0; i < nums.length; i++) { if (nums[i] == target) { lis.add(i); }}The loop checks every position. Whenever the current value equals target, its index is added to the result list.Since the traversal moves from index 0 toward the end of the array, the resulting indices are automatically in increasing order. There is no need to sort the result list separately.Java SolutionThe following implementation uses the submitted approach with Arrays.sort() and an ArrayList to collect the matching indices.class Solution { public List<Integer> targetIndices(int[] nums, int target) { Arrays.sort(nums); List<Integer> lis = new ArrayList<>(); for (int i = 0; i < nums.length; i++) { if (nums[i] == target) { lis.add(i); } } return lis; }}Step-by-Step Dry RunConsider the following input:nums = [1, 2, 5, 2, 3]target = 21. Sort the arrayAfter calling Arrays.sort(nums), the array becomes:Index: 0 1 2 3 4Value: [1, 2, 2, 3, 5]The result list is initially empty:lis = []2. Check each indexIndex inums[i]Matches target?Result list01No[]12Yes[1]22Yes[1, 2]33No[1, 2]45No[1, 2]Both occurrences of 2 are collected.The final result is:[1, 2]What If the Target Is Missing?Suppose the sorted array is:[1, 2, 2, 3, 5]and the target is 4.No element matches the target, so the loop never adds an index to the list. The method returns:[]This also handles the case where the target appears only once or appears multiple times.Complexity AnalysisLet n be the number of elements in the array.Time complexity: O(n log n)Sorting the array takes O(n log n) time.Traversing the array takes O(n) time.Sorting dominates the overall time complexity, making the total O(n log n).Auxiliary space: The result list requires O(k) space, where k is the number of target occurrences. Java's sorting implementation may also use additional internal space.Interview TipWhen a problem asks for indices after sorting, first determine whether the positions refer to the original array or the sorted array. In this problem, the indices belong to the sorted array.Also, repeated target values must all be included. A solution that returns immediately after finding the first match would fail when the target occurs more than once.For this implementation, a full traversal is simple and reliable. Because equal values are grouped together after sorting, a binary-search-based solution could also identify the target's first and last positions, although that additional complexity is unnecessary for the given constraints.ConclusionLeetCode 2089 is a useful exercise in sorting, array traversal, and handling duplicate values. By sorting the array first and collecting every index where nums[i] == target, the solution produces the required result without needing additional index-ordering logic.The key takeaway is to perform operations in the order required by the problem: sort first, then find and return all matching indices.

LeetCodeJavaArraysSortingLinear SearchDSAEasy
Search in Rotated Sorted Array II – Binary Search with Duplicates Explained (LeetCode 81)

Search in Rotated Sorted Array II – Binary Search with Duplicates Explained (LeetCode 81)

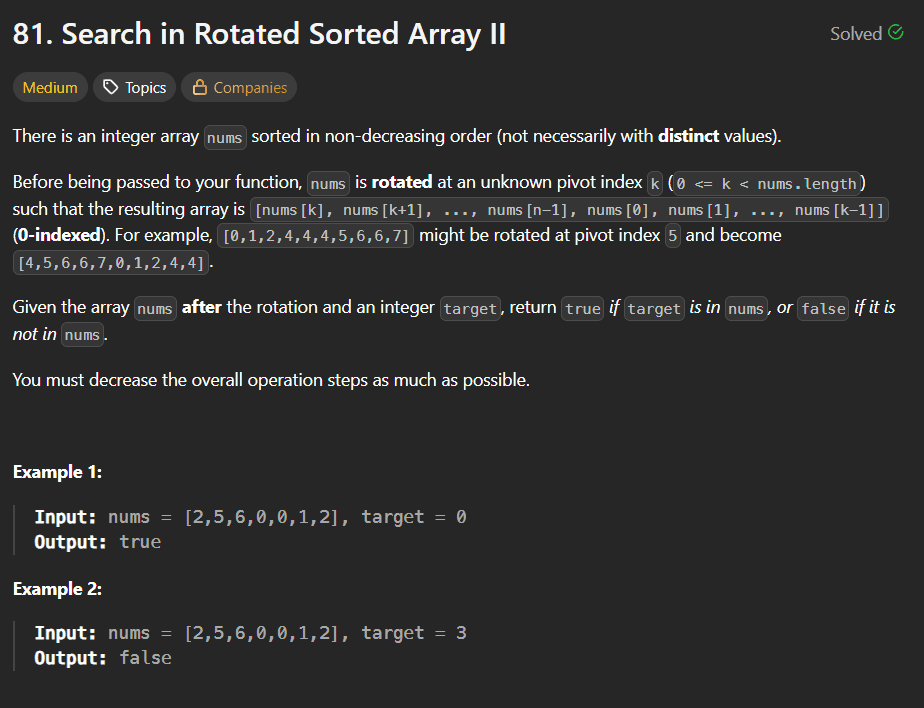
Try the QuestionBefore reading the explanation, try solving the problem yourself:πŸ‘‰ https://leetcode.com/problems/search-in-rotated-sorted-array-ii/Practicing the problem first helps develop stronger problem-solving intuition, especially for binary search variations.Problem StatementYou are given an integer array nums that is sorted in non-decreasing order.Example of a sorted array:[0,1,2,4,4,4,5,6,6,7]Before being passed to your function, the array may be rotated at some pivot index k.After rotation, the structure becomes:[nums[k], nums[k+1], ..., nums[n-1], nums[0], nums[1], ..., nums[k-1]]Example:Original array[0,1,2,4,4,4,5,6,6,7]Rotated at index 5[4,5,6,6,7,0,1,2,4,4]You are also given an integer target.Your task is to determine:Return true if the target exists in the arrayReturn false if the target does not existThe goal is to minimize the number of operations, which suggests using Binary Search.Example WalkthroughExample 1Inputnums = [2,5,6,0,0,1,2]target = 0OutputtrueExplanation:0 exists in the arrayExample 2Inputnums = [2,5,6,0,0,1,2]target = 3OutputfalseExplanation:3 does not exist in the arrayUnderstanding the Core ChallengeThis problem is very similar to the classic problem:Search in Rotated Sorted Array (LeetCode 33).However, there is an important difference.Difference Between the Two ProblemsProblemArray ValuesRotated Sorted ArrayAll elements are distinctRotated Sorted Array IIArray may contain duplicatesDuplicates introduce ambiguity during binary search.Why Duplicates Make the Problem HarderIn the previous problem, we relied on this rule:If nums[left] <= nums[mid]β†’ left half is sortedBut duplicates can break this assumption.Example:nums = [1,0,1,1,1]If:left = 0mid = 2right = 4Then:nums[left] = 1nums[mid] = 1nums[right] = 1Here we cannot determine which half is sorted.This is the main complication introduced by duplicates.Key Idea to Handle DuplicatesWhen the values at left, mid, and right are the same, the algorithm cannot decide which half is sorted.To resolve this situation, we shrink the search space:left++right--This gradually removes duplicate values and allows binary search to continue.Modified Binary Search StrategyThe algorithm works as follows:Step 1Calculate the middle index.Step 2If the middle element equals the target:return trueStep 3If duplicates block decision-making:nums[left] == nums[mid] == nums[right]Then move both pointers inward:left++right--Step 4Otherwise, determine which half is sorted and apply normal binary search logic.Java Implementationclass Solution { public boolean search(int[] nums, int target) { int l = 0; int r = nums.length - 1; while (l <= r) { int mid = l + (r - l) / 2; if (nums[mid] == target) return true; // Handle duplicates if (nums[l] == nums[mid] && nums[mid] == nums[r]) { l++; r--; } // Left half sorted else if (nums[l] <= nums[mid]) { if (nums[l] <= target && target < nums[mid]) { r = mid - 1; } else { l = mid + 1; } } // Right half sorted else { if (nums[mid] < target && target <= nums[r]) { l = mid + 1; } else { r = mid - 1; } } } return false; }}Step-by-Step ExampleArray:[2,5,6,0,0,1,2]target = 0Iteration 1mid = 6value = 0Target found immediately.return trueTime ComplexityBest CaseO(log n)When duplicates do not interfere with binary search decisions.Worst CaseO(n)When many duplicate values force the algorithm to shrink the search space one element at a time.Example worst case:[1,1,1,1,1,1,1,1,1]Binary search cannot divide the array effectively.Space ComplexityO(1)The algorithm only uses a few variables and does not require extra memory.Follow-Up: How Do Duplicates Affect Runtime?Without duplicates, binary search always reduces the search space by half.Time Complexity β†’ O(log n)With duplicates, we sometimes cannot determine which half is sorted.In such cases, we shrink the search space linearly:left++right--This may degrade performance to:Worst Case β†’ O(n)However, in most practical cases the algorithm still performs close to logarithmic time.Key Takeawaysβœ” The array is sorted but rotatedβœ” Duplicates introduce ambiguity in binary searchβœ” Special handling is required when nums[left] == nums[mid] == nums[right]βœ” The algorithm combines binary search with duplicate handlingβœ” Worst-case complexity may degrade to O(n)Final ThoughtsThis problem is a natural extension of the rotated sorted array search problem. It tests your ability to adapt binary search to more complex conditions.Understanding this pattern is valuable because similar techniques appear in many interview problems involving:Rotated arraysBinary search edge casesHandling duplicates in sorted data structuresMastering this approach strengthens both algorithmic thinking and interview preparation.

LeetCodeBinary SearchRotated Sorted ArrayJavaMedium
LeetCode 154: Find Minimum in Rotated Sorted Array II – Java Binary Search Solution Explained

LeetCode 154: Find Minimum in Rotated Sorted Array II – Java Binary Search Solution Explained

IntroductionLeetCode 154 – Find Minimum in Rotated Sorted Array II is a classic binary search interview problem.This problem is an advanced version of:Find Minimum in Rotated Sorted ArrayThe major difference is:The array may contain duplicates.That small change makes the problem much harder because duplicates can break normal binary search logic.This problem teaches:Modified binary searchRotated array conceptsHandling duplicatesEdge case optimizationInterview problem-solving techniquesProblem LinkπŸ”— ProblemLeetCode 154: Find Minimum in Rotated Sorted Array IIOfficial Problem: LeetCode Problem LinkProblem StatementAn ascending sorted array is rotated between 1 and n times.Example:[0,1,4,4,5,6,7]may become:[4,5,6,7,0,1,4]or[0,1,4,4,5,6,7]Given the rotated sorted array nums that may contain duplicates, return the minimum element.ExampleExample 1Input:nums = [1,3,5]Output:1Example 2Input:nums = [2,2,2,0,1]Output:0Understanding Rotated Sorted ArraysNormally a sorted array looks like:[1,2,3,4,5]After rotation:[4,5,1,2,3]The minimum element becomes the pivot point.Our goal is to efficiently find this pivot.Brute Force ApproachIntuitionTraverse the entire array and keep track of the smallest element.AlgorithmInitialize minimum as first element.Traverse the array.Update minimum whenever a smaller element appears.Return minimum.Java Code – Brute Forceclass Solution { public int findMin(int[] nums) { int min = nums[0]; for(int num : nums) { min = Math.min(min, num); } return min; }}Dry Run – Brute ForceInput:[2,2,2,0,1]Traversal:ElementMinimum2222220010Final answer:0Complexity Analysis – Brute ForceTime ComplexityO(N)Space ComplexityO(1)Can We Do Better?Yes.Since the array is sorted and rotated, we can use Binary Search.However, duplicates make the problem tricky.Binary Search IntuitionIn a rotated sorted array:One half is always sorted.The minimum lies in the unsorted half.Without duplicates, binary search becomes straightforward.But duplicates create ambiguity.Example:[2,2,2,0,2]If:nums[mid] == nums[right]we cannot determine which side contains the minimum.So we shrink the search space carefully.Key Binary Search ObservationsCase 1If:nums[mid]<nums[right]nums[mid] < nums[right]nums[mid]<nums[right]then the right half is sorted, and minimum may lie at mid or left side.Move:right = midCase 2If:nums[mid]>nums[right]nums[mid] > nums[right]nums[mid]>nums[right]then minimum lies in the right half.Move:left = mid + 1Case 3If:nums[mid]=nums[right]nums[mid] = nums[right]nums[mid]=nums[right]we cannot identify the correct side.Safely reduce search space:right--Optimized Binary Search ApproachStepsInitialize two pointers:leftrightFind middle element.Compare nums[mid] with nums[right].Narrow the search space accordingly.Continue until pointers meet.Java Binary Search Solutionclass Solution { public int findMin(int[] nums) { if(nums.length == 1) return nums[0]; int left = 0; int right = nums.length - 1; int min = Integer.MAX_VALUE; while(left <= right) { int mid = left + (right - left) / 2; if(nums[mid] < nums[right]) { right = mid; min = Math.min(min, nums[right]); } else if(nums[mid] > nums[right]) { min = Math.min(min, nums[right]); left = mid + 1; } else { right--; } min = Math.min(min, nums[mid]); } return min; }}Dry Run – Binary SearchInputnums = [2,2,2,0,1]Initial StateLeftRight04Iteration 1Midmid = 2Value:nums[mid] = 2nums[right] = 1Since:2>12 > 12>1Move:left = mid + 1Now:LeftRight34Iteration 2Midmid = 3Value:nums[mid] = 0nums[right] = 1Since:0<10 < 10<1Move:right = midNow:LeftRight33Final Answer0Time Complexity AnalysisAverage CaseO(log N)Worst CaseDue to duplicates:O(N)Why Worst Case Becomes O(N)Consider:[1,1,1,1,1]Every comparison becomes:nums[mid] == nums[right]We can only shrink by one element:right--This degrades binary search to linear complexity.Interview ExplanationIn interviews, explain:Duplicates destroy the ability to always determine the sorted half uniquely. When nums[mid] == nums[right], we cannot confidently eliminate one side, so we reduce the search space by one element.This is the key insight interviewers look for.Common Mistakes1. Using Standard Binary Search LogicStandard rotated-array logic fails with duplicates.2. Ignoring Duplicate CaseThis condition is essential:else { right--;}3. Infinite Loop ErrorsAlways update pointers carefully.Alternative Simpler Binary SearchA cleaner version:class Solution { public int findMin(int[] nums) { int left = 0; int right = nums.length - 1; while(left < right) { int mid = left + (right - left) / 2; if(nums[mid] < nums[right]) { right = mid; } else if(nums[mid] > nums[right]) { left = mid + 1; } else { right--; } } return nums[left]; }}This is the most common interview solution.FAQsQ1. Why does binary search become O(N)?Duplicates prevent us from discarding half the search space confidently.Q2. Why compare with nums[right]?It helps identify whether the minimum lies on the left or right side.Q3. Is this problem important for interviews?Yes.It is a very popular advanced binary search interview problem.ConclusionLeetCode 154 is an excellent problem for mastering:Modified binary searchRotated sorted arraysDuplicate handlingSearch optimizationThe key challenge is handling:nums[mid]=nums[right]nums[mid] = nums[right]nums[mid]=nums[right]correctly.Once you understand this pattern, many advanced binary search interview problems become much easier.

HardBinary SearchRotated Sorted ArrayJavaLeetCode
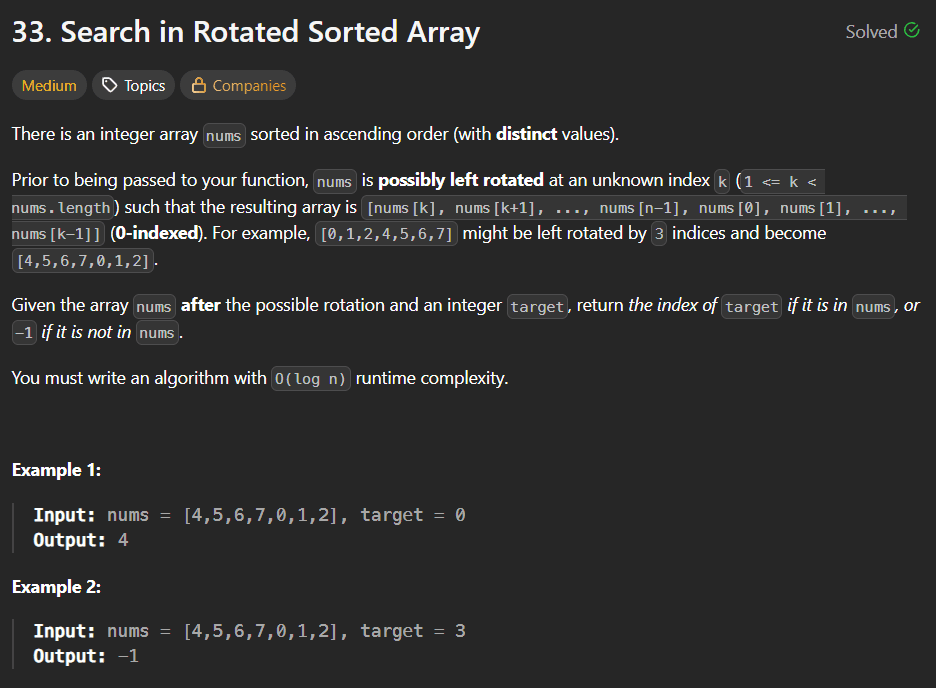
Search in Rotated Sorted Array – Binary Search Explained with Java Solution (LeetCode 33)

Search in Rotated Sorted Array – Binary Search Explained with Java Solution (LeetCode 33)

Try the QuestionBefore reading the solution, try solving the problem yourself:πŸ‘‰ https://leetcode.com/problems/search-in-rotated-sorted-array/Attempting the problem first helps build strong algorithmic intuition, which is extremely valuable during coding interviews.Problem StatementYou are given an integer array nums that was originally sorted in ascending order with distinct elements.Example of a sorted array:[0,1,2,4,5,6,7]Before the array is provided to the function, it may have been rotated at some pivot index k.After rotation, the array structure becomes:[nums[k], nums[k+1], ..., nums[n-1], nums[0], nums[1], ..., nums[k-1]]For example:Original Array[0,1,2,4,5,6,7]Rotated by 3 positions[4,5,6,7,0,1,2]You are also given an integer target.The goal is to return the index of the target element in the array.If the element does not exist, return:-1Important ConstraintThe algorithm must run in O(log n) time complexity, which strongly suggests using Binary Search.Example WalkthroughExample 1Inputnums = [4,5,6,7,0,1,2]target = 0Output4Explanation:0 exists at index 4Example 2Inputnums = [4,5,6,7,0,1,2]target = 3Output-1Explanation:3 does not exist in the arrayExample 3Inputnums = [1]target = 0Output-1Understanding the Core ChallengeIf the array were fully sorted, the problem would be straightforward because binary search could directly be applied.Example:[1,2,3,4,5,6,7]However, due to rotation:[4,5,6,7,0,1,2]the array is no longer globally sorted.But an important observation makes the problem solvable.Key ObservationEven after rotation:At least one half of the array is always sorted.For example:[4,5,6,7,0,1,2] Left part β†’ sorted Right part β†’ sortedThis property allows the use of binary search with additional conditions.Approach 1 β€” Linear Scan (Brute Force)The simplest method is to iterate through the entire array and check each element.AlgorithmTraverse the array from start to end.Compare every element with the target.Return the index if found.Codefor(int i = 0; i < nums.length; i++){ if(nums[i] == target){ return i; }}return -1;Time ComplexityO(n)Space ComplexityO(1)Although simple, this solution does not satisfy the required O(log n) complexity.Approach 2 β€” Modified Binary SearchA better solution uses binary search with sorted half detection.IdeaAt every step:Calculate the middle index.Determine which half of the array is sorted.Check if the target lies inside that sorted half.Adjust the search range accordingly.Implementationpublic int search(int[] nums, int target) { int l = 0; int r = nums.length - 1; while(l <= r){ int mid = l + (r - l) / 2; if(nums[mid] == target){ return mid; } // left half sorted if(nums[l] <= nums[mid]){ if(nums[l] <= target && target < nums[mid]){ r = mid - 1; }else{ l = mid + 1; } } // right half sorted else{ if(nums[mid] < target && target <= nums[r]){ l = mid + 1; }else{ r = mid - 1; } } } return -1;}Time ComplexityO(log n)Space ComplexityO(1)This is the most common interview solution.Approach 3 β€” Find Rotation Point Then Apply Binary SearchAnother elegant strategy is to first locate the minimum element in the rotated array, which represents the rotation index (pivot).Once the pivot is known, the array can be logically split into two sorted subarrays.Example:[4,5,6,7,0,1,2] ^ pivotTwo sorted sections exist:[4,5,6,7][0,1,2]After identifying the pivot:Decide which part may contain the target.Apply standard binary search on that portion.Step 1 β€” Finding the Minimum Element (Rotation Pivot)The smallest element indicates where the rotation happened.Function to Find Minimum Valuepublic int findMinIndex(int[] nums){ int l = 0; int r = nums.length - 1; while(l < r){ int mid = l + (r - l) / 2; if(nums[mid] > nums[r]){ l = mid + 1; }else{ r = mid; } } return l;}Why This WorksIf:nums[mid] > nums[r]the minimum element must be on the right side.Otherwise, it lies on the left side (including mid).Step 2 β€” Standard Binary SearchAfter determining which half contains the target, a normal binary search is applied.public int binarySearch(int[] nums, int l, int r, int target){ while(l <= r){ int mid = l + (r - l) / 2; if(nums[mid] == target){ return mid; } else if(nums[mid] < target){ l = mid + 1; } else{ r = mid - 1; } } return -1;}Complete Solution (Pivot + Binary Search)class Solution { public int findMinIndex(int[] nums){ int l = 0; int r = nums.length - 1; while(l < r){ int mid = l + (r - l) / 2; if(nums[mid] > nums[r]){ l = mid + 1; }else{ r = mid; } } return l; } public int binarySearch(int[] nums, int l, int r, int target){ while(l <= r){ int mid = l + (r - l) / 2; if(nums[mid] == target){ return mid; } else if(nums[mid] < target){ l = mid + 1; } else{ r = mid - 1; } } return -1; } public int search(int[] nums, int target) { int pivot = findMinIndex(nums); if(nums[pivot] <= target && target <= nums[nums.length - 1]){ return binarySearch(nums, pivot, nums.length - 1, target); } return binarySearch(nums, 0, pivot - 1, target); }}Time ComplexityFinding pivot:O(log n)Binary search:O(log n)Total complexity:O(log n)Space ComplexityO(1)No additional memory is used.Key Takeawaysβœ” The array is sorted but rotatedβœ” A rotation creates two sorted sectionsβœ” Binary search can still be appliedβœ” Either detect the sorted half directly or locate the pivot firstβœ” Both optimized approaches achieve O(log n) complexityFinal ThoughtsThis problem is a classic binary search variation frequently asked in coding interviews. It evaluates the ability to:Recognize structural patterns in arraysAdapt binary search to non-standard conditionsMaintain optimal algorithmic complexityUnderstanding this pattern also helps solve related problems such as:Find Minimum in Rotated Sorted ArraySearch in Rotated Sorted Array IIFind Rotation Count in ArrayMastering these concepts significantly strengthens binary search problem-solving skills for technical interviews.

Binary SearchJavaRotated Sorted ArrayLeetCodeMedium
Understanding HashMap and Hashing Techniques: A Complete Guide

Understanding HashMap and Hashing Techniques: A Complete Guide

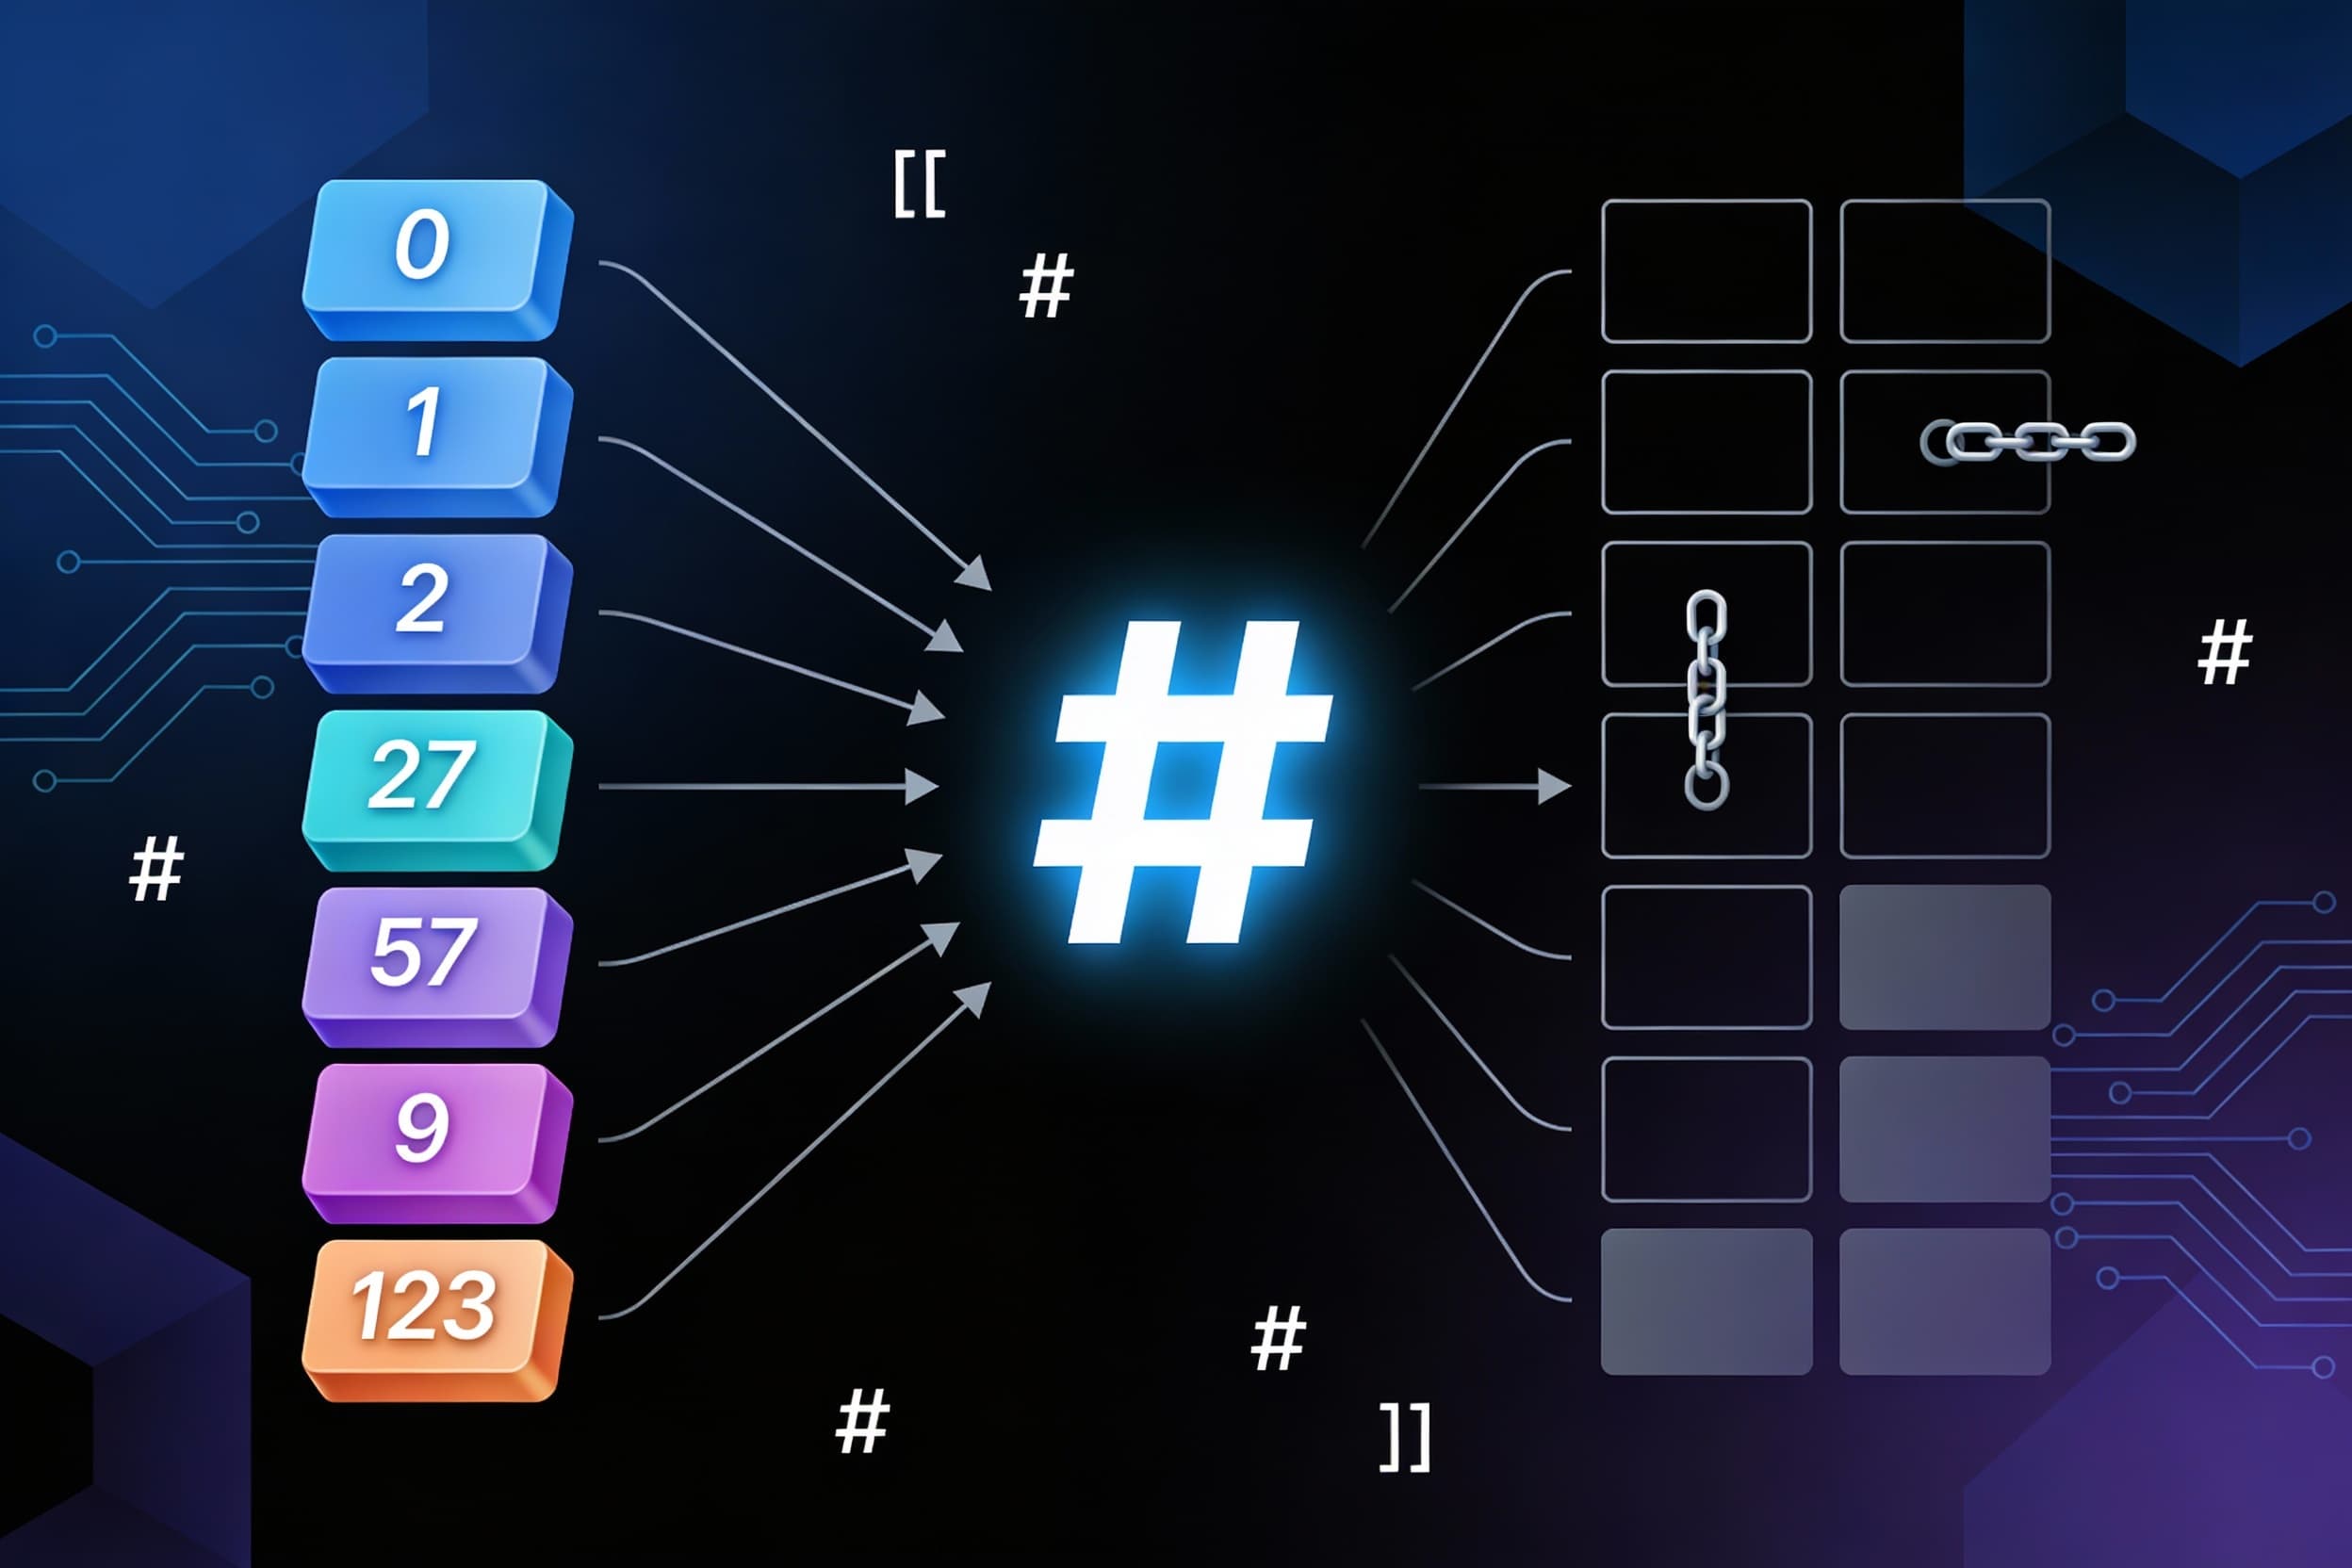
What is HashMap?HashMap is a non-linear data structure that lives inside Java's collection framework, alongside other structures like Trees and Graphs (see the generated image above). What makes it special? It uses a clever technique called hashing to store and retrieve data at blazing speeds.Think of hashing as a smart address system. It converts large keys (like long strings or big numbers) into smaller values that work as array indices. This simple trick transforms your data lookup from slow O(n)O(n) or O(log⁑n)O(logn) operations into lightning-fast O(1)O(1) access times!Understanding Hashing MappingsBefore diving deeper, let's understand the four types of hashing mappings:One-to-one mapping β€” Each key maps to exactly one indexMany-to-one mapping β€” Multiple keys can map to the same indexOne-to-many mapping β€” One key maps to multiple indicesMany-to-many mapping β€” Multiple keys map to multiple indicesHashMap primarily uses one-to-one and many-to-one mapping strategies to achieve its performance goals.The Problem: Why Not Just Use Arrays?Let's say you want to store 7 elements with keys: 1, 5, 23, 57, 234, 678, and 1000.Using direct indexing (where key = array index), you'd need an array of size 1000 just to store 7 items! That leaves 993 empty slots wasting precious memory. Imagine having a parking lot with 1000 spaces for just 7 cars β€” totally inefficient!This is the exact problem hash functions solve.Hash Functions: The SolutionA hash function takes your key and calculates which array index to use. The beauty? You can now store those same 7 elements in an array of just size 10!The most common hash function uses the modulus operator:hash(key)=keymod array sizehash(key)=keymodarray sizeExample: With array size = 10:Key 57 β†’ Index: 57mod 10=757mod10=7Key 234 β†’ Index: 234mod 10=4234mod10=4Key 1000 β†’ Index: 1000mod 10=01000mod10=0Now you only need an array of size 10 instead of 1000. Problem solved!Three Popular Hash Function TypesModulus MethodThe most widely used technique. Divide the key by array size (or a prime number) and use the remainder as the index.index=keymod sizeindex=keymodsizeMid Square MethodSquare the key value, then extract the middle digits to form your hash value.Example: Key = 57 β†’ 572=3249572=3249 β†’ Extract middle digits "24"Folding HashingDivide the key into equal parts, add them together, then apply modulus.Example: Key = 123456Split into: 12, 34, 56Sum: 12+34+56=10212+34+56=102Apply modulus: 102mod 10=2102mod10=2The Collision ProblemHere's the catch: sometimes two different keys produce the same index. This is called a collision.Example:Key 27 β†’ 27mod 10=727mod10=7Key 57 β†’ 57mod 10=757mod10=7Both keys want index 7! We need smart strategies to handle this.Collision Resolution: Two Main TechniquesTechnique 1: Open Chaining (Separate Chaining)Mapping Type: Many-to-oneWhen a collision happens, create a linked list at that index and store all colliding values in sorted order.Example: Keys 22 and 32 both map to index 2:Index 2: [22] β†’ [32] β†’ nullAdvantage: Simple and works well in practiceDrawback: If too many collisions occur, the linked list becomes long and searching degrades to O(n)O(n). However, Java's collection framework uses highly optimized hash functions that achieve amortized O(1)O(1) time complexity.Technique 2: Closed Addressing (Open Addressing)Mapping Type: One-to-manyInstead of creating a list, find another empty slot in the array. There are three approaches:Linear ProbingWhen collision occurs, check the next index. If it's occupied, keep checking the next one until you find an empty slot.Hash Function:h(x)=xmod sizeh(x)=xmodsizeOn Collision:h(x)=(h(x)+i)mod sizeh(x)=(h(x)+i)modsizewhere i=0,1,2,3,…i=0,1,2,3,…Example: Keys 22 and 32 both map to index 2:Store 22 at index 2Try 32 at index 2 β†’ occupiedCheck index 3 β†’ empty, store 32 thereProblems:Clustering: Keys bunch together in adjacent indices, slowing down searchesDeleted Slot Problem: When you delete a key, it creates an empty slot that breaks the search chainThe Deleted Slot Problem Explained:Keys 22 and 32 are at indices 2 and 3Delete key 22 from index 2Now when searching for key 32, the algorithm reaches index 2 (empty), thinks key 32 doesn't exist, and stops searching!Solution: Mark deleted slots with a special marker (like -1) or perform rehashing after deletions.Quadratic ProbingSame concept as linear probing, but instead of checking consecutive slots, jump in quadratic increments: 1, 4, 9, 16, 25...Hash Function:h(x)=xmod sizeh(x)=xmodsizeOn Collision:h(x)=(h(x)+i2)mod sizeh(x)=(h(x)+i2)modsizewhere i=0,1,2,3,…i=0,1,2,3,…Advantage: Significantly reduces clusteringDrawback: Still suffers from the deleted slot problemDouble HashingThe most sophisticated approach! Uses two different hash functions to create unique probe sequences for each key.First Hash Function:h1(x)=xmod sizeh1(x)=xmodsizeSecond Hash Function:h2(x)=primeβˆ’(xmod prime)h2(x)=primeβˆ’(xmodprime)On Collision:h(x)=(h1(x)+iΓ—h2(x))mod sizeh(x)=(h1(x)+iΓ—h2(x))modsizewhere i=0,1,2,3,…i=0,1,2,3,…Advantage: Effectively avoids clustering and provides the best performance among probing techniquesLoad Factor: The Performance IndicatorThe load factor tells you how full your hash table is:Load Factor=Number of elementsArray sizeLoad Factor=Array sizeNumber of elementsPerformance GuidelinesLoad Factor ≀ 0.5 β†’ Good performance, fast operations Load Factor > 0.7 β†’ Poor performance, time to rehash ExamplesBad Load Factor:Array size = 10, Elements = 8Load Factor = 8/10=0.88/10=0.8Action: Rehash the array (typically double the size)Good Load Factor:Array size = 200, Elements = 100Load Factor = 100/200=0.5100/200=0.5Action: No changes needed, performing optimallyWhat is Rehashing?When the load factor exceeds the threshold (usually 0.7), the hash table is resized β€” typically doubled in size. All existing elements are then rehashed and redistributed into the new larger array. This maintains optimal performance as your data grows.Performance SummaryHashMap delivers exceptional average-case performance:Insertion: O(1)O(1)Deletion: O(1)O(1)Search: O(1)O(1)However, in the worst case (many collisions with poor hash functions), operations can degrade to O(n)O(n).The key to maintaining O(1)O(1) performance:Use a good hash functionChoose an appropriate collision resolution strategyMonitor and maintain a healthy load factorRehash when necessaryConclusionHashMap is one of the most powerful and frequently used data structures in programming. By understanding hashing techniques, collision resolution strategies, and load factors, you can write more efficient code and make better design decisions.Whether you're building a cache, implementing a frequency counter, or solving complex algorithm problems, HashMap is your go-to tool for fast data access!

hashmapdata-structureshashingjavaalgorithmscollision-resolutiontime-complexity
Recursion in Java - Complete Guide With Examples and Practice Problems

Recursion in Java - Complete Guide With Examples and Practice Problems

IntroductionIf there is one topic in programming that confuses beginners more than anything else, it is recursion. Most people read the definition, nod their head, and then immediately freeze when they have to write recursive code themselves.The problem is not that recursion is genuinely hard. The problem is that most explanations start with code before building the right mental model. Once you have the right mental model, recursion clicks permanently and you start seeing it everywhere β€” in tree problems, graph problems, backtracking, dynamic programming, divide and conquer, and more.This guide covers everything from the ground up. What recursion is, how the call stack works, how to identify base cases and recursive cases, every type of recursion, common patterns, time and space complexity analysis, the most common mistakes, and the top LeetCode problems to practice.By the end of this article, recursion will not feel like magic anymore. It will feel like a natural tool you reach for confidently.What Is Recursion?Recursion is when a function calls itself to solve a smaller version of the same problem.That is the complete definition. But let us make it concrete.Imagine you want to count down from 5 to 1. One way is a loop. Another way is β€” print 5, then solve the exact same problem for counting down from 4 to 1. Then print 4, solve for 3. And so on until you reach the base β€” there is nothing left to count down.void countDown(int n) { if (n == 0) return; // stop here System.out.println(n); countDown(n - 1); // solve the smaller version}The function countDown calls itself with a smaller input each time. Eventually it reaches 0 and stops. That stopping condition is the most important part of any recursive function β€” the base case.The Two Parts Every Recursive Function Must HaveEvery correctly written recursive function has exactly two parts. Without both, the function either gives wrong answers or runs forever.Part 1: Base CaseThe base case is the condition under which the function stops calling itself and returns a direct answer. It is the smallest version of the problem that you can solve without any further recursion.Without a base case, recursion never stops and you get a StackOverflowError β€” Java's way of telling you the call stack ran out of memory.Part 2: Recursive CaseThe recursive case is where the function calls itself with a smaller or simpler input β€” moving closer to the base case with each call. If your recursive case does not make the problem smaller, you have an infinite loop.Think of it like a staircase. The base case is the ground floor. The recursive case is each step going down. Every step must genuinely bring you one level closer to the ground.How Recursion Works β€” The Call StackThis is the mental model that most explanations skip, and it is the reason recursion confuses people.Every time a function is called in Java, a new stack frame is created and pushed onto the call stack. This frame stores the function's local variables, parameters, and where to return to when the function finishes.When a recursive function calls itself, a new frame is pushed on top. When that call finishes, its frame is popped and execution returns to the previous frame.Let us trace countDown(3) through the call stack:countDown(3) called β†’ frame pushed prints 3 calls countDown(2) β†’ frame pushed prints 2 calls countDown(1) β†’ frame pushed prints 1 calls countDown(0) β†’ frame pushed n == 0, return β†’ frame popped back in countDown(1), return β†’ frame popped back in countDown(2), return β†’ frame popped back in countDown(3), return β†’ frame poppedOutput: 3, 2, 1The call stack grows as calls go deeper, then shrinks as calls return. This is why recursion uses O(n) space for n levels deep β€” each level occupies one stack frame in memory.Your First Real Recursive Function β€” FactorialFactorial is the classic first recursion example. n! = n Γ— (n-1) Γ— (n-2) Γ— ... Γ— 1Notice the pattern β€” n! = n Γ— (n-1)!. The factorial of n is n times the factorial of n-1. That recursive structure makes it perfect for recursion.public int factorial(int n) { // base case if (n == 0 || n == 1) return 1; // recursive case return n * factorial(n - 1);}Dry Run β€” factorial(4)factorial(4)= 4 * factorial(3)= 4 * 3 * factorial(2)= 4 * 3 * 2 * factorial(1)= 4 * 3 * 2 * 1= 24The call stack builds up going in, then multiplications happen coming back out. This "coming back out" phase is called the return phase or unwinding of the stack.Time Complexity: O(n) β€” n recursive calls Space Complexity: O(n) β€” n frames on the call stackThe Two Phases of RecursionEvery recursive function has two phases and understanding both is critical.Phase 1: The Call Phase (Going In)This happens as the function keeps calling itself with smaller inputs. Things you do before the recursive call happen in this phase β€” in order from the outermost call to the innermost.Phase 2: The Return Phase (Coming Back Out)This happens as each call finishes and returns to its caller. Things you do after the recursive call happen in this phase β€” in reverse order, from the innermost call back to the outermost.This distinction explains why the output order can be surprising:void printBothPhases(int n) { if (n == 0) return; System.out.println("Going in: " + n); // call phase printBothPhases(n - 1); System.out.println("Coming out: " + n); // return phase}For printBothPhases(3):Going in: 3Going in: 2Going in: 1Coming out: 1Coming out: 2Coming out: 3This two-phase understanding is what makes problems like reversing a string or printing a linked list backwards via recursion feel natural.Types of RecursionRecursion is not one-size-fits-all. There are several distinct types and knowing which type applies to a problem shapes how you write the solution.1. Direct RecursionThe function calls itself directly. This is the most common type β€” what we have seen so far.void direct(int n) { if (n == 0) return; direct(n - 1); // calls itself}2. Indirect RecursionFunction A calls Function B which calls Function A. They form a cycle.void funcA(int n) { if (n <= 0) return; System.out.println("A: " + n); funcB(n - 1);}void funcB(int n) { if (n <= 0) return; System.out.println("B: " + n); funcA(n - 1);}Used in: state machines, mutual recursion in parsers, certain mathematical sequences.3. Tail RecursionThe recursive call is the last operation in the function. Nothing happens after the recursive call returns β€” no multiplication, no addition, nothing.// NOT tail recursive β€” multiplication happens after returnint factorial(int n) { if (n == 1) return 1; return n * factorial(n - 1); // multiply after return β€” not tail}// Tail recursive β€” recursive call is the last thingint factorialTail(int n, int accumulator) { if (n == 1) return accumulator; return factorialTail(n - 1, n * accumulator); // last operation}Why does tail recursion matter? In languages that support tail call optimization (like Scala, Kotlin, and many functional languages), tail recursive functions can be converted to iteration internally β€” no stack frame accumulation, O(1) space. Java does NOT perform tail call optimization, but understanding tail recursion is still important for interviews and functional programming concepts.4. Head RecursionThe recursive call happens first, before any other processing. All processing happens in the return phase.void headRecursion(int n) { if (n == 0) return; headRecursion(n - 1); // call first System.out.println(n); // process after}// Output: 1 2 3 4 5 (processes in reverse order of calls)5. Tree RecursionThe function makes more than one recursive call per invocation. This creates a tree of calls rather than a linear chain. Fibonacci is the classic example.int fibonacci(int n) { if (n <= 1) return n; return fibonacci(n - 1) + fibonacci(n - 2); // TWO recursive calls}The call tree for fibonacci(4): fib(4) / \ fib(3) fib(2) / \ / \ fib(2) fib(1) fib(1) fib(0) / \ fib(1) fib(0)Time Complexity: O(2ⁿ) β€” exponential! Each call spawns two more. Space Complexity: O(n) β€” maximum depth of the call treeThis is why memoization (caching results) is so important for tree recursion β€” it converts O(2ⁿ) to O(n) by never recomputing the same subproblem twice.6. Mutual RecursionA specific form of indirect recursion where two functions call each other alternately to solve a problem. Different from indirect recursion in that the mutual calls are the core mechanism of the solution.// Check if a number is even or odd using mutual recursionboolean isEven(int n) { if (n == 0) return true; return isOdd(n - 1);}boolean isOdd(int n) { if (n == 0) return false; return isEven(n - 1);}Common Recursion Patterns in DSAThese are the patterns you will see over and over in interview problems. Recognizing them is more important than memorizing solutions.Pattern 1: Linear Recursion (Do Something, Recurse on Rest)Process the current element, then recurse on the remaining problem.// Sum of arrayint arraySum(int[] arr, int index) { if (index == arr.length) return 0; // base case return arr[index] + arraySum(arr, index + 1); // current + rest}Pattern 2: Divide and Conquer (Split Into Two Halves)Split the problem into two halves, solve each recursively, combine results.// Merge Sortvoid mergeSort(int[] arr, int left, int right) { if (left >= right) return; // base case β€” single element int mid = (left + right) / 2; mergeSort(arr, left, mid); // sort left half mergeSort(arr, mid + 1, right); // sort right half merge(arr, left, mid, right); // combine}Pattern 3: Backtracking (Try, Recurse, Undo)Try a choice, recurse to explore it, undo the choice when backtracking.// Generate all subsetsvoid subsets(int[] nums, int index, List<Integer> current, List<List<Integer>> result) { if (index == nums.length) { result.add(new ArrayList<>(current)); return; } // Choice 1: include nums[index] current.add(nums[index]); subsets(nums, index + 1, current, result); current.remove(current.size() - 1); // undo // Choice 2: exclude nums[index] subsets(nums, index + 1, current, result);}Pattern 4: Tree Recursion (Left, Right, Combine)Recurse on left subtree, recurse on right subtree, combine or process results.// Height of binary treeint height(TreeNode root) { if (root == null) return 0; // base case int leftHeight = height(root.left); // solve left int rightHeight = height(root.right); // solve right return 1 + Math.max(leftHeight, rightHeight); // combine}Pattern 5: Memoization (Cache Recursive Results)Store results of recursive calls so the same subproblem is never solved twice.Map<Integer, Integer> memo = new HashMap<>();int fibonacci(int n) { if (n <= 1) return n; if (memo.containsKey(n)) return memo.get(n); // return cached int result = fibonacci(n - 1) + fibonacci(n - 2); memo.put(n, result); // cache before returning return result;}This converts Fibonacci from O(2ⁿ) to O(n) time with O(n) space β€” a massive improvement.Recursion vs Iteration β€” When to Use WhichThis is one of the most common interview questions about recursion. Here is a clear breakdown:Use Recursion when:The problem has a naturally recursive structure (trees, graphs, divide and conquer)The solution is significantly cleaner and easier to understand recursivelyThe problem involves exploring multiple paths or choices (backtracking)The depth of recursion is manageable (not too deep to cause stack overflow)Use Iteration when:The problem is linear and a loop is equally clearMemory is a concern (iteration uses O(1) stack space vs O(n) for recursion)Performance is critical and function call overhead mattersJava's stack size limit could be hit (default around 500-1000 frames for deep recursion)The key rule: Every recursive solution can be converted to an iterative one (usually using an explicit stack). But recursive solutions for tree and graph problems are almost always cleaner to write and understand.Time and Space Complexity of Recursive FunctionsAnalyzing complexity for recursive functions requires a specific approach.The Recurrence Relation MethodExpress the time complexity as a recurrence relation and solve it.Factorial:T(n) = T(n-1) + O(1) = T(n-2) + O(1) + O(1) = T(1) + nΓ—O(1) = O(n)Fibonacci (naive):T(n) = T(n-1) + T(n-2) + O(1) β‰ˆ 2Γ—T(n-1) = O(2ⁿ)Binary Search:T(n) = T(n/2) + O(1) = O(log n) [by Master Theorem]Merge Sort:T(n) = 2Γ—T(n/2) + O(n) = O(n log n) [by Master Theorem]Space Complexity Rule for RecursionSpace complexity of a recursive function = maximum depth of the call stack Γ— space per frameLinear recursion (factorial, sum): O(n) spaceBinary recursion (Fibonacci naive): O(n) space (maximum depth, not number of nodes)Divide and conquer (merge sort): O(log n) space (depth of recursion tree)Memoized Fibonacci: O(n) space (memo table + call stack)Classic Recursive Problems With SolutionsProblem 1: Reverse a StringString reverse(String s) { if (s.length() <= 1) return s; // base case // last char + reverse of everything before last char return s.charAt(s.length() - 1) + reverse(s.substring(0, s.length() - 1));}Dry run for "hello":reverse("hello") = 'o' + reverse("hell")reverse("hell") = 'l' + reverse("hel")reverse("hel") = 'l' + reverse("he")reverse("he") = 'e' + reverse("h")reverse("h") = "h"Unwinding: "h" β†’ "he" β†’ "leh" β†’ "lleh" β†’ "olleh" βœ…Problem 2: Power Function (x^n)double power(double x, int n) { if (n == 0) return 1; // base case if (n < 0) return 1.0 / power(x, -n); // handle negative if (n % 2 == 0) { double half = power(x, n / 2); return half * half; // x^n = (x^(n/2))^2 } else { return x * power(x, n - 1); }}This is the fast power algorithm β€” O(log n) time instead of O(n).Problem 3: Fibonacci With Memoizationint[] memo = new int[100];Arrays.fill(memo, -1);int fib(int n) { if (n <= 1) return n; if (memo[n] != -1) return memo[n]; memo[n] = fib(n - 1) + fib(n - 2); return memo[n];}Time: O(n) β€” each value computed once Space: O(n) β€” memo array + call stackProblem 4: Tower of HanoiThe classic recursion teaching problem. Move n disks from source to destination using a helper rod.void hanoi(int n, char source, char destination, char helper) { if (n == 1) { System.out.println("Move disk 1 from " + source + " to " + destination); return; } // Move n-1 disks from source to helper hanoi(n - 1, source, helper, destination); // Move the largest disk from source to destination System.out.println("Move disk " + n + " from " + source + " to " + destination); // Move n-1 disks from helper to destination hanoi(n - 1, helper, destination, source);}Time Complexity: O(2ⁿ) β€” minimum moves required is 2ⁿ - 1 Space Complexity: O(n) β€” call stack depthProblem 5: Generate All Subsets (Power Set)void generateSubsets(int[] nums, int index, List<Integer> current, List<List<Integer>> result) { result.add(new ArrayList<>(current)); // add current subset for (int i = index; i < nums.length; i++) { current.add(nums[i]); // include generateSubsets(nums, i + 1, current, result); // recurse current.remove(current.size() - 1); // exclude (backtrack) }}For [1, 2, 3] β€” generates all 8 subsets: [], [1], [1,2], [1,2,3], [1,3], [2], [2,3], [3]Time: O(2ⁿ) β€” 2ⁿ subsets Space: O(n) β€” recursion depthProblem 6: Binary Search Recursivelyint binarySearch(int[] arr, int target, int left, int right) { if (left > right) return -1; // base case β€” not found int mid = left + (right - left) / 2; if (arr[mid] == target) return mid; else if (arr[mid] < target) return binarySearch(arr, target, mid + 1, right); else return binarySearch(arr, target, left, mid - 1);}Time: O(log n) β€” halving the search space each time Space: O(log n) β€” log n frames on the call stackRecursion on Trees β€” The Natural HabitatTrees are where recursion truly shines. Every tree problem becomes elegant with recursion because a tree is itself a recursive structure β€” each node's left and right children are trees themselves.// Maximum depth of binary treeint maxDepth(TreeNode root) { if (root == null) return 0; return 1 + Math.max(maxDepth(root.left), maxDepth(root.right));}// Check if tree is symmetricboolean isSymmetric(TreeNode left, TreeNode right) { if (left == null && right == null) return true; if (left == null || right == null) return false; return left.val == right.val && isSymmetric(left.left, right.right) && isSymmetric(left.right, right.left);}// Path sum β€” does any root-to-leaf path sum to target?boolean hasPathSum(TreeNode root, int target) { if (root == null) return false; if (root.left == null && root.right == null) return root.val == target; return hasPathSum(root.left, target - root.val) || hasPathSum(root.right, target - root.val);}Notice the pattern in all three β€” base case handles null, recursive case handles left and right subtrees, result combines both.How to Think About Any Recursive Problem β€” Step by StepThis is the framework you should apply to every new recursive problem you encounter:Step 1 β€” Identify the base case What is the smallest input where you know the answer directly without any recursion? For arrays it is usually empty array or single element. For trees it is null node. For numbers it is 0 or 1.Step 2 β€” Trust the recursive call Assume your function already works correctly for smaller inputs. Do not trace through the entire recursion mentally β€” just trust it. This is the Leap of Faith and it is what makes recursion feel natural.Step 3 β€” Express the current problem in terms of smaller problems How does the answer for size n relate to the answer for size n-1 (or n/2, or subtrees)? This relationship is your recursive case.Step 4 β€” Make sure each call moves toward the base case The input must become strictly smaller with each call. If it does not, you have infinite recursion.Step 5 β€” Write the base case first, then the recursive case Always. Writing the recursive case first leads to bugs because you have not defined when to stop.Common Mistakes and How to Avoid ThemMistake 1: Missing or wrong base case The most common mistake. Missing the base case causes StackOverflowError. Wrong base case causes wrong answers.Always ask β€” what is the simplest possible input, and what should the function return for it? Write that case first.Mistake 2: Not moving toward the base case If you call factorial(n) inside factorial(n) without reducing n, you loop forever. Every recursive call must make the problem strictly smaller.Mistake 3: Trusting your brain to trace deep recursion Do not try to trace 10 levels of recursion in your head. Trust the recursive call, verify the base case, and check that each call reduces the problem. That is all you need.Mistake 4: Forgetting to return the recursive result// WRONG β€” result is computed but not returnedint sum(int n) { if (n == 0) return 0; sum(n - 1) + n; // computed but discarded!}// CORRECTint sum(int n) { if (n == 0) return 0; return sum(n - 1) + n;}Mistake 5: Modifying shared state without backtracking In backtracking problems, if you add something to a list before a recursive call, you must remove it after the call returns. Forgetting to backtrack leads to incorrect results and is one of the trickiest bugs to find.Mistake 6: Recomputing the same subproblems Naive Fibonacci computes fib(3) multiple times when computing fib(5). Use memoization whenever you notice overlapping subproblems in your recursion tree.Top LeetCode Problems on RecursionThese are organized by pattern β€” work through them in this order for maximum learning:Pure Recursion Basics:509. Fibonacci Number β€” Easy β€” start here, implement with and without memoization344. Reverse String β€” Easy β€” recursion on arrays206. Reverse Linked List β€” Easy β€” recursion on linked list50. Pow(x, n) β€” Medium β€” fast power with recursionTree Recursion (Most Important):104. Maximum Depth of Binary Tree β€” Easy β€” simplest tree recursion112. Path Sum β€” Easy β€” decision recursion on tree101. Symmetric Tree β€” Easy β€” mutual recursion on tree110. Balanced Binary Tree β€” Easy β€” bottom-up recursion236. Lowest Common Ancestor of a Binary Tree β€” Medium β€” classic tree recursion124. Binary Tree Maximum Path Sum β€” Hard β€” advanced tree recursionDivide and Conquer:148. Sort List β€” Medium β€” merge sort on linked list240. Search a 2D Matrix II β€” Medium β€” divide and conquerBacktracking:78. Subsets β€” Medium β€” generate all subsets46. Permutations β€” Medium β€” generate all permutations77. Combinations β€” Medium β€” generate combinations79. Word Search β€” Medium β€” backtracking on grid51. N-Queens β€” Hard β€” classic backtrackingMemoization / Dynamic Programming:70. Climbing Stairs β€” Easy β€” Fibonacci variant with memoization322. Coin Change β€” Medium β€” recursion with memoization to DP139. Word Break β€” Medium β€” memoized recursionRecursion Cheat Sheet// Linear recursion templatereturnType solve(input) { if (baseCase) return directAnswer; // process current return solve(smallerInput);}// Tree recursion templatereturnType solve(TreeNode root) { if (root == null) return baseValue; returnType left = solve(root.left); returnType right = solve(root.right); return combine(left, right, root.val);}// Backtracking templatevoid backtrack(choices, current, result) { if (goalReached) { result.add(copy of current); return; } for (choice : choices) { make(choice); // add to current backtrack(...); // recurse undo(choice); // remove from current }}// Memoization templateMap<Input, Output> memo = new HashMap<>();returnType solve(input) { if (baseCase) return directAnswer; if (memo.containsKey(input)) return memo.get(input); returnType result = solve(smallerInput); memo.put(input, result); return result;}FAQs β€” People Also AskQ1. What is recursion in Java with a simple example? Recursion is when a function calls itself to solve a smaller version of the same problem. A simple example is factorial β€” factorial(5) = 5 Γ— factorial(4) = 5 Γ— 4 Γ— factorial(3) and so on until factorial(1) returns 1 directly.Q2. What is the difference between recursion and iteration? Iteration uses loops (for, while) and runs in O(1) space. Recursion uses function calls and uses O(n) stack space for n levels deep. Recursion is often cleaner for tree and graph problems. Iteration is better when memory is a concern or the problem is inherently linear.Q3. What causes StackOverflowError in Java recursion? StackOverflowError happens when recursion goes too deep β€” too many frames accumulate on the call stack before any of them return. This is caused by missing base case, wrong base case, or input too large for Java's default stack size limit.Q4. What is the difference between recursion and dynamic programming? Recursion solves a problem by breaking it into subproblems. Dynamic programming is recursion plus memoization β€” storing results of subproblems so they are never computed twice. DP converts exponential recursive solutions into polynomial ones by eliminating redundant computation.Q5. What is tail recursion and does Java support tail call optimization? Tail recursion is when the recursive call is the absolute last operation in the function. Java does NOT support tail call optimization β€” Java always creates a new stack frame for each call even if it is tail recursive. Languages like Scala and Kotlin (on the JVM) do support it with the tailrec keyword.Q6. How do you convert recursion to iteration? Every recursive solution can be converted to iterative using an explicit stack data structure. The call stack's behavior is replicated manually β€” push the initial call, loop while stack is not empty, pop, process, and push sub-calls. Tree traversals are a common example of this conversion.ConclusionRecursion is not magic. It is a systematic way of solving problems by expressing them in terms of smaller versions of themselves. Once you internalize the two parts (base case and recursive case), understand the call stack mentally, and learn to trust the recursive call rather than trace it completely, everything clicks.The learning path from here is clear β€” start with simple problems like Fibonacci and array sum. Move to tree problems where recursion is most natural. Then tackle backtracking. Finally add memoization to bridge into dynamic programming.Every hour you spend understanding recursion deeply pays dividends across the entire rest of your DSA journey. Trees, graphs, divide and conquer, backtracking, dynamic programming β€” all of them build on this foundation.

RecursionJavaBase CaseCall StackBacktrackingDynamic Programming
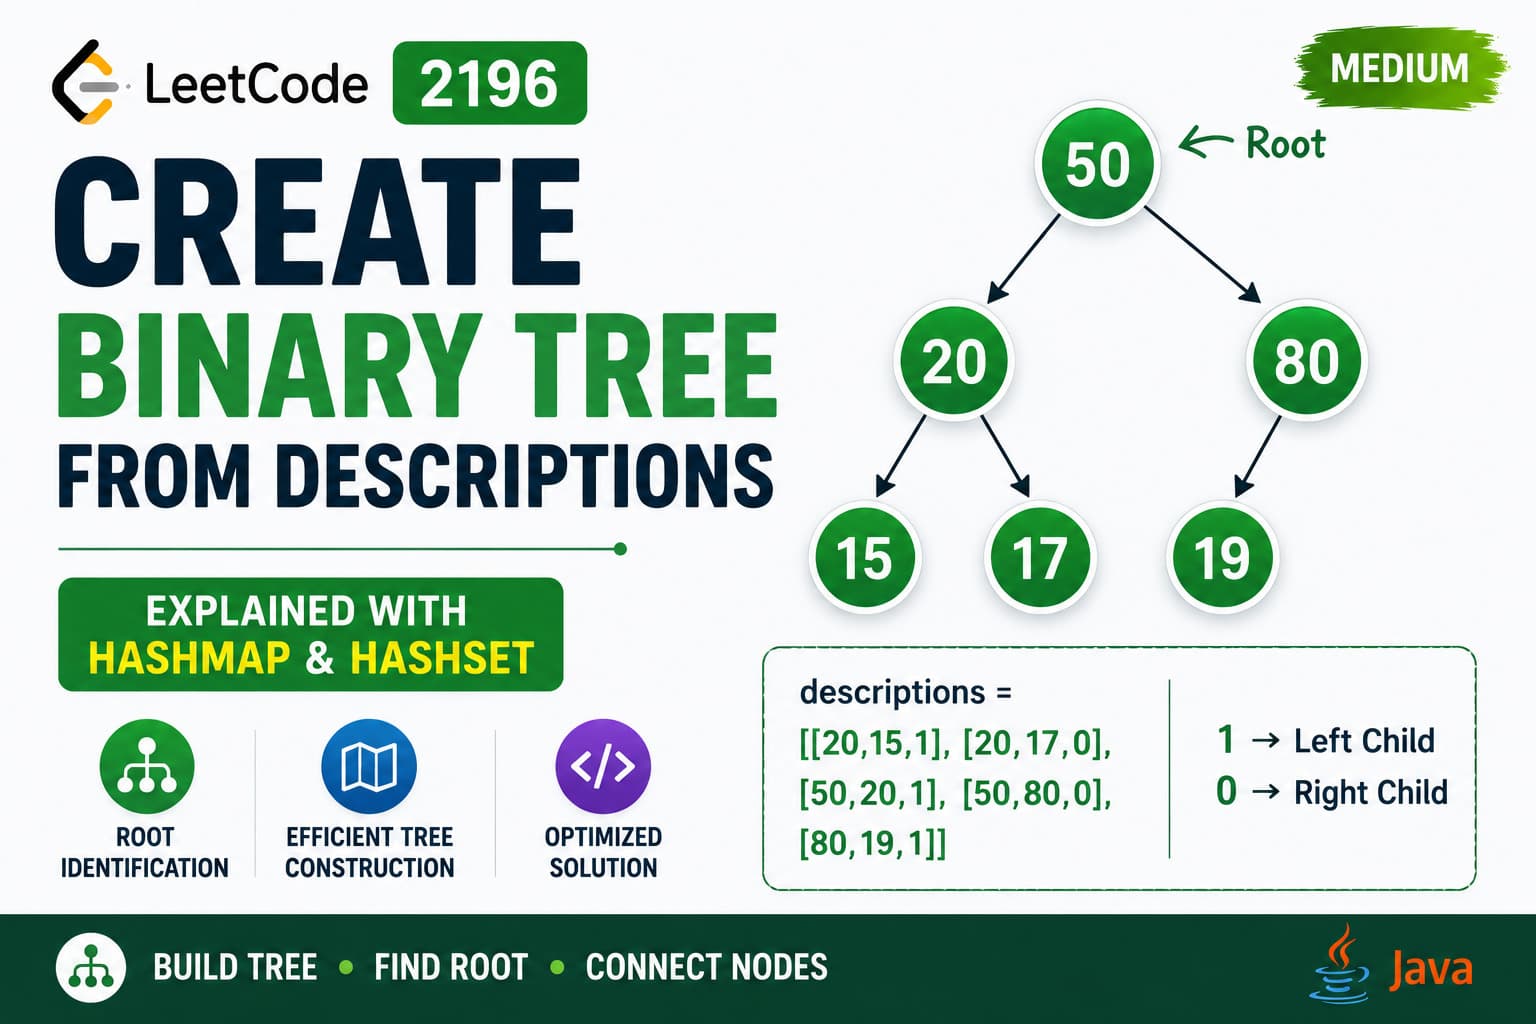
LeetCode 2196: Create Binary Tree From Descriptions – Java HashMap & Tree Construction Solution

LeetCode 2196: Create Binary Tree From Descriptions – Java HashMap & Tree Construction Solution

IntroductionBinary tree construction problems are extremely common in coding interviews because they test multiple concepts together:Tree data structuresHashMap usageParent-child relationshipsGraph-style thinkingRoot identificationLeetCode 2196 is an excellent medium-level problem that focuses on constructing a binary tree from parent-child descriptions efficiently.In this article, we will deeply understand:How the tree is formedHow to identify the root nodeWhy HashMap is useful hereStep-by-step dry runTime and space complexityComplete optimized Java solutionProblem StatementYou are given a 2D array:descriptions[i] = [parent, child, isLeft]Where:parent is the parent nodechild is the child nodeisLeft == 1 means left childisLeft == 0 means right childYour task is to:Construct the binary treeReturn the root nodeHere is the Link to try it now -: Create Binary Tree From DescriptionsExampleInputdescriptions = [ [20,15,1], [20,17,0], [50,20,1], [50,80,0], [80,19,1]]Output[50,20,80,15,17,19]Visual Representation 50 / \ 20 80 / \ / 15 17 19Key ObservationEvery node except the root appears as a child exactly once.This means:Root node never appears in child positionsIf we store all child nodes,The node not present in the child set becomes the rootThis is the core trick of the problem.Approach OverviewWe solve the problem in 3 steps:Step 1: Find the Root NodeStore every child node in a HashSet.Then iterate through descriptions again:The parent that never appears as a child is the root.Step 2: Create Tree NodesUse a HashMap:value β†’ TreeNodeThis prevents duplicate node creation.Step 3: Connect Parent and ChildBased on:isLeftattach nodes accordingly.Optimized Java Solutionclass Solution { public TreeNode createBinaryTree(int[][] descriptions) { HashSet<Integer> childSet = new HashSet<>(); // Store all child nodes for (int[] arr : descriptions) { childSet.add(arr[1]); } // Find root node int rootValue = -1; for (int[] arr : descriptions) { if (!childSet.contains(arr[0])) { rootValue = arr[0]; } } // Map value -> TreeNode HashMap<Integer, TreeNode> map = new HashMap<>(); for (int i = 0; i < descriptions.length; i++) { int parent = descriptions[i][0]; int child = descriptions[i][1]; int isLeft = descriptions[i][2]; // Create parent node if absent if (!map.containsKey(parent)) { map.put(parent, new TreeNode(parent)); } // Create child node if absent if (!map.containsKey(child)) { map.put(child, new TreeNode(child)); } // Connect nodes if (isLeft == 1) { map.get(parent).left = map.get(child); } else { map.get(parent).right = map.get(child); } } return map.get(rootValue); }}Step-by-Step ExplanationStep 1: Store All Child NodeschildSet.add(arr[1]);Every child is stored.Since root never becomes a child,it will not exist inside this set.Step 2: Identify Rootif (!childSet.contains(arr[0]))This finds the node that only acts as parent.That node becomes the root.Step 3: Create Unique Tree NodesHashMap<Integer, TreeNode> mapAvoids duplicate node creation.Each value maps to exactly one TreeNode.Step 4: Connect Parent and Childmap.get(parent).left = map.get(child);ormap.get(parent).right = map.get(child);depending on:isLeftDry RunInput[ [20,15,1], [20,17,0], [50,20,1], [50,80,0], [80,19,1]]Child Set15, 17, 20, 80, 19Root DetectionCheck parents:20 β†’ exists in child set50 β†’ NOT in child setSo:Root = 50Tree Construction50left β†’ 20right β†’ 8020left β†’ 15right β†’ 1780left β†’ 19Final tree becomes: 50 / \ 20 80 / \ / 15 17 19Time ComplexityBuilding Child SetO(N)Finding RootO(N)Constructing TreeO(N)Total Time ComplexityO(N)Efficient for large constraints.Space ComplexityHashMap + HashSetO(N)Why This Problem is ImportantThis problem teaches:Tree constructionParent-child mappingRoot identificationEfficient object reuseHashMap optimizationIt is frequently asked in interviews because it combines multiple concepts in one clean implementation.Common Mistakes1. Creating Duplicate NodesWrong:new TreeNode(parent)every time.Always reuse nodes through HashMap.2. Incorrect Root DetectionRemember:Root never appears as child.3. Forgetting Left vs Right ChildAlways check:isLeftbefore attaching.Interview TipsIn interviews explain:We first identify the root using a child set, then use a HashMap to create and reuse TreeNode objects efficiently while connecting parent-child relationships.This demonstrates:Strong data structure understandingEfficient memory usageClean tree construction logicRelated ProblemsPractice these next:Construct Binary Tree from TraversalsValidate Binary Search TreeSerialize and Deserialize Binary TreeLowest Common AncestorBinary Tree Level Order TraversalConclusionLeetCode 2196 is a clean and elegant binary tree construction problem.The major insight is:The root node is the only node that never appears as a child.Combined with HashMap-based node reuse, we can construct the entire tree efficiently in linear time.This is an excellent interview problem for mastering tree construction patterns.

LeetCodeJavaTreeHashMapHashSetBinary TreeMedium
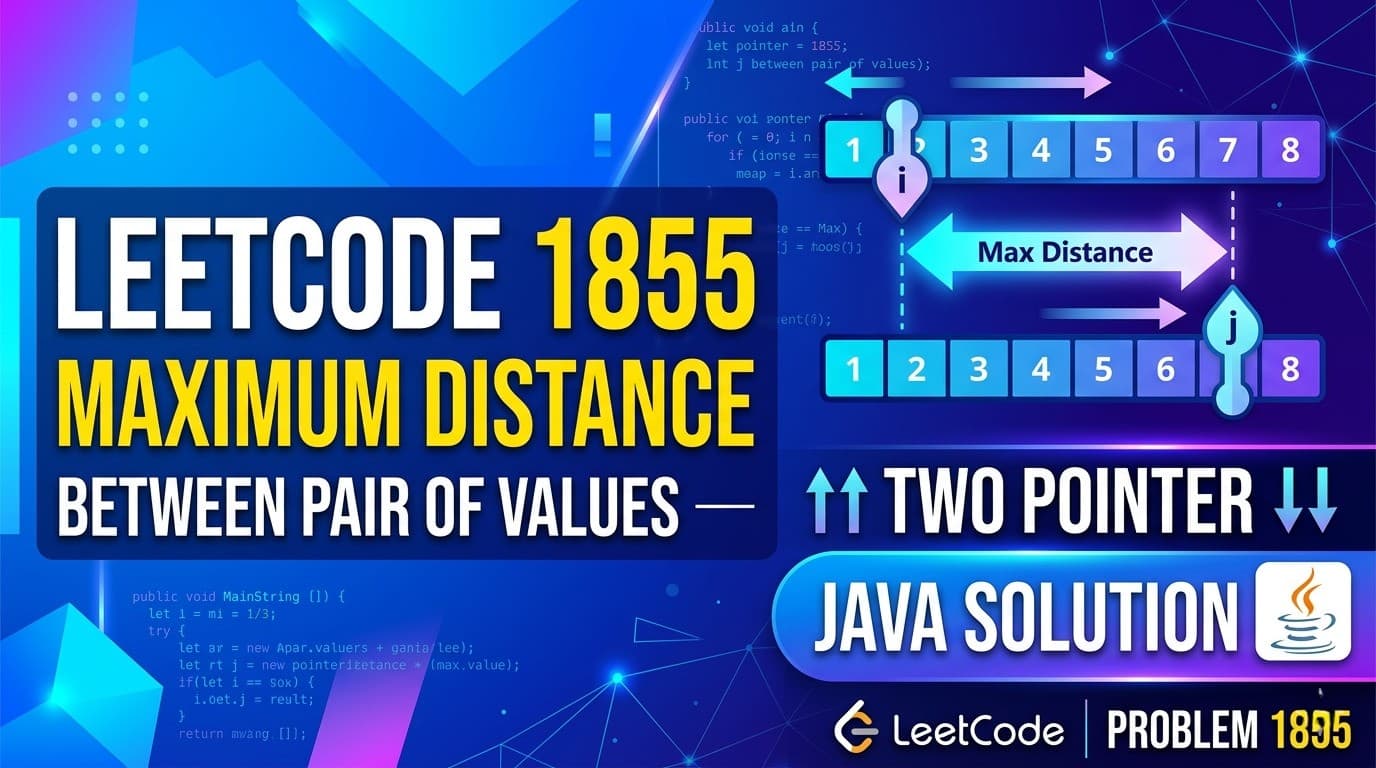
LeetCode 1855 Maximum Distance Between Pair of Values | Two Pointer Java Solution

LeetCode 1855 Maximum Distance Between Pair of Values | Two Pointer Java Solution

IntroductionLeetCode 1855 – Maximum Distance Between a Pair of Values is a classic problem that beautifully demonstrates the power of the Two Pointer technique on sorted (non-increasing) arrays.At first glance, it may feel like a brute-force problemβ€”but using the right observation, it can be solved efficiently in O(n) time.In this article, we will cover:Problem intuitionWhy brute force failsOptimized two-pointer approach (your solution)Alternative approachesTime complexity analysisπŸ”— Problem LinkLeetCode: Maximum Distance Between a Pair of ValuesProblem StatementYou are given two non-increasing arrays:nums1nums2A pair (i, j) is valid if:i <= jnums1[i] <= nums2[j]πŸ‘‰ Distance = j - iReturn the maximum distance among all valid pairs.ExamplesExample 1Input:nums1 = [55,30,5,4,2]nums2 = [100,20,10,10,5]Output:2Key InsightThe most important observation:Both arrays are NON-INCREASINGπŸ‘‰ This allows us to use two pointers efficiently instead of brute force.❌ Naive Approach (Brute Force)IdeaTry all (i, j) pairsCheck conditionsTrack maximumComplexityTime: O(n Γ— m) βŒπŸ‘‰ This will cause TLE for large inputs (up to 10⁡)βœ… Optimized Approach: Two PointersIntuitionUse two pointers:i β†’ nums1j β†’ nums2We try to:Expand j as far as possibleMove i only when necessaryKey LogicIf nums1[i] <= nums2[j] β†’ valid β†’ increase jElse β†’ move i forwardJava Codeclass Solution { public int maxDistance(int[] nums1, int[] nums2) { int i = 0; // pointer for nums1 int j = 0; // pointer for nums2 int max = Integer.MIN_VALUE; // Traverse both arrays while (i < nums1.length && j < nums2.length) { // Valid pair condition if (nums1[i] <= nums2[j] && i <= j) { // Update maximum distance max = Math.max(max, j - i); // Try to expand distance by moving j j++; } else if (nums1[i] >= nums2[j]) { // nums1[i] is too large β†’ move i forward i++; } else { // Just move j forward j++; } } // If no valid pair found, return 0 return max == Integer.MIN_VALUE ? 0 : max; }}Step-by-Step Dry RunInput:nums1 = [55,30,5,4,2]nums2 = [100,20,10,10,5]Execution:(0,0) β†’ valid β†’ distance = 0Move j β†’ (0,1) β†’ invalid β†’ move iContinue...Final best pair:(i = 2, j = 4) β†’ distance = 2Why This WorksArrays are sorted (non-increasing)Moving j increases distanceMoving i helps find valid pairsπŸ‘‰ No need to re-check previous elementsComplexity AnalysisTime ComplexityO(n + m)Each pointer moves at most once through the array.Space ComplexityO(1) (no extra space used)Alternative Approach: Binary SearchIdeaFor each i in nums1:Use binary search in nums2Find farthest j such that:nums2[j] >= nums1[i]ComplexityO(n log m)Code (Binary Search Approach)class Solution { public int maxDistance(int[] nums1, int[] nums2) { int max = 0; for (int i = 0; i < nums1.length; i++) { int left = i, right = nums2.length - 1; while (left <= right) { int mid = left + (right - left) / 2; if (nums2[mid] >= nums1[i]) { max = Math.max(max, mid - i); left = mid + 1; } else { right = mid - 1; } } } return max; }}Two Pointer vs Binary SearchApproachTimeSpaceTwo PointerO(n + m) βœ…O(1)Binary SearchO(n log m)O(1)πŸ‘‰ Two pointer is optimal hereKey TakeawaysUse two pointers when arrays are sortedAlways look for monotonic propertiesAvoid brute force when constraints are largeGreedy pointer movement can optimize drasticallyCommon Interview PatternsThis problem is related to:Two pointer problemsSliding windowBinary search on arraysGreedy expansionConclusionThe Maximum Distance Between a Pair of Values problem is a great example of how recognizing array properties can drastically simplify the solution.By using the two-pointer technique, we reduce complexity from O(nΒ²) to O(n)β€”a massive improvement.Frequently Asked Questions (FAQs)1. Why do we use two pointers?Because arrays are sorted, allowing linear traversal.2. Why not brute force?It is too slow for large inputs (10⁡).3. What is the best approach?πŸ‘‰ Two-pointer approach

MediumLeetCodeJavaArrayBinary SearchTwo Pointer
What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

Introduction β€” Why Dynamic Programming Feels Hard (And Why It Isn't)If you've ever stared at a LeetCode problem, read the solution, understood every single line, and still had absolutely no idea how someone arrived at it β€” welcome. You've just experienced the classic Dynamic Programming (DP) confusion.DP has a reputation. People treat it like some dark art reserved for competitive programmers or Google engineers. The truth? Dynamic Programming is one of the most logical, learnable, and satisfying techniques in all of computer science. Once it clicks, it really clicks.This guide will take you from zero to genuinely confident. We'll cover where DP came from, how it works, what patterns to learn, how to recognize DP problems, real-world places it shows up, LeetCode problems to practice, time complexity analysis, and the mistakes that trip up even experienced developers.Let's go.The Origin Story β€” Who Invented Dynamic Programming and Why?The term "Dynamic Programming" was coined by Richard Bellman in the early 1950s while working at RAND Corporation. Here's the funny part: the name was deliberately chosen to sound impressive and vague.Bellman was doing mathematical research that his employer β€” the US Secretary of Defense, Charles Wilson β€” would have found difficult to fund if described accurately. Wilson had a well-known distaste for the word "research." So Bellman invented a name that sounded suitably grand and mathematical: Dynamic Programming.In his autobiography, Bellman wrote that he picked the word "dynamic" because it had a precise technical meaning and was also impossible to use negatively. "Programming" referred to the mathematical sense β€” planning and decision-making β€” not computer programming.The underlying idea? Break a complex problem into overlapping subproblems, solve each subproblem once, and store the result so you never solve it twice.Bellman's foundational contribution was the Bellman Equation, which underpins not just algorithms but also economics, operations research, and modern reinforcement learning.So the next time DP feels frustrating, remember β€” even its inventor named it specifically to confuse people. You're in good company.What Is Dynamic Programming? (Simple Definition)Dynamic Programming is an algorithmic technique used to solve problems by:Breaking them down into smaller overlapping subproblemsSolving each subproblem only onceStoring the result (memoization or tabulation)Building up the final solution from those stored resultsThe key insight is overlapping subproblems + optimal substructure.Overlapping subproblems means the same smaller problems come up again and again. Instead of solving them every time (like plain recursion does), DP solves them once and caches the answer.Optimal substructure means the optimal solution to the whole problem can be built from optimal solutions to its subproblems.If a problem has both these properties β€” it's a DP problem.The Two Approaches to Dynamic Programming1. Top-Down with Memoization (Recursive + Cache)You write a recursive solution exactly as you would naturally, but add a cache (usually a dictionary or array) to store results you've already computed.fib(n):if n in cache: return cache[n]if n <= 1: return ncache[n] = fib(n-1) + fib(n-2)return cache[n]This is called memoization β€” remember what you computed so you don't repeat yourself.Pros: Natural to write, mirrors the recursive thinking, easy to reason about. Cons: Stack overhead from recursion, risk of stack overflow on large inputs.2. Bottom-Up with Tabulation (Iterative)You figure out the order in which subproblems need to be solved, then solve them iteratively from the smallest up, filling a table.fib(n):dp = [0, 1]for i from 2 to n:dp[i] = dp[i-1] + dp[i-2]return dp[n]This is called tabulation β€” fill a table, cell by cell, bottom to top.Pros: No recursion overhead, usually faster in practice, easier to optimize space. Cons: Requires thinking about the order of computation upfront.🧩 Dynamic Programming Template CodeBefore diving into how to recognize DP problems, here are ready-to-use Java templates for every major DP pattern. Think of these as your reusable blueprints β€” every DP problem you ever solve will fit into one of these structures. Just define your state, plug in your recurrence relation, and you are good to go.Template 1 β€” Top-Down (Memoization)import java.util.HashMap;import java.util.Map;public class TopDownDP {Map<Integer, Integer> memo = new HashMap<>();public int solve(int n) {// Base caseif (n <= 1) return n;// Check cacheif (memo.containsKey(n)) return memo.get(n);// Recurrence relation β€” change this part for your problemint result = solve(n - 1) + solve(n - 2);// Store in cachememo.put(n, result);return result;}}Template 2 β€” Bottom-Up (Tabulation)public class BottomUpDP {public int solve(int n) {// Create DP tableint[] dp = new int[n + 1];// Base casesdp[0] = 0;dp[1] = 1;// Fill the table bottom-upfor (int i = 2; i <= n; i++) {// Recurrence relation β€” change this part for your problemdp[i] = dp[i - 1] + dp[i - 2];}return dp[n];}}Template 3 β€” Bottom-Up with Space Optimizationpublic class SpaceOptimizedDP {public int solve(int n) {// Only keep last two values instead of full tableint prev2 = 0;int prev1 = 1;for (int i = 2; i <= n; i++) {// Recurrence relation β€” change this part for your problemint curr = prev1 + prev2;prev2 = prev1;prev1 = curr;}return prev1;}}Template 4 β€” 2D DP (Two Sequences or Grid)public class TwoDimensionalDP {public int solve(String s1, String s2) {int m = s1.length();int n = s2.length();// Create 2D DP tableint[][] dp = new int[m + 1][n + 1];// Base cases β€” first row and columnfor (int i = 0; i <= m; i++) dp[i][0] = i;for (int j = 0; j <= n; j++) dp[0][j] = j;// Fill table cell by cellfor (int i = 1; i <= m; i++) {for (int j = 1; j <= n; j++) {// Recurrence relation β€” change this part for your problemif (s1.charAt(i - 1) == s2.charAt(j - 1)) {dp[i][j] = dp[i - 1][j - 1];} else {dp[i][j] = 1 + Math.min(dp[i - 1][j],Math.min(dp[i][j - 1], dp[i - 1][j - 1]));}}}return dp[m][n];}}Template 5 β€” Knapsack Patternpublic class KnapsackDP {public int solve(int[] weights, int[] values, int capacity) {int n = weights.length;// dp[i][w] = max value using first i items with capacity wint[][] dp = new int[n + 1][capacity + 1];for (int i = 1; i <= n; i++) {for (int w = 0; w <= capacity; w++) {// Don't take item idp[i][w] = dp[i - 1][w];// Take item i if it fitsif (weights[i - 1] <= w) {dp[i][w] = Math.max(dp[i][w],values[i - 1] + dp[i - 1][w - weights[i - 1]]);}}}return dp[n][capacity];}}πŸ’‘ How to use these templates:Step 1 β€” Identify which pattern your problem fits into. Step 2 β€” Define what dp[i] or dp[i][j] means in plain English before writing any code. Step 3 β€” Write your recurrence relation on paper first. Step 4 β€” Plug it into the matching template above. Step 5 β€” Handle your specific base cases carefully.πŸŽ₯ Visual Learning Resource β€” Watch This Before Moving ForwardIf you prefer learning by watching before reading, this free full-length course by freeCodeCamp is one of the best Dynamic Programming resources on the internet. Watch it alongside this guide for maximum understanding.Credit: freeCodeCamp β€” a free, nonprofit coding education platform.How to Recognize a Dynamic Programming ProblemAsk yourself these four questions:1. Can I define the problem in terms of smaller versions of itself? If you can write a recursive formula (recurrence relation), DP might apply.2. Do the subproblems overlap? If a naive recursive solution would recompute the same thing many times, DP is the right tool.3. Is there an optimal substructure? Is the best answer to the big problem made up of best answers to smaller problems?4. Are you looking for a count, minimum, maximum, or yes/no answer? DP problems often ask: "What is the minimum cost?", "How many ways?", "Can we achieve X?"Red flag words in problem statements: minimum, maximum, shortest, longest, count the number of ways, can we reach, is it possible, fewest steps.The Core DP Patterns You Must LearnMastering DP is really about recognizing patterns. Here are the most important ones:Pattern 1 β€” 1D DP (Linear) Problems where the state depends on previous elements in a single sequence. Examples: Fibonacci, Climbing Stairs, House Robber.Pattern 2 β€” 2D DP (Grid / Two-sequence) Problems with two dimensions of state, often grids or two strings. Examples: Longest Common Subsequence, Edit Distance, Unique Paths.Pattern 3 β€” Interval DP You consider all possible intervals or subarrays and build solutions from them. Examples: Matrix Chain Multiplication, Burst Balloons, Palindrome Partitioning.Pattern 4 β€” Knapsack DP (0/1 and Unbounded) You decide whether to include or exclude items under a capacity constraint. Examples: 0/1 Knapsack, Coin Change, Partition Equal Subset Sum.Pattern 5 β€” DP on Trees State is defined per node; you combine results from children. Examples: Diameter of Binary Tree, House Robber III, Maximum Path Sum.Pattern 6 β€” DP on Subsets / Bitmask DP State includes a bitmask representing which elements have been chosen. Examples: Travelling Salesman Problem, Shortest Superstring.Pattern 7 β€” DP on Strings Matching, editing, or counting arrangements within strings. Examples: Longest Palindromic Subsequence, Regular Expression Matching, Wildcard Matching.Top LeetCode Problems to Practice Dynamic Programming (With Links)Here are the essential problems, organized by difficulty and pattern. Solve them in this order.Beginner β€” Warm UpProblemPatternLinkClimbing Stairs1D DPhttps://leetcode.com/problems/climbing-stairs/Fibonacci Number1D DPhttps://leetcode.com/problems/fibonacci-number/House Robber1D DPhttps://leetcode.com/problems/house-robber/Min Cost Climbing Stairs1D DPhttps://leetcode.com/problems/min-cost-climbing-stairs/Best Time to Buy and Sell Stock1D DPhttps://leetcode.com/problems/best-time-to-buy-and-sell-stock/Intermediate β€” Core PatternsProblemPatternLinkCoin ChangeKnapsackhttps://leetcode.com/problems/coin-change/Longest Increasing Subsequence1D DPhttps://leetcode.com/problems/longest-increasing-subsequence/Longest Common Subsequence2D DPhttps://leetcode.com/problems/longest-common-subsequence/0/1 Knapsack (via Subset Sum)Knapsackhttps://leetcode.com/problems/partition-equal-subset-sum/Unique Paths2D Grid DPhttps://leetcode.com/problems/unique-paths/Jump Game1D DP / Greedyhttps://leetcode.com/problems/jump-game/Word BreakString DPhttps://leetcode.com/problems/word-break/Decode Ways1D DPhttps://leetcode.com/problems/decode-ways/Edit Distance2D String DPhttps://leetcode.com/problems/edit-distance/Triangle2D DPhttps://leetcode.com/problems/triangle/Advanced β€” Interview LevelProblemPatternLinkBurst BalloonsInterval DPhttps://leetcode.com/problems/burst-balloons/Regular Expression MatchingString DPhttps://leetcode.com/problems/regular-expression-matching/Wildcard MatchingString DPhttps://leetcode.com/problems/wildcard-matching/Palindrome Partitioning IIInterval DPhttps://leetcode.com/problems/palindrome-partitioning-ii/Maximum Profit in Job SchedulingDP + Binary Searchhttps://leetcode.com/problems/maximum-profit-in-job-scheduling/Distinct Subsequences2D DPhttps://leetcode.com/problems/distinct-subsequences/Cherry Pickup3D DPhttps://leetcode.com/problems/cherry-pickup/Real-World Use Cases of Dynamic ProgrammingDP is not just for coding interviews. It is deeply embedded in the technology you use every day.1. Google Maps & Navigation (Shortest Path) The routing engines behind GPS apps use DP-based algorithms like Dijkstra and Bellman-Ford to find the shortest or fastest path between two points across millions of nodes.2. Spell Checkers & Autocorrect (Edit Distance) When your phone corrects "teh" to "the," it is computing Edit Distance β€” a classic DP problem β€” between what you typed and every word in the dictionary.3. DNA Sequence Alignment (Bioinformatics) Researchers use the Needleman-Wunsch and Smith-Waterman algorithms β€” both DP β€” to align DNA and protein sequences and find similarities between species or identify mutations.4. Video Compression (MPEG, H.264) Modern video codecs use DP to determine the most efficient way to encode video frames, deciding which frames to store as full images and which to store as differences from the previous frame.5. Financial Portfolio Optimization Investment algorithms use DP to find the optimal allocation of assets under risk constraints β€” essentially a variant of the knapsack problem.6. Natural Language Processing (NLP) The Viterbi algorithm β€” used in speech recognition, part-of-speech tagging, and machine translation β€” is a DP algorithm. Every time Siri or Google Assistant understands your sentence, DP played a role.7. Game AI (Chess, Checkers) Game trees and minimax algorithms with memoization use DP to evaluate board positions and find the best move without recomputing already-seen positions.8. Compiler Optimization Compilers use DP to decide the optimal order of operations and instruction scheduling to generate the most efficient machine code.9. Text Justification (Word Processors) Microsoft Word and LaTeX use DP to optimally break paragraphs into lines β€” minimizing raggedness and maximizing visual appeal.10. Resource Scheduling in Cloud Computing AWS, Google Cloud, and Azure use DP-based scheduling to assign computational tasks to servers in the most cost-efficient way possible.Time Complexity Analysis of Common DP ProblemsUnderstanding the time complexity of DP is critical for interviews and for building scalable systems.ProblemTime ComplexitySpace ComplexityNotesFibonacci (naive recursion)O(2ⁿ)O(n)Exponential β€” terribleFibonacci (DP)O(n)O(1) with optimizationLinear β€” excellentLongest Common SubsequenceO(m Γ— n)O(m Γ— n)m, n = lengths of two stringsEdit DistanceO(m Γ— n)O(m Γ— n)Can optimize space to O(n)0/1 KnapsackO(n Γ— W)O(n Γ— W)n = items, W = capacityCoin ChangeO(n Γ— amount)O(amount)Classic tabulationLongest Increasing SubsequenceO(nΒ²) or O(n log n)O(n)Binary search version is fasterMatrix Chain MultiplicationO(nΒ³)O(nΒ²)Interval DPTravelling Salesman (bitmask)O(2ⁿ Γ— nΒ²)O(2ⁿ Γ— n)Still exponential but manageable for small nThe general rule: DP trades time for space. You use memory to avoid recomputation. The time complexity equals the number of unique states multiplied by the work done per state.How to Learn and Master Dynamic Programming β€” Step by StepHere is an honest, structured path to mastery:Step 1 β€” Get recursion absolutely solid first. DP is memoized recursion at its core. If you cannot write clean recursive solutions confidently, DP will remain confusing. Practice at least 20 pure recursion problems first.Step 2 β€” Start with the classics. Fibonacci β†’ Climbing Stairs β†’ House Robber β†’ Coin Change. These teach you the core pattern of defining state and transition without overwhelming you.Step 3 β€” Learn to define state explicitly. Before writing any code, ask: "What does dp[i] represent?" Write it in plain English. "dp[i] = the minimum cost to reach step i." This single habit separates good DP thinkers from struggling ones.Step 4 β€” Write the recurrence relation before coding. On paper or in a comment. Example: dp[i] = min(dp[i-1] + cost[i-1], dp[i-2] + cost[i-2]). If you can write the recurrence, the code writes itself.Step 5 β€” Master one pattern at a time. Don't jump between knapsack and interval DP in the same week. Spend a few days on each pattern until it feels intuitive.Step 6 β€” Solve the same problem both ways. Top-down and bottom-up. This builds deep understanding of what DP is actually doing.Step 7 β€” Optimize space after getting correctness. Many 2D DP solutions can use a single row instead of a full matrix. Learn this optimization after you understand the full solution.Step 8 β€” Do timed practice under interview conditions. Give yourself 35 minutes per problem. Review what you got wrong. DP is a muscle β€” it builds with reps.Common Mistakes in Dynamic Programming (And How to Avoid Them)Mistake 1 β€” Jumping to code before defining state. The most common DP error. Always define what dp[i] or dp[i][j] means before writing a single line of code.Mistake 2 β€” Wrong base cases. A single wrong base case corrupts every answer built on top of it. Trace through your base cases manually on a tiny example before running code.Mistake 3 β€” Off-by-one errors in indexing. Whether your dp array is 0-indexed or 1-indexed must be 100% consistent throughout. This causes more bugs in DP than almost anything else.Mistake 4 β€” Confusing top-down with bottom-up state order. In bottom-up DP, you must ensure that when you compute dp[i], all values it depends on are already filled. If you compute in the wrong order, you get garbage answers.Mistake 5 β€” Memoizing in the wrong dimension. In 2D problems, some people cache only one dimension when the state actually requires two. Always identify all variables that affect the outcome.Mistake 6 β€” Using global mutable state in recursion. If you use a shared array and don't clear it between test cases, you'll get wrong answers on subsequent inputs. Always scope your cache correctly.Mistake 7 β€” Not considering the full state space. In problems like Knapsack, forgetting that the state is (item index, remaining capacity) β€” not just item index β€” leads to fundamentally wrong solutions.Mistake 8 β€” Giving up after not recognizing the pattern immediately. DP problems don't announce themselves. The skill is learning to ask "is there overlapping subproblems here?" on every problem. This takes time. Don't mistake unfamiliarity for inability.Frequently Asked Questions About Dynamic ProgrammingQ: Is Dynamic Programming the same as recursion? Not exactly. Recursion is a technique for breaking problems into smaller pieces. DP is recursion plus memoization β€” or iterative tabulation. All DP can be written recursively, but not all recursion is DP.Q: What is the difference between DP and Divide and Conquer? Divide and Conquer (like Merge Sort) breaks problems into non-overlapping subproblems. DP is used when subproblems overlap β€” meaning the same subproblem is solved multiple times in a naive approach.Q: How do I know when NOT to use DP? If the subproblems don't overlap (no repeated computation), greedy or divide-and-conquer may be better. If the problem has no optimal substructure, DP won't give a correct answer.Q: Do I need to memorize DP solutions for interviews? No. You need to recognize patterns and be able to derive the recurrence relation. Memorizing solutions without understanding them will fail you in interviews. Focus on the thinking process.Q: How long does it take to get good at DP? Most people start to feel genuinely comfortable after solving 40–60 varied DP problems with deliberate practice. The first 10 feel impossible. The next 20 feel hard. After 50, patterns start feeling obvious.Q: What programming language is best for DP? Any language works. Python is often used for learning because its dictionaries make memoization trivial. C++ is preferred in competitive programming for its speed. For interviews, use whatever language you're most comfortable in.Q: What is space optimization in DP? Many DP problems only look back one or two rows to compute the current row. In those cases, you can replace an nΓ—m table with just two arrays (or even one), reducing space complexity from O(nΓ—m) to O(m). This is called space optimization or rolling array technique.Q: Can DP be applied to graph problems? Absolutely. Shortest path algorithms like Bellman-Ford are DP. Longest path in a DAG is DP. DP on trees is a rich subfield. Anywhere you have states and transitions, DP can potentially apply.Q: Is Greedy a type of Dynamic Programming? Greedy is related but distinct. Greedy makes locally optimal choices without reconsidering. DP considers all choices and picks the globally optimal one. Some DP solutions reduce to greedy when the structure allows, but they are different techniques.Q: What resources should I use to learn DP? For structured learning: Neetcode.io (organized problem list), Striver's DP Series on YouTube, and the book "Introduction to Algorithms" (CLRS) for theoretical depth. For practice: LeetCode's Dynamic Programming study plan and Codeforces for competitive DP.Final Thoughts β€” Dynamic Programming Is a SuperpowerDynamic Programming is genuinely one of the most powerful ideas in computer science. It shows up in your GPS, your autocorrect, your streaming video, your bank's risk models, and the AI assistants you talk to daily.The path to mastering it is not memorization. It is developing the habit of asking: can I break this into smaller problems that overlap? And then learning to define state clearly, write the recurrence, and trust the process.Start with Climbing Stairs. Write dp[i] in plain English before every problem. Solve everything twice β€” top-down and bottom-up. Do 50 problems with genuine reflection, not just accepted solutions.The click moment will come. And when it does, you'll wonder why it ever felt hard.

Dynamic ProgrammingMemoizationTabulationJavaOrigin StoryRichard Bellman
Stack Data Structure in Java: The Complete In-Depth Guide

Stack Data Structure in Java: The Complete In-Depth Guide

1. What Is a Stack?A Stack is a linear data structure that stores elements in a sequential order, but with one strict rule β€” you can only insert or remove elements from one end, called the top.It is one of the simplest yet most powerful data structures in computer science. Its strength comes from its constraint. Because everything happens at one end, the behavior of a stack is completely predictable.The formal definition: A Stack is a linear data structure that follows the Last In, First Out (LIFO) principle β€” the element inserted last is the first one to be removed.Here is what a stack looks like visually: β”Œβ”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β” β”‚ 50 β”‚ ← TOP (last inserted, first removed) β”œβ”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β”€ β”‚ 40 β”‚ β”œβ”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β”€ β”‚ 30 β”‚ β”œβ”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β”€ β”‚ 20 β”‚ β”œβ”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β”€ β”‚ 10 β”‚ ← BOTTOM (first inserted, last removed) β””β”€β”€β”€β”€β”€β”€β”€β”€β”€β”€β”˜When you push 60 onto this stack, it goes on top. When you pop, 60 comes out first. That is LIFO.2. Real-World AnalogiesBefore writing a single line of code, it helps to see stacks in the real world. These analogies will make the concept permanently stick.A Pile of Plates In a cafeteria, clean plates are stacked on top of each other. You always pick the top plate. You always place a new plate on top. You never reach into the middle. This is a stack.Browser Back Button Every time you visit a new webpage, it gets pushed onto a history stack. When you press the Back button, the browser pops the most recent page off the stack and takes you there. The page you visited first is at the bottom β€” you only reach it after going back through everything else.Undo Feature in Text Editors When you type in a document and press Ctrl+Z, the most recent action is undone first. That is because every action you perform is pushed onto a stack. Undo simply pops from that stack.Call Stack in Programming When a function calls another function, the current function's state is pushed onto the call stack. When the inner function finishes, it is popped off and execution returns to the outer function. This is the literal stack your programs run on.A Stack of Books Put five books on a table, one on top of another. You can only take the top book without knocking the pile over. That is a stack.3. The LIFO Principle ExplainedLIFO stands for Last In, First Out.It means whatever you put in last is the first thing to come out. This is the exact opposite of a Queue (which is FIFO β€” First In, First Out).Let us trace through an example step by step:Start: Stack is empty β†’ []Push 10 β†’ [10] (10 is at the top)Push 20 β†’ [10, 20] (20 is at the top)Push 30 β†’ [10, 20, 30] (30 is at the top)Pop β†’ returns 30 (30 was last in, first out) Stack: [10, 20]Pop β†’ returns 20 Stack: [10]Peek β†’ returns 10 (just looks, does not remove) Stack: [10]Pop β†’ returns 10 Stack: [] (stack is now empty)Every single operation happens only at the top. The bottom of the stack is never directly accessible.4. Stack Operations & Time ComplexityA stack supports the following core operations:OperationDescriptionTime Complexitypush(x)Insert element x onto the top of the stackO(1)pop()Remove and return the top elementO(1)peek() / top()Return the top element without removing itO(1)isEmpty()Check if the stack has no elementsO(1)isFull()Check if the stack has reached its capacity (Array only)O(1)size()Return the number of elements in the stackO(1)search(x)Find position of element from top (Java built-in only)O(n)All primary stack operations β€” push, pop, peek, isEmpty β€” run in O(1) constant time. This is what makes the stack so efficient. It does not matter whether the stack has 10 elements or 10 million β€” these operations are always instant.Space complexity for a stack holding n elements is O(n).5. Implementation 1 β€” Using a Static ArrayThis is the most fundamental way to implement a stack. We use a fixed-size array and a variable called top to track where the top of the stack currently is.How it works:top starts at -1 (stack is empty)On push: increment top, then place the element at arr[top]On pop: return arr[top], then decrement topOn peek: return arr[top] without changing it// StackUsingArray.javapublic class StackUsingArray { private int[] arr; private int top; private int capacity; // Constructor β€” initialize with a fixed capacity public StackUsingArray(int capacity) { this.capacity = capacity; arr = new int[capacity]; top = -1; } // Push: add element to the top public void push(int value) { if (isFull()) { System.out.println("Stack Overflow! Cannot push " + value); return; } arr[++top] = value; System.out.println("Pushed: " + value); } // Pop: remove and return top element public int pop() { if (isEmpty()) { System.out.println("Stack Underflow! Stack is empty."); return -1; } return arr[top--]; } // Peek: view the top element without removing public int peek() { if (isEmpty()) { System.out.println("Stack is empty."); return -1; } return arr[top]; } // Check if stack is empty public boolean isEmpty() { return top == -1; } // Check if stack is full public boolean isFull() { return top == capacity - 1; } // Return current size public int size() { return top + 1; } // Display all elements public void display() { if (isEmpty()) { System.out.println("Stack is empty."); return; } System.out.print("Stack (top β†’ bottom): "); for (int i = top; i >= 0; i--) { System.out.print(arr[i] + " "); } System.out.println(); } // Main method to test public static void main(String[] args) { StackUsingArray stack = new StackUsingArray(5); stack.push(10); stack.push(20); stack.push(30); stack.push(40); stack.push(50); stack.push(60); // This will trigger Stack Overflow stack.display(); System.out.println("Peek: " + stack.peek()); System.out.println("Pop: " + stack.pop()); System.out.println("Pop: " + stack.pop()); stack.display(); System.out.println("Size: " + stack.size()); }}```**Output:**```Pushed: 10Pushed: 20Pushed: 30Pushed: 40Pushed: 50Stack Overflow! Cannot push 60Stack (top β†’ bottom): 50 40 30 20 10Peek: 50Pop: 50Pop: 40Stack (top β†’ bottom): 30 20 10Size: 3Key Points about Array Implementation:Fixed size β€” you must declare capacity upfrontVery fast β€” direct array index accessStack Overflow is possible if capacity is exceededMemory is pre-allocated even if stack is not full6. Implementation 2 β€” Using an ArrayListAn ArrayList-based stack removes the fixed-size limitation. The ArrayList grows dynamically, so you never have to worry about stack overflow due to capacity.How it works:The end of the ArrayList acts as the topadd() is used for pushremove(size - 1) is used for popget(size - 1) is used for peek// StackUsingArrayList.javaimport java.util.ArrayList;public class StackUsingArrayList { private ArrayList<Integer> list; // Constructor public StackUsingArrayList() { list = new ArrayList<>(); } // Push: add to the end (which is our top) public void push(int value) { list.add(value); System.out.println("Pushed: " + value); } // Pop: remove and return the last element public int pop() { if (isEmpty()) { System.out.println("Stack Underflow! Stack is empty."); return -1; } int top = list.get(list.size() - 1); list.remove(list.size() - 1); return top; } // Peek: view the last element public int peek() { if (isEmpty()) { System.out.println("Stack is empty."); return -1; } return list.get(list.size() - 1); } // Check if stack is empty public boolean isEmpty() { return list.isEmpty(); } // Return size public int size() { return list.size(); } // Display elements from top to bottom public void display() { if (isEmpty()) { System.out.println("Stack is empty."); return; } System.out.print("Stack (top β†’ bottom): "); for (int i = list.size() - 1; i >= 0; i--) { System.out.print(list.get(i) + " "); } System.out.println(); } // Main method to test public static void main(String[] args) { StackUsingArrayList stack = new StackUsingArrayList(); stack.push(5); stack.push(15); stack.push(25); stack.push(35); stack.display(); System.out.println("Peek: " + stack.peek()); System.out.println("Pop: " + stack.pop()); System.out.println("Pop: " + stack.pop()); stack.display(); System.out.println("Is Empty: " + stack.isEmpty()); System.out.println("Size: " + stack.size()); }}```**Output:**```Pushed: 5Pushed: 15Pushed: 25Pushed: 35Stack (top β†’ bottom): 35 25 15 5Peek: 35Pop: 35Pop: 25Stack (top β†’ bottom): 15 5Is Empty: falseSize: 2Key Points about ArrayList Implementation:Dynamic size β€” grows automatically as neededNo overflow riskSlight overhead compared to raw array due to ArrayList internalsExcellent for most practical use cases7. Implementation 3 β€” Using a LinkedListA LinkedList-based stack is the most memory-efficient approach when you do not know the stack size in advance. Each element (node) holds data and a pointer to the next node. The head of the LinkedList acts as the top of the stack.How it works:Each node stores a value and a reference to the node below itPush creates a new node and makes it the new headPop removes the head node and returns its valuePeek returns the head node's value without removing it// StackUsingLinkedList.javapublic class StackUsingLinkedList { // Inner Node class private static class Node { int data; Node next; Node(int data) { this.data = data; this.next = null; } } private Node top; // Head of the linked list = top of stack private int size; // Constructor public StackUsingLinkedList() { top = null; size = 0; } // Push: create new node and link it to top public void push(int value) { Node newNode = new Node(value); newNode.next = top; // new node points to current top top = newNode; // new node becomes the new top size++; System.out.println("Pushed: " + value); } // Pop: remove and return top node's data public int pop() { if (isEmpty()) { System.out.println("Stack Underflow! Stack is empty."); return -1; } int value = top.data; top = top.next; // move top pointer to next node size--; return value; } // Peek: return top node's data without removing public int peek() { if (isEmpty()) { System.out.println("Stack is empty."); return -1; } return top.data; } // Check if empty public boolean isEmpty() { return top == null; } // Return size public int size() { return size; } // Display elements from top to bottom public void display() { if (isEmpty()) { System.out.println("Stack is empty."); return; } System.out.print("Stack (top β†’ bottom): "); Node current = top; while (current != null) { System.out.print(current.data + " "); current = current.next; } System.out.println(); } // Main method to test public static void main(String[] args) { StackUsingLinkedList stack = new StackUsingLinkedList(); stack.push(100); stack.push(200); stack.push(300); stack.push(400); stack.display(); System.out.println("Peek: " + stack.peek()); System.out.println("Pop: " + stack.pop()); System.out.println("Pop: " + stack.pop()); stack.display(); System.out.println("Size: " + stack.size()); }}```**Output:**```Pushed: 100Pushed: 200Pushed: 300Pushed: 400Stack (top β†’ bottom): 400 300 200 100Peek: 400Pop: 400Pop: 300Stack (top β†’ bottom): 200 100Size: 2Key Points about LinkedList Implementation:Truly dynamic β€” each node allocated only when neededNo wasted memory from pre-allocationSlightly more memory per element (each node carries a pointer)Ideal for stacks where size is completely unknown8. Java's Built-in Stack ClassJava provides a ready-made Stack class inside java.util. It extends Vector and is thread-safe by default.// JavaBuiltinStack.javaimport java.util.Stack;public class JavaBuiltinStack { public static void main(String[] args) { Stack<Integer> stack = new Stack<>(); // Push elements stack.push(10); stack.push(20); stack.push(30); stack.push(40); System.out.println("Stack: " + stack); // Peek β€” look at top without removing System.out.println("Peek: " + stack.peek()); // Pop β€” remove top System.out.println("Pop: " + stack.pop()); System.out.println("After pop: " + stack); // Search β€” returns 1-based position from top System.out.println("Search 20: position " + stack.search(20)); // isEmpty System.out.println("Is Empty: " + stack.isEmpty()); // Size System.out.println("Size: " + stack.size()); }}```**Output:**```Stack: [10, 20, 30, 40]Peek: 40Pop: 40After pop: [10, 20, 30]Search 20: position 2Is Empty: falseSize: 3Important Note: In modern Java development, it is often recommended to use Deque (specifically ArrayDeque) instead of Stack for better performance, since Stack is synchronized and carries the overhead of Vector.// Using ArrayDeque as a stack (modern preferred approach)import java.util.ArrayDeque;import java.util.Deque;public class ModernStack { public static void main(String[] args) { Deque<Integer> stack = new ArrayDeque<>(); stack.push(10); // pushes to front stack.push(20); stack.push(30); System.out.println("Top: " + stack.peek()); System.out.println("Pop: " + stack.pop()); System.out.println("Stack: " + stack); }}9. Comparison of All ImplementationsFeatureArrayArrayListLinkedListJava StackArrayDequeSizeFixedDynamicDynamicDynamicDynamicStack Overflow RiskYesNoNoNoNoMemory UsagePre-allocatedAuto-growsPer-node overheadAuto-growsAuto-growsPush TimeO(1)O(1) amortizedO(1)O(1)O(1)Pop TimeO(1)O(1)O(1)O(1)O(1)Peek TimeO(1)O(1)O(1)O(1)O(1)Thread SafeNoNoNoYesNoBest ForKnown size, max speedGeneral useUnknown/huge sizeLegacy codeModern Java10. Advantages & DisadvantagesAdvantagesAdvantageExplanationSimple to implementVery few rules and operations to worry aboutO(1) operationsPush, pop, and peek are all constant timeMemory efficientNo extra pointers needed (array-based)Supports recursionThe call stack is itself a stackEasy undo/redoNatural fit for reversible action trackingBacktrackingPerfectly suited for maze, puzzle, and game solvingExpression evaluationPowers compilers and calculatorsDisadvantagesDisadvantageExplanationLimited accessCannot access elements in the middle directlyFixed size (array)Array-based stacks overflow if size is exceededNo random accessYou cannot do stack[2] β€” only top is accessibleMemory waste (array)Pre-allocated array wastes space if underusedNot suitable for all problemsMany problems need queues, trees, or graphs insteadStack overflow in recursionVery deep recursion can overflow the JVM call stack11. Real-World Use Cases of StackUnderstanding when to use a stack is just as important as knowing how to implement one. Here is where stacks show up in real software:Function Call Management (Call Stack) Every time your Java program calls a method, the JVM pushes that method's frame onto the call stack. When the method returns, the frame is popped. This is why you see "StackOverflowError" when you write infinite recursion.Undo and Redo Operations Text editors, image editors (Photoshop), and IDEs use two stacks β€” one for undo history and one for redo history. Every action pushes onto the undo stack. Ctrl+Z pops from it and pushes to the redo stack.Browser Navigation Your browser maintains a back-stack and a forward-stack. Visiting a new page pushes to the back-stack. Pressing Back pops from it and pushes to the forward-stack.Expression Evaluation and Conversion Compilers use stacks to evaluate arithmetic expressions and convert between infix, prefix, and postfix notations. For example: 3 + 4 * 2 must be evaluated considering operator precedence β€” this is done with a stack.Balanced Parentheses Checking Linters, compilers, and IDEs use stacks to check if brackets are balanced: {[()]} is valid, {[(])} is not.Backtracking Algorithms Maze solving, N-Queens, Sudoku solvers, and depth-first search all use stacks (explicitly or via recursion) to backtrack to previous states when a path fails.Syntax Parsing Compilers parse source code using stacks to match opening and closing constructs like if/else, try/catch, { and }.12. Practice Problems with Full SolutionsHere is where things get really interesting. These problems will sharpen your stack intuition and prepare you for coding interviews.Problem 1 β€” Reverse a String Using a StackDifficulty: EasyProblem: Write a Java program to reverse a string using a Stack.Approach: Push every character of the string onto a stack, then pop them all. Since LIFO reverses the order, the characters come out reversed.// ReverseString.javaimport java.util.Stack;public class ReverseString { public static String reverse(String str) { Stack<Character> stack = new Stack<>(); // Push all characters for (char c : str.toCharArray()) { stack.push(c); } // Pop all characters to build reversed string StringBuilder reversed = new StringBuilder(); while (!stack.isEmpty()) { reversed.append(stack.pop()); } return reversed.toString(); } public static void main(String[] args) { System.out.println(reverse("hello")); // olleh System.out.println(reverse("java")); // avaj System.out.println(reverse("racecar")); // racecar (palindrome) System.out.println(reverse("datastructure")); // erutcurtasatad }}Problem 2 β€” Check Balanced ParenthesesDifficulty: Easy–MediumProblem: Given a string containing (, ), {, }, [, ], determine if the brackets are balanced.Approach: Push every opening bracket onto the stack. When you see a closing bracket, check if it matches the top of the stack. If it does, pop. If it does not, the string is unbalanced.// BalancedParentheses.javaimport java.util.Stack;public class BalancedParentheses { public static boolean isBalanced(String expr) { Stack<Character> stack = new Stack<>(); for (char c : expr.toCharArray()) { // Push all opening brackets if (c == '(' || c == '{' || c == '[') { stack.push(c); } // For closing brackets, check the top of stack else if (c == ')' || c == '}' || c == ']') { if (stack.isEmpty()) return false; char top = stack.pop(); if (c == ')' && top != '(') return false; if (c == '}' && top != '{') return false; if (c == ']' && top != '[') return false; } } // Stack must be empty at the end for a balanced expression return stack.isEmpty(); } public static void main(String[] args) { System.out.println(isBalanced("{[()]}")); // true System.out.println(isBalanced("{[(])}")); // false System.out.println(isBalanced("((()))")); // true System.out.println(isBalanced("{]")); // false System.out.println(isBalanced("")); // true (empty is balanced) }}Problem 3 β€” Reverse a Stack (Without Extra Data Structure)Difficulty: Medium–HardProblem: Reverse all elements of a stack using only recursion β€” no array or extra stack allowed.Approach: This is a classic recursion problem. You need two recursive functions:insertAtBottom(stack, item) β€” inserts an element at the very bottom of the stackreverseStack(stack) β€” pops all elements, reverses, and uses insertAtBottom to rebuild// ReverseStack.javaimport java.util.Stack;public class ReverseStack { // Insert an element at the bottom of the stack public static void insertAtBottom(Stack<Integer> stack, int item) { if (stack.isEmpty()) { stack.push(item); return; } int top = stack.pop(); insertAtBottom(stack, item); stack.push(top); } // Reverse the stack using insertAtBottom public static void reverseStack(Stack<Integer> stack) { if (stack.isEmpty()) return; int top = stack.pop(); reverseStack(stack); // reverse the remaining stack insertAtBottom(stack, top); // insert popped element at bottom } public static void main(String[] args) { Stack<Integer> stack = new Stack<>(); stack.push(1); stack.push(2); stack.push(3); stack.push(4); stack.push(5); System.out.println("Before: " + stack); // [1, 2, 3, 4, 5] reverseStack(stack); System.out.println("After: " + stack); // [5, 4, 3, 2, 1] }}Problem 4 β€” Evaluate a Postfix ExpressionDifficulty: MediumProblem: Evaluate a postfix (Reverse Polish Notation) expression. Example: "2 3 4 * +" should return 14 because it is 2 + (3 * 4).Approach: Scan left to right. If you see a number, push it. If you see an operator, pop two numbers, apply the operator, and push the result.// PostfixEvaluation.javaimport java.util.Stack;public class PostfixEvaluation { public static int evaluate(String expression) { Stack<Integer> stack = new Stack<>(); String[] tokens = expression.split(" "); for (String token : tokens) { // If it's a number, push it if (token.matches("-?\\d+")) { stack.push(Integer.parseInt(token)); } // If it's an operator, pop two and apply else { int b = stack.pop(); // second operand int a = stack.pop(); // first operand switch (token) { case "+": stack.push(a + b); break; case "-": stack.push(a - b); break; case "*": stack.push(a * b); break; case "/": stack.push(a / b); break; } } } return stack.pop(); } public static void main(String[] args) { System.out.println(evaluate("2 3 4 * +")); // 14 β†’ 2 + (3*4) System.out.println(evaluate("5 1 2 + 4 * + 3 -")); // 14 β†’ 5+((1+2)*4)-3 System.out.println(evaluate("3 4 +")); // 7 }}Problem 5 β€” Next Greater ElementDifficulty: MediumProblem: For each element in an array, find the next greater element to its right. If none exists, output -1.Example: Input: [4, 5, 2, 10, 8] β†’ Output: [5, 10, 10, -1, -1]Approach: Iterate right to left. Maintain a stack of candidates. For each element, pop all stack elements that are smaller than or equal to it β€” they can never be the answer for any element to the left. The top of the stack (if not empty) is the next greater element.// NextGreaterElement.javaimport java.util.Stack;import java.util.Arrays;public class NextGreaterElement { public static int[] nextGreater(int[] arr) { int n = arr.length; int[] result = new int[n]; Stack<Integer> stack = new Stack<>(); // stores elements, not indices // Traverse from right to left for (int i = n - 1; i >= 0; i--) { // Pop elements smaller than or equal to current while (!stack.isEmpty() && stack.peek() <= arr[i]) { stack.pop(); } // Next greater element result[i] = stack.isEmpty() ? -1 : stack.peek(); // Push current element for future comparisons stack.push(arr[i]); } return result; } public static void main(String[] args) { int[] arr1 = {4, 5, 2, 10, 8}; System.out.println(Arrays.toString(nextGreater(arr1))); // [5, 10, 10, -1, -1] int[] arr2 = {1, 3, 2, 4}; System.out.println(Arrays.toString(nextGreater(arr2))); // [3, 4, 4, -1] int[] arr3 = {5, 4, 3, 2, 1}; System.out.println(Arrays.toString(nextGreater(arr3))); // [-1, -1, -1, -1, -1] }}Problem 6 β€” Sort a Stack Using RecursionDifficulty: HardProblem: Sort a stack in ascending order (smallest on top) using only recursion β€” no loops, no extra data structure.// SortStack.javaimport java.util.Stack;public class SortStack { // Insert element in correct sorted position public static void sortedInsert(Stack<Integer> stack, int item) { if (stack.isEmpty() || item > stack.peek()) { stack.push(item); return; } int top = stack.pop(); sortedInsert(stack, item); stack.push(top); } // Sort the stack public static void sortStack(Stack<Integer> stack) { if (stack.isEmpty()) return; int top = stack.pop(); sortStack(stack); // sort remaining sortedInsert(stack, top); // insert top in sorted position } public static void main(String[] args) { Stack<Integer> stack = new Stack<>(); stack.push(34); stack.push(3); stack.push(31); stack.push(98); stack.push(92); stack.push(23); System.out.println("Before sort: " + stack); sortStack(stack); System.out.println("After sort: " + stack); // smallest on top }}13. Summary & Key TakeawaysA stack is a simple, elegant, and powerful data structure. Here is everything in one place:What it is: A linear data structure that follows LIFO β€” Last In, First Out.Core operations: push (add to top), pop (remove from top), peek (view top), isEmpty β€” all in O(1) time.Three ways to implement it in Java:Array-based: fast, fixed size, risk of overflowArrayList-based: dynamic, easy, slightly more overheadLinkedList-based: truly dynamic, memory-efficient per-element, best for unknown sizesWhen to use it:Undo/redo systemsBrowser navigationBalancing brackets and parenthesesEvaluating mathematical expressionsBacktracking problemsManaging recursive function callsDepth-first searchWhen NOT to use it:When you need random access to elementsWhen insertion/deletion is needed from both ends (use Deque)When you need to search efficiently (use HashMap or BST)Modern Java recommendation: Prefer ArrayDeque over the legacy Stack class for non-thread-safe scenarios. Use Stack only when you need synchronized access.The stack is one of those data structures that once you truly understand, you start seeing it everywhere β€” in your browser, in your IDE, in recursive algorithms, and deep within the operating system itself.This article covered everything from the fundamentals of the Stack data structure to multiple Java implementations, time complexity analysis, real-world applications, and six practice problems of increasing difficulty. Bookmark it as a reference and revisit the practice problems regularly β€” they are the real test of your understanding.

DataStructuresJavaStackDataStructureLIFO
Find Peak Element – Binary Search Explained with Java Solution (LeetCode 162)

Find Peak Element – Binary Search Explained with Java Solution (LeetCode 162)

Try the QuestionBefore reading the explanation, try solving the problem yourself:πŸ‘‰ https://leetcode.com/problems/find-peak-element/Attempting the problem first helps develop algorithmic intuition, especially for binary search problems.Problem StatementYou are given a 0-indexed integer array nums.Your task is to find the index of a peak element.What is a Peak Element?A peak element is an element that is strictly greater than its immediate neighbors.For an element nums[i] to be a peak:nums[i] > nums[i-1]nums[i] > nums[i+1]However, the array boundaries have a special rule.Boundary RuleYou can imagine that:nums[-1] = -∞nums[n] = -∞This means:The first element only needs to be greater than the second element.The last element only needs to be greater than the second last element.Constraints1 <= nums.length <= 1000-2^31 <= nums[i] <= 2^31 - 1nums[i] != nums[i + 1] for all valid iImportant implications:Adjacent elements are never equal.The array always has at least one peak.Understanding the Problem with ExamplesExample 1Inputnums = [1,2,3,1]Visualization1 2 3 1^Here:3 > 23 > 1So 3 is a peak element.Output2(index of value 3)Example 2Inputnums = [1,2,1,3,5,6,4]Visualization1 2 1 3 5 6 4^ ^Possible peaks:26Valid outputs:1 or 5Either peak index is acceptable.Key ObservationsImportant facts about peak elements:Every array must contain at least one peak.If numbers keep increasing, the last element will be a peak.If numbers keep decreasing, the first element will be a peak.If the array has ups and downs, peaks exist in the middle.This guarantees a solution exists.Approach 1 β€” Linear Scan (Brute Force)The simplest approach is to check each element and see whether it satisfies the peak condition.AlgorithmTraverse the array.Check if the current element is greater than neighbors.Return the index if found.Examplenums = [1,2,3,1]Check:1 < 22 < 33 > 2 and 3 > 1 β†’ PeakImplementationpublic int findPeakElement(int[] nums) {for(int i = 0; i < nums.length; i++){boolean left = (i == 0) || nums[i] > nums[i-1];boolean right = (i == nums.length-1) || nums[i] > nums[i+1];if(left && right){return i;}}return -1;}Time ComplexityO(n)Space ComplexityO(1)Although simple, this solution does not satisfy the required O(log n) complexity.Approach 2 β€” Binary Search Using Peak ConditionsInstead of scanning the entire array, we can use binary search.Key IdeaIf we are at index mid, compare it with the neighbors.Three situations may occur.Case 1 β€” Peak Foundnums[mid-1] < nums[mid] > nums[mid+1]Then:mid is the peakCase 2 β€” Increasing Slopenums[mid] < nums[mid+1]Example:1 3 5 7^This means the peak must exist on the right side.Move search to the right.Case 3 β€” Decreasing Slopenums[mid] < nums[mid-1]Example:7 5 3 1^Peak exists on the left side.Move search to the left.Implementationint i = 1;int j = nums.length - 2;while(i <= j){int mid = i + (j - i)/2;if(nums[mid-1] < nums[mid] && nums[mid] > nums[mid+1]){return mid;}else if(nums[mid] < nums[mid+1]){i = mid + 1;}else{j = mid - 1;}}Time ComplexityO(log n)Space ComplexityO(1)Approach 3 β€” Optimized Binary Search (Most Elegant Solution)A simpler and more elegant version of binary search exists.Core IntuitionCompare:nums[mid]nums[mid + 1]Two possibilities exist.Case 1 β€” Increasing Slopenums[mid] < nums[mid+1]Example:1 2 3 4^The peak must exist on the right side.Move:left = mid + 1Case 2 β€” Decreasing Slopenums[mid] > nums[mid+1]Example:4 3 2 1^Peak exists on the left side including mid.Move:right = midThis gradually narrows down to the peak.Final Optimized Implementationclass Solution {public int findPeakElement(int[] nums) {int i = 0;int j = nums.length - 1;while(i < j){int mid = i + (j - i) / 2;if(nums[mid] < nums[mid + 1]){i = mid + 1;}else{j = mid;}}return i;}}Step-by-Step ExampleArray[1,2,1,3,5,6,4]Iteration 1mid = 3nums[mid] = 3nums[mid+1] = 5Increasing slope β†’ move right.Iteration 2mid = 5nums[mid] = 6nums[mid+1] = 4Decreasing slope β†’ move left.Eventually:peak index = 5Value:6Why This Binary Search WorksThe array behaves like a mountain landscape.Example visualization:/\/ \/ \__If you stand at mid:If the right side is higher, go right.If the left side is higher, go left.This guarantees that you will eventually reach a peak.Time ComplexityO(log n)Each iteration cuts the search space in half.Space ComplexityO(1)Only a few variables are used.Key Takeawaysβœ” A peak element is greater than its neighborsβœ” The array always contains at least one peakβœ” Binary search can be applied using slope comparisonβœ” The optimized solution only compares nums[mid] and nums[mid+1]βœ” The final algorithm runs in O(log n) timeFinal ThoughtsThis problem is an excellent example of applying binary search beyond sorted arrays.Instead of searching for a value, binary search is used here to locate a structural property of the array (a peak).Understanding this pattern is extremely valuable because similar logic appears in many interview problems involving:Mountain arraysBitonic arraysOptimization search problemsMastering this approach will significantly improve your binary search problem-solving skills for technical interviews.

LeetCodeBinary SearchMediumJava
LeetCode 3488 β€” Closest Equal Element Queries: A Complete Walkthrough from Brute Force to Optimal

LeetCode 3488 β€” Closest Equal Element Queries: A Complete Walkthrough from Brute Force to Optimal

If you have been grinding LeetCode lately, you have probably run into problems where your first clean-looking solution times out and forces you to rethink from scratch. LeetCode 3488 is exactly that kind of problem. This article walks through the complete thought process β€” from the naive approach that got me TLE, to the intuition shift, to the final optimized solution in Java.You can find the original problem here: LeetCode 3488 β€” Closest Equal Element Queries at Problem LinkUnderstanding the ProblemYou are given a circular array nums and an array of queries. For each query queries[i], you must find the minimum distance between the element at index queries[i] and any other index j such that nums[j] == nums[queries[i]]. If no such other index exists, the answer is -1.The critical detail here is the word circular. The array wraps around, which means the distance between two indices i and j in an array of length n is not simply |i - j|. It is:min( |i - j| , n - |i - j| )You can travel either clockwise or counterclockwise, and you take whichever path is shorter.Breaking Down the ExamplesExample 1nums = [1, 3, 1, 4, 1, 3, 2], queries = [0, 3, 5]For query index 0, the value is 1. Other indices holding 1 are 2 and 4. Circular distances are min(2, 5) = 2 and min(4, 3) = 3. The minimum is 2.For query index 3, the value is 4. It appears nowhere else in the array. Answer is -1.For query index 5, the value is 3. The other 3 sits at index 1. Circular distance is min(4, 3) = 3. Answer is 3.Output: [2, -1, 3]Example 2nums = [1, 2, 3, 4], queries = [0, 1, 2, 3]Every element is unique. Every query returns -1.Output: [-1, -1, -1, -1]First Attempt β€” Brute ForceMy first instinct was straightforward. For each query, scan the entire array, collect every index that matches the queried value, compute the circular distance to each, and return the minimum. Clean logic, easy to reason about, and dead simple to implement.while (i != queries.length) { int max = Integer.MAX_VALUE; for (int j = 0; j < nums.length; j++) { int target = nums[queries[i]]; if (nums[j] == target && j != queries[i]) { // Linear distance between the two indices int right = Math.abs(j - queries[i]); // Distance going the other direction around the ring int left = nums.length - right; // True circular distance is the shorter of the two int dist = Math.min(right, left); max = Math.min(max, dist); } } lis.add(max == Integer.MAX_VALUE ? -1 : max); i++;}This got TLE immediately, and once you look at the constraints it is obvious why. Both nums.length and queries.length can be up to 10^5. For every query you are scanning every element, giving you O(n Γ— q) time β€” which in the worst case is 10 billion operations. No judge is going to wait for that.Rethinking the Approach β€” Where Is the Waste?After the TLE, the question I asked myself was: what work is being repeated unnecessarily?The answer was obvious in hindsight. Every time a query asks about a value like 3, the brute force scans the entire array again looking for every index that holds 3. If ten different queries all ask about value 3, you are doing that scan ten times. You are finding the same indices over and over.The fix is to do that work exactly once, before any query is processed. You precompute a map from each value to all the indices where it appears. Then for every query you simply look up the relevant list and work within it.That observation reduces the precomputation to O(n) β€” one pass through the array. The question then becomes: once you have that sorted list of indices for a given value, how do you find the closest one to your query index efficiently?The Key Insight β€” You Only Need Two NeighboursHere is the insight that makes this problem elegant. The index list for any value is sorted in ascending order because you build it by iterating left to right through the array. If your query index sits at position mid inside that sorted list, then by definition every index to the left of mid - 1 is farther away than arr[mid - 1], and every index to the right of mid + 1 is farther away than arr[mid + 1].This means you never need to compare against all duplicates. You only ever need to check the immediate left and right neighbours of your query index within the sorted list.The one subtlety is the circular wrap. Because the array itself is circular, the left neighbour of the very first element in the list is actually the last element in the list, since you can wrap around the ring. This is handled cleanly with modular arithmetic: (mid - 1 + n) % n for the left neighbour and (mid + 1) % n for the right.The Optimized Solution β€” HashMap + Binary SearchStep 1 β€” Precompute the index mapIterate through nums once and build a HashMap mapping each value to a list of all indices where it appears. The lists are sorted by construction since you insert indices in order.Step 2 β€” Binary search to locate the query indexFor a given query at index q, look up the index list for nums[q]. Binary search the list to find the position of q within it. This runs in O(log n) rather than O(n).Step 3 β€” Check immediate neighbours and compute circular distancesOnce you have the position mid, fetch arr[(mid + 1) % n] and arr[(mid - 1 + n) % n]. For each, compute the circular distance using min(|diff|, totalLength - |diff|). Return the smaller of the two.Full Annotated Java Solutionclass Solution { public List<Integer> solveQueries(int[] nums, int[] queries) { int c = 0; // Precompute: map each value to the sorted list of indices where it appears. // Since we iterate left to right, the list is sorted by construction. HashMap<Integer, List<Integer>> mp = new HashMap<>(); for (int i = 0; i < nums.length; i++) { mp.computeIfAbsent(nums[i], k -> new ArrayList<>()).add(i); } List<Integer> lis = new ArrayList<>(); while (c != queries.length) { // Retrieve the sorted index list for the value at the queried position List<Integer> arr = mp.get(nums[queries[c]]); int n = arr.size(); int i = 0; int j = n - 1; int min = -1; while (i <= j) { int mid = i + (j - i) / 2; if (arr.get(mid) == queries[c]) { // Only one occurrence in the entire array β€” no duplicate exists if (n == 1) { min = -1; } else { // Circular neighbour to the right within the index list int right = arr.get((mid + 1) % n); // Circular neighbour to the left within the index list int left = arr.get((mid - 1 + n) % n); // Compute circular distance to the right neighbour int d1 = Math.abs(right - queries[c]); int distRight = Math.min(d1, nums.length - d1); // Compute circular distance to the left neighbour int d2 = Math.abs(left - queries[c]); int distLeft = Math.min(d2, nums.length - d2); // The answer is the closer of the two neighbours min = Math.min(distLeft, distRight); } break; } else if (arr.get(mid) > queries[c]) { // Query index is smaller β€” search the left half j = mid - 1; } else { // Query index is larger β€” search the right half i = mid + 1; } } lis.add(min); c++; } return lis; }}Complexity AnalysisTime Complexity: O(n log n)Building the HashMap takes O(n). For each of the q queries, binary search over the index list takes O(log n) in the worst case. Total: O(n + q log n), which simplifies to O(n log n) given the constraint that q ≀ n.Space Complexity: O(n)The HashMap stores every index exactly once across all its lists, so total space used is O(n).Compared to the brute force O(n Γ— q), this is the difference between ~1.7 million operations and ~10 billion operations at the constraint limits.Common PitfallsMixing up the two values of n. Inside the solution, n refers to arr.size() β€” the number of occurrences of a particular value. But when computing circular distance, you need nums.length β€” the full array length. These are different numbers and swapping them silently produces wrong answers.Forgetting the + n in the left neighbour formula. Writing (mid - 1) % n when mid is 0 produces -1 in Java, since Java's modulo preserves the sign of the dividend. Always write (mid - 1 + n) % n.Not handling the single-occurrence case. If a value appears only once, n == 1, and the neighbour formula wraps around to the element itself, giving a distance of zero β€” which is completely wrong. Guard against this explicitly before running the neighbour logic.What This Problem Teaches YouThe journey from brute force to optimal here follows a pattern worth internalizing.The brute force was correct but repeated work. Recognizing that repeated work and lifting it into a precomputation step is the single move that makes this problem tractable. The HashMap does that.Once you have a sorted structure, binary search is almost always the right tool to find a position within it. And once you have a position in a sorted structure, you only ever need to look at adjacent elements to find the nearest one β€” checking anything further is redundant by definition.These are not tricks specific to this problem. They are transferable patterns that appear across dozens of medium and hard problems on the platform. Internalizing them β€” rather than memorizing solutions β€” is what actually builds problem-solving ability over time.

ArraysHashMapBinary SearchCircular ArraysMediumLeetCodeJava
Queue Data Structure Complete Guide - Java Explained With All Operations

Queue Data Structure Complete Guide - Java Explained With All Operations

IntroductionIf you have been learning Data Structures and Algorithms, you have probably already spent time with arrays, linked lists, and stacks. Now it is time to meet one of the most important and widely used data structures in computer science β€” the Queue.Queue is not just a theoretical concept. It powers some of the most critical systems you use every day β€” from how your printer handles jobs, to how your CPU schedules tasks, to how Google Maps finds the shortest path between two locations. Understanding Queue deeply means understanding how real systems work.In this complete guide we will cover absolutely everything β€” what a Queue is, how it differs from a Stack, every type of Queue, all operations with code, Java implementations, time and space complexity, common interview questions, and the most important LeetCode problems that use Queue.What Is a Queue?A Queue is a linear data structure that follows the FIFO principle β€” First In First Out. This means the element that was added first is the one that gets removed first.Think of it exactly like a real-world queue (a line of people). The person who joined the line first gets served first. No cutting in line, no serving from the back β€” strict order from front to back.This is the fundamental difference between a Queue and a Stack:Stack β†’ LIFO (Last In First Out) β€” like a stack of plates, you take from the topQueue β†’ FIFO (First In First Out) β€” like a line of people, you serve from the frontReal Life Examples of QueueBefore writing a single line of code, let us understand where queues appear in real life. This will make every technical concept feel natural.Printer Queue β€” when you send multiple documents to print, they print in the order they were sent. The first document sent prints first.CPU Task Scheduling β€” your operating system manages running processes in a queue. Tasks get CPU time in the order they arrive (in basic scheduling).Customer Service Call Center β€” when you call a helpline and are put on hold, you are placed in a queue. The first caller on hold gets connected first.WhatsApp Messages β€” messages are delivered in the order they are sent. The first message sent is the first one received.BFS (Breadth First Search) β€” every time you use Google Maps or any navigation app to find the shortest path, it uses BFS internally which is entirely powered by a Queue.Ticket Booking Systems β€” online booking portals process requests in the order they arrive. First come first served.Queue Terminology β€” Key Terms You Must KnowBefore diving into code, let us get the vocabulary right:Front β€” the end from which elements are removed (dequeued). This is where the "first person in line" stands.Rear (or Back) β€” the end at which elements are added (enqueued). New arrivals join here.Enqueue β€” the operation of adding an element to the rear of the queue. Like joining the back of a line.Dequeue β€” the operation of removing an element from the front of the queue. Like the first person in line being served and leaving.Peek (or Front) β€” looking at the front element without removing it. Like seeing who is first in line without serving them yet.isEmpty β€” checking whether the queue has no elements.isFull β€” relevant for fixed-size queues, checking whether no more elements can be added.Types of QueuesThis is where most beginners get confused. There is not just one type of Queue β€” there are several variations each designed to solve specific problems.1. Simple Queue (Linear Queue)The most basic form. Elements enter from the rear and leave from the front. Strict FIFO, nothing fancy.Enqueue β†’ [ 1 | 2 | 3 | 4 | 5 ] β†’ Dequeue rear frontProblem with Simple Queue: In array-based implementation, once elements are dequeued from the front, those slots cannot be reused even if there is space. This wastes memory. This is why Circular Queue was invented.2. Circular QueueIn a Circular Queue, the rear wraps around to the front when it reaches the end of the array. The last position connects back to the first, forming a circle. This solves the wasted space problem of simple queues. [1] [2] [3] / \ [6] [4] \ / [5] ← rearUsed in: CPU scheduling, memory management, traffic light systems, streaming buffers.3. Double Ended Queue (Deque)A Deque (pronounced "deck") allows insertion and deletion from both ends β€” front and rear. It is the most flexible queue type.Enqueue Front β†’ [ 1 | 2 | 3 | 4 | 5 ] β†’ Dequeue FrontEnqueue Rear β†’ [ 1 | 2 | 3 | 4 | 5 ] β†’ Dequeue RearTwo subtypes:Input Restricted Deque β€” insertion only at rear, deletion from both endsOutput Restricted Deque β€” deletion only at front, insertion at both endsUsed in: browser history (back and forward), undo-redo operations, sliding window problems.4. Priority QueueElements are not served in FIFO order β€” instead each element has a priority and the element with the highest priority is served first regardless of when it was added.Think of an emergency room. A patient with a critical injury jumps ahead of someone with a minor cut even if they arrived later.Two types:Max Priority Queue β€” highest value = highest priorityMin Priority Queue β€” lowest value = highest priorityUsed in: Dijkstra's shortest path, Huffman encoding, A* search algorithm, task scheduling with priorities.5. Blocking QueueA thread-safe queue used in multi-threading. If the queue is empty, a thread trying to dequeue will wait (block) until an element is available. If the queue is full, a thread trying to enqueue will wait until space is available.Used in: Producer-Consumer problems, thread pool implementations, Java's java.util.concurrent package.Queue Operations and Time ComplexityEvery queue operation has a specific time complexity that you must know cold for interviews.OperationDescriptionTime ComplexityEnqueueAdd element to rearO(1)DequeueRemove element from frontO(1)Peek/FrontView front elementO(1)isEmptyCheck if queue is emptyO(1)SizeNumber of elementsO(1)SearchFind a specific elementO(n)Space Complexity: O(n) β€” where n is the number of elements stored.All core queue operations are O(1). This is what makes Queue so powerful β€” no matter how many elements are in the queue, adding and removing always takes constant time.Implementing Queue in Java β€” All WaysJava gives you multiple ways to use a Queue. Let us go through each one.Way 1: Using LinkedList (Most Common)LinkedList implements the Queue interface in Java. This is the most commonly used Queue implementation.import java.util.LinkedList;import java.util.Queue;Queue<Integer> queue = new LinkedList<>();// Enqueue β€” add to rearqueue.offer(10);queue.offer(20);queue.offer(30);// Peek β€” view front without removingSystem.out.println(queue.peek()); // 10// Dequeue β€” remove from frontSystem.out.println(queue.poll()); // 10System.out.println(queue.poll()); // 20// Check emptySystem.out.println(queue.isEmpty()); // false// SizeSystem.out.println(queue.size()); // 1offer() vs add() β€” both add to the queue. add() throws an exception if the queue is full (for bounded queues). offer() returns false instead. Always prefer offer().poll() vs remove() β€” both remove from front. remove() throws an exception if queue is empty. poll() returns null. Always prefer poll().peek() vs element() β€” both view the front. element() throws exception if empty. peek() returns null. Always prefer peek().Way 2: Using ArrayDeque (Fastest)ArrayDeque is faster than LinkedList for Queue operations because it uses a resizable array internally with no node allocation overhead.import java.util.ArrayDeque;import java.util.Queue;Queue<Integer> queue = new ArrayDeque<>();queue.offer(1);queue.offer(2);queue.offer(3);System.out.println(queue.peek()); // 1System.out.println(queue.poll()); // 1System.out.println(queue.size()); // 2When to use ArrayDeque over LinkedList? Use ArrayDeque whenever possible for Queue or Stack operations. It is faster because it avoids the overhead of node objects that LinkedList creates for every element. In competitive programming and interviews, ArrayDeque is the preferred choice.Way 3: Using Deque (Double Ended Queue)import java.util.ArrayDeque;import java.util.Deque;Deque<Integer> deque = new ArrayDeque<>();// Add to frontdeque.offerFirst(10);// Add to reardeque.offerLast(20);deque.offerLast(30);// Remove from frontSystem.out.println(deque.pollFirst()); // 10// Remove from rearSystem.out.println(deque.pollLast()); // 30// Peek front and rearSystem.out.println(deque.peekFirst()); // 20System.out.println(deque.peekLast()); // 20Way 4: Using PriorityQueueimport java.util.PriorityQueue;// Min Heap β€” smallest element has highest priorityPriorityQueue<Integer> minPQ = new PriorityQueue<>();minPQ.offer(30);minPQ.offer(10);minPQ.offer(20);System.out.println(minPQ.poll()); // 10 β€” smallest comes out first// Max Heap β€” largest element has highest priorityPriorityQueue<Integer> maxPQ = new PriorityQueue<>((a, b) -> b - a);maxPQ.offer(30);maxPQ.offer(10);maxPQ.offer(20);System.out.println(maxPQ.poll()); // 30 β€” largest comes out firstWay 5: Implementing Queue From Scratch Using ArrayUnderstanding the underlying implementation helps you in interviews when asked to build one from scratch.class MyQueue { private int[] arr; private int front; private int rear; private int size; private int capacity; public MyQueue(int capacity) { this.capacity = capacity; arr = new int[capacity]; front = 0; rear = -1; size = 0; } public void enqueue(int val) { if (size == capacity) { System.out.println("Queue is full!"); return; } rear = (rear + 1) % capacity; // circular wrapping arr[rear] = val; size++; } public int dequeue() { if (isEmpty()) { System.out.println("Queue is empty!"); return -1; } int val = arr[front]; front = (front + 1) % capacity; // circular wrapping size--; return val; } public int peek() { if (isEmpty()) return -1; return arr[front]; } public boolean isEmpty() { return size == 0; } public int size() { return size; }}Notice the % capacity in enqueue and dequeue β€” that is what makes it a Circular Queue. Without this, once the rear reaches the end of the array, you cannot add more even if front has moved forward and freed up space.Way 6: Implementing Queue Using Two StacksThis is a very popular interview question β€” implement a Queue using two stacks. The idea is to use one stack for enqueue and another for dequeue.class QueueUsingTwoStacks { Stack<Integer> s1 = new Stack<>(); // for enqueue Stack<Integer> s2 = new Stack<>(); // for dequeue public void enqueue(int val) { s1.push(val); // always push to s1 } public int dequeue() { if (s2.isEmpty()) { // transfer all elements from s1 to s2 // this reverses the order, giving FIFO behavior while (!s1.isEmpty()) { s2.push(s1.pop()); } } return s2.pop(); } public int peek() { if (s2.isEmpty()) { while (!s1.isEmpty()) { s2.push(s1.pop()); } } return s2.peek(); } public boolean isEmpty() { return s1.isEmpty() && s2.isEmpty(); }}Why does this work?When you transfer elements from s1 to s2, the order reverses. The element that was added first to s1 ends up on top of s2 β€” which means it gets dequeued first. FIFO achieved using two LIFOs!Amortized time complexity: Each element is pushed and popped at most twice (once in s1, once in s2). So dequeue is O(1) amortized even though individual calls might take O(n).This is LeetCode 232 β€” Implement Queue using Stacks.Queue vs Stack β€” Side by SideFeatureQueueStackPrincipleFIFO β€” First In First OutLIFO β€” Last In First OutInsert atRearTopRemove fromFrontTopReal lifeLine of peopleStack of platesJava classLinkedList, ArrayDequeStack, ArrayDequeMain useBFS, schedulingDFS, backtracking, parsingPeekFront elementTop elementBFS β€” The Most Important Application of QueueBreadth First Search (BFS) is the single most important algorithm that uses a Queue. Understanding BFS is why Queue matters so much in DSA.BFS explores a graph or tree level by level β€” all nodes at distance 1 first, then all at distance 2, and so on. A Queue naturally enforces this level-by-level behavior.public void bfs(int start, List<List<Integer>> graph) { Queue<Integer> queue = new LinkedList<>(); boolean[] visited = new boolean[graph.size()]; queue.offer(start); visited[start] = true; while (!queue.isEmpty()) { int node = queue.poll(); // process front node System.out.print(node + " "); for (int neighbor : graph.get(node)) { if (!visited[neighbor]) { visited[neighbor] = true; queue.offer(neighbor); // add unvisited neighbors to rear } } }}Why Queue and not Stack for BFS? Queue ensures you process all neighbors of a node before going deeper. Stack would take you deep into one path first β€” that is DFS, not BFS. The FIFO property is what guarantees level-by-level exploration.BFS with Queue is used in:Shortest path in unweighted graphsLevel order traversal of treesFinding connected componentsWord ladder problemsRotten oranges, flood fill, and matrix BFS problemsLevel Order Traversal β€” BFS on TreesOne of the most common Queue problems in interviews is Level Order Traversal of a binary tree.public List<List<Integer>> levelOrder(TreeNode root) { List<List<Integer>> result = new ArrayList<>(); if (root == null) return result; Queue<TreeNode> queue = new LinkedList<>(); queue.offer(root); while (!queue.isEmpty()) { int levelSize = queue.size(); // number of nodes at current level List<Integer> level = new ArrayList<>(); for (int i = 0; i < levelSize; i++) { TreeNode node = queue.poll(); level.add(node.val); if (node.left != null) queue.offer(node.left); if (node.right != null) queue.offer(node.right); } result.add(level); } return result;}The key trick here is using queue.size() at the start of each while loop iteration to know exactly how many nodes belong to the current level. Process exactly that many nodes, then move to the next level.This is LeetCode 102 β€” Binary Tree Level Order Traversal.Sliding Window Maximum β€” Monotonic DequeOne of the most impressive Queue applications is the Sliding Window Maximum problem using a Monotonic Deque. This is the queue equivalent of the Monotonic Stack pattern you saw in stack problems.The idea β€” maintain a deque that stores indices of elements in decreasing order. The front always holds the index of the maximum element in the current window.public int[] maxSlidingWindow(int[] nums, int k) { Deque<Integer> deque = new ArrayDeque<>(); // stores indices int[] result = new int[nums.length - k + 1]; int idx = 0; for (int i = 0; i < nums.length; i++) { // remove indices that are out of the current window while (!deque.isEmpty() && deque.peekFirst() < i - k + 1) { deque.pollFirst(); } // remove indices whose values are smaller than current // they can never be the maximum for any future window while (!deque.isEmpty() && nums[deque.peekLast()] < nums[i]) { deque.pollLast(); } deque.offerLast(i); // window is fully formed, record maximum (front of deque) if (i >= k - 1) { result[idx++] = nums[deque.peekFirst()]; } } return result;}This gives O(n) time for what would otherwise be an O(nΓ—k) problem. This is LeetCode 239 β€” Sliding Window Maximum.Java Queue Interface β€” Complete Method ReferenceHere is every method you will ever need from Java's Queue and Deque interfaces:Queue Methods:offer(e) β€” add to rear, returns false if full (preferred over add) poll() β€” remove from front, returns null if empty (preferred over remove) peek() β€” view front without removing, returns null if empty (preferred over element) isEmpty() β€” returns true if no elements size() β€” returns number of elements contains(o) β€” returns true if element existsDeque Additional Methods:offerFirst(e) β€” add to front offerLast(e) β€” add to rear pollFirst() β€” remove from front pollLast() β€” remove from rear peekFirst() β€” view front peekLast() β€” view rearPriorityQueue Specific:offer(e) β€” add with natural ordering or custom comparator poll() β€” remove element with highest priority peek() β€” view highest priority element without removingCommon Interview Questions About QueueThese are the questions interviewers ask to test your understanding of queues conceptually β€” not just coding.Q1. What is the difference between Queue and Stack? Queue is FIFO β€” elements are removed in the order they were added. Stack is LIFO β€” the most recently added element is removed first. Queue removes from the front, Stack removes from the top.Q2. Why is ArrayDeque preferred over LinkedList for Queue in Java? ArrayDeque uses a resizable array internally and has better cache locality and no node allocation overhead. LinkedList creates a new node object for every element added, which means more garbage collection pressure. ArrayDeque is faster in practice for most Queue use cases.Q3. When would you use a PriorityQueue instead of a regular Queue? When the order of processing depends on priority rather than arrival order. For example in a hospital, critical patients are treated before minor cases regardless of when they arrived. Or in Dijkstra's algorithm, always processing the shortest known distance first.Q4. How is Queue used in BFS? BFS uses a Queue to explore nodes level by level. The starting node is enqueued first. Each time a node is dequeued, all its unvisited neighbors are enqueued. Since Queue is FIFO, all neighbors of a node are processed before going deeper β€” guaranteeing level-by-level exploration.Q5. What is the difference between poll() and remove() in Java Queue? Both remove the front element. remove() throws NoSuchElementException if the queue is empty. poll() returns null instead of throwing. Always use poll() for safer code.Q6. Can a Queue have duplicates? Yes. Queue does not have any restriction on duplicate values unlike Sets. The same value can appear multiple times in a Queue.Q7. What is a Blocking Queue and when is it used? A Blocking Queue is a thread-safe Queue used in multi-threaded applications. When a thread tries to dequeue from an empty queue, it blocks (waits) until an element is available. When a thread tries to enqueue into a full queue, it blocks until space is available. Used in Producer-Consumer patterns.Top LeetCode Problems on QueueHere are the most important LeetCode problems that use Queue β€” organized from beginner to advanced:Beginner Level:232. Implement Queue using Stacks β€” implement Queue with two stacks, classic interview question225. Implement Stack using Queues β€” reverse of 232, implement Stack using Queue933. Number of Recent Calls β€” sliding window with QueueIntermediate Level:102. Binary Tree Level Order Traversal β€” BFS on tree, must know107. Binary Tree Level Order Traversal II β€” same but bottom up994. Rotting Oranges β€” multi-source BFS on grid1091. Shortest Path in Binary Matrix β€” BFS shortest path542. 01 Matrix β€” multi-source BFS, distance to nearest 0127. Word Ladder β€” BFS on word graph, classicAdvanced Level:239. Sliding Window Maximum β€” monotonic deque, must know862. Shortest Subarray with Sum at Least K β€” monotonic deque with prefix sums407. Trapping Rain Water II β€” 3D BFS with priority queue787. Cheapest Flights Within K Stops β€” BFS with constraintsQueue Cheat Sheet β€” Everything at a GlanceCreate a Queue:Queue<Integer> q = new LinkedList<>(); // standardQueue<Integer> q = new ArrayDeque<>(); // faster, preferredDeque<Integer> dq = new ArrayDeque<>(); // double endedPriorityQueue<Integer> pq = new PriorityQueue<>(); // min heapPriorityQueue<Integer> pq = new PriorityQueue<>((a,b) -> b-a); // max heapCore Operations:q.offer(x); // enqueueq.poll(); // dequeueq.peek(); // front elementq.isEmpty(); // check emptyq.size(); // number of elementsDeque Operations:dq.offerFirst(x); // add to frontdq.offerLast(x); // add to reardq.pollFirst(); // remove from frontdq.pollLast(); // remove from reardq.peekFirst(); // view frontdq.peekLast(); // view rearBFS Template:Queue<Integer> queue = new LinkedList<>();queue.offer(start);visited[start] = true;while (!queue.isEmpty()) { int node = queue.poll(); for (int neighbor : graph.get(node)) { if (!visited[neighbor]) { visited[neighbor] = true; queue.offer(neighbor); } }}ConclusionQueue is one of those data structures that appears simple on the surface but has incredible depth once you start exploring its variations and applications. From the basic FIFO concept to Circular Queues, Deques, Priority Queues, Monotonic Deques, and BFS β€” each layer adds a new tool to your problem-solving arsenal.Here is the learning path to follow based on everything covered in this guide:Start with understanding FIFO vs LIFO and when each applies. Then get comfortable with Java's Queue interface β€” offer, poll, peek. Practice the BFS template until it feels automatic. Then move to Level Order Traversal problems. Once BFS clicks, tackle multi-source BFS problems like Rotting Oranges. Finally learn the Monotonic Deque pattern for sliding window problems.Master these and you will handle every Queue problem in any coding interview with confidence.

QueueData StructureJavaBFSDequePriority QueueCircular Queue
Amazon OA: Find the Element Occurring Less Than K Times in a Sorted Array – Java Solution

Amazon OA: Find the Element Occurring Less Than K Times in a Sorted Array – Java Solution

IntroductionThis is a sorted array frequency problem that can appear in coding assessments and online assessments such as an Amazon OA.You are given a sorted array B of size N. Every distinct element occurs exactly K times except for one element, whose frequency is less than K.The task is to find that element.Because the array is sorted, all occurrences of the same element are located together. This allows us to process the array sequentially and keep track of the current element and its frequency.For example:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3Here:2 β†’ 3 times3 β†’ 2 times4 β†’ 3 times5 β†’ 3 timesTherefore, the answer is:3because 3 occurs fewer than K = 3 times.QuestionYou are given a sorted array B of size N.Every element in the array occurs exactly K times except one element, which occurs fewer than K times.Find that element.It is guaranteed that there is exactly one element whose frequency is less than K.ConstraintsN <= 100000K >= 21 <= B[i] <= 10000000000Since B[i] can be as large as 10^10, a Java long should be used to safely store the array values.ExampleConsider:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3Frequency table:Element Frequency2 33 24 35 3Only 3 occurs fewer than K times.Therefore:Output: 3Understanding the Sorted ArrayThe most important property of this problem is that the array is sorted.Because of that, identical elements always appear consecutively.For example:1 1 1 2 2 2 3 3 4 4 4We never have to search the entire array to count the occurrences of an element.We can simply scan from left to right.When the value changes, the frequency of the previous value is known.For example:1 1 1When we encounter 2, we know that:1 occurred 3 timesWe can compare this frequency with K.If it is less than K, then 1 is the required answer.Approach: Track the Current Element and Its FrequencyWe can maintain two variables:int cand;int count;where:cand represents the current element.count represents how many times that element has appeared so far.Initially:cand = arr[0];count = 1;Then we scan the remaining elements.There are three important situations.Case 1: Same ElementIf:cand == arr[i]then the current element is still being counted.So:count++;Case 2: Element Changes and Frequency Is KIf:cand != arr[i] && count == kthen the previous element occurred exactly K times.Therefore, we can start counting the new element:cand = arr[i];count = 1;Case 3: Element Changes and Frequency Is Less Than KIf:cand != arr[i] && count < kthen the previous element is the unique element whose frequency is less than K.So we can immediately stop.Java SolutionThe same logic can be implemented more cleanly as follows:class Main { public static void main(String[] args) { int[] arr = {1, 1, 2, 2, 2, 3, 3, 3}; int k = 3; int cand = arr[0]; int count = 1; for (int i = 1; i < arr.length; i++) { // Current element is still the same if (cand == arr[i]) { count++; } // Current element changed else { // Previous element occurred less than K times if (count < k) { break; } // Start counting the new element cand = arr[i]; count = 1; } } // The incomplete-frequency element may be the last element if (count < k) { System.out.println(cand); } }}Dry RunConsider:arr = [1, 1, 2, 2, 2, 3, 3, 3]k = 3Initially:cand = 1count = 1Now process the array.Step 1Current value:arr[1] = 1It is the same as cand.count = 2Step 2Current value:arr[2] = 2The value changed.Before moving to 2, we check the frequency of 1:count = 2k = 3Since:2 < 3we have found the answer.Therefore:Output: 1Another ExampleConsider:B = [2, 2, 2, 3, 3, 4, 4, 4, 5, 5, 5]K = 3We start with:cand = 2count = 1After processing the three 2s:cand = 2count = 3The next value is 3.Since:count == Kwe move to the next candidate:cand = 3count = 1After processing the second 3:cand = 3count = 2The next value is 4.Now:count < Kbecause:2 < 3Therefore:3is the required answer.Important Edge Case: Answer at the EndThere is one important case to handle.Suppose the incomplete element is the last element in the array.For example:arr = [1, 1, 1, 2, 2]K = 3When the loop finishes, there is no next element that causes the value to change.So the condition:if (cand != arr[i])will never execute for the final 2.We therefore need one final check after the loop:if (count < k) { System.out.println(cand);}This handles the case where the answer is at the end.Complexity AnalysisWe scan the array only once.For every element, we perform constant-time operations.Therefore:Time Complexity:O(N)Space Complexity:O(1)This is efficient enough for:N <= 100000and does not require an additional HashMap or frequency array.Why Does the Sorted Property Matter?Without the sorted property, the same element could appear at different positions.For example:2 3 2 4 3 2In that case, simply maintaining the frequency of the current consecutive value would not work.We would need another approach such as a HashMap.But because the input is sorted:2 2 2 3 3 4 4 4all occurrences of an element form one continuous block.That is what allows us to solve the problem with:O(N) timeO(1) extra spaceA Simpler AlternativeBecause the array is sorted, another straightforward solution is to count consecutive equal values.For example:class Main { public static void main(String[] args) { int[] arr = {2, 2, 2, 3, 3, 4, 4, 4}; int k = 3; int count = 1; for (int i = 1; i <= arr.length; i++) { if (i < arr.length && arr[i] == arr[i - 1]) { count++; } else { if (count < k) { System.out.println(arr[i - 1]); break; } count = 1; } } }}This version focuses directly on counting each consecutive group.The idea is:Read same values ↓Count them ↓Value changes ↓Check count < K ↓If yes β†’ answer foundInterview TipWhen an interview or OA problem gives you a sorted array, always ask yourself:What does sorting allow me to avoid?Here, sorting means all equal values are adjacent.Instead of using:HashMapor sorting the array again, we can simply maintain a running frequency.The important pattern is:Current value+Consecutive frequency+Check when value changesThis pattern is useful in many array problems involving duplicate or repeated elements.ConclusionThis Amazon OA-style problem can be solved efficiently by taking advantage of the fact that the input array is sorted.Since equal elements appear consecutively, we only need to maintain:current elementcurrent frequencyWhenever the element changes, we check whether its frequency was less than K.The solution requires:Time: O(N)Space: O(1)The main takeaway is that the sorted property removes the need for additional frequency data structures and lets us find the unique incomplete-frequency element with a single linear scan.

Amazon OAAmazon Online AssessmentJavaArraysFrequency CountingSorted ArrayDSAArray Problems
LeetCode 1752: Check if Array Is Sorted and Rotated – Java Solution Explained

LeetCode 1752: Check if Array Is Sorted and Rotated – Java Solution Explained

IntroductionLeetCode 1752 – Check if Array Is Sorted and Rotated is a classic array observation problem that tests your understanding of:Sorted arraysRotation logicCircular traversalEdge case handlingPattern recognitionAt first, many developers overcomplicate this problem by trying to actually rotate arrays and compare them. However, the problem can be solved using a very elegant observation.This problem is commonly asked in coding interviews because it evaluates:Logical thinkingArray traversal skillsOptimization abilityUnderstanding of rotated arraysProblem LinkπŸ”— https://leetcode.com/problems/check-if-array-is-sorted-and-rotated/Problem StatementGiven an array:numsReturn:trueif the array was originally sorted in non-decreasing order and then rotated some number of times.Otherwise return:falseDuplicates are allowed.Understanding RotationSuppose the original sorted array is:[1,2,3,4,5]After rotation:[3,4,5,1,2]The array is still almost sorted except for one β€œbreaking point”.Key ObservationA sorted rotated array can have:At most one decreasing pairExample:[3,4,5,1,2]Breaking point:5 > 1Only once.Invalid Example[2,1,3,4]Breaking points:2 > 1and circularly:4 > 2Two breaking points.So answer is:falseBrute Force ApproachIntuitionTry all possible rotations.For every rotation:Rotate arrayCheck if sortedIf any rotation works β†’ return trueBrute Force AlgorithmFor every rotation count:Create rotated arrayVerify sorted orderIf sorted:return trueElse:return falseBrute Force ComplexityTime ComplexityO(NΒ²)because each rotation requires traversal.Space ComplexityO(N)This solution:Finds rotation pointSorts arrayRotates sorted arrayCompares with originalThis is a valid simulation-based approach.Java Solutionclass Solution { public boolean check(int[] nums) { int[] arr = new int[nums.length]; int o = 0; int mini = Integer.MIN_VALUE; int temp = 0; int maxnumind = 0; for(int a : nums) { arr[o] = a; temp = mini; mini = Math.max(mini, a); if(mini != temp) { maxnumind = o; } o++; } for(int i = 0; i < nums.length - 1; i++) { if(nums[i] > nums[i + 1]) { maxnumind = i; } } int ro = nums.length - maxnumind - 1; Arrays.sort(nums); int[] rotarr = new int[nums.length]; for(int i = 0; i < nums.length; i++) { rotarr[i] = nums[(i + ro) % nums.length]; } for(int i = 0; i < arr.length; i++) { if(rotarr[i] != arr[i]) { return false; } } return true; }}Optimized Approach (Best Solution)We do not need:SortingExtra arraysRotation simulationWe only count:decreasing pairsOptimized IntuitionFor a valid rotated sorted array:nums[i] > nums[i+1]can happen only once.Also check circular condition:last element > first elementOptimized Java Solutionclass Solution { public boolean check(int[] nums) { int count = 0; for(int i = 0; i < nums.length; i++) { if(nums[i] > nums[(i + 1) % nums.length]) { count++; } } return count <= 1; }}Why This WorksIf array is sorted and rotated:Sequence increases normallyOnly one position breaks orderIf more than one break exists:Not a rotated sorted arrayDry RunInputnums = [3,4,5,1,2]Step 1Compare adjacent elements:3 < 44 < 55 > 1 ← breaking point1 < 22 < 3 (circular)Breaking points:1Valid.Return:trueAnother Dry RunInputnums = [2,1,3,4]Comparisons:2 > 1 ← break1 < 33 < 44 > 2 ← circular breakBreaking points:2Invalid.Return:falseTime Complexity AnalysisTime ComplexityO(N log N)because of sorting.Space ComplexityO(N)extra arrays used.Optimized ApproachTime ComplexityO(N)single traversal.Space ComplexityO(1)Comparison of ApproachesApproachTime ComplexitySpace ComplexityRotation SimulationO(N log N)O(N)Decreasing Pair CountO(N)O(1)Interview ExplanationIn interviews, explain:A sorted rotated array can contain only one position where the order decreases. By counting such breaking points including circular comparison, we can determine validity in linear time.This demonstrates:Pattern recognitionCircular traversal understandingOptimization thinkingCommon Mistakes1. Forgetting Circular CheckAlways compare:nums[n-1] > nums[0]using modulo.2. Actually Rotating ArraysUnnecessary and inefficient.3. Using Strictly Increasing LogicDuplicates are allowed.So:1,1,2,2is valid.FAQsQ1. Why use modulo?To compare:last element with first elementcircularly.Q2. Why is only one break allowed?Because rotation shifts sorted order only once.Q3. Is sorting required?No.Observation-based traversal is enough.Q4. Is this problem important for interviews?Yes.It tests:Array logicRotationsOptimizationObservation skillsRelated ProblemsAfter mastering this problem, practice:Search in Rotated Sorted ArrayFind Minimum in Rotated Sorted ArrayFind Minimum in Rotated Sorted Array IIConclusionLeetCode 1752 is an excellent observation-based array problem.It teaches:Rotated array logicCircular traversalOptimization techniquesPattern recognitionThe key insight is:A sorted rotated array can have at most one decreasing point.Once you understand this observation, the optimized solution becomes extremely clean and efficient.

LeetCodeJavaArrayRotation ProblemsSortingEasy
LeetCode 735: Asteroid Collision β€” Java Solution Explained

LeetCode 735: Asteroid Collision β€” Java Solution Explained

IntroductionIf you have been building your stack skills through problems like Valid Parentheses, Next Greater Element, and Backspace String Compare, then LeetCode 735 Asteroid Collision is the problem where everything comes together. It is one of the most satisfying Medium problems on LeetCode because it feels like a real simulation β€” you are literally modelling asteroids flying through space and crashing into each other.You can find the problem here β€” LeetCode 735 Asteroid Collision.This article breaks everything down in plain English so that anyone β€” beginner or experienced β€” can understand exactly what is happening and why the stack is the perfect tool for this problem.What Is the Problem Really Asking?You have a row of asteroids moving through space. Each asteroid has a size and a direction:Positive number β†’ asteroid moving to the rightNegative number β†’ asteroid moving to the leftAll asteroids move at the same speed. When a right-moving asteroid and a left-moving asteroid meet head-on, they collide:The smaller one explodesIf they are the same size, both explodeThe bigger one survives and keeps movingTwo asteroids moving in the same direction never meet, so they never collide.Return the final state of all surviving asteroids after every possible collision has happened.Real Life Analogy β€” Cars on a HighwayImagine a highway with cars driving in both directions. Cars going right are in one lane, cars going left are in another lane. Now imagine the lanes overlap at some point.A small car going right crashes into a big truck going left β€” the car gets destroyed, the truck keeps going. Two equally sized cars crash β€” both are destroyed. A massive truck going right demolishes everything coming from the left until it meets something bigger or nothing at all.That is exactly the asteroid problem. The stack helps us track which asteroids are still "alive" and moving right, waiting to potentially collide with the next left-moving asteroid that comes along.Why Stack Is the Perfect Data Structure HereThe key observation is this β€” only a right-moving asteroid followed by a left-moving asteroid can collide. A left-moving asteroid might destroy several right-moving ones in a chain before it either survives or gets destroyed itself.This chain reaction behavior β€” where the outcome of one collision immediately triggers the possibility of another β€” is exactly what a stack handles naturally. The stack holds right-moving asteroids that are still alive and waiting. When a left-moving asteroid arrives, it battles the top of the stack repeatedly until either it is destroyed or no more collisions are possible.All Possible Collision ScenariosBefore looking at code it is important to understand every case that can happen:Case 1 β€” Right-moving asteroid (ast[i] > 0) No collision possible immediately. Push it onto the stack and move on.Case 2 β€” Left-moving asteroid, stack is empty Nothing to collide with. Push it onto the stack.Case 3 β€” Left-moving asteroid, top of stack is also left-moving (negative) Two asteroids going the same direction never meet. Push it onto the stack.Case 4 β€” Left-moving asteroid meets right-moving asteroid (collision!) Three sub-cases:Stack top is bigger β†’ left-moving asteroid explodes, stack top survivesStack top is smaller β†’ stack top explodes, left-moving asteroid continues (loop again)Same size β†’ both explodeThe Solution β€” Stack Simulationpublic int[] asteroidCollision(int[] ast) { Stack<Integer> st = new Stack<>(); for (int i = 0; i < ast.length; i++) { boolean survived = true; // assume current asteroid survives // collision only happens when stack top is positive // and current asteroid is negative while (!st.empty() && st.peek() > 0 && ast[i] < 0) { if (st.peek() > Math.abs(ast[i])) { // stack top is bigger β€” current asteroid explodes survived = false; break; } else if (st.peek() < Math.abs(ast[i])) { // current asteroid is bigger β€” stack top explodes // current asteroid keeps going, check next stack element st.pop(); } else { // equal size β€” both explode st.pop(); survived = false; break; } } if (survived) { st.push(ast[i]); } } // build result array from stack (stack gives reverse order) int[] ans = new int[st.size()]; for (int i = ans.length - 1; i >= 0; i--) { ans[i] = st.pop(); } return ans;}Step-by-Step Dry Run β€” asteroids = [10, 2, -5]Let us trace exactly what happens:Processing 10:Stack is empty, no collision possiblesurvived = true β†’ push 10Stack: [10]Processing 2:Stack top is 10 (positive), current is 2 (positive) β€” same direction, no collisionsurvived = true β†’ push 2Stack: [10, 2]Processing -5:Stack top is 2 (positive), current is -5 (negative) β€” collision!2 < 5 β†’ stack top smaller, pop 2. survived stays trueStack: [10]Stack top is 10 (positive), current is -5 (negative) β€” collision again!10 > 5 β†’ stack top bigger, current asteroid destroyed. survived = false, breakStack: [10]survived = false β†’ do not push -5Final stack: [10] β†’ output: [10] βœ…Step-by-Step Dry Run β€” asteroids = [3, 5, -6, 2, -1, 4]Processing 3: stack empty β†’ push. Stack: [3]Processing 5: both positive, same direction β†’ push. Stack: [3, 5]Processing -6:Collision with 5: 5 < 6 β†’ pop 5. Stack: [3]Collision with 3: 3 < 6 β†’ pop 3. Stack: []Stack empty β†’ survived = true β†’ push -6Stack: [-6]Processing 2: stack top is -6 (negative), current is 2 (positive) β€” same direction check fails, no collision β†’ push. Stack: [-6, 2]Processing -1:Collision with 2: 2 > 1 β†’ stack top bigger, -1 explodes. survived = falseStack: [-6, 2]Processing 4: stack top is 2 (positive), current is 4 (positive) β€” same direction β†’ push. Stack: [-6, 2, 4]Final stack: [-6, 2, 4] β†’ output: [-6, 2, 4] βœ…Understanding the survived FlagThe survived boolean flag is the most important design decision in this solution. It tracks whether the current asteroid makes it through all collisions.It starts as true β€” we assume the asteroid survives until proven otherwise. It only becomes false in two situations β€” when the stack top is bigger (current asteroid destroyed) or when both are equal size (mutual destruction). If survived is still true after the while loop, the asteroid either won all its battles or never had any β€” either way it gets pushed onto the stack.This flag eliminates the need for complicated nested conditions and makes the logic clean and readable.Building the Result ArrayOne important detail β€” when you pop everything from a stack to build an array, the order is reversed. The stack gives you elements from top to bottom (last to first). So we fill the result array from the end to the beginning using i = ans.length - 1 going down to 0. This preserves the original left-to-right order of surviving asteroids.Time and Space ComplexityTime Complexity: O(n) β€” each asteroid is pushed onto the stack at most once and popped at most once. Even though there is a while loop inside the for loop, each element participates in at most one push and one pop across the entire run. Total operations stay linear.Space Complexity: O(n) β€” in the worst case (all asteroids moving right, no collisions) all n asteroids sit on the stack simultaneously.Common Mistakes to AvoidForgetting that same-direction asteroids never collide The collision condition is specifically st.peek() > 0 && ast[i] < 0. Two positive asteroids, two negative asteroids, or a negative followed by a positive β€” none of these collide. Only right then left.Not using a loop for chain collisions A single left-moving asteroid can destroy multiple right-moving ones in sequence. If you only check the stack top once instead of looping, you will miss chain destructions like in the [3, 5, -6] example.Forgetting the survived flag and always pushing Without the flag, a destroyed asteroid still gets pushed onto the stack, giving wrong results.Wrong array reconstruction from stack Forgetting that stack order is reversed and filling the array from left to right gives a backwards answer. Always fill from the last index downward.How This Problem Differs From Previous Stack ProblemsEvery previous stack problem in this series had a simple push-or-pop decision per character. Asteroid Collision introduces something new β€” a while loop inside the for loop. This is because one incoming asteroid can trigger multiple consecutive pops (chain collisions). The stack is no longer just storing history β€” it is actively participating in a simulation where multiple stored elements can be affected by a single incoming element.This is the defining characteristic of harder stack problems and is exactly what appears in problems like Largest Rectangle in Histogram and Trapping Rain Water.FAQs β€” People Also AskQ1. Why is a Stack used to solve LeetCode 735 Asteroid Collision? Because right-moving asteroids wait on the stack until a left-moving asteroid arrives. The left-moving asteroid battles the top of the stack repeatedly β€” this LIFO chain reaction behavior is exactly what a stack handles naturally and efficiently.Q2. What is the time complexity of LeetCode 735? O(n) time because each asteroid is pushed and popped at most once regardless of how many chain collisions happen. Space complexity is O(n) for the stack in the worst case.Q3. When do two asteroids NOT collide in LeetCode 735? Two asteroids never collide when both move right (both positive), both move left (both negative), or when a left-moving asteroid comes before a right-moving one β€” they move away from each other in that case.Q4. Is LeetCode 735 asked in coding interviews? Yes, it is commonly asked at companies like Amazon, Google, and Microsoft as a Medium stack problem. It tests whether you can handle simulation problems with multiple conditional branches and chain reactions β€” skills that translate directly to real world system design thinking.Q5. What is the difference between LeetCode 735 and LeetCode 496 Next Greater Element? Both use a stack and involve comparing elements. In Next Greater Element, you search forward for something bigger. In Asteroid Collision, collisions happen between the current element and stack contents, and the current element might destroy multiple previous elements in a chain before settling. The collision logic in 735 is more complex.Similar LeetCode Problems to Practice Next496. Next Greater Element I β€” Easy β€” monotonic stack pattern739. Daily Temperatures β€” Medium β€” next greater with index distance1047. Remove All Adjacent Duplicates In String β€” Easy β€” chain removal with stack84. Largest Rectangle in Histogram β€” Hard β€” advanced stack simulation503. Next Greater Element II β€” Medium β€” circular array with monotonic stackConclusionLeetCode 735 Asteroid Collision is a wonderful problem that takes the stack simulation pattern to the next level. The key insight is recognizing that only right-then-left asteroid pairs can collide, that chain collisions require a while loop not just an if statement, and that the survived flag keeps the logic clean across all cases.Work through every dry run in this article carefully β€” especially the [3, 5, -6, 2, -1, 4] example β€” because seeing chain collisions play out step by step is what makes this pattern click permanently.Once this problem makes sense, you are genuinely ready for the harder stack problems that follow. Keep going!

LeetCodeJavaStackArrayMedium
Ai Assistant Kas