Search Blogs

Showing results for "AI Engineering"

Found 3 results

Jev AI Explained: What Is the Jev Decision-Making Model?

Jev AI Explained: What Is the Jev Decision-Making Model?

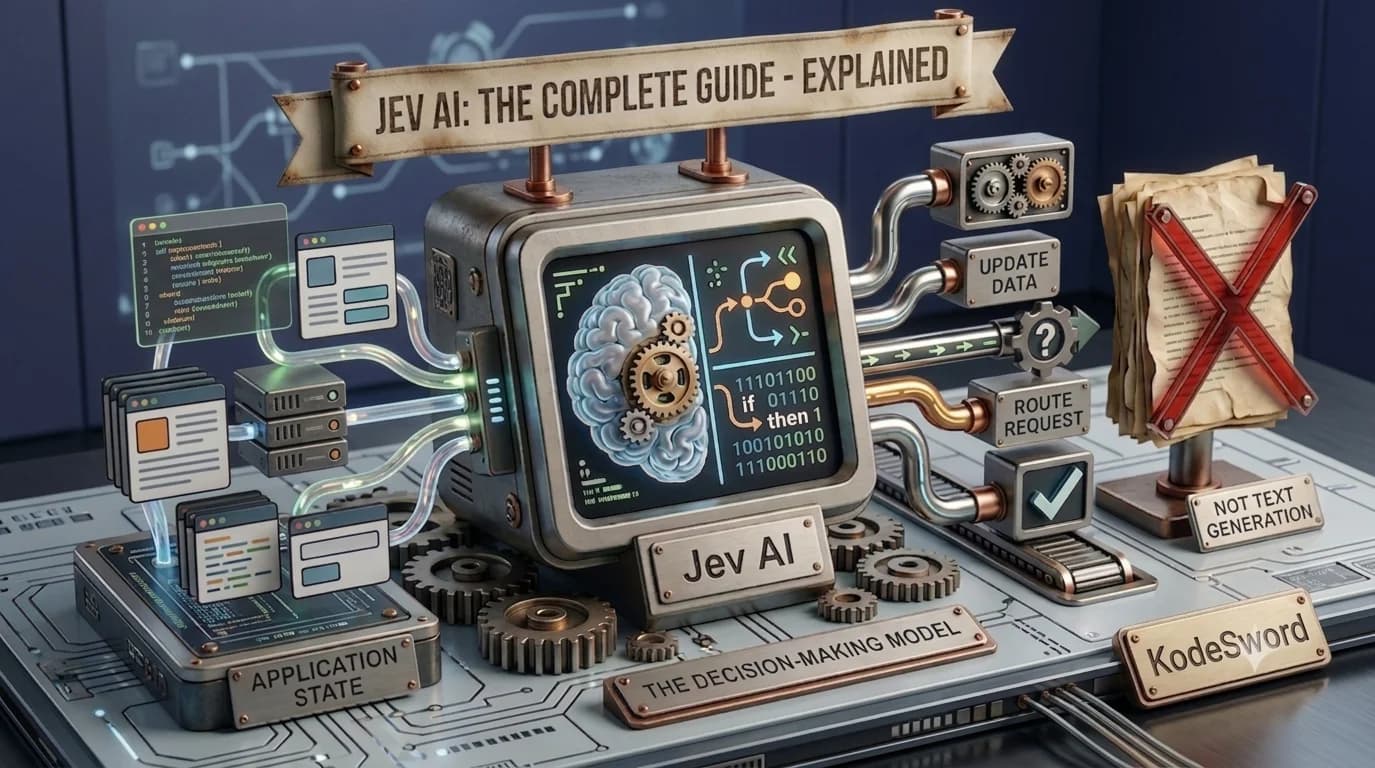
Jev AI Explained: The Decision-Making Model Built for Software AutomationTypeSafe AI just launched Jev, and it highlights a major flaw in how we currently build AI agents: we are wasting massive computing power forcing LLMs to output paragraphs when all our code needs is a simple yes or no.That's the idea behind Jev: a model designed to turn application state into structured, actionable decisions instead of generating traditional text.AI applications do not always need another paragraph of generated text.Sometimes, the application simply needs an answer to a small but important question:Which support team should handle this ticket?Should an AI agent call a particular tool?Is this request urgent?Should this workflow continue or stop?Does this response pass a specific quality check?Should this action require human approval?Traditionally, developers often use a general-purpose large language model (LLM) for these decisions. The application sends a prompt, asks the model to return structured JSON, parses the response, validates it, and then decides what to do.Jev takes a different approach.Jev is TypeSafe AI's first public System One Model, designed specifically for making fast, structured decisions inside software. Instead of generating open-ended text, Jev evaluates application state against predefined questions and returns typed decisions with probabilities and confidence information.Read the official announcement on TypeSafe AI's website .The result is a different way of thinking about AI architecture:Instead of asking an AI to explain a decision, ask it to make the decision your software actually needs.What Is Jev?Jev is a probabilistic decision model created by TypeSafe AI.The model was introduced on September 15, 2026, as the company's first public System One Model. TypeSafe describes System One models as a new class of models designed for decisions inside software rather than traditional human-facing chat.Jev System One ModelThe simplest way to understand Jev is:Unlike a normal LLM, Jev does not try to generate a paragraph explaining what it thinks.Instead, your application defines the possible decision space beforehand.For example:Jev can select one of those choices and provide probability information that your application can use when deciding whether to automate the next step or request human review.Jev in One PictureWhy Do We Need a Decision Model?Large language models are extremely capable.But many software workflows do not actually require text generation.Imagine an AI agent that receives a user request.The agent has five possible tools:Search documentationSearch databaseCall payment APISend emailAsk the userThe agent may need an intelligent decision about which tool to use next.A traditional approach might ask an LLM:"Based on the current state, decide which tool should be called next and return your answer as JSON."That introduces an unnecessary generation step.The model generates text.The application parses the text.The application validates the JSON.Then the application extracts the actual decision.Jev is designed around the decision itself.Vercel's AI Gateway describes the same distinction: regular language models generate text that applications then parse and validate, while Jev evaluates declared questions and returns typed answers directly.The Three Core Decision Types in JevJev's current interface revolves around three fundamental types of decisions:ChoiceScoreBoolean probabilityThese cover different kinds of bounded decisions.1. ChoiceA Choice question asks Jev to select one option from a predefined set.For example:Question: Which department should handle this ticket?Options:BillingTechnical SupportAccount SupportHuman ReviewJev does not need to invent another category.It chooses from the options supplied by the application.This makes Choice useful for:Ticket routingAgent selectionTool selectionModel selectionIntent classificationWorkflow routingFor example:The exact output structure and probability interpretation should be tested against your own workflow and labeled examples before using it for autonomous actions. Vercel specifically recommends calibrating probabilities and confidence against known examples.Choice Decision2. ScoreSome decisions are not about choosing a category.Instead, software may need to determine how strongly something satisfies a defined criterion.That is where a Score question can be useful.For example:Question: How urgent is this support request?Scale:1 → Very Low2 → Low3 → Moderate4 → High5 → CriticalA support system could then use the score in its workflow:This is particularly useful when the application has a predefined rubric.Potential examples include:Urgency scoringRisk assessmentQuality evaluationRelevance scoringPriority classificationResponse evaluationThe important point is that the application defines what the scale means.Jev is not being asked to write an explanation such as:"I think this request is fairly urgent because..."Instead, the software asks for a structured judgment against a known scale.3. Boolean ProbabilityThe third primitive handles questions that essentially have a yes/no outcome.For example:Question: "Does this request ask for a refund?"Instead of producing:Yes, the customer is asking for a refund.Jev can provide a probability associated with the Boolean decision.Conceptually:P(True) = 0.94The application can then define its own threshold.For example:This is one of the important architectural ideas behind Jev.The model supplies the judgment and uncertainty; your application decides what threshold should trigger an action.Jev vs Traditional LLMsThe biggest difference becomes easier to understand through a side-by-side comparison.Traditional LLMJevGenerates textProduces structured decisionsOpen-ended outputBounded outputApplication parses generated outputApplication receives typed answersOften used for reasoning + writingDesigned for focused decisionsCan generate explanationsDoes not generate proseUseful for open-ended tasksUseful for bounded decisionsOutput must often be validatedDecision schema is defined beforehandThis does not mean Jev replaces LLMs.In many applications, the two can work together.A generative model can handle:UnderstandingWritingReasoningCode generationConversationwhile Jev can handle:RoutingClassificationScoringVerificationTool selectionWorkflow decisionsVercel similarly describes Jev as something that can sit at a decision point inside an agent loop while a generative model handles responses or other open-ended work.The Most Important Architectural DifferenceConsider an AI customer-support agent.A user sends:"My payment was successful but my order still says pending. Can you fix it?"A traditional architecture might look like this:A Jev-based architecture can separate the decision from the generation:This is the architectural role Jev is trying to occupy: a decision layer between application state and application action.Full AI Agent ArchitectureJev in an AI Agent LoopAI agents repeatedly make small decisions.For example:Jev can participate at these decision points.For example, after an agent runs a search:Another possible decision is:"Should this tool call be allowed?"or:"Should the agent ask the user for clarification?"or:"Should the workflow stop?"These are all bounded decisions that can be expressed using predefined answers.Vercel's documentation specifically describes Jev being used inside agent loops for selecting next steps, deciding whether to continue/retry/ask/stop, scoring risk, and checking proposed actions.A Practical Example: Support Ticket RoutingLet's build a simple conceptual system.Suppose your application receives:"I was charged for my subscription but my account is still showing the free plan."The application sends the state to Jev.It defines three questions:Question 1: Which team should handle this?Options:- Billing- Account- Technical SupportQuestion 2: How urgent is the request?Scale:1–5Question 3: Does the request require human review?BooleanJev evaluates the questions.The application might receive something conceptually like:The application can then implement its own logic:Notice something important:Jev did not perform the action.The application did.That separation is important for production systems.Jev provides a decision.Your software controls permissions, thresholds, tool execution, and business rules.Why Typed Decisions MatterOne of the fundamental ideas behind Jev is that the software should know the possible output space before the model answers.Imagine asking an LLM:Which tool should I use?Return JSON.The model could theoretically return:{"tool": "search_database"}But production software still needs to validate:Is search_database valid?Did the model use the correct field?Is the value spelled correctly?Did it return extra information?Is the JSON valid?Does the selected tool actually exist?With a bounded decision interface, the possible choices are defined by the application.Conceptually:The model does not need to invent a new tool name.But Jev Can Still Be WrongThis distinction is extremely important.A structured answer is not automatically a correct answer.Suppose the application provides:Choices:BillingTechnical SupportAccount SupportJev must select one of them.Even if the output is perfectly typed, it could still select the wrong team.That means Jev changes one problem:Unstructured generationinto:Structured decisionIt does not magically eliminate model error.Vercel explicitly notes that a typed answer can still misinterpret the evidence, and recommends testing decisions against known outcomes before allowing them to trigger automated actions.This is why probabilities and confidence information matter.A production system can create different paths:Confidence-Based AutomationJev Does Not Replace Generative AIIt is tempting to describe Jev as a replacement for LLMs.That would be misleading.Jev and generative models are optimized for different interfaces.A generative model is useful when the application needs something like:"Explain why the deployment failed and write a response for the developer."That requires open-ended text generation.Jev is better suited to a question such as:"Should the agent inspect the deployment logs?"with answers like:Yes / Noor:"Which diagnostic tool should the agent call?"with a predefined list of tools.A realistic AI system could therefore look like:The interesting architecture is therefore not:Jev vs LLMbut:Jev + LLM + application codeWhere Can Jev Be Used?Jev's design makes it applicable to many software workflows involving bounded decisions.1. AI Agent RoutingAn agent may have several possible next actions.2. Customer SupportJev can help classify and route incoming tickets.3. Tool ApprovalBefore an agent executes an important tool:The actual permission and execution should remain under application control.4. Model RoutingAn application might have several AI models:Cheap ModelFast ModelReasoning ModelSpecialized ModelHumanJev can make a bounded routing decision based on the current request and application state.5. Response EvaluationSuppose a generative model produces an answer.Another component can evaluate:Is the answer relevant?Is it safe?Does it follow the requested format?Should it be shown to the user?Jev can provide structured judgments for these types of bounded questions.6. Workflow ControlA multi-step automation system frequently needs decisions such as:Continue?Retry?Ask user?Escalate?Stop?These are small decisions, but they occur repeatedly.That makes them natural candidates for a specialized decision model.Jev's Place in the AI StackA useful way to visualize modern AI software is as multiple layers.This separation is useful because different components can have different responsibilities.The LLM can generate.Jev can decide.Application code can enforce.Tools can execute.Humans can review uncertain or high-risk cases.AI StackHow Fast Is Jev?TypeSafe reports that Jev can be significantly faster and cheaper than general-purpose LLM workflows on the company's System One workflow evaluations.Its website currently reports up to 193.6× faster and 444.6× cheaper on those workflows. These are TypeSafe's reported results, not a universal guarantee for every workload.Vercel has also published the same broad comparison, reporting up to approximately 194× faster and 445× cheaper in TypeSafe's workflow evaluations.The reason for the difference in architecture is straightforward.A traditional LLM is designed to produce tokens.Jev is designed around structured decisions.For a workload that only needs:Which option?What score?Yes or no?generating a long natural-language response can be unnecessary overhead.How Jev Fits Into a Real Production WorkflowA sensible production architecture might look like this:The application should remain responsible for:AuthenticationPermissionsBusiness rulesTool argumentsSide effectsThresholdsHuman escalationLoggingError handlingJev should not be treated as a replacement for those controls.Vercel's guidance similarly recommends keeping tool execution and policy enforcement in application code even when Jev supplies the decision.When Should You Use Jev?Jev makes the most sense when the problem has a bounded decision space.Ask yourself:Can I clearly define the possible answers?If yes, Jev may be a candidate.For example:Which queue?→ Billing / Technical / AccountShould we continue?→ Yes / NoHow urgent is this?→ 1–5But:Write a detailed explanationis not a bounded decision.Use a generative model instead.Likewise:Generate a Java implementationis not what Jev is designed for.The easiest mental model is:If your software needs a paragraph, think generative model. If your software needs a bounded judgment, think decision model.Jev Through Vercel AI GatewayJev is also available through Vercel AI Gateway, which makes it possible to access Jev alongside other models through Vercel's AI infrastructure.Vercel's integration exposes Jev as:typesafe-ai/jevand supports evaluation questions such as Boolean, Choice, and Score. Multiple questions can be evaluated within the same request.As of September 21, 2026, Vercel also supports calling Jev through the TypeSafe client and a native HTTP API in addition to the AI SDK.This makes Jev accessible from different application architectures rather than limiting it to one specific framework.The Bigger Idea Behind JevThe most interesting part of Jev may not be its speed.It is the idea of treating decision-making itself as an AI primitive.For years, AI software has largely been built around:Jev suggests another abstraction:That is a meaningful architectural difference.Software does not always need an AI that talks.Sometimes it needs an AI that answers one narrow question reliably enough for the software to decide what happens next.Final TakeawayJev is not another chatbot and it is not simply a smaller version of a traditional LLM.It is designed around a different interface:state in → bounded questions → typed decisions out.Its three central decision primitives are:ChoiceScoreBoolean probabilityThat makes it particularly interesting for:AI agent routingTool selectionCustomer-support classificationWorkflow controlRisk and urgency scoringModel routingResponse evaluationAutomated verificationThe most important thing to remember is that structured does not mean infallible.Jev can constrain the shape of a decision, provide probability information, and remove the need for applications to parse generated prose. But the application still needs sensible question design, thresholds, evaluation data, permissions, and human-review paths for uncertain or high-risk cases.The broader architectural lesson is simple:Not every AI problem needs text generation. Some software problems need a decision.And that is the space Jev is designed to occupy.Quick Mental ModelJev does not try to replace generative AI. It adds a decision-making layer that software can use directly.Resources & LinksOfficial Website: TypeSafe AI / JevDeveloper Documentation: Vercel AI Gateway Integration
Jev AIJev Decision-Making ModelJevTypeSafe AIAI Decision MakingAI AgentsAI ModelsLLMAI AutomationAI Engineering
Building an AI Art Detective: From Kaggle Data to Deployed Vision Transformer (ViT)

Building an AI Art Detective: From Kaggle Data to Deployed Vision Transformer (ViT)

IntroductionThe rise of generative AI has created a new frontier for verification. As developers, we are no longer just building features; we are building filters for reality. This project explores how to fine-tune Google’s Vision Transformer (ViT) to detect the subtle "fingerprints" of AI-generated art.By the end of this guide, you will understand how to orchestrate a full ML lifecycle: data ingestion, model fine-tuning, threshold calibration, and cloud deployment.1. Data Engineering: The "Super Dataset"A model is only as good as its training data. For this project, I used the AI Generated vs Real Images dataset (2.5GB).To ensure a reproducible pipeline, I automated the download and extraction directly within the environment. This is a critical step for "Headless" training in cloud environments like Google Colab or Kaggle Kernels.import osimport zipfile# Automating Data Ingestion via Kaggle APIdataset_name = "cashbowman/ai-generated-images-vs-real-images"zip_path = "ai-generated-images-vs-real-images.zip"target_dir = 'super_dataset'print("Downloading 2.5GB high-quality dataset...")!kaggle datasets download -d {dataset_name}if os.path.exists(zip_path):with zipfile.ZipFile(zip_path, 'r') as z:z.extractall(target_dir)os.remove(zip_path) # Storage optimization: remove zip after extractionprint(f"Success! Data structure ready in /{target_dir}")2. Architecture Deep Dive: Why ViT?Standard Convolutional Neural Networks (CNNs) process images through local filters, which are great for textures but often miss "global" errors (like lighting inconsistency or anatomical impossible structures).I chose the google/vit-base-patch16-224 model because it treats an image like a sequence of tokens, similar to how BERT treats words:Patching: The 224x224 image is sliced into 196 patches (each 16x16 pixels).Linear Projection: Each patch is flattened into a 768-dimensional vector.Self-Attention: 12 attention heads allow the model to compare every patch against every other patch. This "global view" helps the model realize that while a texture looks "real," the overall structure is "AI-generated."3. The Training Loop & The "Safety Threshold"Training involved Transfer Learning. We froze the base "knowledge" of the model and only trained the final classification head to recognize the specific artifacts of generative AI.The Critical Logic: Confidence ThresholdingIn a production setting, a "False Positive" (calling a real artist's work AI) is a disaster for user trust. I implemented a 0.75 Confidence Threshold:AI Generated: Only if Probability > 0.75Real Art: The default if the model is uncertain.# The inference logic in app.pydef predict(image):inputs = processor(images=image, return_tensors="pt")outputs = model(**inputs)probs = torch.nn.functional.softmax(outputs.logits, dim=-1)ai_score = probs[0][0].item()real_score = probs[0][1].item()# Custom safety gatelabel = "AI Generated" if ai_score > 0.75 else "Real Art"return label, {"AI": ai_score, "Real": real_score}4. Deployment MLOps: Navigating "Dependency Hell"Deploying on Hugging Face Spaces sounds easy, but it often involves complex version conflicts. Here is the "Stability Recipe" used to overcome common runtime errors (like the audioop removal in Python 3.13):The Requirements RecipeTo ensure the Space remains "Running," we pinned specific versions in requirements.txt:torch --index-url https://download.pytorch.org/whl/cputransformers==4.44.2huggingface_hub==0.24.7gradio==4.44.1pydantic==2.10.6Git LFS (Large File Storage)Since the model weights are ~350MB, standard Git won't track them. We used Git LFS to ensure the binary files were uploaded correctly to the Hugging Face Hub.5. The Full-Stack IntegrationOne of the most powerful features of this deployment is the automatic API. Any modern application can now consume this model as a microservice.Example: Integrating with a React Frontendimport { Client } from "@gradio/client";async function checkArt(imageBlob) {const app = await Client.connect("hugua/vit");const result = await app.predict("/predict", [imageBlob]);console.log("Verdict:", result.data[0]);}Here are the demonstrations of it:Like can you tell is it a Ai image or Real ImageHere is our model prediction you can cross check this image from this youtube video-:Youtube video from where image takenSimilarly here is another exampleHere is our model prediction:Conclusion & Next StepsThis project bridges the gap between raw data science and full-stack engineering. We moved from a 2.5GB raw ZIP file to a live, globally accessible API.The next evolution of this project would be to implement Explainability using Attention Maps, allowing users to see exactly which parts of the image (e.g., the eyes or the background) triggered the "AI" flag.Resources:Dataset: AI vs Real Images (Kaggle)Live Demo: Live LinkDocumentation: Hugging Face Transformers GuideGoogle Collab: Link

MachineLearningComputerVisionNextJSPythonAIVisionTransformer
What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

What Is Dynamic Programming? Origin Story, Real-Life Uses, LeetCode Problems & Complete Beginner Guide

Introduction — Why Dynamic Programming Feels Hard (And Why It Isn't)If you've ever stared at a LeetCode problem, read the solution, understood every single line, and still had absolutely no idea how someone arrived at it — welcome. You've just experienced the classic Dynamic Programming (DP) confusion.DP has a reputation. People treat it like some dark art reserved for competitive programmers or Google engineers. The truth? Dynamic Programming is one of the most logical, learnable, and satisfying techniques in all of computer science. Once it clicks, it really clicks.This guide will take you from zero to genuinely confident. We'll cover where DP came from, how it works, what patterns to learn, how to recognize DP problems, real-world places it shows up, LeetCode problems to practice, time complexity analysis, and the mistakes that trip up even experienced developers.Let's go.The Origin Story — Who Invented Dynamic Programming and Why?The term "Dynamic Programming" was coined by Richard Bellman in the early 1950s while working at RAND Corporation. Here's the funny part: the name was deliberately chosen to sound impressive and vague.Bellman was doing mathematical research that his employer — the US Secretary of Defense, Charles Wilson — would have found difficult to fund if described accurately. Wilson had a well-known distaste for the word "research." So Bellman invented a name that sounded suitably grand and mathematical: Dynamic Programming.In his autobiography, Bellman wrote that he picked the word "dynamic" because it had a precise technical meaning and was also impossible to use negatively. "Programming" referred to the mathematical sense — planning and decision-making — not computer programming.The underlying idea? Break a complex problem into overlapping subproblems, solve each subproblem once, and store the result so you never solve it twice.Bellman's foundational contribution was the Bellman Equation, which underpins not just algorithms but also economics, operations research, and modern reinforcement learning.So the next time DP feels frustrating, remember — even its inventor named it specifically to confuse people. You're in good company.What Is Dynamic Programming? (Simple Definition)Dynamic Programming is an algorithmic technique used to solve problems by:Breaking them down into smaller overlapping subproblemsSolving each subproblem only onceStoring the result (memoization or tabulation)Building up the final solution from those stored resultsThe key insight is overlapping subproblems + optimal substructure.Overlapping subproblems means the same smaller problems come up again and again. Instead of solving them every time (like plain recursion does), DP solves them once and caches the answer.Optimal substructure means the optimal solution to the whole problem can be built from optimal solutions to its subproblems.If a problem has both these properties — it's a DP problem.The Two Approaches to Dynamic Programming1. Top-Down with Memoization (Recursive + Cache)You write a recursive solution exactly as you would naturally, but add a cache (usually a dictionary or array) to store results you've already computed.fib(n):if n in cache: return cache[n]if n <= 1: return ncache[n] = fib(n-1) + fib(n-2)return cache[n]This is called memoization — remember what you computed so you don't repeat yourself.Pros: Natural to write, mirrors the recursive thinking, easy to reason about. Cons: Stack overhead from recursion, risk of stack overflow on large inputs.2. Bottom-Up with Tabulation (Iterative)You figure out the order in which subproblems need to be solved, then solve them iteratively from the smallest up, filling a table.fib(n):dp = [0, 1]for i from 2 to n:dp[i] = dp[i-1] + dp[i-2]return dp[n]This is called tabulation — fill a table, cell by cell, bottom to top.Pros: No recursion overhead, usually faster in practice, easier to optimize space. Cons: Requires thinking about the order of computation upfront.🧩 Dynamic Programming Template CodeBefore diving into how to recognize DP problems, here are ready-to-use Java templates for every major DP pattern. Think of these as your reusable blueprints — every DP problem you ever solve will fit into one of these structures. Just define your state, plug in your recurrence relation, and you are good to go.Template 1 — Top-Down (Memoization)import java.util.HashMap;import java.util.Map;public class TopDownDP {Map<Integer, Integer> memo = new HashMap<>();public int solve(int n) {// Base caseif (n <= 1) return n;// Check cacheif (memo.containsKey(n)) return memo.get(n);// Recurrence relation — change this part for your problemint result = solve(n - 1) + solve(n - 2);// Store in cachememo.put(n, result);return result;}}Template 2 — Bottom-Up (Tabulation)public class BottomUpDP {public int solve(int n) {// Create DP tableint[] dp = new int[n + 1];// Base casesdp[0] = 0;dp[1] = 1;// Fill the table bottom-upfor (int i = 2; i <= n; i++) {// Recurrence relation — change this part for your problemdp[i] = dp[i - 1] + dp[i - 2];}return dp[n];}}Template 3 — Bottom-Up with Space Optimizationpublic class SpaceOptimizedDP {public int solve(int n) {// Only keep last two values instead of full tableint prev2 = 0;int prev1 = 1;for (int i = 2; i <= n; i++) {// Recurrence relation — change this part for your problemint curr = prev1 + prev2;prev2 = prev1;prev1 = curr;}return prev1;}}Template 4 — 2D DP (Two Sequences or Grid)public class TwoDimensionalDP {public int solve(String s1, String s2) {int m = s1.length();int n = s2.length();// Create 2D DP tableint[][] dp = new int[m + 1][n + 1];// Base cases — first row and columnfor (int i = 0; i <= m; i++) dp[i][0] = i;for (int j = 0; j <= n; j++) dp[0][j] = j;// Fill table cell by cellfor (int i = 1; i <= m; i++) {for (int j = 1; j <= n; j++) {// Recurrence relation — change this part for your problemif (s1.charAt(i - 1) == s2.charAt(j - 1)) {dp[i][j] = dp[i - 1][j - 1];} else {dp[i][j] = 1 + Math.min(dp[i - 1][j],Math.min(dp[i][j - 1], dp[i - 1][j - 1]));}}}return dp[m][n];}}Template 5 — Knapsack Patternpublic class KnapsackDP {public int solve(int[] weights, int[] values, int capacity) {int n = weights.length;// dp[i][w] = max value using first i items with capacity wint[][] dp = new int[n + 1][capacity + 1];for (int i = 1; i <= n; i++) {for (int w = 0; w <= capacity; w++) {// Don't take item idp[i][w] = dp[i - 1][w];// Take item i if it fitsif (weights[i - 1] <= w) {dp[i][w] = Math.max(dp[i][w],values[i - 1] + dp[i - 1][w - weights[i - 1]]);}}}return dp[n][capacity];}}💡 How to use these templates:Step 1 — Identify which pattern your problem fits into. Step 2 — Define what dp[i] or dp[i][j] means in plain English before writing any code. Step 3 — Write your recurrence relation on paper first. Step 4 — Plug it into the matching template above. Step 5 — Handle your specific base cases carefully.🎥 Visual Learning Resource — Watch This Before Moving ForwardIf you prefer learning by watching before reading, this free full-length course by freeCodeCamp is one of the best Dynamic Programming resources on the internet. Watch it alongside this guide for maximum understanding.Credit: freeCodeCamp — a free, nonprofit coding education platform.How to Recognize a Dynamic Programming ProblemAsk yourself these four questions:1. Can I define the problem in terms of smaller versions of itself? If you can write a recursive formula (recurrence relation), DP might apply.2. Do the subproblems overlap? If a naive recursive solution would recompute the same thing many times, DP is the right tool.3. Is there an optimal substructure? Is the best answer to the big problem made up of best answers to smaller problems?4. Are you looking for a count, minimum, maximum, or yes/no answer? DP problems often ask: "What is the minimum cost?", "How many ways?", "Can we achieve X?"Red flag words in problem statements: minimum, maximum, shortest, longest, count the number of ways, can we reach, is it possible, fewest steps.The Core DP Patterns You Must LearnMastering DP is really about recognizing patterns. Here are the most important ones:Pattern 1 — 1D DP (Linear) Problems where the state depends on previous elements in a single sequence. Examples: Fibonacci, Climbing Stairs, House Robber.Pattern 2 — 2D DP (Grid / Two-sequence) Problems with two dimensions of state, often grids or two strings. Examples: Longest Common Subsequence, Edit Distance, Unique Paths.Pattern 3 — Interval DP You consider all possible intervals or subarrays and build solutions from them. Examples: Matrix Chain Multiplication, Burst Balloons, Palindrome Partitioning.Pattern 4 — Knapsack DP (0/1 and Unbounded) You decide whether to include or exclude items under a capacity constraint. Examples: 0/1 Knapsack, Coin Change, Partition Equal Subset Sum.Pattern 5 — DP on Trees State is defined per node; you combine results from children. Examples: Diameter of Binary Tree, House Robber III, Maximum Path Sum.Pattern 6 — DP on Subsets / Bitmask DP State includes a bitmask representing which elements have been chosen. Examples: Travelling Salesman Problem, Shortest Superstring.Pattern 7 — DP on Strings Matching, editing, or counting arrangements within strings. Examples: Longest Palindromic Subsequence, Regular Expression Matching, Wildcard Matching.Top LeetCode Problems to Practice Dynamic Programming (With Links)Here are the essential problems, organized by difficulty and pattern. Solve them in this order.Beginner — Warm UpProblemPatternLinkClimbing Stairs1D DPhttps://leetcode.com/problems/climbing-stairs/Fibonacci Number1D DPhttps://leetcode.com/problems/fibonacci-number/House Robber1D DPhttps://leetcode.com/problems/house-robber/Min Cost Climbing Stairs1D DPhttps://leetcode.com/problems/min-cost-climbing-stairs/Best Time to Buy and Sell Stock1D DPhttps://leetcode.com/problems/best-time-to-buy-and-sell-stock/Intermediate — Core PatternsProblemPatternLinkCoin ChangeKnapsackhttps://leetcode.com/problems/coin-change/Longest Increasing Subsequence1D DPhttps://leetcode.com/problems/longest-increasing-subsequence/Longest Common Subsequence2D DPhttps://leetcode.com/problems/longest-common-subsequence/0/1 Knapsack (via Subset Sum)Knapsackhttps://leetcode.com/problems/partition-equal-subset-sum/Unique Paths2D Grid DPhttps://leetcode.com/problems/unique-paths/Jump Game1D DP / Greedyhttps://leetcode.com/problems/jump-game/Word BreakString DPhttps://leetcode.com/problems/word-break/Decode Ways1D DPhttps://leetcode.com/problems/decode-ways/Edit Distance2D String DPhttps://leetcode.com/problems/edit-distance/Triangle2D DPhttps://leetcode.com/problems/triangle/Advanced — Interview LevelProblemPatternLinkBurst BalloonsInterval DPhttps://leetcode.com/problems/burst-balloons/Regular Expression MatchingString DPhttps://leetcode.com/problems/regular-expression-matching/Wildcard MatchingString DPhttps://leetcode.com/problems/wildcard-matching/Palindrome Partitioning IIInterval DPhttps://leetcode.com/problems/palindrome-partitioning-ii/Maximum Profit in Job SchedulingDP + Binary Searchhttps://leetcode.com/problems/maximum-profit-in-job-scheduling/Distinct Subsequences2D DPhttps://leetcode.com/problems/distinct-subsequences/Cherry Pickup3D DPhttps://leetcode.com/problems/cherry-pickup/Real-World Use Cases of Dynamic ProgrammingDP is not just for coding interviews. It is deeply embedded in the technology you use every day.1. Google Maps & Navigation (Shortest Path) The routing engines behind GPS apps use DP-based algorithms like Dijkstra and Bellman-Ford to find the shortest or fastest path between two points across millions of nodes.2. Spell Checkers & Autocorrect (Edit Distance) When your phone corrects "teh" to "the," it is computing Edit Distance — a classic DP problem — between what you typed and every word in the dictionary.3. DNA Sequence Alignment (Bioinformatics) Researchers use the Needleman-Wunsch and Smith-Waterman algorithms — both DP — to align DNA and protein sequences and find similarities between species or identify mutations.4. Video Compression (MPEG, H.264) Modern video codecs use DP to determine the most efficient way to encode video frames, deciding which frames to store as full images and which to store as differences from the previous frame.5. Financial Portfolio Optimization Investment algorithms use DP to find the optimal allocation of assets under risk constraints — essentially a variant of the knapsack problem.6. Natural Language Processing (NLP) The Viterbi algorithm — used in speech recognition, part-of-speech tagging, and machine translation — is a DP algorithm. Every time Siri or Google Assistant understands your sentence, DP played a role.7. Game AI (Chess, Checkers) Game trees and minimax algorithms with memoization use DP to evaluate board positions and find the best move without recomputing already-seen positions.8. Compiler Optimization Compilers use DP to decide the optimal order of operations and instruction scheduling to generate the most efficient machine code.9. Text Justification (Word Processors) Microsoft Word and LaTeX use DP to optimally break paragraphs into lines — minimizing raggedness and maximizing visual appeal.10. Resource Scheduling in Cloud Computing AWS, Google Cloud, and Azure use DP-based scheduling to assign computational tasks to servers in the most cost-efficient way possible.Time Complexity Analysis of Common DP ProblemsUnderstanding the time complexity of DP is critical for interviews and for building scalable systems.ProblemTime ComplexitySpace ComplexityNotesFibonacci (naive recursion)O(2ⁿ)O(n)Exponential — terribleFibonacci (DP)O(n)O(1) with optimizationLinear — excellentLongest Common SubsequenceO(m × n)O(m × n)m, n = lengths of two stringsEdit DistanceO(m × n)O(m × n)Can optimize space to O(n)0/1 KnapsackO(n × W)O(n × W)n = items, W = capacityCoin ChangeO(n × amount)O(amount)Classic tabulationLongest Increasing SubsequenceO(n²) or O(n log n)O(n)Binary search version is fasterMatrix Chain MultiplicationO(n³)O(n²)Interval DPTravelling Salesman (bitmask)O(2ⁿ × n²)O(2ⁿ × n)Still exponential but manageable for small nThe general rule: DP trades time for space. You use memory to avoid recomputation. The time complexity equals the number of unique states multiplied by the work done per state.How to Learn and Master Dynamic Programming — Step by StepHere is an honest, structured path to mastery:Step 1 — Get recursion absolutely solid first. DP is memoized recursion at its core. If you cannot write clean recursive solutions confidently, DP will remain confusing. Practice at least 20 pure recursion problems first.Step 2 — Start with the classics. Fibonacci → Climbing Stairs → House Robber → Coin Change. These teach you the core pattern of defining state and transition without overwhelming you.Step 3 — Learn to define state explicitly. Before writing any code, ask: "What does dp[i] represent?" Write it in plain English. "dp[i] = the minimum cost to reach step i." This single habit separates good DP thinkers from struggling ones.Step 4 — Write the recurrence relation before coding. On paper or in a comment. Example: dp[i] = min(dp[i-1] + cost[i-1], dp[i-2] + cost[i-2]). If you can write the recurrence, the code writes itself.Step 5 — Master one pattern at a time. Don't jump between knapsack and interval DP in the same week. Spend a few days on each pattern until it feels intuitive.Step 6 — Solve the same problem both ways. Top-down and bottom-up. This builds deep understanding of what DP is actually doing.Step 7 — Optimize space after getting correctness. Many 2D DP solutions can use a single row instead of a full matrix. Learn this optimization after you understand the full solution.Step 8 — Do timed practice under interview conditions. Give yourself 35 minutes per problem. Review what you got wrong. DP is a muscle — it builds with reps.Common Mistakes in Dynamic Programming (And How to Avoid Them)Mistake 1 — Jumping to code before defining state. The most common DP error. Always define what dp[i] or dp[i][j] means before writing a single line of code.Mistake 2 — Wrong base cases. A single wrong base case corrupts every answer built on top of it. Trace through your base cases manually on a tiny example before running code.Mistake 3 — Off-by-one errors in indexing. Whether your dp array is 0-indexed or 1-indexed must be 100% consistent throughout. This causes more bugs in DP than almost anything else.Mistake 4 — Confusing top-down with bottom-up state order. In bottom-up DP, you must ensure that when you compute dp[i], all values it depends on are already filled. If you compute in the wrong order, you get garbage answers.Mistake 5 — Memoizing in the wrong dimension. In 2D problems, some people cache only one dimension when the state actually requires two. Always identify all variables that affect the outcome.Mistake 6 — Using global mutable state in recursion. If you use a shared array and don't clear it between test cases, you'll get wrong answers on subsequent inputs. Always scope your cache correctly.Mistake 7 — Not considering the full state space. In problems like Knapsack, forgetting that the state is (item index, remaining capacity) — not just item index — leads to fundamentally wrong solutions.Mistake 8 — Giving up after not recognizing the pattern immediately. DP problems don't announce themselves. The skill is learning to ask "is there overlapping subproblems here?" on every problem. This takes time. Don't mistake unfamiliarity for inability.Frequently Asked Questions About Dynamic ProgrammingQ: Is Dynamic Programming the same as recursion? Not exactly. Recursion is a technique for breaking problems into smaller pieces. DP is recursion plus memoization — or iterative tabulation. All DP can be written recursively, but not all recursion is DP.Q: What is the difference between DP and Divide and Conquer? Divide and Conquer (like Merge Sort) breaks problems into non-overlapping subproblems. DP is used when subproblems overlap — meaning the same subproblem is solved multiple times in a naive approach.Q: How do I know when NOT to use DP? If the subproblems don't overlap (no repeated computation), greedy or divide-and-conquer may be better. If the problem has no optimal substructure, DP won't give a correct answer.Q: Do I need to memorize DP solutions for interviews? No. You need to recognize patterns and be able to derive the recurrence relation. Memorizing solutions without understanding them will fail you in interviews. Focus on the thinking process.Q: How long does it take to get good at DP? Most people start to feel genuinely comfortable after solving 40–60 varied DP problems with deliberate practice. The first 10 feel impossible. The next 20 feel hard. After 50, patterns start feeling obvious.Q: What programming language is best for DP? Any language works. Python is often used for learning because its dictionaries make memoization trivial. C++ is preferred in competitive programming for its speed. For interviews, use whatever language you're most comfortable in.Q: What is space optimization in DP? Many DP problems only look back one or two rows to compute the current row. In those cases, you can replace an n×m table with just two arrays (or even one), reducing space complexity from O(n×m) to O(m). This is called space optimization or rolling array technique.Q: Can DP be applied to graph problems? Absolutely. Shortest path algorithms like Bellman-Ford are DP. Longest path in a DAG is DP. DP on trees is a rich subfield. Anywhere you have states and transitions, DP can potentially apply.Q: Is Greedy a type of Dynamic Programming? Greedy is related but distinct. Greedy makes locally optimal choices without reconsidering. DP considers all choices and picks the globally optimal one. Some DP solutions reduce to greedy when the structure allows, but they are different techniques.Q: What resources should I use to learn DP? For structured learning: Neetcode.io (organized problem list), Striver's DP Series on YouTube, and the book "Introduction to Algorithms" (CLRS) for theoretical depth. For practice: LeetCode's Dynamic Programming study plan and Codeforces for competitive DP.Final Thoughts — Dynamic Programming Is a SuperpowerDynamic Programming is genuinely one of the most powerful ideas in computer science. It shows up in your GPS, your autocorrect, your streaming video, your bank's risk models, and the AI assistants you talk to daily.The path to mastering it is not memorization. It is developing the habit of asking: can I break this into smaller problems that overlap? And then learning to define state clearly, write the recurrence, and trust the process.Start with Climbing Stairs. Write dp[i] in plain English before every problem. Solve everything twice — top-down and bottom-up. Do 50 problems with genuine reflection, not just accepted solutions.The click moment will come. And when it does, you'll wonder why it ever felt hard.

Dynamic ProgrammingMemoizationTabulationJavaOrigin StoryRichard Bellman
Ai Assistant Kas